Microsoft인증AI-300시험은 국제적으로 승인해주는 IT인증시험의 한과목입니다. 근 몇년간 IT인사들에게 최고의 인기를 누리고 있는 과목으로서 그 난이도 또한 높습니다. 자격증을 취득하여 직장에서 혹은 IT업계에서 자시만의 위치를 찾으련다면 자격증 취득이 필수입니다. Microsoft인증AI-300시험을 패스하고 싶은 분들은KoreaDumps제품으로 가보세요.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Topic 2: Implement machine learning model lifecycle and operations | 25–30% | - Register, version, and package models
|
| Topic 3: Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
| Topic 4: Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Topic 5: Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
Microsoft AI-300 시험이 어렵다고해도 KoreaDumps의 Microsoft AI-300시험잡이 덤프가 있는한 아무리 어려운 시험이라도 쉬워집니다. 어려운 시험이라 막무가내로 시험준비하지 마시고 문항수도 적고 모든 시험문제를 커버할수 있는Microsoft AI-300자료로 대비하세요. 가장 적은 투자로 가장 큰 득을 보실수 있습니다.
질문 # 144
Hotspot Question
You create an Azure Machine Learning workspace.
You must use the Python SDK v2 to implement an experiment from a Jupyter notebook in the workspace. The experiment must log a table in the following format: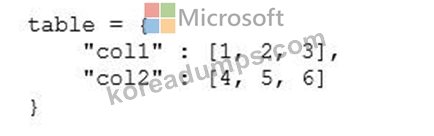
You need to complete the Python code to log the table.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.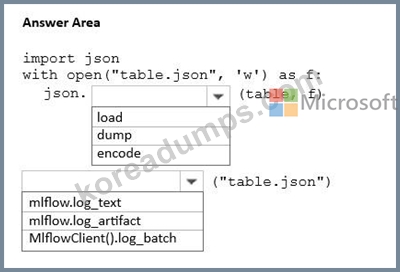
정답:
설명: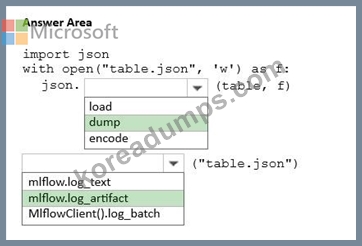
Explanation:
Box 1: dump
Log a table, SDK v2 with MLflow
# Add a metric for each column prefixed by metric name. Similar to log_row row1 = {"table.col1": 5, "table.col2": 10}
# To be done for each row in the table
mlflow.log_metrics(row1)
# Using mlflow.log_artifact
import json
with open("table.json", 'w') as f:
json.dump(table, f)
mlflow.log_artifact("table.json")
Box 2: mlflow.log_artifact
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/reference-migrate-sdk-v1-mlflow-tracking
질문 # 145
Drag and Drop Question
You have an Azure Machine Learning workspace named WS1 and a GitHub account named account1 that hosts a private repository named repo1.
You need to clone repo1 to make it available directly from WS1. The configuration must maximize the performance of the repo1 clone.
Which four actions should you perform in sequence?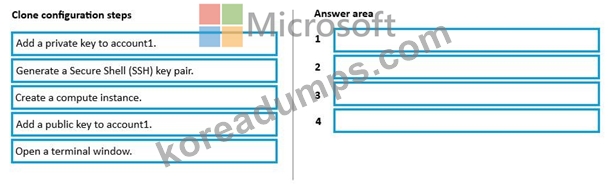
정답:
설명: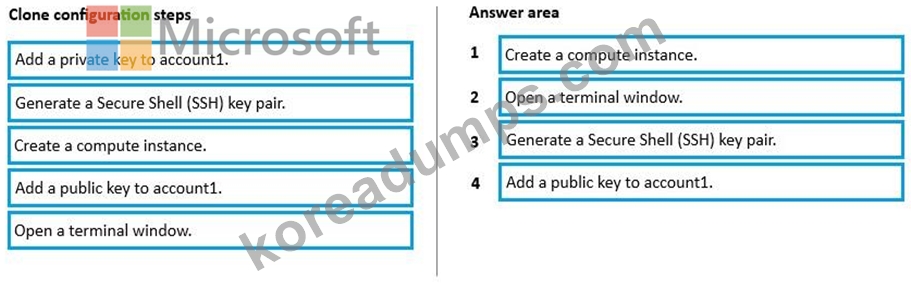
Explanation:
Step 1: Create a compute instance
Git integration for Azure Machine Learning
Clone Git repositories into your workspace file system
Azure Machine Learning provides a shared file system for all users in the workspace. To clone a Git repository into this file share, we recommend that you create a compute instance (Step 1) & open a terminal (Step 2). Once the terminal is opened, you have access to a full Git client and can clone and work with Git via the Git CLI experience.
We recommend that you clone the repository into your user directory so that others will not make collisions directly on your working branch.
Step 2: Open a terminal window
Step 3: Generate a Secure Shell (SSH) key pair
Authenticate your Git Account with SSH
Generate a new SSH key
1. Open the terminal window in the Azure Machine Learning Notebook Tab.
2. Paste the text below, substituting in your email address.
ssh-keygen -t rsa -b 4096 -C your_email@example.com
This creates a new ssh key, using the provided email as a label.
3. When you're prompted to "Enter a file in which to save the key" press Enter. This accepts the default file location.
4. Verify that the default location is '/home/azureuser/.ssh' and press enter. Otherwise specify the location '/home/azureuser/.ssh'.
5. At the prompt, type a secure passphrase. We recommend you add a passphrase to your SSH key for added security Step 4: Add a public key to account1.
Add the public key to Git Account
1. In your terminal window, copy the contents of your public key file. If you renamed the key, replace id_rsa.pub with the public key file name.
cat ~/.ssh/id_rsa.pub
2. Select and copy the SSH key output to your clipboard.
3. Next, follow the steps to add the SSH key to your preferred account type:
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/concept-train-model-git-integration
질문 # 146
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
The default datastore of workspace1 contains a folder named sample_data.
The folder structure contains the following content: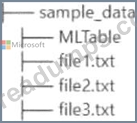
You write Python SDK v2 code to materialize the data from the files in the sample_data folder into a Pandas data frame.
You need to complete the Python SDK v2 code to use the MLTable folder as the materialization blueprint.
How should you complete the code? To answer, select the appropriate options in the answer area . NOTE:
Each correct selection is worth one point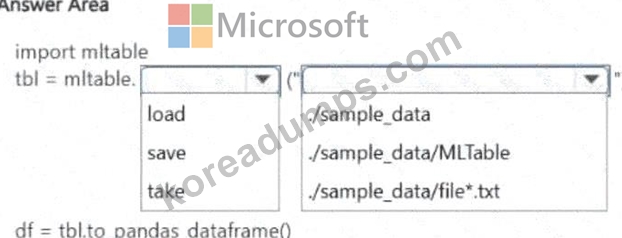
정답:
설명: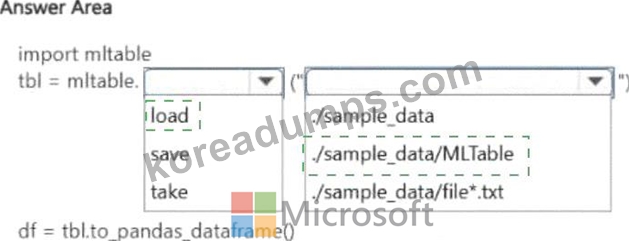
Explanation:
The MLTable format in Azure Machine Learning Python SDK v2 is a structured abstraction over tabular data sources. It stores a YAML file alongside data files, describing how to read and transform the data. To materialize this into a Pandas DataFrame, you use the mltable library: first call mltable.load with the path to the MLTable folder to load the definition, then call to_pandas_dataframe() on the returned object. The path parameter should point to the folder containing the MLTable YAML file on the default datastore. MLTable abstracts the storage location and transformation steps, making the code storage-agnostic - the same code works whether data lives in Blob Storage, ADLS Gen2, or a local path. The SDK v2 approach with MLTable is the recommended pattern for governed, reusable data access in Azure Machine Learning.
Microsoft Learn Reference Topic: Create and use MLTable data assets in Azure Machine Learning Python SDK v2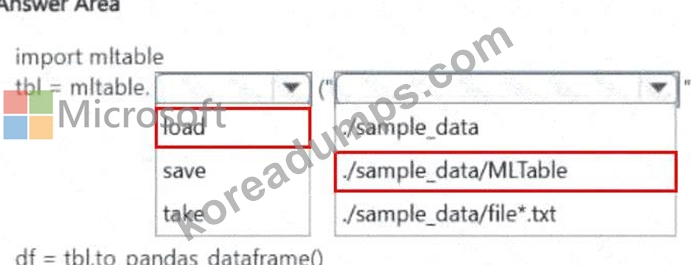
질문 # 147
You are training machine learning models in Azure Machine Learning. You use Hyperdrive to tune the hyperparameters.
In previous model training and tuning runs, many models showed similar performance.
You need to select an early termination policy that meets the following requirements:
- accounts for the performance of all previous runs when evaluating the current run
- avoids comparing the current run with only the best performing run to date Which two early termination policies should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
정답:C,D
설명:
The Median Stopping Policy and the Truncation Selection Policy are the most appropriate early termination policies for this scenario. Both evaluate runs based on the performance of all previous runs instead of strictly benchmarking against the single best run.
Median Stopping Policy: This policy calculates the running averages of the primary metric across all historical and current training runs at each evaluation interval. It terminates any ongoing run if its performance is worse than the median of those averages. This directly accounts for all previous run performances rather than just the single best run.
Truncation Selection Policy: This policy evaluates all active runs at each interval and terminates a specified bottom percentage (X%) of the lowest-performing runs. Because it aggregates and compares the entire cohort of runs, it avoids making narrow comparisons against only the best- performing run.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-tune-hyperparameters
질문 # 148
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You work in Microsoft Foundry with a prompt flow.
You must manually evaluate prompts and compare results across prompt variants.
You need to capture the inputs, outputs, token usage, and latencies for each flow run for the evaluation.
Solution: In Microsoft Foundry, turn on Tracing for the prompt flow of the project and execute test runs to produce trace data.
Does the solution meet the goal?
정답:A
설명:
Correct:
* In Microsoft Foundry, turn on Tracing for the prompt flow of the project and execute test runs to produce trace data.
Incorrect:
* Create prompt variants and compare their outputs in the Evaluation experience.
* Use the prompt flow SDK to enable tracing for the flow before executing runs. Then run the flow to generate traceable results.
Note:
In Azure AI Foundry, you can capture and compare these metrics by enabling Tracing and using the Bulk Test feature. This allows you to systematically evaluate different prompt variants against a common dataset.
Steps to Evaluate and Compare Prompt Variants
*-> 1. Enable Tracing
Navigate to your Prompt Flow project.
Locate the Tracing toggle at the top of the flow authoring page.
Switch it to On.
This ensures every execution captures latency, token counts, and node-level inputs/outputs.
2. Create Prompt Variants
Within your flow, identify the LLM node you want to test.
Click Variants to create multiple versions of your prompt (e.g., Variant_0, Variant_1).
This allows you to test different instructions or few-shot examples side-by-side.
3. Run a Bulk Test (Evaluation)
4. Analyze the Results
Reference:
https://www.linkedin.com/pulse/streamlining-generative-ai-development-azure-foundry-tracing- taneja-mbwze
질문 # 149
......
Microsoft인증 AI-300시험을 패스하여 자격증을 취득하여 승진이나 이직을 꿈구고 있는 분이신가요? 이 글을 읽게 된다면Microsoft인증 AI-300시험패스를 위해 공부자료를 마련하고 싶은 마음이 크다는것을 알고 있어 시장에서 가장 저렴하고 가장 최신버전의 Microsoft인증 AI-300덤프자료를 강추해드립니다. 높은 시험패스율을 자랑하고 있는Microsoft인증 AI-300덤프는 여러분이 승진으로 향해 달리는 길에 날개를 펼쳐드립니다.자격증을 하루 빨리 취득하여 승진꿈을 이루세요.
AI-300시험덤프공부: https://www.koreadumps.com/AI-300_exam-braindumps.html