2026 Latest Dumpkiller AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=1P0ZhHqekoLnzFuua-g0N4_yYC-cZ-LyX
Do not miss the opportunity to buy the best AI-300 preparation questions in the international market which will also help you to advance with the times. If you are still worrying about our AI-300 exam questions, I would like to help you out with the free demos of our AI-300 Training Materials compiled by our company. There are so many strong points of our AI-300 training materials, such as wide applicability, sharpen the saw and responsible after sale service to name.
| Section | Objectives |
|---|---|
| Implement generative AI quality assurance and observability | - Implement logging, tracing, and telemetry for GenAI applications - Monitor latency, token usage, cost, and error rates - Evaluate generative AI outputs for quality, safety, and grounding - Conduct red teaming, adversarial testing, and content filtering |
| Design and implement a GenAIOps infrastructure | - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Manage API keys, rate limits, and responsible AI guardrails - Configure prompt orchestration, prompt flows, and agent frameworks |
| Optimize generative AI systems and model performance | - Optimize inference performance, caching, and throughput - Implement cost management and scaling strategies for GenAI workloads - Fine-tune and distill models for specific use cases - Tune prompts, system messages, and grounding strategies |
| Implement machine learning model lifecycle and operations | - Monitor model performance, data drift, and operational health - Deploy models to real-time and batch endpoints - Train, register, and version models using Azure Machine Learning - Retrain, update, and manage model versions in production |
| Design and implement an MLOps infrastructure | - Set up Azure Machine Learning workspace and compute targets - Configure source control, CI/CD pipelines, and automation for ML workflows - Manage environments, data stores, and model registries - Implement security, governance, and compliance for MLOps |
>> AI-300 Latest Test Report <<
What is more, some after-sales services behave indifferently towards exam candidates who eager to get success, our AI-300 practice materials are on the opposite of it. So just set out undeterred with our AI-300 practice materials, These AI-300 practice materials win honor for our company, and we treat it as our utmost privilege to help you achieve your goal. Our AI-300 practice materials are made by our responsible company which means you can gain many other benefits as well.
NEW QUESTION # 100
You manage an Azure Machine Learning workspace.
You must set up an event-driven process to trigger a retraining pipeline.
You need to configure an Azure service that will trigger a retraining pipeline in response to data drift in Azure Machine Learning datasets. Which Azure service should you use?
Answer: C
NEW QUESTION # 101
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
You must register datastores in workspace1 for Azure Blob and Azure Data Lake Gen2 storage to meet the following requirements:
* Data scientists accessing the datastore must have the same level of access.
* Access must be restricted to specified containers or folders.
You need to configure a security access method used to register the Azure Blob and Azure Data lake Gen?
storage in workspace1. Which security access method should you configure? To answer, select the appropriate options in the answers area.
NOTE: Each correct selection is worth one point.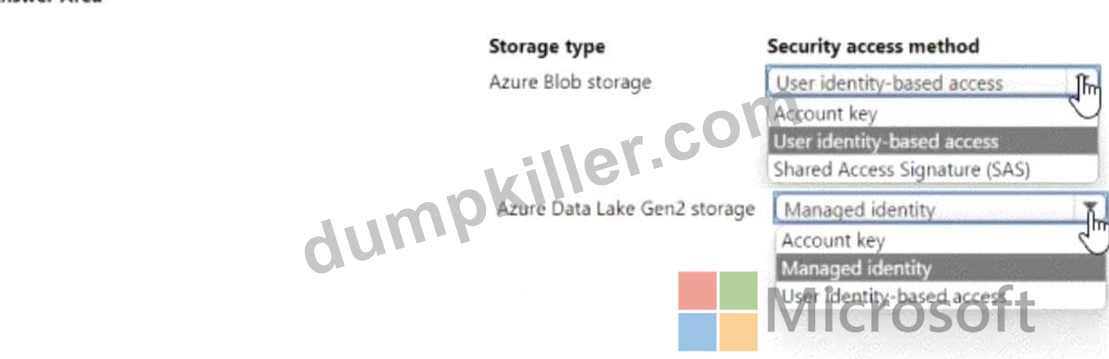
Answer:
Explanation: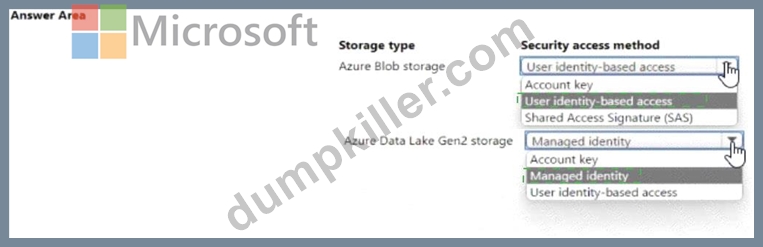
Explanation: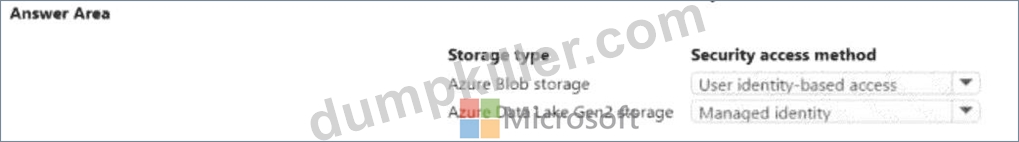
NEW QUESTION # 102
A team is building a Retrieval-Augmented Generation (RAG) system.
The team observes that the retrieved documents are often irrelevant or incomplete.
You need to improve retrieval accuracy.
What should you adjust?
Answer: A
Explanation:
To best improve retrieval accuracy when documents are irrelevant or incomplete, you should adjust Chunk size and overlap.
Fixes Irrelevant Retrievals: If your chunks are too large, they pack in multiple unrelated topics.
This adds noise, dilutes the semantic vector, and causes the system to pull in massive blocks of text where only a single sentence was actually relevant. Tuning the size ensures chunks stay highly specific.
Fixes Incomplete Retrievals: If your chunks are too small or lack sufficient overlap, vital context gets completely cut off at the boundaries. Adding an optimal overlap (typically 10%-20%) ensures that a sentence split across a boundary preserves its surrounding meaning, keeping the context whole.
Incorrect:
[Not B]
Temperature parameter: This is a generative LLM setting that dictates the creativity or randomness of the output text. It has absolutely zero control over the vector search database or the specific documents picked during the initial retrieval phase.
[Not C]¨
Token limits: This caps how much context you can pass into the prompt window or how much text the model can generate. While a higher limit lets you pass more documents, it does not magically fix the underlying data quality or prevent the retrieval algorithm from pulling in wrong files.
[Not D]
Embedding strategy: While choosing a stronger model or fine-tuning embeddings changes how text is numerically represented, it cannot overcome poorly structured data. Even the best embedding model cannot successfully capture semantic meaning if your data ingestion pipeline is feeding it randomly sliced, incomplete paragraphs Reference:
https://pmc.ncbi.nlm.nih.gov/articles/PMC12649634/
NEW QUESTION # 103
You create an Azure Machine Learning workspace and install the MLflow library.
You need to log different types of data by using the MLflow library.
Which method should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.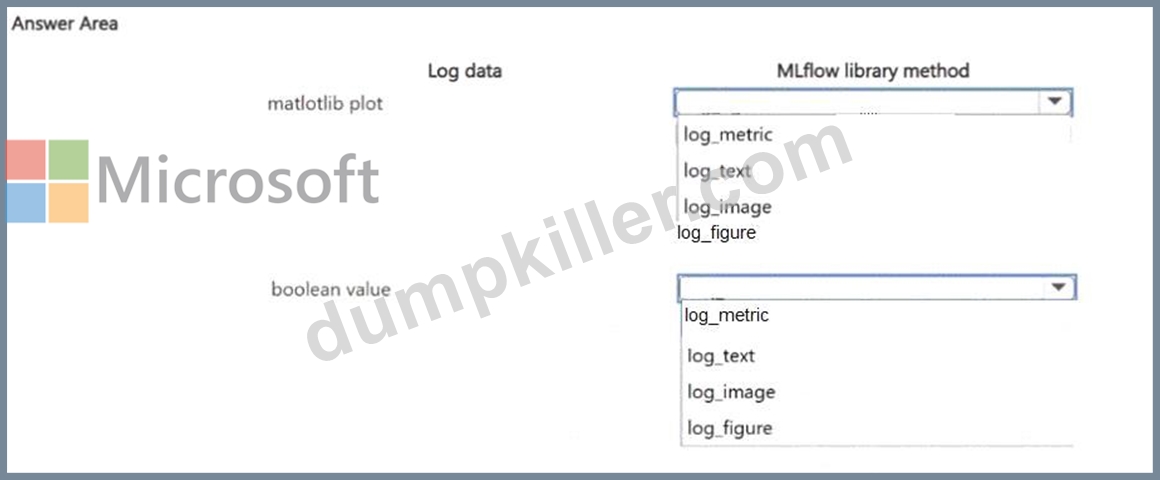
Answer:
Explanation: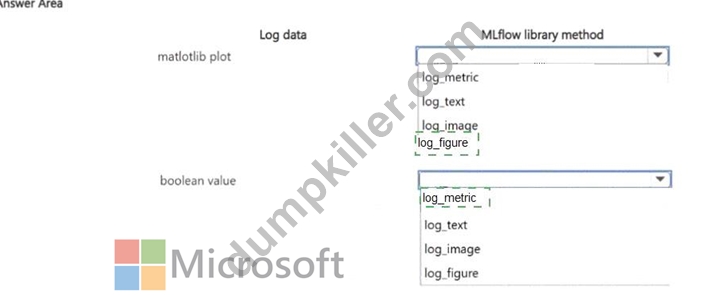
Explanation: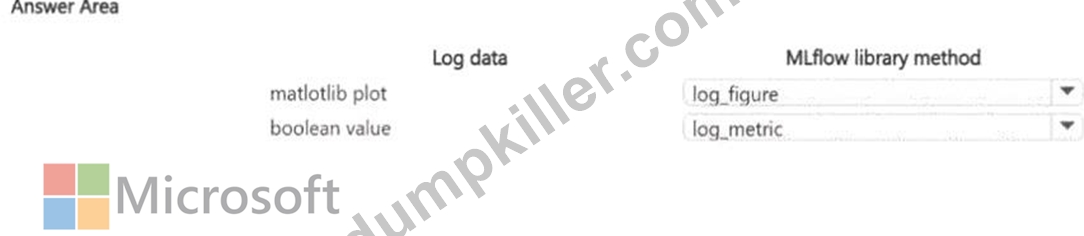
NEW QUESTION # 104
A team develops multiple AI applications in Microsoft Foundry that rely on shared prompt templates.
The team requires a centralized way to track, version, and reuse prompt content across projects.
You need to recommend a solution to track and reuse prompt content.
Which approach should you recommend?
Answer: D
Explanation:
A Git repository provides all three capabilities required: version history for every change with author attribution and timestamp, branching for experimentation, tagging for stable releases, and a single source of truth accessible to all projects via clone or submodule reference. Azure ML datasets (option B) are designed for training data, not text configuration artifacts, and lack per-line diff tracking and review workflows.
Embedding prompts in application configuration files (option C) scatters prompt content across multiple applications with no unified view, no shared versioning, and no cross-project reuse. Unstructured Blob Storage with folder organization (option D) provides no version history, no diff tracking, no review workflow, and no native tooling for comparing prompt variants. Git is the definitive answer for centralized tracking, versioning, and reuse of prompt content across Microsoft Foundry projects.
Microsoft Learn Reference Topic: Prompt engineering and version control - Managing prompts in AI applications with Git
NEW QUESTION # 105
......
The three versions of our AI-300 training materials each have its own advantage. On the one hand, the software version can simulate the real AI-300 examination for all of the users in windows operation system. By actually simulating the real test environment. On the other hand, if you choose to use the software version, you can download our AI-300 Exam Prep only for Windows system. We strongly believe that the software version of our AI-300 study materials will be of great importance for you to prepare for the exam and all of the employees in our company wish you early success.
Reliable AI-300 Practice Materials: https://www.dumpkiller.com/AI-300_braindumps.html
BONUS!!! Download part of Dumpkiller AI-300 dumps for free: https://drive.google.com/open?id=1P0ZhHqekoLnzFuua-g0N4_yYC-cZ-LyX