DP-600難易度受験料 & DP-600入門知識

P.S. GoShikenがGoogle Driveで共有している無料かつ新しいDP-600ダンプ:https://drive.google.com/open?id=1fWSzPJmPtqBvxy4_jjnFShM4BynHsvCb
人によって目標が違いますが、あなたにMicrosoft DP-600試験に順調に合格できるのは我々の共同の目標です。この目標の達成はあなたがIT技術領域へ行く更なる発展の一歩ですけど、我々社GoShiken存在するこそすべての意義です。だから、我々社は力の限りで弊社のMicrosoft DP-600試験資料を改善し、改革の変更に応じて更新します。あなたはいつまでも最新版の問題集を使用できるために、ご購入の一年間で無料の更新を提供します。
Microsoft DP-600 Exam Overview:
| Certification Vendor: | Microsoft |
|---|
| Exam Name: | Implementing Analytics Solutions Using Microsoft Fabric |
|---|
| Exam Number: | DP-600 |
|---|
| Available Languages: | English, Korean, Portuguese (Brazil), Spanish, French, Japanese, Simplified Chinese, German |
|---|
| Real Exam Qty: | 40-60 |
|---|
| Exam Format: | Drag and drop, Scenario-based questions, Multiple choice, Case studies |
|---|
| Passing Score: | 700 (out of 1000) |
|---|
| Certificate Validity Period: | 1 year (renewable via Microsoft certification renewal) |
|---|
| Related Certifications: | DP-900
DP-203
PL-300 |
|---|
| Exam Duration: | 120 minutes |
|---|
| Exam Price: | $165 USD (varies by country) |
|---|
| Recommended Training: | Microsoft Fabric Documentation
DP-600 Learning Path (Microsoft Learn) |
|---|
| Exam Registration: | Microsoft Certification Dashboard
Pearson VUE Microsoft Exams |
|---|
| Sample Questions: | Microsoft DP-600 Sample Questions |
|---|
| Exam Way: | Online proctored exam or in-person at Pearson VUE test centers |
|---|
| Pre Condition: | No formal prerequisites required, but familiarity with data analytics, Power BI, and Azure data services is recommended. |
|---|
| Official Syllabus URL: | https://learn.microsoft.com/credentials/certifications/fabric-analytics-engineer/ |
|---|
>> DP-600難易度受験料 <<
DP-600入門知識、DP-600日本語pdf問題
専門家と他の作業スタッフの熱心な献身により、当社のDP-600学習教材はより成熟し、困難に立ち向かうことができます。 DP-600準備試験は、業界で高い合格率を達成しており、DP-600試験問題では、絶え間ない努力で常に99%の合格率を維持しています。私たちは、このようなスターのような人物の背後に、当社からの大量投資を受け入れていることを認めなければなりません。当社の設立以来、私たちはDP-600試験資料に大量の人材、資料、資金を投入しました。
Microsoft DP-600 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - Maintain a data analytics solution: This section of the exam measures the skills of administrators and covers tasks related to enforcing security and managing the Power BI environment. It involves setting up access controls at both workspace and item levels, ensuring appropriate permissions for users and groups. Row-level, column-level, object-level, and file-level access controls are also included, alongside the application of sensitivity labels to classify data securely. This section also tests the ability to endorse Power BI items for organizational use and oversee the complete development lifecycle of analytics assets by configuring version control, managing Power BI Desktop projects, setting up deployment pipelines, assessing downstream impacts from various data assets, and handling semantic model deployments using XMLA endpoint. Reusable asset management is also a part of this domain.
|
| トピック 2 | - Implement and manage semantic models: This section of the exam measures the skills of architects and focuses on designing and optimizing semantic models to support enterprise-scale analytics. It evaluates understanding of storage modes and implementing star schemas and complex relationships, such as bridge tables and many-to-many joins. Architects must write DAX-based calculations using variables, iterators, and filtering techniques. The use of calculation groups, dynamic format strings, and field parameters is included. The section also includes configuring large semantic models and designing composite models. For optimization, candidates are expected to improve report visual and DAX performance, configure Direct Lake behaviors, and implement incremental refresh strategies effectively.
|
| トピック 3 | - Prepare data: This section of the exam measures the skills of engineers and covers essential data preparation tasks. It includes establishing data connections and discovering sources through tools like the OneLake data hub and the real-time hub. Candidates must demonstrate knowledge of selecting the appropriate storage type—lakehouse, warehouse, or eventhouse—depending on the use case. It also includes implementing OneLake integrations with Eventhouse and semantic models. The transformation part involves creating views, stored procedures, and functions, as well as enriching, merging, denormalizing, and aggregating data. Engineers are also expected to handle data quality issues like duplicates, missing values, and nulls, along with converting data types and filtering. Furthermore, querying and analyzing data using tools like SQL, KQL, and the Visual Query Editor is tested in this domain.
|
Microsoft Implementing Analytics Solutions Using Microsoft Fabric 認定 DP-600 試験問題 (Q166-Q171):
質問 # 166
You have a Fabric warehouse that contains a table named Staging.Sales. Staging.Sales contains the following columns.
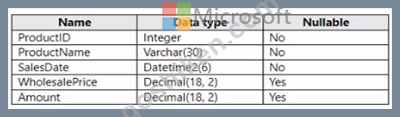
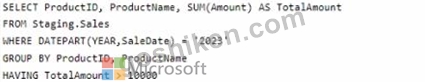
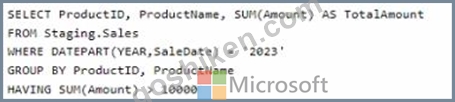
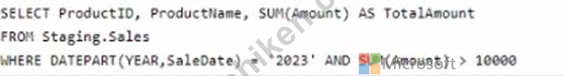
You need to write a T-SQL query that will return data for the year 2023 that displays ProductID and ProductName arxl has a summarized Amount that is higher than 10,000. Which query should you use?
正解:C
質問 # 167
You have a Fabric tenant that contains 30 CSV files in OneLake. The files are updated daily.
You create a Microsoft Power Bl semantic model named Modell that uses the CSV files as a data source. You configure incremental refresh for Model 1 and publish the model to a Premium capacity in the Fabric tenant.
When you initiate a refresh of Model1, the refresh fails after running out of resources.
What is a possible cause of the failure?
- A. The data type of the column used to partition the data has changed.
- B. Query folding is occurring.
- C. Only refresh complete days is selected.
- D. Query folding is NOT occurring.
- E. XMLA Endpoint is set to Read Only.
正解:A
質問 # 168
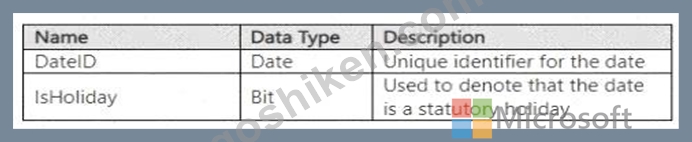
You have a Fabric warehouse that contains two tables named DimDate and Trips.
DimDate contains the following fields.
Trips contains the following fields.
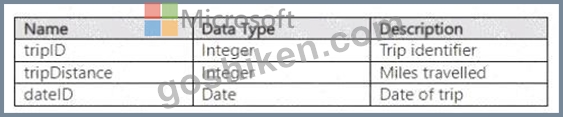
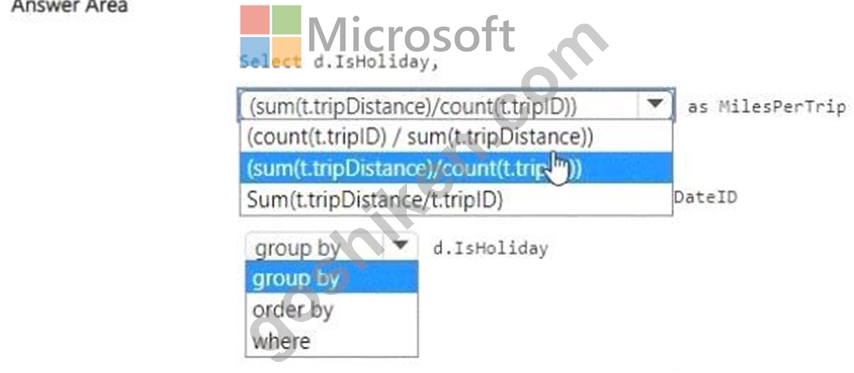
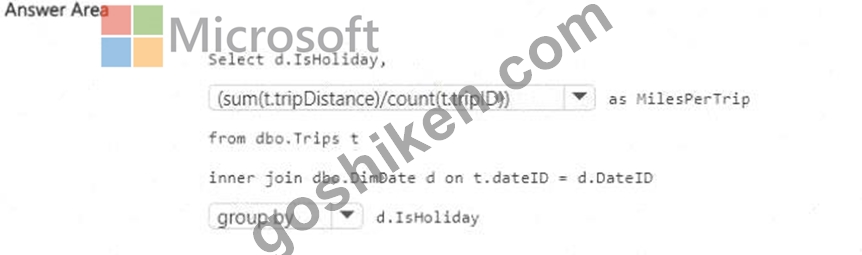
You need to compare the average miles per trip for statutory holidays versus non-statutory holidays.
How should you complete the T-SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
正解:
解説:
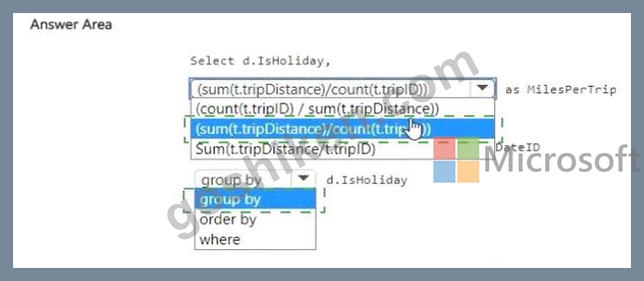
Explanation:
質問 # 169
You have a Fabric workspace named Workspace1 that contains a lakehouse named Lakehouse1.
In Workspace1. you create a data pipeline named Pipeline1.
You have CSV files stored in an Azure Storage account.
You need to add an activity to Pipeline1 that will copy data from the CSV files to Lakehouse1. The activity must support Power Query M formula language expressions.
Which type of activity should you add?
- A. Notebook
- B. Copy data
- C. Script
- D. Dataflow
正解:D
解説:
The requirement is to copy data from CSV files in Azure Storage into a Fabric Lakehouse, and it must support Power Query M formula language.
Dataflow activity in Fabric pipelines allows you to use Power Query Online, which is based on the M formula language.
Notebook uses Spark (Python, PySpark, Scala, SQL), not M.
Copy data activity moves data but does not support Power Query M transformations.
Script is for T-SQL or stored procedure execution, not M.
Therefore, the correct activity is Dataflow.
Reference: Dataflows in Microsoft Fabric
質問 # 170
You need to create a data loading pattern for a Type 1 slowly changing dimension (SCD).
Which two actions should you include in the process? Each correct answer presents part of the solution.
NOTE: Each correct answer is worth one point.
- A. Insert new records when the natural key is a new value in the table.
- B. Update the effective end date of rows when the non-key attribute values have changed.
- C. Insert new rows when the natural key exists in the dimension table, and the non-key attribute values have changed.
- D. Update rows when the non-key attributes have changed.
正解:A、D
解説:
For a Type 1 SCD, you should include actions that update rows when non-key attributes have changed (A), and insert new records when the natural key is a new value in the table (D). A Type 1 SCD does not track historical data, so you always overwrite the old data with the new data for a given key. References = Details on Type 1 slowly changing dimension patterns can be found in data warehousing literature and Microsoft's official documentation.
質問 # 171
......
DP-600入門知識: https://www.goshiken.com/Microsoft/DP-600-mondaishu.html
- 信頼できるDP-600難易度受験料 - 合格スムーズDP-600入門知識 | 真実的なDP-600日本語pdf問題 🧺 ▶ jp.fast2test.com ◀から簡単に[ DP-600 ]を無料でダウンロードできますDP-600全真問題集
- 素敵なDP-600難易度受験料 - 合格スムーズDP-600入門知識 | 実際的なDP-600日本語pdf問題 ⚽ ➡ www.goshiken.com ️⬅️で➡ DP-600 ️⬅️を検索し、無料でダウンロードしてくださいDP-600テストサンプル問題
- 最高のDP-600難易度受験料一回合格-ハイパスレートのDP-600入門知識 🪁 検索するだけで《 www.xhs1991.com 》から☀ DP-600 ️☀️を無料でダウンロードDP-600試験問題集
- 素敵なDP-600難易度受験料試験-試験の準備方法-ユニークなDP-600入門知識 🍕 今すぐ「 www.goshiken.com 」を開き、➤ DP-600 ⮘を検索して無料でダウンロードしてくださいDP-600日本語サンプル
- 信頼できるDP-600難易度受験料 - 合格スムーズDP-600入門知識 | 真実的なDP-600日本語pdf問題 🍗 今すぐ《 www.xhs1991.com 》を開き、⮆ DP-600 ⮄を検索して無料でダウンロードしてくださいDP-600学習資料
- 最新のDP-600難易度受験料を今すぐダウンロード 🍄 《 www.goshiken.com 》サイトで【 DP-600 】の最新問題が使えるDP-600コンポーネント
- DP-600練習問題 🏭 DP-600復習資料 😫 DP-600日本語版参考書 💂 ➤ www.jptestking.com ⮘サイトで{ DP-600 }の最新問題が使えるDP-600トレーリング学習
- 最高のDP-600難易度受験料一回合格-ハイパスレートのDP-600入門知識 🧜 { www.goshiken.com }で▶ DP-600 ◀を検索して、無料で簡単にダウンロードできますDP-600日本語版サンプル
- DP-600関連資格知識 🦜 DP-600認定デベロッパー 👨 DP-600最新試験 🚛 ⇛ www.mogiexam.com ⇚で“ DP-600 ”を検索して、無料でダウンロードしてくださいDP-600テストサンプル問題
- DP-600関連資格知識 🐲 DP-600日本語版サンプル 🍪 DP-600資格認定試験 🐦 [ DP-600 ]を無料でダウンロード「 www.goshiken.com 」ウェブサイトを入力するだけDP-600関連日本語版問題集
- ユニークMicrosoft DP-600|更新するDP-600難易度受験料試験|試験の準備方法Implementing Analytics Solutions Using Microsoft Fabric入門知識 ⚗ 【 www.passtest.jp 】に移動し、⇛ DP-600 ⇚を検索して、無料でダウンロード可能な試験資料を探しますDP-600テストサンプル問題
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S.GoShikenがGoogle Driveで共有している無料の2026 Microsoft DP-600ダンプ:https://drive.google.com/open?id=1fWSzPJmPtqBvxy4_jjnFShM4BynHsvCb