What's more, part of that Dumpexams Databricks-Certified-Data-Engineer-Professional dumps now are free: https://drive.google.com/open?id=1wdWtr2QRvPGDMyLjjACQTicqpj3nTcPC
Thanks to modern technology, learning online gives people access to a wider range of knowledge, and people have got used to convenience of electronic equipment. As you can see, we are selling our Databricks-Certified-Data-Engineer-Professional learning guide in the international market, thus there are three different versions of our Databricks-Certified-Data-Engineer-Professional exam materials: PDF, Soft and APP versions. It is worth mentioning that, the simulation test of our Databricks-Certified-Data-Engineer-Professional Study Guide is available in our software version. With the simulation test, all of our customers will get accustomed to the Databricks-Certified-Data-Engineer-Professional exam easily, and pass the exam with confidence.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Processing | 28% | - Structured Streaming - Spark SQL - Data Transformation - ETL Pipelines |
| Topic 2: Data Modeling and Storage | 20% | - Storage Optimization - Data Modeling - File Formats |
| Topic 3: Data Quality and Governance | 12% | - Governance - Data Quality - Data Lineage |
| Topic 4: Databricks Lakehouse Platform | 24% | - Delta Lake - Unity Catalog - Lakehouse Architecture - Data Management |
| Topic 5: Monitoring and Troubleshooting | 16% | - Monitoring - Troubleshooting - Performance Optimization |
>> Databricks-Certified-Data-Engineer-Professional Reliable Test Forum <<
Our company according to the situation reform on conception, question types, designers training and so on. Our latest Databricks-Certified-Data-Engineer-Professional exam torrent was designed by many experts and professors. You will have the chance to learn about the demo for if you decide to use our Databricks-Certified-Data-Engineer-Professional quiz prep. We can sure that it is very significant for you to be aware of the different text types and how best to approach them by demo. At the same time, our Databricks-Certified-Data-Engineer-Professional Quiz torrent has summarized some features and rules of the cloze test to help customers successfully pass their exams. More importantly, you have the opportunity to get the demo of our latest Databricks-Certified-Data-Engineer-Professional exam torrent for free, yes, you read that right, and our demo is free. So why still hesitate?
NEW QUESTION # 175
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed: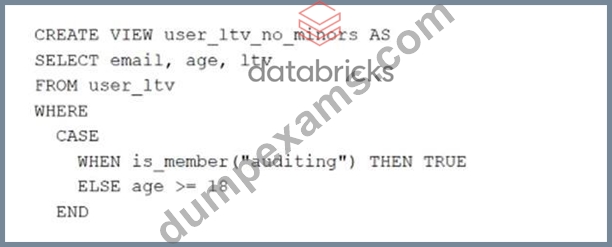
An analyst who is not a member of the auditing group executes the following query:
SELECT * FROM user_ltv_no_minors
Which statement describes the results returned by this query?
Answer: D
Explanation:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 176
A data engineer manages a production Lakeflow Declarative Pipeline that processes customer transaction data. The pipeline includes several data quality expectations such as transaction_amount > 0 and customer_id IS NOT NULL. These expectations are defined using the EXPECT clause in SQL.
The engineer aims to monitor the pipeline's data quality by analyzing the number of records that passed or failed each expectation during the latest pipeline update. The Lakeflow Declarative Pipelines event logs are stored in a Delta table named event_log_table.
For the most recent pipeline update, determine a programmatically appropriate approach to extract information like the name of each expectation, associated dataset, count of records that passed the expectation, and count of records that failed the expectation.
Which method retrieves the desired data quality metrics from the Lakeflow Declarative Pipelines event log?
Answer: A
Explanation:
The Databricks documentation specifies that for Lakeflow Declarative Pipelines, detailed data quality metrics are logged as events of type expectation_result within the event log. Each record of this type contains fields including expectation_name, dataset_name, passed_records, and failed_records. Filtering on event_type = 'expectation_result' and expanding the details field allows retrieving metrics for each expectation from the most recent pipeline update. While flow_progress provides summary statistics and data_quality events aggregate results, only expectation_result events provide granular, per-expectation metrics required for audit and monitoring automation.
NEW QUESTION # 177
A nightly batch job is configured to ingest all data files from a cloud object storage container where records are stored in a nested directory structure YYYY/MM/DD. The data for each date represents all records that were processed by the source system on that date, noting that some records may be delayed as they await moderator approval. Each entry represents a user review of a product and has the following schema:
user_id STRING, review_id BIGINT, product_id BIGINT, review_timestamp TIMESTAMP, review_text STRING The ingestion job is configured to append all data for the previous date to a target table reviews_raw with an identical schema to the source system. The next step in the pipeline is a batch write to propagate all new records inserted into reviews_raw to a table where data is fully deduplicated, validated, and enriched.
Which solution minimizes the compute costs to propagate this batch of data?
Answer: C
Explanation:
https://www.databricks.com/blog/2017/05/22/running-streaming-jobs-day-10x-cost-savings.html
NEW QUESTION # 178
A Delta table of weather records is partitioned by date and has the below schema:
date DATE, device_id INT, temp FLOAT, latitude FLOAT, longitude FLOAT
To find all the records from within the Arctic Circle, you execute a query with the below filter:
latitude > 66.3
Which statement describes how the Delta engine identifies which files to load?
Answer: C
Explanation:
This is the correct answer because Delta Lake uses a transaction log to store metadata about each table, including min and max statistics for each column in each data file. The Delta engine can use this information to quickly identify which files to load based on a filter condition, without scanning the entire table or the file footers. This is called data skipping and it can improve query performance significantly. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; [Databricks Documentation], under "Optimizations - Data Skipping" section.
In the Transaction log, Delta Lake captures statistics for each data file of the table. These statistics indicate per file:
- Total number of records
- Minimum value in each column of the first 32 columns of the table
- Maximum value in each column of the first 32 columns of the table
- Null value counts for in each column of the first 32 columns of the table When a query with a selective filter is executed against the table, the query optimizer uses these statistics to generate the query result. it leverages them to identify data files that may contain records matching the conditional filter.
For the SELECT query in the question, The transaction log is scanned for min and max statistics for the price column.
NEW QUESTION # 179
A data engineering team is setting up deployment automation. To deploy workspace assets remotely using the Databricks CLI command, they must configure it with proper authentication.
Which authentication approach will provide the highest level of security?
Answer: D
Explanation:
The most secure and enterprise-recommended authentication method for Databricks automation is OAuth token federation with service principals.
This configuration allows service principals (non-human identities) to authenticate using temporary OAuth access tokens from a trusted identity provider (such as Azure AD or AWS IAM federation). These tokens are short-lived and scoped, significantly reducing credential exposure risks.
By contrast, static client secrets (B) or PATs (C) are long-lived and require periodic manual rotation, increasing security vulnerability. Shared user accounts (D) violate least-privilege and auditability principles. Therefore, A provides the strongest, most compliant authentication model for automated CLI and CI/CD workflows.
NEW QUESTION # 180
......
Our study material is not same as other dumps or study tools, it not only has good quality but also has cheap price. We have most professional team to compiled and revise Databricks-Certified-Data-Engineer-Professional exam question, in order to try our best to help you pass the exam and get a better condition of your life and your work. Moreover, only need to spend 20-30 is it enough for you to grasp whole content of Databricks-Certified-Data-Engineer-Professional practice materials that you can pass the exam easily, this is simply unimaginable.
Valid Dumps Databricks-Certified-Data-Engineer-Professional Sheet: https://www.dumpexams.com/Databricks-Certified-Data-Engineer-Professional-real-answers.html
2026 Latest Dumpexams Databricks-Certified-Data-Engineer-Professional PDF Dumps and Databricks-Certified-Data-Engineer-Professional Exam Engine Free Share: https://drive.google.com/open?id=1wdWtr2QRvPGDMyLjjACQTicqpj3nTcPC