BTW, DOWNLOAD part of DumpsActual AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1m1ZzjoAYdMYOq-yk9IV-qNyh9dTRRlRU
With our AI-300 test prep, you don't have to worry about the complexity and tediousness of the operation. Our AI-300 exam torrent is available in different versions. Whether you like to study on a computer or enjoy reading paper materials, our test prep can meet your needs. Our PDF version of the AI-300 quiz guide is available for customers to print. You can print it out, so you can practice it repeatedly conveniently. And our AI-300 Exam Torrent make it easy for you to take notes on it so that your free time can be well utilized and you can often consolidate your knowledge. Everything you do will help you successfully pass the exam and get the card.
| Section | Objectives |
|---|---|
| Optimize generative AI systems and model performance | - Implement cost management and scaling strategies for GenAI workloads - Optimize inference performance, caching, and throughput - Fine-tune and distill models for specific use cases - Tune prompts, system messages, and grounding strategies |
| Design and implement an MLOps infrastructure | - Manage environments, data stores, and model registries - Implement security, governance, and compliance for MLOps - Configure source control, CI/CD pipelines, and automation for ML workflows - Set up Azure Machine Learning workspace and compute targets |
| Implement generative AI quality assurance and observability | - Monitor latency, token usage, cost, and error rates - Implement logging, tracing, and telemetry for GenAI applications - Conduct red teaming, adversarial testing, and content filtering - Evaluate generative AI outputs for quality, safety, and grounding |
| Design and implement a GenAIOps infrastructure | - Manage API keys, rate limits, and responsible AI guardrails - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Configure prompt orchestration, prompt flows, and agent frameworks - Set up Microsoft Foundry and Azure AI services for generative AI workloads |
| Implement machine learning model lifecycle and operations | - Retrain, update, and manage model versions in production - Monitor model performance, data drift, and operational health - Train, register, and version models using Azure Machine Learning - Deploy models to real-time and batch endpoints |
>> Valid AI-300 Practice Materials <<
One of the top features of Microsoft AI-300 exam dumps is the AI-300 exam passing a money-back guarantee. In other words, your investments with DumpsActual Links to an external site. Microsoft Operationalizing Machine Learning and Generative AI Solutions exam questions are secured with the 100 Operationalizing Machine Learning and Generative AI Solutions AI-300 Exam passing a money-back guarantee. Due to any reason, if you did not succeed in the final AI-300 exam despite using DumpsActual AI-300 pdf questions and practice tests, we will return your whole payment without any deduction.
NEW QUESTION # 61
You create an Azure Machine Learning workspace.
You must use the Python SDK v2 to implement an experiment from a Jupiter notebook in the workspace. The experiment must log string metrics.
You need to implement the method to log the string metrics.
Which method should you use?
Answer: C
NEW QUESTION # 62
A data science team trains a classification model that predicts loan approval outcomes.
Before registering the model, the team must ensure the following:
- Predictions must not disproportionately impact protected groups.
- Prediction errors can be evaluated across different data segments.
You need to assess whether the model meets Responsible AI expectations.
Which two approaches should you use? Each correct answer presents part of the solution.
Choose two.
NOTE: Each correct selection is worth one point.
Answer: C,E
Explanation:
[D]
To evaluate a trained loan classification model for Responsible AI expectations--ensuring no disproportionate impact on protected groups, evaluating error across segments, and verifying prediction transparency--you can employ SHAP (SHapley Additive exPlanations) values to assess feature importance.
This approach allows you to identify which variables (e.g., credit history, debt levels) drive the model's predictions, fostering trust and fairness.
Feature Importance for Transparency: Use SHAP (model-agnostic) or LIME (local approximations) to explain why the model approved or denied a loan. These techniques identify how each feature contributes to individual predictions.
[E]
To ensure a trained loan approval classification model meets responsible AI expectations-- specifically, that it does not disproportionately impact protected groups and that errors can be evaluated across segments--you should analyze error rates across defined demographic cohorts using Fairness-Aware Machine Learning metrics.
Reference:
https://urfpublishers.com/journal/artificial-intelligence/article/view/explainable-aiml-testing- ensuring-transparency-accountability-and-compliance
https://timvero.com/blog/ethics-in-automated-lending-can-ai-make-fair-credit-decisions
NEW QUESTION # 63
A team plans to deploy a large foundation model in Microsoft Foundry as part of a new enterprise AI capability.
Different business units across the team's organization will access the model from various internal applications.
You need to deploy a foundation model by minimizing latency.
Which deployment type should you use?
Answer: C
Explanation:
In this scenario, Data Zone Standard is the most appropriate deployment type for minimizing latency.
While other options cater to high-volume or testing needs, Data Zone Standard is specifically designed for real-time application traffic with a balance of performance and regional availability.
Why Data Zone Standard is the Correct Choice
Real-Time Processing: Unlike the "Batch" options, Data Zone Standard is built for synchronous, real-time requests from internal applications, ensuring the low latency required for interactive user experiences.
Dynamic Routing: It dynamically routes traffic to the most available data centers within a specific Microsoft-defined data zone (e.g., US or EU), which helps maintain responsiveness even if one region experiences high load.
Higher Quotas: It offers higher default throughput (TPM/RPM) than standard regional deployments, allowing multiple business units to access the model simultaneously without hitting restrictive limits that could cause queuing and latency spikes.
Incorrect:
[Not A]
Developer: This deployment type is typically used for initial testing, prototyping, and experimentation rather than high-performance production workloads accessed by many different business units.
[Not B, not D]
Global Batch & Data Zone Batch: These are asynchronous deployment types. They are designed for processing large datasets (like document summaries or mass sentiment analysis) with a 24- hour turnaround time. While they are 50% cheaper, they are not suitable for real-time applications where immediate response is needed.
Reference:
https://learn.microsoft.com/en-us/azure/foundry/foundry-models/concepts/deployment-types
NEW QUESTION # 64
You manage an Azure Machine Learning workspace named Workspace1.
You plan to create a pipeline in the Azure Machine Learning Studio designer. The pipeline must include a custom component You need to ensure the custom component can be used in the pipeline. What should you do first.
Answer: D
Explanation:
Topic 1, Fabrikam Inc.Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States. Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions. Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support.
Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets Azure AI Search indexing curated analytical documents and reference materials A small set of Python-based training scripts maintained by data scientists Azure OpenAI Service with deployed foundational models A Microsoft Foundry resource for building a RAG-based solution Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
Model training jobs are run manually from notebooks.
Experiment tracking is inconsistent
Model versions are registered without standardized metadata.
Deployment is performed manually by data scientists, with limited rollback capability.
The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities.
Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
Provide a conversational interface that answers analytics questions by using internal documents and datasets.
Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
Enable repeatable and auditable model training and deployment processes.
Support experimentation to compare prompt strategies and fine-tuned models.
Align the model with the ranked preferences and optimize behavior for the long term.
Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
Implement experiment tracking and model versioning for all training jobs.
Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
Deploy traditional machine learning models with support for staged rollout and rollback.
Improve RAG-based solution output quality.
Use the existing evaluation datasets that are based on real data with input-output pairs.
Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
NEW QUESTION # 65
Hotspot Question
You manage an Azure Machine Learning workspace named workspace1.
You must register an Azure Blob storage datastore in workspace1 by using an access key. You develop Python SDK v2 code to import all modules required to register the datastore.
You need to complete the Python SDK v2 code to define the datastore.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.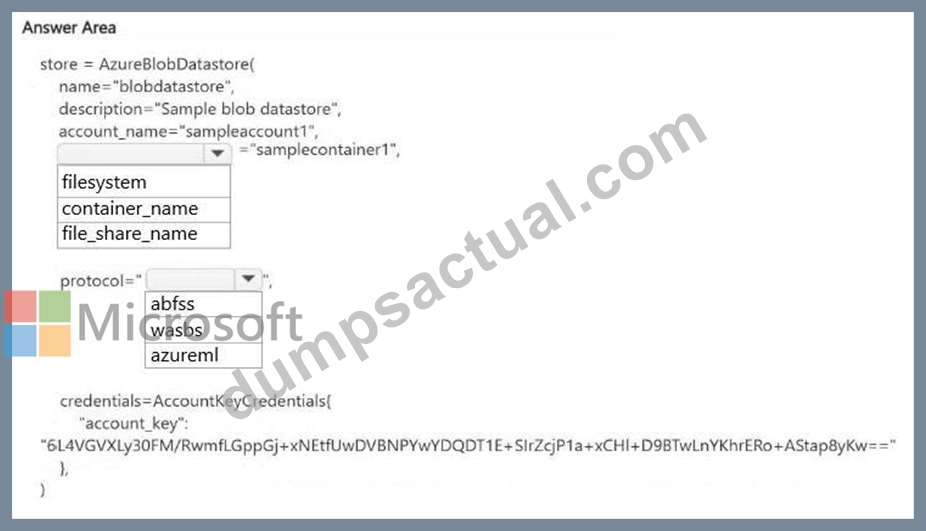
Answer:
Explanation: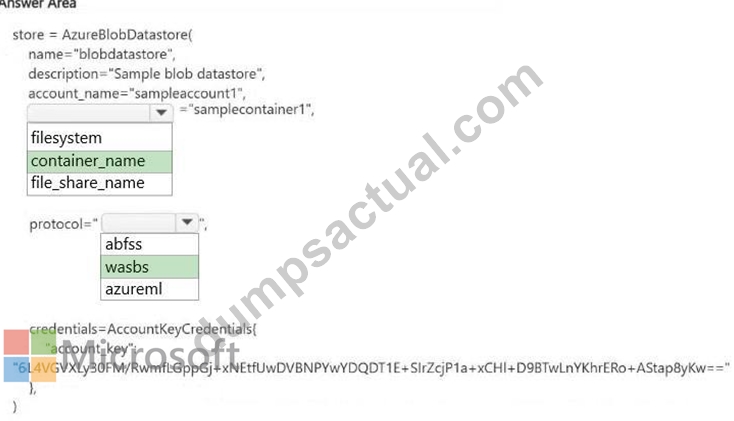
Explanation:
How should you complete the code?
Box 1: container_name
container_name specifies the parameter name used in the AzureBlobDatastore constructor to identify your target blob storage container.
Box 2: wasbs
Correct Code Formats
Depending on your preference for the storage connection protocol, your completed line of code should look like one of the following variations:
Using the standard HTTPS protocol (Default).
-> Using the WASBS (Windows Azure Storage Blob Secure).
Reference:
https://stackoverflow.com/questions/75275875/create-an-azureblobdatastore-with-sdk-v2
NEW QUESTION # 66
......
These AI-300 practice exams train you to manage time so that you can solve questions of the AI-300 real test on time. DumpsActual offers Microsoft practice tests which provide you with real examination scenarios. By practicing under the pressure of AI-300 real test again and again, you can overcome your Operationalizing Machine Learning and Generative AI Solutions exam anxiety. Taking AI-300 these practice exams is important for you to attempt Microsoft real dumps questions and pass AI-300 certification exam test on the first take.
Latest AI-300 Test Guide: https://www.dumpsactual.com/AI-300-actualtests-dumps.html
DOWNLOAD the newest DumpsActual AI-300 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1m1ZzjoAYdMYOq-yk9IV-qNyh9dTRRlRU