ITDumpsKR는Microsoft DP-750인증시험의 촉매제 같은 사이트입니다.Microsoft DP-750인증시험 관연 덤프가 우리ITDumpsKR에서 출시되었습니다. 여러분이Microsoft DP-750인증시험으로 나 자신과 자기만의 뛰어난 지식 면을 증명하고 싶으시다면 우리 ITDumpsKR의Microsoft DP-750덤프자료가 많은 도움이 될 것입니다.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
ITDumpsKR 의 IT전문가들이 자신만의 경험과 끊임없는 노력으로 최고의 Microsoft DP-750학습자료를 작성해 여러분들이Microsoft DP-750시험에서 패스하도록 최선을 다하고 있습니다. 덤프는 최신 시험문제를 커버하고 있어 시험패스율이 높습니다. Microsoft DP-750시험을 보기로 결심한 분은 가장 안전하고 가장 최신인 적중율 100%에 달하는Microsoft DP-750시험대비덤프를 ITDumpsKR에서 받을 수 있습니다.
질문 # 39
Case Study 1 - Contoso, Inc.
Overview
Company Information
Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
Existing Environment
Azure Environment
Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
Workspace1 contains all-purpose clusters for both development and production workloads.
The company's Azure environment contains:
- In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
- A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
- An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Data Environment Contoso ingests the following operational and business data:
- Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
- Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
- Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
- External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
- ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
Problem Statements
The company's existing analytics environment has several issues:
Ingestion
- Telemetry pipelines fall behind during peak loads.
- Telemetry ingestion fails when schema drift occurs.
- Streaming pipelines reprocess events after a pipeline restarts.
Compute
Production and development workloads run on the same all-purpose clusters.
Production and development workloads do NOT support autoscaling or workload isolation.
Governance
- The ERP data is duplicated across systems and development teams.
- Naming conventions are inconsistent across development teams, regions, and products.
- Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
- Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names.
Historical values are NOT required.
Pipeline operations
- Pipelines lack resiliency, alerting, and centralized scheduling.
Requirements
Planned Changes
Contoso plans to implement the following changes:
- Implement scalable data pipeline orchestration.
- Create a managed analytics catalog in Unity Catalog.
- Implement a consistent approach to creating curated datasets.
- Establish a centralized governance model across ingestion, cleansed, and curated layers.
- Grant data engineers access to the ERP tables by using minimal development effort.
- Adopt a compute strategy that isolates production workloads and supports autoscaling.
- Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
Technical Requirements
Contoso identifies the following environment and compute requirements:
- Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
- Provide fast and consistent performance for business intelligence (BI) workloads.
- Prevent development activity from affecting production pipelines.
- Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Contoso identifies the following data ingestion and processing requirements:
- Auto-scale ingestion pipelines to handle bursty workloads.
- Handle schema drift for the maintenance and telemetry data.
- Ingest file-based telemetry data by using minimal operational effort.
- Store all the ingested data in a format that supports incremental processing.
- Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
- Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
- Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
- Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
Contoso identifies the following data modeling and optimization requirements:
- Build curated tables that standardize business logic.
- Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
Contoso identifies the following pipeline deployment and operation requirements:
- Orchestrate multi-step ingestion and transformation workflows.
- Define a clear execution order and dependencies.
- Automatically retry failed steps and notify operators.
- Schedule ingestion and transformation workloads consistently.
Governance Requirements
Contoso identifies the following governance requirements:
- Centralize the metadata catalog.
- Provide isolated development areas that follow standard naming conventions.
- Establish a consistent structure for organizing raw, cleansed, and curated data.
- Provide a read-only mechanism to reference the ERP data through a foreign catalog.
Business Requirements
Contoso identifies the following business requirements:
- Improve ingestion reliability and reduce operational effort.
- Standardize data definitions across development teams.
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements. What should you do?
정답:A
설명:
Enabling Photon acceleration on a job compute cluster is the best option. It significantly speeds up data engineering pipelines, handles JSON file ingestion seamlessly, and optimizes cost- efficiency for bursty production workloads, which are key for processing rapidly arriving IoT sensor events.
Enable Photon acceleration for a job compute cluster:
Databricks Auto Loader is designed for low-latency, high-volume file ingestion. Running Auto Loader on a job compute cluster provides the lowest operational cost because job clusters are billed at a much lower rate than all-purpose clusters.
Enabling Photon acceleration heavily optimizes the ingestion, parsing, and processing of raw JSON data strings, allowing the cluster to handle bursty workloads faster and auto-scale more efficiently.
Scenario, Data Environment, Contoso ingests the following operational and business data:
Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
Contoso identifies the following data ingestion and processing requirements:
-> Auto-scale ingestion pipelines to handle bursty workloads.
Handle schema drift for the maintenance and telemetry data.
-> Ingest file-based telemetry data by using minimal operational effort.
Reference:
https://medium.com/@krthiak/10-days-of-data-engineering-interview-qna-day-5-db1c0b58bf86
질문 # 40
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You need to configure Cluster1 to meet the following requirements:
- The cluster must scale up automatically when workloads increase.
- The cluster must scale down automatically when workloads decrease.
The solution must minimize costs.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
정답:C,E
설명:
Enabling autoscaling and setting a 30-minute auto-termination timeout is the correct configuration to meet the goals.
Autoscaling handles fluctuating workloads, while auto-termination prevents you from paying for idle compute resources.
Dynamic Scaling: Autoscaling automatically adds workers during high loads and removes them when demand drops.
Cost Control: The 30-minute termination window ensures the cluster shuts down completely if no jobs are running, stopping all compute charges.
Reference:
https://community.databricks.com/t5/get-started-discussions/cluster-auto-termination-best- practices/td-p/75826
질문 # 41
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to create an external volume named Volume1 in an existing schema. Volume1 must expose files from an Azure Storage container. The solution must meet the following requirements:
* Ensure that authentication does NOT require storing credentials in Databricks
* Ensure that users can access the files, but NOT modify the files.
* Follow the principle of least privilege
Which type of authentication should you configure, and which permission should you grant to the users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.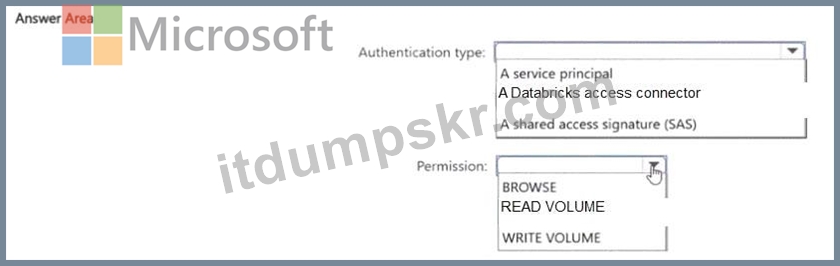
정답:
설명: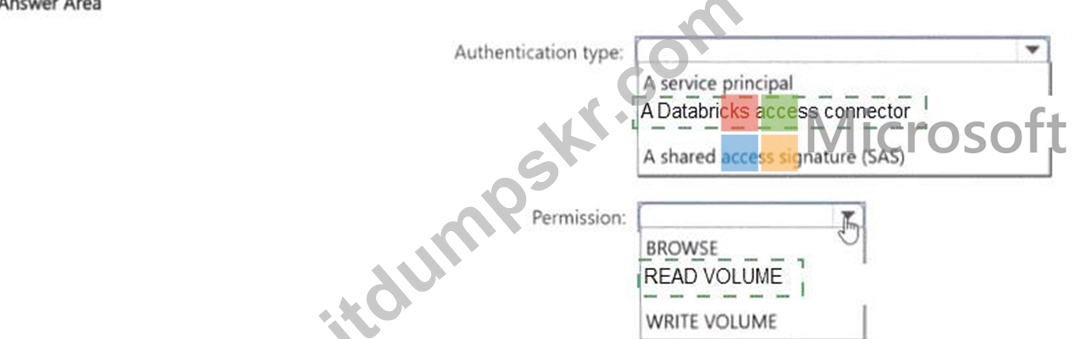
Explanation:
For authentication, a Managed Identity (via a Databricks Access Connector) is the right choice. The Access Connector wraps an Azure-managed identity so Databricks can authenticate to Azure Storage without any credentials being stored in the workspace. The cloud security team controls the identity through Azure RBAC
- there are no secrets to rotate or leak inside Databricks.
For the permission, READ FILES on the volume is exactly right. It allows users to read and list files through the volume path while blocking writes, deletes, and modifications. This is the minimum necessary access, honouring the principle of least privilege.
WRITE FILES would allow modifications, contradicting 'users can access but NOT modify.' ALL PRIVILEGES grants far more than needed. Service principals with stored client secrets would mean credentials inside Databricks, violating the 'does not require storing credentials' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/volumes
질문 # 42
You have an Azure Databricks workspace.
Users report that a Databricks notebook that runs each day takes longer than expected to run.
When reading the Directed Acyclic Graph (DAG), you discover the following issues concerning the Apache Spark stage:
* Most tasks in the stage finish quickly.
* A few tasks in the stage run more slowly.
* The CPU is underutilized at the end of the stage.
* The slow tasks process many more input records.
* The stage is blocked while it waits for the few slow tasks.
What is the root cause of the issues?
정답:D
질문 # 43
You have an Azure Databricks workspace that uses serverless compute.
You need to ingest data by using Lakeflow Jobs. New records must be processed as soon as they become available.
Which type of job trigger should you use for the ingestion?
정답:D
설명:
The correct answer is D - Continuous trigger.
A Continuous trigger keeps the job running as a perpetual loop. As soon as one micro-batch or iteration completes, the next begins. New records are picked up with the shortest possible latency - as close to real- time as a Lakeflow Jobs pipeline gets.
File Arrival (Option B) is event-driven but introduces per-file trigger overhead and is best suited for file-based ingestion rather than continuous streaming workloads. Scheduled (Option C) runs at fixed clock intervals - if new data arrives between runs, it waits until the next scheduled execution. Manual (Option A) requires a human to start each run.
The question specifies serverless compute, which pairs naturally with Continuous trigger because serverless handles cluster lifecycle automatically - the job stays active without managing a persistent cluster. 'New records must be processed as soon as they become available' is the exact use case the Continuous trigger is designed for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/triggers
질문 # 44
......
우리ITDumpsKR 에서는 여러분들한테 아주 편리하고 시간 절약함과 바꿀 수 있는 좋은 대책을 마련하였습니다. ITDumpsKR에서는Microsoft DP-750인증시험관련가이드로 효과적으로Microsoft DP-750시험을 패스하도록 도와드리겠습니다.만약 여러분이 다른 사이트에서도 관련덤프자료를 보셨을 경우 페이지 아래를 보시면 자료출처는 당연히 ITDumpsKR 일 것입니다. ITDumpsKR의 자료만의 제일 전면적이고 또 최신 업데이트일것입니다.
DP-750 PDF: https://www.itdumpskr.com/DP-750-exam.html