BTW, DOWNLOAD part of iPassleader DY0-001 dumps from Cloud Storage: https://drive.google.com/open?id=1pUcTCXu5oAWBHj010q5sSj30vrwrKNK6
There may be customers who are concerned about the installation or use of our DY0-001 training questions. You don't have to worry about this. In addition to high quality and high efficiency, considerate service is also a big advantage of our company. We will provide 24 - hour online after-sales service to every customer. If you have any questions about installing or using our DY0-001 Real Exam, our professional after-sales service staff will provide you with warm remote service. As long as it is about our DY0-001 learning materials, we will be able to solve. Whether you're emailing or contacting us online, we'll help you solve the problem as quickly as possible. You don't need any worries at all.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
Have you been many years at your position but haven't got a promotion? Or are you a new comer in your company and eager to make yourself outstanding? Our DY0-001 exam materials can help you. With our DY0-001 exam questions, you can study the most latest and specialized knowledge to deal with the problems in you daily job as well as get the desired DY0-001 Certification. You can lead a totally different and more successfully life latter on.
NEW QUESTION # 54
Which of the following environmental changes is most likely to resolve a memory constraint error when running a complex model using distributed computing?
Answer: D
Explanation:
When running a model on a distributed system, encountering memory constraint errors indicates that the current nodes in the cluster do not have enough memory to handle the model. The most scalable and immediate solution is:
# Adding Nodes to a Cluster Deployment - This increases the total available memory and compute power. In distributed computing environments like Apache Spark or Hadoop, horizontal scaling via node addition is a standard remedy for resource bottlenecks, including memory limitations.
Why the other options are incorrect:
* A. Containerizing doesn't inherently solve memory issues unless paired with resource upgrades.
* B. Cloud migration may offer more resources, but without scaling configuration, memory limits may persist.
* C. Edge deployment is for low-latency, local processing - often with less memory, not more.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 5.2 (Infrastructure & Scaling):"To resolve memory limitations in distributed systems, scaling out by adding nodes is the most direct and cost- effective method."
* Data Engineering Fundamentals (Cloud/Distributed Systems):"Cluster resource constraints (e.g., memory) can be mitigated by increasing node count, enabling parallel execution and expanded memory pools."
-
NEW QUESTION # 55
A data scientist is attempting to identify sentences that are conceptually similar to each other within a set of text files. Which of the following is the best way to prepare the data set to accomplish this task after data ingestion?
Answer: C
Explanation:
# Embeddings (e.g., word2vec, sentence transformers) are vector representations of text that capture semantic similarity. They allow comparison of conceptual meaning between sentences in a high-dimensional space, which is essential for tasks like semantic similarity or clustering.
Why the other options are incorrect:
* B: Extrapolation predicts values beyond a dataset's range - not relevant here.
* C: Sampling reduces data volume but doesn't aid in similarity analysis.
* D: One-hot encoding captures presence of words but lacks semantic understanding.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 6.3:"Embeddings transform text into numeric vectors, enabling similarity computation and semantic analysis."
-
NEW QUESTION # 56
Which of the following measures would a data scientist most likely use to calculate the similarity of two text strings?
Answer: D
Explanation:
Edit distance quantifies how many single-character insertions, deletions, or substitutions are needed to transform one string into another, making it a direct measure of their similarity.
NEW QUESTION # 57
A data scientist is designing a real-time machine-learning model that classifies a user based on initial behavior. The run times of these models are provided in the following table: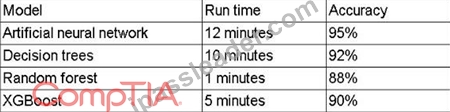
Which of the following models should the data scientist recommend for deployment?
Answer: C
Explanation:
# In real-time systems, low latency (short run time) is critical. While the Artificial Neural Network provides the highest accuracy, its 12-minute runtime makes it unsuitable for real-time inference. Random forest is the fastest but offers the lowest accuracy.
XGBoost provides an excellent balance between runtime (5 minutes) and accuracy (90%). It's well-optimized for performance and scalability, and thus is a strong candidate for real-time classification when balancing both efficiency and predictive quality.
Why the other options are less ideal:
* B: Random forest is faster but significantly less accurate.
* C: Decision trees have longer run time than XGBoost with only a 2% accuracy improvement.
* D: Artificial neural network has the highest accuracy but is too slow for real-time applications.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 4.3:"In real-time applications, model selection involves a trade-off between accuracy and inference speed. XGBoost offers competitive accuracy with efficient runtime."
* Machine Learning Systems Design Guide, Chapter 7:"XGBoost is well-suited for real-time systems due to its balance of model complexity and fast prediction times."
-
NEW QUESTION # 58
Which of the following distance metrics for KNN is best described as a straight line?
Answer: B
Explanation:
# Euclidean distance is the most intuitive distance metric. It measures the shortest "straight-line" distance between two points in Euclidean space. This is typically used in KNN and clustering when features are continuous and appropriately scaled.
Why the other options are incorrect:
* A: "Radial" isn't a standard distance metric; may refer vaguely to radial basis functions.
* C: Cosine measures the angle (orientation) between vectors - not straight-line distance.
* D: Manhattan distance sums the absolute differences across dimensions - visualized as block-like (taxicab) paths, not direct lines.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.4:"Euclidean distance is the default metric in KNN for measuring straight-line proximity in feature space."
* Data Mining Techniques, Chapter 3:"Euclidean distance represents the shortest path between two points and is widely used in distance-based learning algorithms."
-
NEW QUESTION # 59
......
As long as you are willing to exercise on a regular basis, the exam will be a piece of cake, because what our DY0-001 practice questions include are quintessential points about the exam. They are almost all the keypoints and the latest information contained in our DY0-001 Study Materials that you have to deal with in the real exam. And we have high pass rate of our DY0-001 exam questions as 98% to 100%. It is hard to find in the market.
DY0-001 Valid Test Prep: https://www.ipassleader.com/CompTIA/DY0-001-practice-exam-dumps.html
DOWNLOAD the newest iPassleader DY0-001 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1pUcTCXu5oAWBHj010q5sSj30vrwrKNK6