Exam Certified-Data-Engineer-Professional Material | Test Certified-Data-Engineer-Professional Engine Version

The rapid development of information will not infringe on the learning value of our Certified-Data-Engineer-Professional exam questions, because our customers will have the privilege to enjoy the free update of our Certified-Data-Engineer-Professional learing materials for one year. You will receive the renewal of Certified-Data-Engineer-Professional study files through the email. And our Certified-Data-Engineer-Professional study files have three different version can meet your demands: PDF, Soft and APP version. Meanwhile, we offer our customers with consideralbe services for 24/7, as long as you contact us on our Certified-Data-Engineer-Professional exam questions, we will give you the best suggestions.
| Section | Objectives |
|---|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Analyze errors and remediate failed job runs
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use system tables for resource, cost, audit, and workload monitoring
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use Query Profiler and Spark UI to monitor workloads
- 4. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest data from message buses and cloud storage
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Data Sharing and Federation | - Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Share live Lakehouse data with external computing platforms
- 3. Configure Databricks-to-Databricks Sharing
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Ensuring Data Security and Compliance | - Data Security
- 1. Use ACLs to secure workspace objects and enforce least privilege
- 2. Apply anonymization and pseudonymization techniques
- 3. Use row filters and column masks for sensitive data
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Design and implement scalable data models using Delta Lake
|
| Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
- Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
|
| Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Apply data skipping and file pruning techniques
- 3. Understand deletion vectors and liquid clustering
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
|
| Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 2. Use APPLY CHANGES APIs for change data capture
- 3. Compare streaming tables and materialized views
- 4. Develop unit and integration tests for data processing code
- 5. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 6. Use control flow operators in pipeline components
- 7. Configure environments, dependencies, memory, and retry behavior
- 8. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Manage and troubleshoot third-party library installations and dependencies
|
>> Exam Certified-Data-Engineer-Professional Material <<
Authorized Exam Certified-Data-Engineer-Professional Material & Guaranteed Databricks Certified-Data-Engineer-Professional Exam Success with The Best Test Certified-Data-Engineer-Professional Engine Version
For candidates who preparing for the exam, knowing the latest information for the exam is quite necessary. Certified-Data-Engineer-Professional exam cram of us can offer free update for 365 days for you, and we have skilled professionals examine the update every day, once we have the update version, we will send you the first time. Certified-Data-Engineer-Professional training materials is not only high-quality, but also contain certain quantity, therefore they will be enough for you to pass the exam. We have a professional service team, and the service staffs have professional knowledge for Certified-Data-Engineer-Professional Exam Materials, if you have any questions, you can consult us.
Databricks Certified Data Engineer Professional Sample Questions (Q169-Q174):
NEW QUESTION # 169
A data engineer is analyzing a large, partitioned retail dataset in Databricks, where each row represents a sale made by a salesperson. The dataset contains millions of records with the following schema:
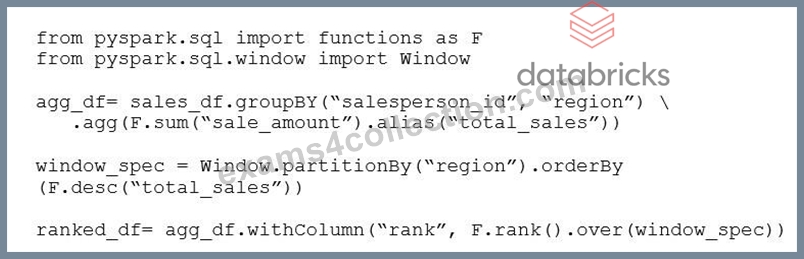
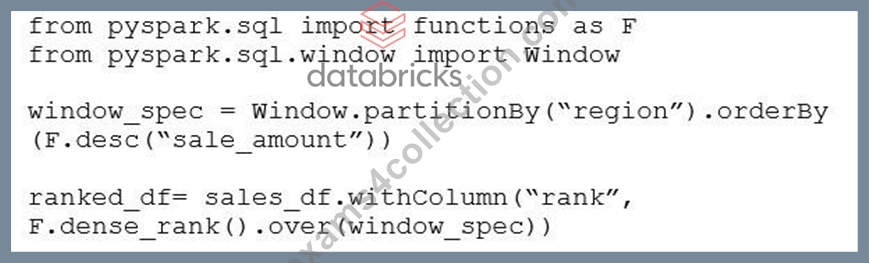
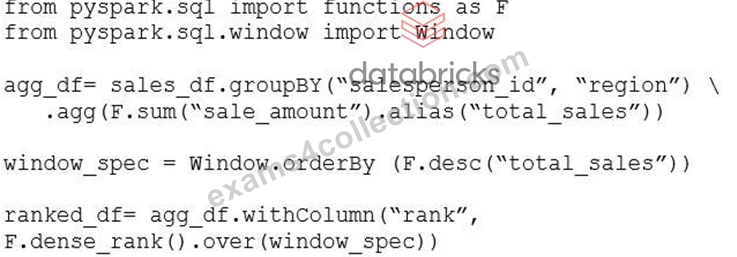
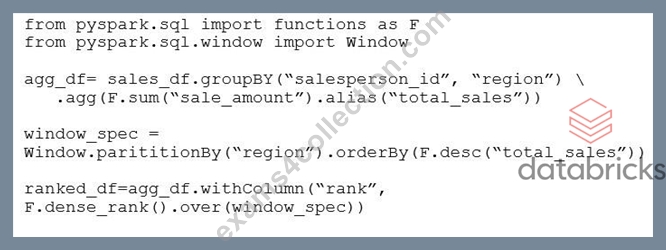
sales_df: [salesperson_id: string, region: string, sale_amount: double, sale_date: date] The data engineer needs to generate a DataFrame that ranks salespeople within each region based on their total cumulative sales, with the highest seller ranked as 1. If multiple salespeople have the same total sales, they should share the same rank.
The data engineer wants to implement this logic using a PySpark window function and the dense_rank () function.
Which code snippet will perform this ranking?
Answer: D
Explanation:
This approach first aggregates sales by salesperson and region to compute total cumulative sales. It then applies a window function partitioned by region and ordered by total sales in descending order, using dense_rank to assign ranks so that salespeople with equal totals share the same rank and the highest total receives rank 1.
NEW QUESTION # 170
Which distribution does Databricks support for installing custom Python code packages?
- A. CRAN
- B. jars
- C. CRAM
- D. Wheels
- E. nom
- F. sbt
Answer: E
Explanation:
https://learn.microsoft.com/en-us/azure/databricks/workflows/jobs/how-to/use-python-wheels-in-workflows
NEW QUESTION # 171
A query is taking too long to run. After investigating the Spark UI, the data engineer discovered a significant amount of disk spill. The compute instance being used has a core-to-memory ratio of
1:2. What are the two steps the data engineer should take to minimize spillage? (Choose two.)
- A. Reduce spark.sql.files.maxPartitionBytes.
- B. Choose a compute instance with more disk space.
- C. Choose a compute instance with a higher core-to-memory ratio.
- D. Choose a compute instance with more network bandwidth.
- E. Increase spark.sql.files.maxPartitionBytes.
Answer: A,C
Explanation:
Databricks recommends addressing disk spilling--which occurs when Spark tasks run out of memory--by increasing memory per core and controlling partition size. Selecting an instance type with a higher memory-to-core ratio (A) provides each task with more available RAM, directly reducing the chance of spilling to disk. Additionally, reducing spark.sql.files.maxPartitionBytes (D) creates smaller partitions, preventing any single task from holding too much data in memory.
Increasing partition size (C) or disk capacity (B) does not solve memory bottlenecks, and bandwidth (E) affects network I/O, not spill behavior. Therefore, the correct actions are A and D.
NEW QUESTION # 172
A data engineer manages a production Lakeflow Declarative Pipeline that processes customer transaction data. The pipeline includes several data quality expectations such as transaction_amount > 0 and customer_id IS NOT NULL. These expectations are defined using the EXPECT clause in SQL.
The engineer aims to monitor the pipeline's data quality by analyzing the number of records that passed or failed each expectation during the latest pipeline update. The Lakeflow Declarative Pipelines event logs are stored in a Delta table named event_log_table.
For the most recent pipeline update, determine a programmatically appropriate approach to extract information like the name of each expectation, associated dataset, count of records that passed the expectation, and count of records that failed the expectation.
Which method retrieves the desired data quality metrics from the Lakeflow Declarative Pipelines event log?
- A. Query the event_log_table for events with event_type = 'data_quality' and directly select the passed_records and failed_records fields.
- B. Use the Lakeflow Declarative Pipelines UI to navigate to the specific pipeline, select the dataset, and view the Data Quality tab to manually retrieve the expectation metrics.
- C. Access the event_log_table, filter for events where event_type = 'flow_progress', and parse details.flow_progress.data_quality.expectations field to extract the required metrics.
- D. Access the event_log_table, filter for events where event_type = 'expectation_result', and extract the expectation metrics from the details field.
Answer: D
Explanation:
The Databricks documentation specifies that for Lakeflow Declarative Pipelines, detailed data quality metrics are logged as events of type expectation_result within the event log. Each record of this type contains fields including expectation_name, dataset_name, passed_records, and failed_records. Filtering on event_type = 'expectation_result' and expanding the details field allows retrieving metrics for each expectation from the most recent pipeline update. While flow_progress provides summary statistics and data_quality events aggregate results, only expectation_result events provide granular, per-expectation metrics required for audit and monitoring automation.
NEW QUESTION # 173
A data engineer is building a Lakeflow Declarative Pipelines pipeline to process healthcare claims data. A metadata JSON file defines data quality rules for multiple tables, including:
{
"claims": [
{"name": "valid_patient_id", "constraint": "patient_id IS NOT NULL"},
{"name": "non_negative_amount", "constraint": "claim_amount >= 0"}
]
}
The pipeline must dynamically apply these rules to the claims table without hardcoding the rules.
How should the data engineer achieve this?
- A. Load the JSON metadata, loop through its entries, and apply expectations using dlt.expect_all.
- B. Invoke an external API to validate records against the metadata rules.
- C. Reference each expectation with @dlt.expect decorators in the table declaration.
- D. Use a SQL CONSTRAINT block referencing the JSON file path.
Answer: A
Explanation:
Lakeflow Declarative Pipelines provide the expect_all method for programmatically applying multiple data quality expectations at once. The documentation explains that @dlt.expect_all accepts a dictionary of expectation names mapped to SQL constraints, allowing rules to be dynamically loaded from metadata such as JSON files. This ensures that pipelines remain maintainable and scalable without needing to hardcode individual @dlt.expect decorators. The event logs will track each expectation's pass and fail counts individually, making it auditable.
NEW QUESTION # 174
......
The committed team of the Exams4Collection is always striving hard to resolve any confusion among its users. The similarity between our Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam questions and the real Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) certification exam will amaze you. The similarity between the Exams4Collection Certified-Data-Engineer-Professional PDF Questions and the actual Certified-Data-Engineer-Professional certification exam will help you succeed in obtaining the highly desired Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) certification on the first go.
Test Certified-Data-Engineer-Professional Engine Version: https://www.exams4collection.com/Certified-Data-Engineer-Professional-latest-braindumps.html
- Certified-Data-Engineer-Professional Test Sample Questions 🤶 Certified-Data-Engineer-Professional Test Sample Questions 🪂 Certified-Data-Engineer-Professional Exams Dumps 🤛 Easily obtain ➥ Certified-Data-Engineer-Professional 🡄 for free download through ➽ www.dumpsquestion.com 🢪 📉Valid Exam Certified-Data-Engineer-Professional Registration
- Exam Certified-Data-Engineer-Professional Material | Pass-Sure Databricks Certified Data Engineer Professional 100% Free Test Engine Version 🔹 Search for ✔ Certified-Data-Engineer-Professional ️✔️ on ➥ www.pdfvce.com 🡄 immediately to obtain a free download 🔇Test Certified-Data-Engineer-Professional Book
- Pass Guaranteed Databricks - Certified-Data-Engineer-Professional - Latest Exam Databricks Certified Data Engineer Professional Material 🕴 The page for free download of ➤ Certified-Data-Engineer-Professional ⮘ on ➠ www.vceengine.com 🠰 will open immediately 🍋Certified-Data-Engineer-Professional Exam Labs
- Dumps Certified-Data-Engineer-Professional Collection 🌕 Certified-Data-Engineer-Professional Reliable Exam Answers 🐦 Test Certified-Data-Engineer-Professional Book 👡 Search for ➠ Certified-Data-Engineer-Professional 🠰 and download exam materials for free through ▶ www.pdfvce.com ◀ 🏊Valid Certified-Data-Engineer-Professional Cram Materials
- Reliable Certified-Data-Engineer-Professional Test Duration 👱 Latest Certified-Data-Engineer-Professional Exam Format 🔓 Valid Exam Certified-Data-Engineer-Professional Registration 🦑 Search for ➽ Certified-Data-Engineer-Professional 🢪 and download it for free immediately on 《 www.pdfdumps.com 》 🧾Online Certified-Data-Engineer-Professional Lab Simulation
- Certified-Data-Engineer-Professional Cert Guide 🙁 Dumps Certified-Data-Engineer-Professional Collection 🧭 Online Certified-Data-Engineer-Professional Lab Simulation 🤡 Search for ➥ Certified-Data-Engineer-Professional 🡄 and easily obtain a free download on ➤ www.pdfvce.com ⮘ 🔼Dumps Certified-Data-Engineer-Professional Collection
- Pass Guaranteed Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional –Valid Exam Material ↘ Easily obtain ▷ Certified-Data-Engineer-Professional ◁ for free download through 「 www.dumpsmaterials.com 」 🐋Test Certified-Data-Engineer-Professional Book
- Exam Certified-Data-Engineer-Professional Material | Pass-Sure Databricks Certified Data Engineer Professional 100% Free Test Engine Version 👇 Download “ Certified-Data-Engineer-Professional ” for free by simply searching on ➡ www.pdfvce.com ️⬅️ 👾Certified-Data-Engineer-Professional Test Sample Questions
- Certified-Data-Engineer-Professional Test Sample Questions 🧐 Certified-Data-Engineer-Professional Exams Dumps 🦝 Certified-Data-Engineer-Professional Exams Dumps 📄 { www.torrentvce.com } is best website to obtain ▷ Certified-Data-Engineer-Professional ◁ for free download 🦥Certified-Data-Engineer-Professional Valid Exam Sims
- Overcome Fear of Exam with Databricks Certified-Data-Engineer-Professional Exam Dumps 🥅 Search for ➽ Certified-Data-Engineer-Professional 🢪 and download it for free on ( www.pdfvce.com ) website 👰Certified-Data-Engineer-Professional Reliable Test Dumps
- Pass Certified-Data-Engineer-Professional Test 🤡 Online Certified-Data-Engineer-Professional Lab Simulation 📙 Certified-Data-Engineer-Professional Reliable Test Dumps 🧧 The page for free download of ⇛ Certified-Data-Engineer-Professional ⇚ on ( www.troytecdumps.com ) will open immediately 🆒Online Certified-Data-Engineer-Professional Lab Simulation
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes