Außerdem sind jetzt einige Teile dieser ZertSoft Databricks-Certified-Professional-Data-Engineer Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1Ue5tTLnvVRKJrgP7wairAtYMYISs2qmj
ZertSoft hat vielen IT-Zertifizierungskandidaten geholfen. Und ZertSoft bekommt gute Bewertung von den Kandidaten. Die Erfolgsquote von ZertSoft Prüfungsfragen erreicht 100%, was auch die Tatsache von vielen Kadidaten geprüft werden. Wenn Sie sich sehr müde für die Vorbereitung der Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung fühlen, können Sie die Databricks-Certified-Professional-Data-Engineer Prüfungsunterlagen nicht ignorieren. Das ist ein Werkzeug für die hocheffektive Vorbereitung der Databricks Databricks-Certified-Professional-Data-Engineer Prüfung. Es kann Ihre Effektivität am größten Teil erhöhen.
Die Zertifizierung zum Databricks Certified Professional Data Engineer ist eine ausgezeichnete Wahl für Personen, die sich auf Datenengineering spezialisieren möchten und ihre Expertise in Databricks-Technologien demonstrieren wollen. Sie ist auch eine wertvolle Referenz für Unternehmen, die Databricks nutzen und sicherstellen möchten, dass ihre Mitarbeiter über die erforderlichen Fähigkeiten verfügen, um große Datenmengen effektiv zu verwalten und zu analysieren.
>> Databricks-Certified-Professional-Data-Engineer Exam <<
Die Konkurrenz in der IT-Branche wird immer heftiger. Wie können Sie sich beweisen, dass Sie wichig und unerlässlich ist? Die Zertifizierung der Databricks Databricks-Certified-Professional-Data-Engineer zu erwerben macht es überzeugend. Was wir für Sie tun können ist, dass Ihnen helfen, die Databricks Databricks-Certified-Professional-Data-Engineer Prüfung mit höhere Effizienz und weniger Mühen zu bestehen. Mit langjährigen Entwicklung besitzt jetzt ZertSoft große Menge von Ressourcen und Erfahrungen. Immer verbesserte Software gibt Ihnen bessere Vorbereitungsphase der Databricks Databricks-Certified-Professional-Data-Engineer Prüfung.
Databricks ist eine führende Cloud-basierte Datenplattform, mit der Unternehmen Innovationen beschleunigen und ihre datengesteuerten Ziele erreichen können. Um ihre Expertise bei der Verwendung der Datenbank-Plattform zu präsentieren, können Datenfachleute die Zertifizierung von Datenbäumen (DATABRICKS-Zertifizierung professional-data-Engineer (Databricks Certified Professional Data Engineer) erhalten. Diese Zertifizierung wurde entwickelt, um die Fähigkeiten und Kenntnisse zu validieren, die zum Entwerfen, Erstellen und Wartung von Datenlösungen auf der Datenbankplattform erforderlich sind.
Die Databricks-zertifizierte Prüfung zum Data Engineer ist umfassend und umfasst eine breite Palette von Themen im Zusammenhang mit der Datenverarbeitung. Diese Themen umfassen Datenmodellierung, Datenübernahme, Datenintegration, Datenverarbeitung, Datenspeicherung und Datenanalyse. Die Kandidaten müssen ihr Wissen und ihre Fähigkeiten in diesen Bereichen durch das Absolvieren einer Reihe von Aufgaben und Übungen unter Beweis stellen.
124. Frage
You have configured AUTO LOADER to process incoming IOT data from cloud object storage every 15 mins, recently a change was made to the notebook code to update the processing logic but the team later realized that the notebook was failing for the last 24 hours, what steps team needs to take to reprocess the data that was not loaded after the notebook was corrected?
Antwort: B
Begründung:
Explanation
The answer is,
Autoloader automatically re-processes data that was not loaded using the checkpoint.
125. Frage
Where in the Spark UI can one diagnose a performance problem induced by not leveraging predicate push-down?
Antwort: D
Begründung:
Explanation
This is the correct answer because it is where in the Spark UI one can diagnose a performance problem induced by not leveraging predicate push-down. Predicate push-down is an optimization technique that allows filtering data at the source before loading it into memory or processing it further. This can improve performance and reduce I/O costs by avoiding reading unnecessary data. To leverage predicate push-down, one should use supported data sources and formats, such as Delta Lake, Parquet, or JDBC, and use filter expressions that can be pushed down to the source. To diagnose a performance problem induced by not leveraging predicate push-down, one can use the Spark UI to access the Query Detail screen, which showsinformation about a SQL query executed on a Spark cluster. The Query Detail screen includes the Physical Plan, which is the actual plan executed by Spark to perform the query. The Physical Plan shows the physical operators used by Spark, such as Scan, Filter, Project, or Aggregate, and their input and output statistics, such as rows and bytes. By interpreting the Physical Plan, one can see if the filter expressions are pushed down to the source or not, and how much data is read or processed by each operator. Verified References: [Databricks Certified Data Engineer Professional], under "Spark Core" section; Databricks Documentation, under "Predicate pushdown" section; Databricks Documentation, under "Query detail page" section.
126. Frage
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed: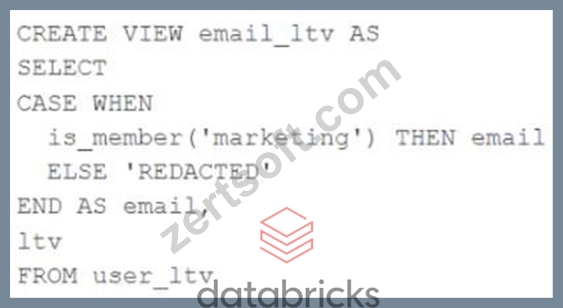
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
Antwort: B
Begründung:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row. Verified Reference: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "CASE expression" section.
127. Frage
A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on Task A.
If task A fails during a scheduled run, which statement describes the results of this run?
Antwort: D
Begründung:
When a Databricks job runs multiple tasks with dependencies, the tasks are executed in a dependency graph.
If a task fails, the downstream tasks that depend on it are skipped and marked as Upstream failed. However, the failed task may have already committed some changes to the Lakehouse before the failure occurred, and those changes are not rolled back automatically. Therefore, the job run may result in a partial update of the Lakehouse. To avoid this, you can use the transactional writes feature of Delta Lake to ensure that the changes are only committed when the entire job run succeeds. Alternatively, you can use the Run if condition to configure tasks to run even when some or all of their dependencies have failed, allowing your job to recover from failures and continue running. References:
* transactional writes: https://docs.databricks.com/delta/delta-intro.html#transactional-writes
* Run if: https://docs.databricks.com/en/workflows/jobs/conditional-tasks.html
128. Frage
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table namedusers.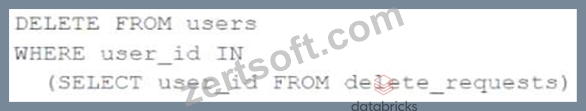
Assuming thatuser_idis a unique identifying key and thatdelete_requestscontains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
Antwort: E
Begründung:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delete from a table" section; Databricks Documentation, under
"Remove files no longer referenced by a Delta table" section.
129. Frage
......
Databricks-Certified-Professional-Data-Engineer German: https://www.zertsoft.com/Databricks-Certified-Professional-Data-Engineer-pruefungsfragen.html
Übrigens, Sie können die vollständige Version der ZertSoft Databricks-Certified-Professional-Data-Engineer Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=1Ue5tTLnvVRKJrgP7wairAtYMYISs2qmj