Außerdem sind jetzt einige Teile dieser ZertPruefung Data-Engineer-Associate Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1lbjOt7YpsfTKRfMkAUQszUhNI8bbBYzk
Wenn Sie eine gute Lernwebsite suchen, die Ihnen hilft, die Data-Engineer-Associate Prüfung zu bestehen, ist ZertPruefung die beste Wahl. Per ZertPruefung können Sie die Spitzenfertigkeiten in der IT-Branche meistern und die Amazon Data-Engineer-Associate Zertifizierungsprüfung leicht bestehen. Es ist allen bekannt, dass diese Prüfung schwer zu bestehen ist. Und die Erfolgsquote für die Prüfung ist sehr niedrig. Aber Sie können geeignete Lernhilfe und Fragen und Antworten zur Amazon Data-Engineer-Associate Zertifizierungsprüfung von ZertPruefung wählen. Diese Schulungsunterlagen sind nicht nur vollständig, sondern umfasst auch viele Wissensgebiete. Ihre Ähnlichkeit mit den echten Prüfungen ist sehr hoch. Das wird von der Praxis bewiesen. Wenn Sie die Amazon Data-Engineer-Associate Zertifizierungsprüfung bestehen wollen, wählen Sie doch ZertPruefung. Ganz richtig!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Ingestion and Transformation | 34% | - Build and manage data pipelines - Ingest and transform data using AWS services |
| Topic 2: Data Operations and Support | 22% | - Troubleshoot data workflow issues - Monitor and maintain data pipelines |
| Topic 3: Data Security and Governance | 18% | - Apply governance and compliance best practices - Implement data security controls |
| Topic 4: Data Store Management | 26% | - Optimize storage performance and cost - Select appropriate data storage solutions |
>> Data-Engineer-Associate Dumps Deutsch <<
Sie können im Internet kostenlos die Software und Prüfungsfragen und Antworten zur Amazon Data-Engineer-Associate Zertifizierungsprüfung als Probe herunterladen. ZertPruefung wird Ihnen helfen, die Amazon Data-Engineer-Associate Zertifizierungsprüfung zu bestehen. Wenn Sie unvorsichtigerweise in der Prüfung durchfallen, erstatten wir Ihnen Ihre an uns geleistene Zahlung.
70. Frage
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?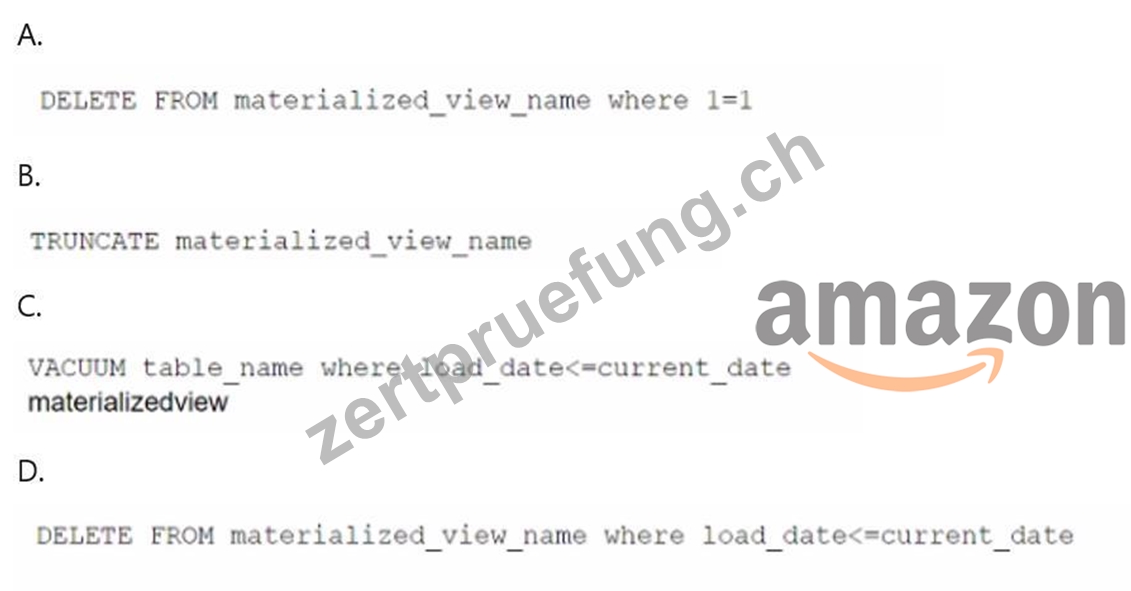
Antwort: A
Begründung:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
* Option A: DELETE FROM materialized_view_name WHERE 1=1;This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
References:
* Amazon Redshift Materialized Views Documentation
* Deleting Data from Redshift
71. Frage
A company needs to optimize storage for an Amazon S3 bucket. Objects older than 1 year must be accessible within 5 hours. All versions of the objects must be retained and immutable for 7 years. All versions of the objects must use the write-once-read-many (WORM) model.
Which solution will meet these requirements?
Antwort: D
Begründung:
The requirement to retain immutable object versions using a WORM model mandates the use of S3 Object Lock, not just S3 Versioning. Object Lock enforces immutability by preventing deletion or modification of objects for a specified retention period, which is required for compliance scenarios such as regulatory data retention.
To meet the access requirement of retrieving data within 5 hours, the appropriate archival storage class is S3 Glacier Flexible Retrieval, which supports expedited and standard retrieval within minutes to hours. S3 Glacier Deep Archive does not meet this requirement because retrieval times are typically 12 hours or longer.
Using S3 Intelligent-Tiering for active data optimizes storage costs automatically before transitioning older objects. A lifecycle policy can then transition objects older than 1 year to Glacier Flexible Retrieval and delete them after the 7-year retention period expires.
Options that rely only on S3 Versioning do not provide immutability guarantees. Options using Glacier Deep Archive fail the access-time requirement. Therefore, Option C is the only solution that satisfies WORM compliance, retrieval-time constraints, and cost optimization.
72. Frage
A company uses Amazon S3 buckets, AWS Glue tables, and Amazon Athena as components of a data lake.
Recently, the company expanded its sales range to multiple new states. The company wants to introduce state names as a new partition to the existing S3 bucket, which is currently partitioned by date.
The company needs to ensure that additional partitions will not disrupt daily synchronization between the AWS Glue Data Catalog and the S3 buckets.
Which solution will meet these requirements with the LEAST operational overhead?
Antwort: A
Begründung:
Scheduling an AWS Glue crawler to periodically update the Data Catalog automates the process of detecting new partitions and updating the catalog, which minimizes manual maintenance and operational overhead.
73. Frage
A company wants to implement real-time analytics capabilities. The company wants to use Amazon Kinesis Data Streams and Amazon Redshift to ingest and process streaming data at the rate of several gigabytes per second. The company wants to derive near real-time insights by using existing business intelligence (BI) and analytics tools.
Which solution will meet these requirements with the LEAST operational overhead?
Antwort: A
Begründung:
This solution meets the requirements of implementing real-time analytics capabilities with the least operational overhead. By creating an external schema in Amazon Redshift, you can access the data from Kinesis Data Streams using SQL queries without having to load the data into the cluster. By creating a materialized view on top of the stream, you can store the results of the query in the cluster and make them available for analysis. By setting the materialized view to auto refresh, you can ensure that the view is updated with the latest data from the stream at regular intervals. This way, you can derive near real-time insights by using existing BI and analytics tools. Reference:
Amazon Redshift streaming ingestion
Creating an external schema for Amazon Kinesis Data Streams
Creating a materialized view for Amazon Kinesis Data Streams
74. Frage
A company has a data processing pipeline that runs multiple SQL queries in sequence against an Amazon Redshift cluster. The company merges with a second company. The original company modifies a query that aggregates sales revenue data to join sales tables from both companies.
The sales table for the first company is named Table S1 and contains 10 billion records. The sales table for the second company is named Table S2 and contains 900 million records. The query becomes slow after the modification.
A data engineer must improve the query performance.
Which solutions will meet these requirements? (Select TWO)
Antwort: C,E
Begründung:
Amazon Redshift query performance for large joins depends heavily on data distribution and query optimization. Using the KEY distribution style on both tables ensures that rows with the same join key are co-located on the same compute nodes, minimizing costly data redistribution during joins.
Selecting a high-cardinality column as the distribution key is critical to evenly distribute data across nodes and prevent data skew. Low-cardinality keys can cause hotspots where too much data resides on a small number of nodes, degrading performance.
Using EVEN distribution on the 10-billion-row table and ALL distribution on the 900-million-row table is inefficient because ALL distribution replicates the entire table to every node, which is not appropriate for large datasets. The Amazon Redshift query optimizer operates automatically and does not require manual selection.
Amazon Redshift Advisor analyzes workload patterns and provides actionable recommendations for distribution styles, sort keys, and query optimizations. Using Redshift Advisor allows the data engineer to apply proven optimizations based on actual cluster usage.
Therefore, combining KEY distribution with a high-cardinality join column and leveraging Amazon Redshift Advisor recommendations is the most effective solution to improve query performance.
75. Frage
......
Machen Sie sich noch Sorgen um die Amazon Data-Engineer-Associate Zertifzierungsprüfung? Bemühen Sie sich noch anstrengend um die Amazon Data-Engineer-Associate Zertifzierungsprüfung? Wollen Sie so schnell wie mlglich die die Amazon Data-Engineer-Associate Zertifizierungsprüfung bestehen? Wählen Sie doch ZertPruefung! Mit ihm können Sie ganz schnell Ihren Traum verwirklichen.
Data-Engineer-Associate Antworten: https://www.zertpruefung.ch/Data-Engineer-Associate_exam.html
P.S. Kostenlose 2026 Amazon Data-Engineer-Associate Prüfungsfragen sind auf Google Drive freigegeben von ZertPruefung verfügbar: https://drive.google.com/open?id=1lbjOt7YpsfTKRfMkAUQszUhNI8bbBYzk