Quiz 2026 Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Updated Reliable Exam Voucher

With more than thousands of satisfied applicants in multiple countries, we guarantee that you will clear the Databricks Certified-Data-Engineer-Professional exam as quickly as possible by using our product. In this way, Exams.SOlutions save you time and money. In addition to all these excellent offers, in any case despite properly studying with Certified-Data-Engineer-Professional Practice Test material.
| Section | Objectives |
|---|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 4. Apply Change Data Feed to address streaming table limitations and improve latency
- 5. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Monitoring and Alerting | - Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Query Profile and Spark UI to monitor workloads
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
|
| Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Design and implement scalable data models using Delta Lake to manage large datasets
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 2. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 3. Create pipeline components using control flow operators such as if/else and foreach
- 4. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 5. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 6. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
|
>> Certified-Data-Engineer-Professional Reliable Exam Voucher <<
Top Certified-Data-Engineer-Professional Reliable Exam Voucher | Valid Valid Certified-Data-Engineer-Professional Exam Format: Databricks Certified Data Engineer Professional
Since the content of the examination is also updating daily, you will need real and latest Databricks Certified-Data-Engineer-Professional Exam Dumps to prepare successfully for the Certified-Data-Engineer-Professional certification exam in a short time. People who don't study from updated Databricks Certified-Data-Engineer-Professional Questions fail the examination and loss time and money.
Databricks Certified Data Engineer Professional Sample Questions (Q135-Q140):
NEW QUESTION # 135
Which statement describes the default execution mode for Databricks Auto Loader?
- A. Webhook trigger Databricks job to run anytime new data arrives in a source directory; new data automatically merged into target tables using rules inferred from the data.
- B. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; new files are incrementally and impotently into the target Delta Lake table.
- C. New files are identified by listing the input directory; new files are incrementally and idempotently loaded into the target Delta Lake table.
- D. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; the target table is materialized by directly querying all valid files in the source directory.
- E. New files are identified by listing the input directory; the target table is materialized by directory querying all valid files in the source directory.
Answer: C
Explanation:
Databricks Auto Loader simplifies and automates the process of loading data into Delta Lake.
The default execution mode of the Auto Loader identifies new files by listing the input directory. It incrementally and idempotently loads these new files into the target Delta Lake table. This approach ensures that files are not missed and are processed exactly once, avoiding data duplication. The other options describe different mechanisms or integrations that are not part of the default behavior of the Auto Loader.
NEW QUESTION # 136
A departing platform owner currently holds ownership of multiple catalogs and controls storage credentials and external locations. A data engineer has been asked to ensure continuity: transfer catalog ownership to the platform team group, delegate ongoing privilege management, and retain the ability to receive and share data via Delta Sharing. Which role must be in place to perform these actions across the metastore?
- A. Account Admin, because account admins can only create metastores but cannot change ownership of catalogs.
- B. Workspace Admin, because workspace admins can transfer ownership of any Unity Catalog object.
- C. Catalog Owner, because catalog owners can transfer any object in any catalog in the metastore.
- D. Metastore Admin, because metastore admins can transfer ownership and manage privileges across all metastore objects, including shares and recipients.
Answer: D
NEW QUESTION # 137
A CHECK constraint has been successfully added to the Delta table named activity_details using the following logic:
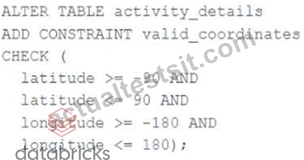
A batch job is attempting to insert new records to the table, including a record where latitude =
45.50 and longitude = 212.67.
Which statement describes the outcome of this batch insert?
- A. The write will fail completely because of the constraint violation and no records will be inserted into the target table.
- B. The write will fail when the violating record is reached; any records previously processed will be recorded to the target table.
- C. The write will include all records in the target table; any violations will be indicated in the boolean column named valid_coordinates.
- D. The write will insert all records except those that violate the table constraints; the violating records will be recorded to a quarantine table.
- E. The write will insert all records except those that violate the table constraints; the violating records will be reported in a warning log.
Answer: A
Explanation:
The CHECK constraint is used to ensure that the data inserted into the table meets the specified conditions. In this case, the CHECK constraint is used to ensure that the latitude and longitude values are within the specified range. If the data does not meet the specified conditions, the write operation will fail completely and no records will be inserted into the target table. This is because Delta Lake supports ACID transactions, which means that either all the data is written or none of it is written. Therefore, the batch insert will fail when it encounters a record that violates the constraint, and the target table will not be updated.
NEW QUESTION # 138
A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on task A.
If tasks A and B complete successfully but task C fails during a scheduled run, which statement describes the resulting state?
- A. All logic expressed in the notebook associated with tasks A and B will have been successfully completed; any changes made in task C will be rolled back due to task failure.
- B. Because all tasks are managed as a dependency graph, no changes will be committed to the Lakehouse until ail tasks have successfully been completed.
- C. Unless all tasks complete successfully, no changes will be committed to the Lakehouse; because task C failed, all commits will be rolled back automatically.
- D. All logic expressed in the notebook associated with tasks A and B will have been successfully completed; some operations in task C may have completed successfully.
- E. All logic expressed in the notebook associated with task A will have been successfully completed; tasks B and C will not commit any changes because of stage failure.
Answer: D
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The resulting state after running the second command is that an external table will be created in the storage container mounted to /mnt/finance_eda_bucket with the new name prod.sales_by_store. The command will not change any data or move any files in the storage container; it will only update the table reference in the metastore and create a new Delta transaction log for the renamed table.
NEW QUESTION # 139
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should have five workers, one driver of type i3.xlarge, and should use the '14.3.x- scala2.12' runtime. Which command should the data engineer use?
- A. databricks clusters add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- B. databricks clusters create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster- name DataEngineer_cluster
- C. databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster- name Data Engineer_cluster
- D. databricks compute add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
Answer: B
Explanation:
The correct Databricks CLI command to create a new cluster is databricks clusters create. You specify the runtime with --spark-version (here '14.3.x-scala2.12'), the number of workers with -- num-workers, the node type with --node-type-id, and the cluster name with --cluster-name. This command properly initializes the cluster with the desired configuration.
NEW QUESTION # 140
......
First and foremost, in order to cater to the different needs of people from different countries in the international market, we have prepared three kinds of versions of our Certified-Data-Engineer-Professional learning questions in this website. Second, we can assure you that you will get the latest version of our training materials for free from our company in the whole year after payment on Certified-Data-Engineer-Professional practice materials. Last but not least, we will provide the most considerate after sale service for our customers in twenty four hours a day seven days a week.
Valid Certified-Data-Engineer-Professional Exam Format: https://www.actualtestsit.com/Databricks/Certified-Data-Engineer-Professional-exam-prep-dumps.html
- Databricks Certified Data Engineer Professional practice questions - Certified-Data-Engineer-Professional reliable study - Databricks Certified Data Engineer Professional torrent vce 🌲 Easily obtain ⇛ Certified-Data-Engineer-Professional ⇚ for free download through { www.prepawaypdf.com } 🎻Certified-Data-Engineer-Professional Exam Topics
- Vce Certified-Data-Engineer-Professional Free 🚌 Certified-Data-Engineer-Professional Practice Test Engine 🕸 Reliable Certified-Data-Engineer-Professional Test Preparation 🎄 Enter ⮆ www.pdfvce.com ⮄ and search for ▛ Certified-Data-Engineer-Professional ▟ to download for free 🔡Valid Test Certified-Data-Engineer-Professional Braindumps
- Certified-Data-Engineer-Professional Exam Topics 🧛 Valid Study Certified-Data-Engineer-Professional Questions 🚇 100% Certified-Data-Engineer-Professional Exam Coverage 🔽 Search for ⮆ Certified-Data-Engineer-Professional ⮄ on ⏩ www.prepawayete.com ⏪ immediately to obtain a free download 🐇Certified-Data-Engineer-Professional Free Exam
- Latest Certified-Data-Engineer-Professional Exam Topics ✅ Exam Certified-Data-Engineer-Professional Duration 🐜 Latest Certified-Data-Engineer-Professional Exam Topics 🧰 Search for ▛ Certified-Data-Engineer-Professional ▟ on ⮆ www.pdfvce.com ⮄ immediately to obtain a free download ✉Latest Certified-Data-Engineer-Professional Practice Questions
- 100% Pass 2026 Databricks Certified-Data-Engineer-Professional –High Hit-Rate Reliable Exam Voucher 🚠 Search for ➥ Certified-Data-Engineer-Professional 🡄 and easily obtain a free download on ( www.validtorrent.com ) ⭐Pass Certified-Data-Engineer-Professional Guarantee
- Reliable Certified-Data-Engineer-Professional Test Preparation 💫 100% Certified-Data-Engineer-Professional Exam Coverage ⏏ Exam Certified-Data-Engineer-Professional Duration 🛴 Open ➥ www.pdfvce.com 🡄 enter 【 Certified-Data-Engineer-Professional 】 and obtain a free download 🥎Cheap Certified-Data-Engineer-Professional Dumps
- Vce Certified-Data-Engineer-Professional Free 🏢 Valid Study Certified-Data-Engineer-Professional Questions 🧞 Certified-Data-Engineer-Professional Reliable Exam Voucher 🎾 Search for ( Certified-Data-Engineer-Professional ) and download it for free immediately on ▷ www.validtorrent.com ◁ 🙃Pass Certified-Data-Engineer-Professional Guarantee
- Databricks Certified Data Engineer Professional practice questions - Certified-Data-Engineer-Professional reliable study - Databricks Certified Data Engineer Professional torrent vce 🙈 Download 《 Certified-Data-Engineer-Professional 》 for free by simply searching on ⮆ www.pdfvce.com ⮄ 🌹Reliable Certified-Data-Engineer-Professional Test Preparation
- Top Certified-Data-Engineer-Professional Dumps ✈ Cost Effective Certified-Data-Engineer-Professional Dumps 🎫 Top Certified-Data-Engineer-Professional Dumps 🍵 Immediately open ( www.prepawayexam.com ) and search for ( Certified-Data-Engineer-Professional ) to obtain a free download 🛵Certified-Data-Engineer-Professional Practice Test Engine
- Certified-Data-Engineer-Professional Latest Braindumps Pdf 🌾 Reliable Certified-Data-Engineer-Professional Test Preparation 🦰 Certified-Data-Engineer-Professional Free Exam 🔲 Immediately open 【 www.pdfvce.com 】 and search for { Certified-Data-Engineer-Professional } to obtain a free download ⤵Latest Certified-Data-Engineer-Professional Exam Topics
- Free PDF Quiz Databricks - Certified-Data-Engineer-Professional –Reliable Reliable Exam Voucher 🚕 Go to website ➤ www.practicevce.com ⮘ open and search for 【 Certified-Data-Engineer-Professional 】 to download for free 🎇Pass Certified-Data-Engineer-Professional Guarantee
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes