Itcertkr SPS-C01 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1CU0w1zZ94XNJ30u1klOCqbRb0JvtNXW7
Itcertkr에서는 전문Snowflake SPS-C01인증시험을 겨냥한 덤프 즉 문제와 답을 제공합니다.여러분이 처음Snowflake SPS-C01인증시험준비라면 아주 좋은 덤프입니다. Itcertkr에서 제공되는 덤프는 모두 실제시험과 아주 유사한 덤프들입니다.Snowflake SPS-C01인증시험패스는 보장합니다. 만약 떨어지셨다면 우리는 덤프비용전액을 환불해드립니다.
| Section | Objectives |
|---|---|
| Topic 1: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 2: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 3: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 4: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 5: Data Engineering with Snowpark | - Pipeline development
|
| Topic 6: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
Itcertkr의Snowflake인증 SPS-C01덤프의 인지도는 아주 높습니다. 인지도 높은 원인은Snowflake인증 SPS-C01덤프의 시험적중율이 높고 가격이 친근하고 구매후 서비스가 끝내주기 때문입니다. Itcertkr의Snowflake인증 SPS-C01덤프로Snowflake인증 SPS-C01시험에 도전해보세요.
질문 # 339
You are working with two large Snowpark DataFrames: 'transaction_df and 'product df. 'transaction_df contains transaction data including 'transaction id', 'product id', and 'transaction_date'. 'product df contains product details including 'product id', product_name', and 'product category'. You need to join these DataFrames to analyze transaction data by product category. The 'transaction_df is significantly larger than 'product_df. Which of the following strategies can significantly improve the performance of the join operation in Snowpark? (Select all that apply)
정답:A,B,E
설명:
Options A, B, and D are correct. A ensures efficient comparison and join execution. B leverages broadcast join when smaller dataframe is broadcasted to all nodes, reducing data movement. D reduces the size of the larger DataFrame before the join, improving performance. C is incorrect because caching the larger 'transaction_df DataFrame before the join won't significantly improve performance; Snowpark automatically optimizes query execution. E is wrong because Snowflake manages join algorithms efficiently, forcing a specific algorithm might be counterproductive.
질문 # 340
You are developing a Snowpark application to analyze website traffic data'. You have a DataFrame named 'website_logs' with columns 'user_id', 'page_url', and 'timestamp'. You need to create a new DataFrame that contains the count of distinct users who visited each page within a specific time window Consider the following (incomplete) Snowpark Python code: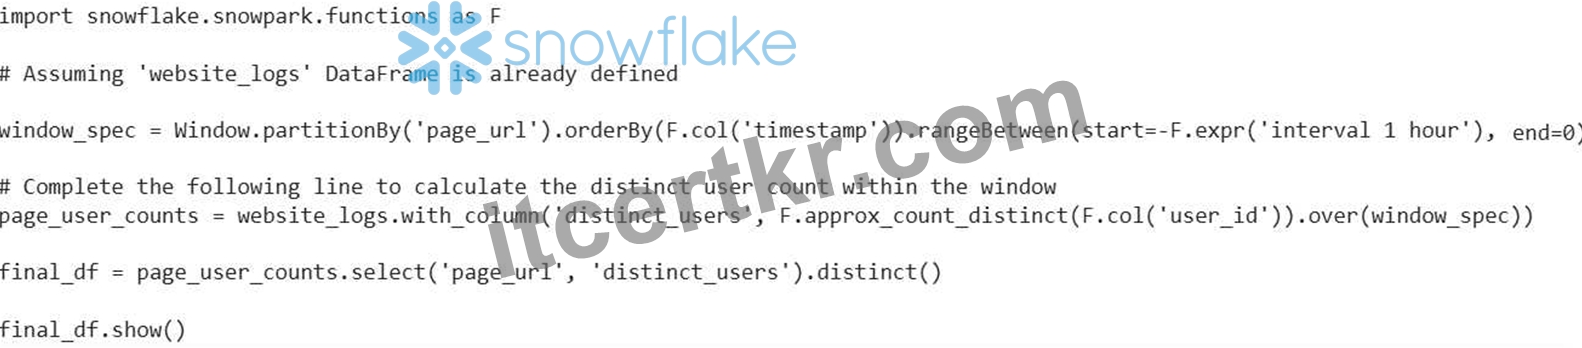
Which of the following code lines, when inserted into the Complete the following line...' comment, will correctly calculate the approximate distinct user count for each page within the specified time window?
정답:D
설명:
The correct code line is 'website_logs.with_column('distinct_users', F.approx_count_distinct('user_id').over(window_spec))'. This uses the function to calculate the approximate distinct count of user IDs within the window defined by 'window_spec' . Option B uses exact count which is less performant. Option A performs an aggregation, which will give a different type of result. Option D uses F.window' which is used for tumbling windows, not sliding windows as requested by the problem.
질문 # 341
You are tasked with developing a data pipeline using Snowpark that involves reading data from multiple CSV files, performing transformations using Pandas DataFrames, and then loading the transformed data into a Snowflake table. You want to optimize the process by leveraging the capabilities of Snowpark and Pandas effectively. Which of the following approaches is the MOST efficient for creating the Snowpark DataFrame from the pandas dataframe? (Select all that apply.)
정답:B,D
설명:
Option C is the most efficient when the transformations can be effectively done using Snowpark itself, bypassing Pandas entirely and leveraging Snowflake's compute power directly. Option D, while using Pandas for transformation, optimizes data transfer using the optimized 'write_pandas' function. Creating Snowpark DataFrames from Pandas DataFrames and then unioning (Option B) can be less performant due to data transfer overhead. Concatenating Pandas DataFrames and then creating a Snowpark DataFrame (Option A) can be memory-intensive. Option E is incorrect, setting will throw an error if table does not exist.
질문 # 342
You have a Snowpark DataFrame named with the following schema: '(timestamp: TmestampType, sensor_id: StringType, value: FloatType)'. You need to identify the top 3 sensors with the highest average value over the entire dataset. Which of the following Snowpark Python code snippets correctly implements this requirement?





정답:C
설명:
Option A provides the correct and most concise solution. It groups the 'sensor_data' DataFrame by , calculates the average value for each sensor using , orders the results by the average value in descending order using ascending-Falsey , and then limits the results to the top 3 sensors using 'limit(3)'. Option B attempts to use window function over the entire dataset without grouping by sensor, the result would be incorrect. Option C incorrectly attempts to use window specification without partition. Option D is similar as C with missing group by partition. Option E use 'sort' instead of 'orderBy' .
질문 # 343
A data engineering team is developing a Snowpark stored procedure to perform complex data transformations and load the results into a target table. They want to operationalize this procedure by scheduling it to run daily. Which of the following is the MOST reliable and scalable way to schedule the execution of this Snowpark stored procedure within Snowflake?
정답:D
설명:
Snowflake Tasks are the recommended way to schedule stored procedures within Snowflake. They are a native Snowflake feature, providing scalability, reliability, and integration with Snowflake's monitoring and management tools. Airflow is a valid option, but adds external dependencies.
질문 # 344
......
많은 분들이Snowflake SPS-C01시험을 패스하려고 하는데 시험대비방법을 찾지 못하고 계십니다. Snowflake SPS-C01덤프를 구매하려면 먼저Snowflake SPS-C01샘플문제를 다운받아 덤프품질을 검증후 주문하시면 믿음이 생길것입니다. Snowflake SPS-C01시험대비덤프는 IT업계에 오랜 시간동안 종사한 전문가들의 노하우로 연구해낸 최고의 자료입니다.
SPS-C01시험준비: https://www.itcertkr.com/SPS-C01_exam.html
BONUS!!! Itcertkr SPS-C01 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=1CU0w1zZ94XNJ30u1klOCqbRb0JvtNXW7