Our Databricks-Certified-Professional-Data-Engineer training materials offer you everything you need to take the certification and face the challenge of professional knowledge points. The Databricks-Certified-Professional-Data-Engineer exam dumps are written and approved by our IT specialist based on the real questions of the formal test. Our latest learning materials contain the valid test questions and correct Databricks-Certified-Professional-Data-Engineer Test Answers along with detailed explanation. We will give your money back in full if you lose exam with our Databricks-Certified-Professional-Data-Engineer practice exam.
| Section | Objectives |
|---|---|
| Production Pipelines and Orchestration | - Automate ETL pipelines and scheduling - Pipeline reliability and fault tolerance - Build and manage workflows using Databricks Jobs |
| Security, Governance, Monitoring, and Optimization | - Monitor and optimize Spark workloads - Cost optimization and performance tuning - Implement Unity Catalog governance and access control |
| Data Modeling and Storage | - Schema evolution and data partitioning strategies - Design scalable data lakehouse architectures - Delta Lake table design and optimization |
| Data Ingestion and Transformation | - Ingest data using Apache Spark and Databricks - Handle batch and streaming data pipelines - Transform and clean datasets using Spark SQL and DataFrame APIs |
>> Databricks-Certified-Professional-Data-Engineer Latest Test Materials <<
Do you want to pass Databricks-Certified-Professional-Data-Engineer certification exam easily? Then it is necessary to have Itcerttest Databricks-Certified-Professional-Data-Engineer exam certification training materials. Itcerttest Databricks-Certified-Professional-Data-Engineer test training materials are summarized by IT experts with constant practice, which is the combination of Databricks-Certified-Professional-Data-Engineer Exam Dumps and answers, and can't be matched by any Databricks-Certified-Professional-Data-Engineer test training materials from others. Itcerttest will take you to a more beautiful future.
NEW QUESTION # 56
You are currently working with the application team to setup a SQL Endpoint point, once the team started consuming the SQL Endpoint you noticed that during peak hours as the number of concur-rent users increases you are seeing degradation in the query performance and the same queries are taking longer to run, which of the following steps can be taken to resolve the issue?
Answer: D
Explanation:
Explanation
The answer is, They can increase the maximum bound of the SQL endpoint's scaling range, when you increase the max scaling range more clusters are added so queries instead of waiting in the queue can start running using available clusters, see below for more explanation.
The question is looking to test your ability to know how to scale a SQL Endpoint(SQL Warehouse) and you have to look for cue words or need to understand if the queries are running sequentially or concurrently. if the queries are running sequentially then scale up(Size of the cluster from 2X-Small to 4X-Large) if the queries are running concurrently or with more users then scale out(add more clusters).
SQL Endpoint(SQL Warehouse) Overview: (Please read all of the below points and the below diagram to understand )
1.A SQL Warehouse should have at least one cluster
2.A cluster comprises one driver node and one or many worker nodes
3.No of worker nodes in a cluster is determined by the size of the cluster (2X -Small ->1 worker, X-Small ->2 workers.... up to 4X-Large -> 128 workers) this is called Scale up
4.A single cluster irrespective of cluster size(2X-Smal.. to ...4XLarge) can only run 10 queries at any given time if a user submits 20 queries all at once to a warehouse with 3X-Large cluster size and cluster scaling (min
1, max1) while 10 queries will start running the remaining 10 queries wait in a queue for these 10 to finish.
5.Increasing the Warehouse cluster size can improve the performance of a query, example if a query runs for 1 minute in a 2X-Small warehouse size, it may run in 30 Seconds if we change the warehouse size to X-Small.
this is due to 2X-Small has 1 worker node and X-Small has 2 worker nodes so the query has more tasks and runs faster (note: this is an ideal case example, the scalability of a query performance depends on many factors, it can not always be linear)
6.A warehouse can have more than one cluster this is called Scale out. If a warehouse is con-figured with X-Small cluster size with cluster scaling(Min1, Max 2) Databricks spins up an additional cluster if it detects queries are waiting in the queue, If a warehouse is configured to run 2 clusters(Min1, Max 2), and let's say a user submits 20 queries, 10 queriers will start running and holds the remaining in the queue and databricks will automatically start the second cluster and starts redirecting the 10 queries waiting in the queue to the second cluster.
7.A single query will not span more than one cluster, once a query is submitted to a cluster it will remain in that cluster until the query execution finishes irrespective of how many clusters are available to scale.
Please review the below diagram to understand the above concepts:
Box and whisker chart Description automatically generated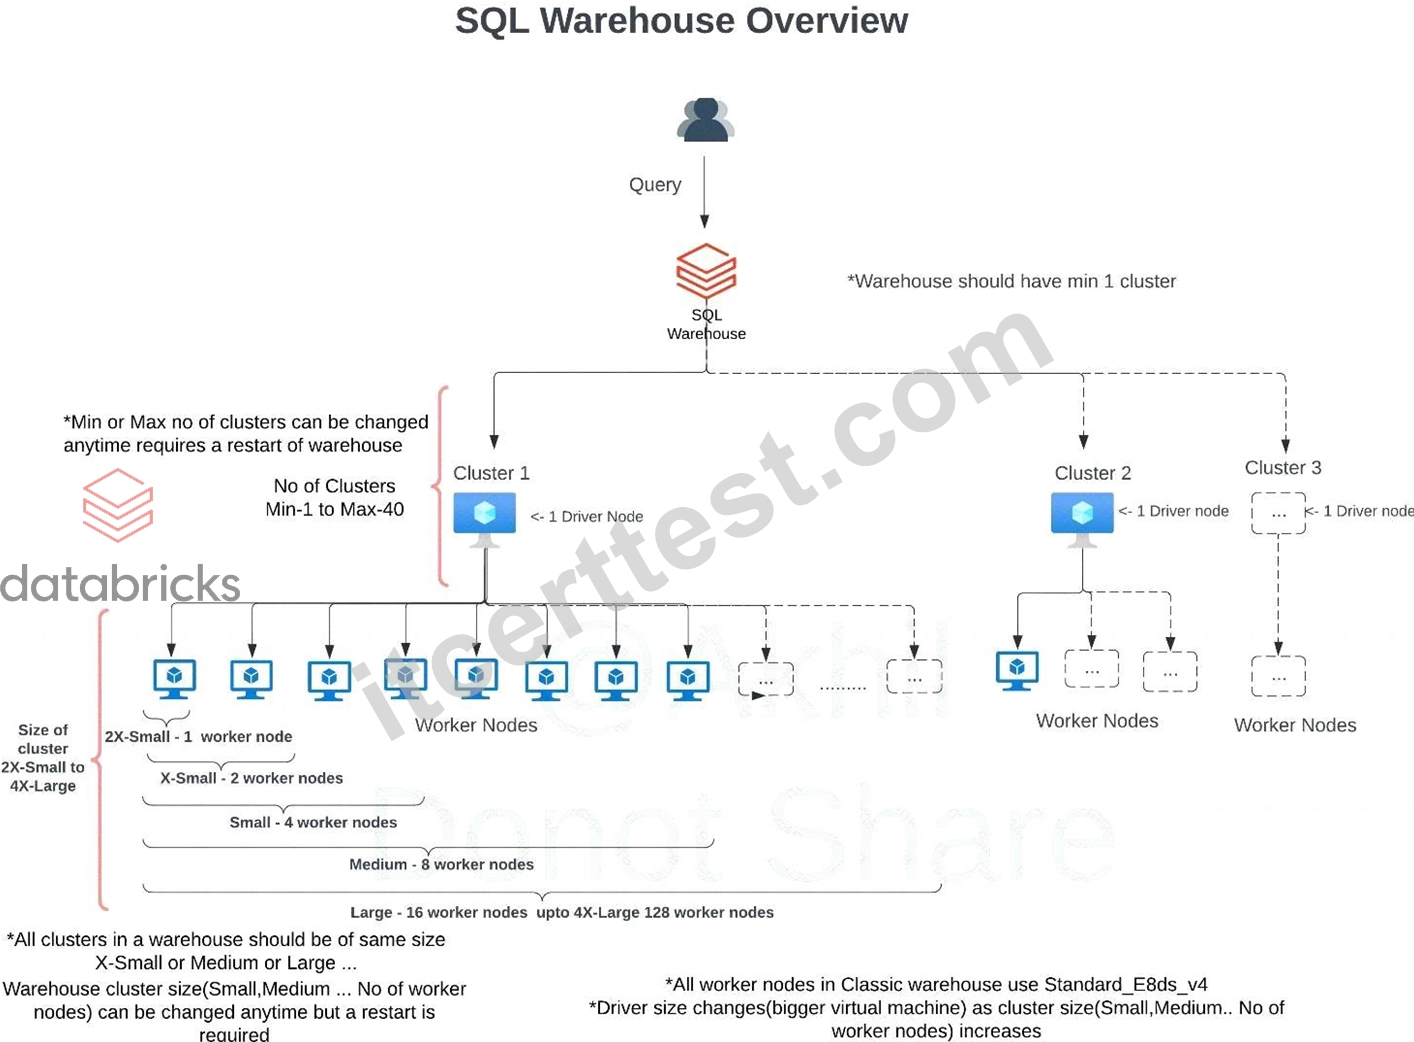
SQL endpoint(SQL Warehouse) scales horizontally(scale-out) and vertical (scale-up), you have to understand when to use what.
Scale-out -> to add more clusters for a SQL endpoint, change max number of clusters If you are trying to improve the throughput, being able to run as many queries as possible then having an additional cluster(s) will improve the performance.
Databricks SQL automatically scales as soon as it detects queries are in queuing state, in this example scaling is set for min 1 and max 3 which means the warehouse can add three clusters if it detects queries are waiting.
Diagram Description automatically generated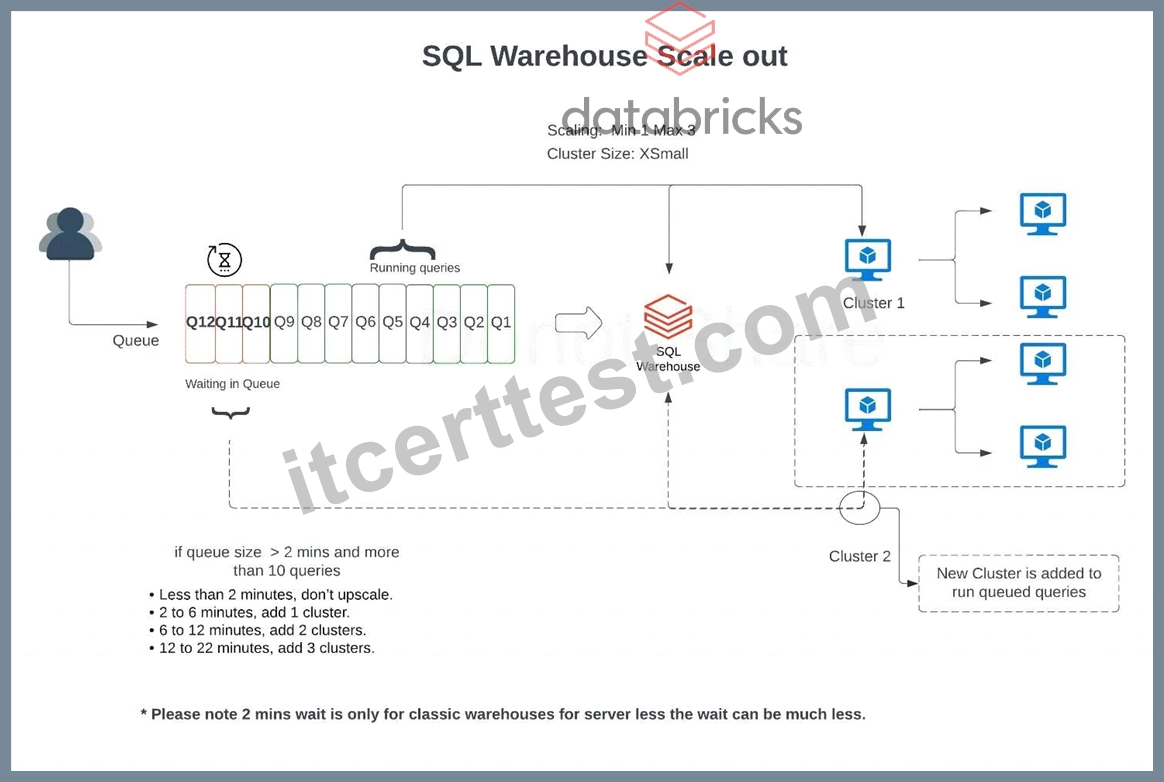
During the warehouse creation or after you have the ability to change the warehouse size (2X-Small....to
...4XLarge) to improve query performance and the maximize scaling range to add more clusters on a SQL Endpoint(SQL Warehouse) scale-out, if you are changing an existing warehouse you may have to restart the warehouse to make the changes effective.
A picture containing diagram Description automatically generated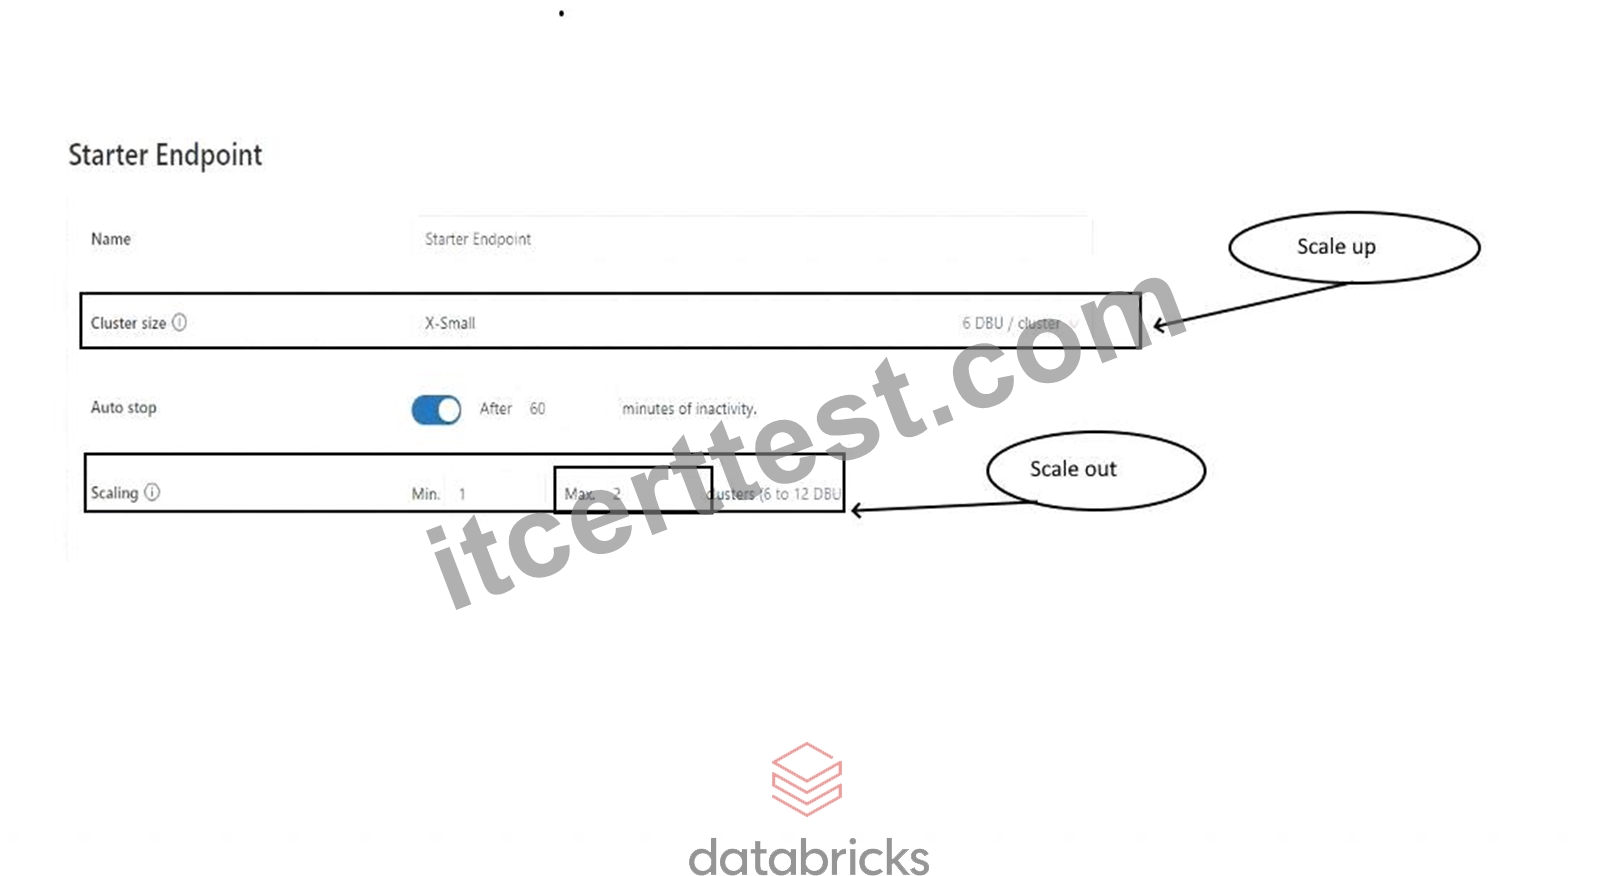
NEW QUESTION # 57
A junior data engineer on your team has implemented the following code block.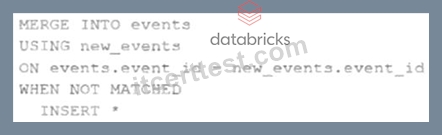
The viewnew_eventscontains a batch of records with the same schema as theeventsDelta table.
Theevent_idfield serves as a unique key for this table.
When this query is executed, what will happen with new records that have the sameevent_idas an existing record?
Answer: D
Explanation:
This is the correct answer because it describes what will happen with new records that have the same event_id as an existing record when the query is executed. The query uses the INSERT INTO command to append new records from the view new_events to the table events. However, the INSERT INTO command does not check for duplicate values in the primary key column (event_id) and does not perform any update or delete operations on existing records. Therefore, if there are new records that have the same event_id as an existing record, they will be ignored and not inserted into the table events. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Append data using INSERT INTO" section.
"If none of the WHEN MATCHED conditions evaluate to true for a source and target row pair that matches the merge_condition, then the target row is left unchanged."https://docs.databricks.com/en/sql/language-manual/delta-merge-into.html#:~:text=If%20none%20o
NEW QUESTION # 58
Which of the following is a true statement about the global temporary view?
Answer: D
Explanation:
Explanation
The answer is, A global temporary view is available only on the cluster it was created.
Two types of temporary views can be created Session scoped and Global
*A session scoped temporary view is only available with a spark session, so another notebook in the same cluster can not access it. if a notebook is detached and re attached the temporary view is lost.
*A global temporary view is available to all the notebooks in the cluster, if a cluster restarts global temporary view is lost.
NEW QUESTION # 59
A departing platform owner currently holds ownership of multiple catalogs and controls storage credentials and external locations. A data engineer has been asked to ensure continuity: transfer catalog ownership to the platform team group, delegate ongoing privilege management, and retain the ability to receive and share data via Delta Sharing.
Which role must be in place to perform these actions across the metastore?
Answer: C
Explanation:
Metastore Admins have the highest administrative privileges within a Unity Catalog metastore. They can transfer ownership of any Unity Catalog object, including catalogs, schemas, tables, storage credentials, and external locations. Metastore Admins are also required to manage Delta Sharing configurations such as creating or transferring shares and recipients.
Account Admins, by contrast, only create metastores and cannot change ownership or manage Delta Sharing objects. Workspace Admins have privileges limited to workspace-level management, not cross-metastore access.
Reference Source: Databricks Unity Catalog Administration Guide - "Metastore admin privileges and ownership transfer."
NEW QUESTION # 60
Which statement describes Delta Lake Auto Compaction?
Answer: A
Explanation:
This is the correct answer because it describes the behavior of Delta Lake Auto Compaction, which is a feature that automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones.
Auto Compaction runs as an asynchronous job after a write to a table has succeeded and checks if files within a partition can be further compacted. If yes, it runs an optimize job with a default target file size of 128 MB.
Auto Compaction only compacts files that have not been compacted previously. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Auto Compaction for Delta Lake on Databricks" section.
"Auto compaction occurs after a write to a table has succeeded and runs synchronously on the cluster that has performed the write. Auto compaction only compacts files that haven't been compacted previously."
https://learn.microsoft.com/en-us/azure/databricks/delta/tune-file-size
NEW QUESTION # 61
......
As what have been demonstrated in the records concerning the pass rate of our Databricks-Certified-Professional-Data-Engineer free demo, our pass rate has kept the historical record of 98% to 99% from the very beginning of their foundation. During these years, our PDF version of our Databricks-Certified-Professional-Data-Engineer study engine stays true to its original purpose to pursue a higher pass rate that has never been attained in the past. And you will be content about our considerate service on our Databricks-Certified-Professional-Data-Engineer training guide. If you have any question, you can just contact us!
Positive Databricks-Certified-Professional-Data-Engineer Feedback: https://www.itcerttest.com/Databricks-Certified-Professional-Data-Engineer_braindumps.html