What's more, part of that Pass4SureQuiz AI-300 dumps now are free: https://drive.google.com/open?id=1qCOYJVAZvperQNPI_o4Nm53cFq4h6EgF
By unremitting effort and studious research of the AI-300 practice materials, they devised our high quality and high effective AI-300 practice materials which win consensus acceptance around the world. They are meritorious experts with a professional background in this line and remain unpretentious attitude towards our AI-300 practice materials all the time. They are unsuspecting experts who you can count on.
| Section | Objectives |
|---|---|
| Design and implement an MLOps infrastructure | - Manage environments, data stores, and model registries - Set up Azure Machine Learning workspace and compute targets - Configure source control, CI/CD pipelines, and automation for ML workflows - Implement security, governance, and compliance for MLOps |
| Implement generative AI quality assurance and observability | - Evaluate generative AI outputs for quality, safety, and grounding - Conduct red teaming, adversarial testing, and content filtering - Monitor latency, token usage, cost, and error rates - Implement logging, tracing, and telemetry for GenAI applications |
| Design and implement a GenAIOps infrastructure | - Manage API keys, rate limits, and responsible AI guardrails - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Configure prompt orchestration, prompt flows, and agent frameworks - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search |
| Optimize generative AI systems and model performance | - Tune prompts, system messages, and grounding strategies - Optimize inference performance, caching, and throughput - Implement cost management and scaling strategies for GenAI workloads - Fine-tune and distill models for specific use cases |
| Implement machine learning model lifecycle and operations | - Retrain, update, and manage model versions in production - Train, register, and version models using Azure Machine Learning - Deploy models to real-time and batch endpoints - Monitor model performance, data drift, and operational health |
To attempt the Microsoft AI-300 exam optimally and ace it on the first attempt, proper exam planning is crucial. Since the Microsoft AI-300 exam demands a lot of time and effort, we designed the Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam dumps in such a way that you won't have to go through sleepless study nights or disturb your schedule. Before starting the Microsoft AI-300 Preparation, plan the amount of time you will allot to each topic, determine the topics that demand more effort and prioritize the components that possess more weightage in the Microsoft AI-300 exam.
NEW QUESTION # 63
You have a deployment of an Azure OpenAI Service base model.
You plan to fine-tune the model.
You need to prepare a file that contains training data.
Which file format should you use?
Answer: A
Explanation:
Azure OpenAI Service fine-tuning requires training data in JSON Lines (JSONL) format - a text file where each line is a self-contained, valid JSON object representing one training example. For chat fine-tuning, each line contains a messages array with system, user, and assistant turns. JSONL is ideal for machine-learning datasets because it is streamable, easy to generate programmatically, and directly supported by the Azure OpenAI fine-tuning API. CSV (option A) and TSV (option B) are tabular formats that cannot natively represent the nested, multi-turn conversation structure required by chat models. Plain JSON (option D) would require loading the entire file as a single object, which is impractical for large datasets and is not accepted by the Azure OpenAI fine-tuning endpoint. Always use JSONL with UTF-8 encoding for Azure OpenAI training files.
Microsoft Learn Reference Topic: Prepare training data for Azure OpenAI fine-tuning - JSONL file format
NEW QUESTION # 64
Drag and Drop Question
An organization uses Microsoft Foundry to develop generative AI projects that access shared Azure resources such as storage accounts and vector databases.
The organization s security policy requires eliminating secret key-based authentication and enforcing least-privilege access.
You must configure identity and access so that:
Services authenticate without stored credentials.
Permissions are scoped appropriately across projects and shared resources.
You need to configure the appropriate identity or access mechanism for each requirement.
What should you configure in Microsoft Foundry to meet each requirement? To answer, move the appropriate configuration mechanisms to the correct requirements. You may use each configuration mechanism once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.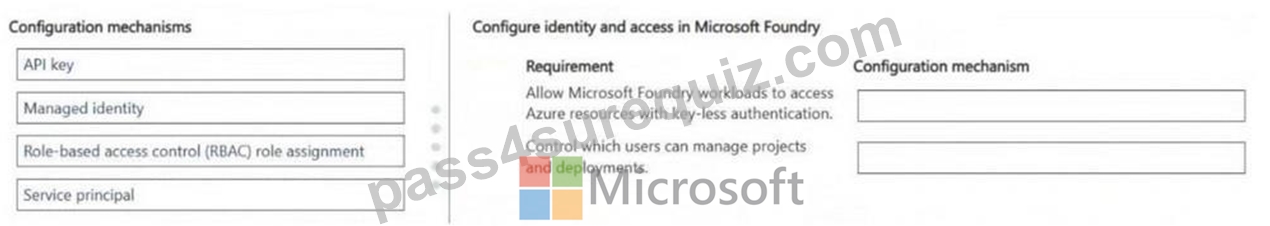
Answer:
Explanation: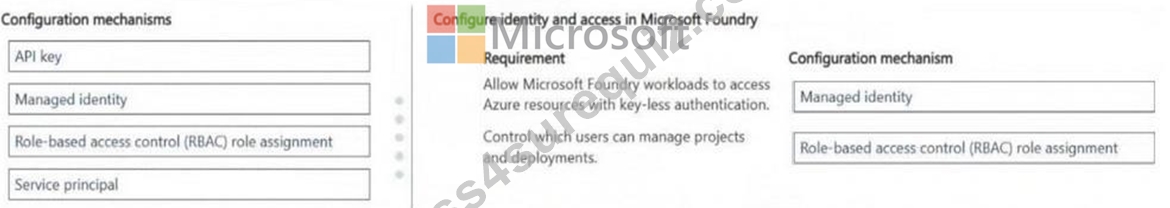
NEW QUESTION # 65
Hotspot Question
You manage an Azure Machine Learning workspace named Workspace1 and an Azure Blob Storage accessed by using the URL https://storage1.blob.core.windows.net/data1.
You plan to create an Azure Blob datastore in Workspace1. The datastore must target the Blob Storage by using Azure Machine Learning Python SDK v2. Access authorization to the datastore must be limited to a specific amount of time.
You need to select the parameters of the AzureBlobDatastore class that will point to the target datastore and authorize access to it.
Which parameters should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.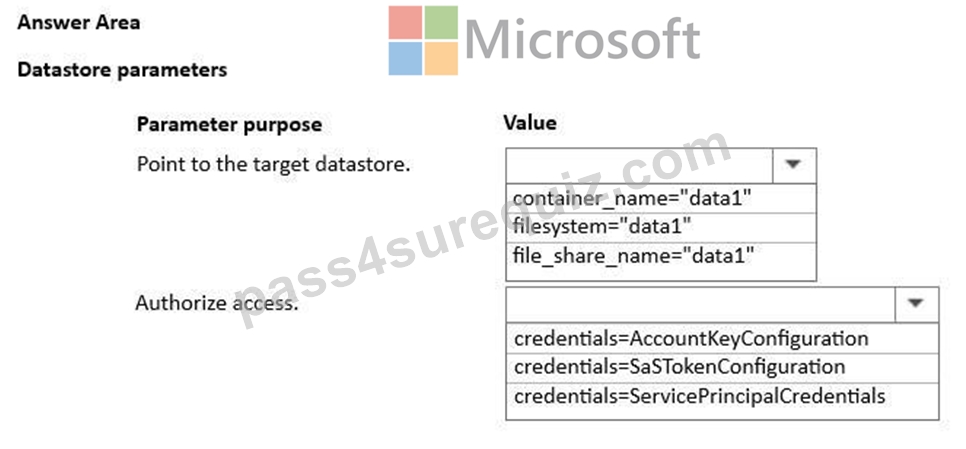
Answer:
Explanation: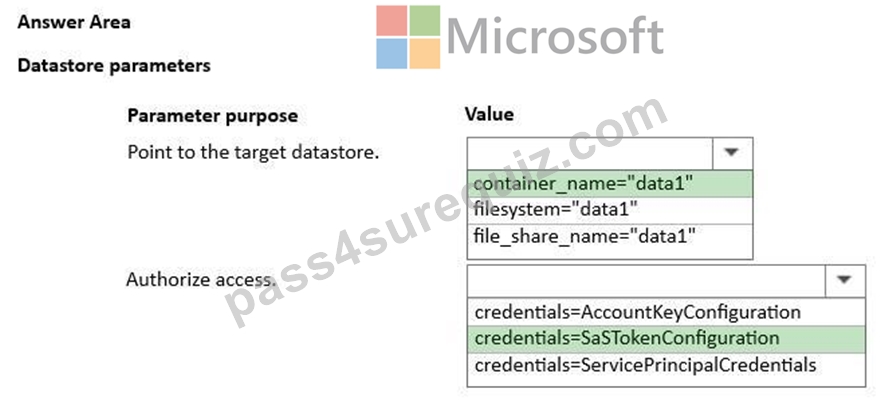
Explanation:
Box 1: container_name = "data1"
Point to target datastore
Example:
# my_blob_datastore.yml
$schema: https://azuremlschemas.azureedge.net/latest/azureBlob.schema.json name: blob_example type: azure_blob description: Datastore pointing to a blob container.
account_name: mytestblobstore
*--> container_name: data-container
credentials:
account_key: XXXxxxXXXxXXXXxxXXXXXxXXXXXxXxxXxXXXxXXX
Box 2: credentials=SASTokenConfiguration
Authorize access
When you create a shared access signature (SAS), the default duration is 48 hours. After 48 hours, you'll need to create a new token.
Consider setting a longer duration period for the time you're using your storage account for Translator Service operations.
Reference:
https://learn.microsoft.com/en-us/azure/ai-services/translator/document-translation/how-to-guides/create-sas-tokens
https://www.brainscape.com/flashcards/path2mod1b-make-data-available-creating-13697887/packs/21445573
NEW QUESTION # 66
You are preparing training data for a fine-tuning job in Microsoft Foundry.
Real production conversations cannot be used due to compliance requirements.
You need to generate synthetic interaction data that can be used for fine-tuning a generative model.
What should you do?
Answer: A
Explanation:
You can use a simulator or an LLM-as-a-judge pipeline to generate synthetic interaction data for fine-tuning. This technique is standard practice for maintaining strict data privacy while training models on specific business tasks.
Here is how to effectively structure and execute a synthetic data generation pipeline for Microsoft Azure AI Foundry (formerly Azure AI Studio).
Generation Methods
Persona-Driven Simulation: Prompt one LLM to act as a customer and another as your support agent to generate multi-turn dialogues.
Seed Data Expansion: Feed 10-20 hand-written, compliant examples into an LLM and instruct it to generate hundreds of diverse variations.
Schema-Based Evolution: Define variables (e.g., product types, user intents, sentiment levels) and programmatically combine them into prompt templates for an LLM to flesh out.
Reference:
https://www.digitaldividedata.com/blog/synthetic-data-generation-in-gen-ai
NEW QUESTION # 67
You create a binary classification model. You use the Fairlearn package to assess model fairness.
You must eliminate the need to retrain the model.
You need to implement the Fairlearn package.
Which algorithm should you use?
Answer: D
Explanation:
The best algorithm to implement within the Fairlearn package for a binary classification model without retraining is the ThresholdOptimizer.
Why ThresholdOptimizer?
This algorithm is a post-processing technique specifically designed to mitigate unfairness after a model has already been trained. By setting the prefit parameter to True, it treats your existing model as a "black box," adjusting its decision thresholds for different groups to satisfy fairness constraints (like demographic parity or equalized odds) without changing the underlying model weights.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/concept-fairness-ml
NEW QUESTION # 68
......
The computer is widely used in all phases of society. If you get a Microsoft certification you will have wide development for business, education, medicine and nearly all walks of life. AI-300 test dumps materials play an important role if you are willing to get a certificate. If you can show your computer skills and talents, it will be your outstanding advantage over others. Pass4SureQuiz Valid AI-300 Test Dumps materials may be your first step to success as an IT worker.
Latest AI-300 Test Format: https://www.pass4surequiz.com/AI-300-exam-quiz.html
What's more, part of that Pass4SureQuiz AI-300 dumps now are free: https://drive.google.com/open?id=1qCOYJVAZvperQNPI_o4Nm53cFq4h6EgF