Exam Databricks Certified-Data-Engineer-Professional Consultant, Online Certified-Data-Engineer-Professional Test

What's more, part of that TestBraindump Certified-Data-Engineer-Professional dumps now are free: https://drive.google.com/open?id=1txCqqsbflhSxG-WTeXT7wQzwHhDEDBn2
About Certified-Data-Engineer-Professional exam, TestBraindump has a great sound quality, will be the most trusted sources. Feedback from the thousands of registration department, a large number of in-depth analysis, we are in a position to determine which supplier will provide you with the latest and the best Certified-Data-Engineer-Professional practice questions. The TestBraindump Databricks Certified-Data-Engineer-Professional Training Materials are constantly being updated and modified, has the highest Databricks Certified-Data-Engineer-Professional training experience. If you want to pass the exam, please using our TestBraindump Databricks Certified-Data-Engineer-Professional exam training materials. TestBraindump Databricks Certified-Data-Engineer-Professional Add to your shopping cart, it will let you see unexpected results.
| Section | Objectives |
|---|
| Topic 1: Debugging and Deploying | - Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
|
| Topic 2: Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Topic 3: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 4: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 2. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 3. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 4. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 5. Create pipeline components using control flow operators such as if/else and foreach
- 6. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 7. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 8. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Develop User-Defined Functions using Pandas/Python UDF
|
| Topic 5: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 4. Apply Change Data Feed to address streaming table limitations and improve latency
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Topic 6: Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Topic 7: Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Topic 8: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use Query Profile and Spark UI to monitor workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 4. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
|
| Topic 9: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Topic 10: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use row filters and column masks to protect sensitive table data
|
>> Exam Databricks Certified-Data-Engineer-Professional Consultant <<
Online Certified-Data-Engineer-Professional Test - Latest Certified-Data-Engineer-Professional Exam Pass4sure
The top personal and professional Databricks Certified-Data-Engineer-Professional certification exam benefits are recognition of skills, updated knowledge, more career opportunities, instant promotion, and increase in salary, etc. If your answer is yes first of all you have to enroll in the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) certification exam and put all your efforts to pass this career advancement certification exam. Are you looking for the right and recommended way to pass the Databricks Certified-Data-Engineer-Professional exam?
Databricks Certified Data Engineer Professional Sample Questions (Q91-Q96):
NEW QUESTION # 91
A data engineer is performing a join operation to combine values from a static userlookup table with a streaming DataFrame streamingDF.
Which code block attempts to perform an invalid stream-static join?
- A. streamingDF.join(userLookup, ["user_id"], how="left")
- B. userLookup.join(streamingDF, ["userid"], how="inner")
- C. streamingDF.join(userLookup, ["userid"], how="inner")
- D. userLookup.join(streamingDF, ["user_id"], how="right")
- E. streamingDF.join(userLookup, ["user_id"], how="outer")
Answer: E
Explanation:
https://spark.apache.org/docs/latest/structured-streaming-programming-guide.html#support-matrix-for-joins-in-streaming-queries
NEW QUESTION # 92
A small company based in the United States has recently contracted a consulting firm in India to implement several new data engineering pipelines to power artificial intelligence applications. All the company's data is stored in regional cloud storage in the United States.
The workspace administrator at the company is uncertain about where the Databricks workspace used by the contractors should be deployed.
Assuming that all data governance considerations are accounted for, which statement accurately informs this decision?
- A. Databricks notebooks send all executable code from the user's browser to virtual machines over the open internet; whenever possible, choosing a workspace region near the end users is the most secure.
- B. Databricks workspaces do not rely on any regional infrastructure; as such, the decision should be made based upon what is most convenient for the workspace administrator.
- C. Cross-region reads and writes can incur significant costs and latency; whenever possible, compute should be deployed in the same region the data is stored.
- D. Databricks runs HDFS on cloud volume storage; as such, cloud virtual machines must be deployed in the region where the data is stored.
- E. Databricks leverages user workstations as the driver during interactive development; as such, users should always use a workspace deployed in a region they are physically near.
Answer: C
Explanation:
This is the correct answer because it accurately informs this decision. The decision is about where the Databricks workspace used by the contractors should be deployed. The contractors are based in India, while all the company's data is stored in regional cloud storage in the United States. When choosing a region for deploying a Databricks workspace, one of the important factors to consider is the proximity to the data sources and sinks. Cross-region reads and writes can incur significant costs and latency due to network bandwidth and data transfer fees.
Therefore, whenever possible, compute should be deployed in the same region the data is stored to optimize performance and reduce costs.
NEW QUESTION # 93
A data engineer, while designing a Pandas UDF to process financial time-series data with complex calculations that require maintaining state across rows within each stock symbol group, must ensure the function is efficient and scalable. Which approach will solve the problem with minimum overhead while preserving data integrity?
- A. Use a SCALAR_ITER Pandas UDF with iterator-based processing, implementing state management through persistent storage (Delta tables) that gets updated after each batch to maintain continuity across iterator chunks.
- B. Use a SCALAR Pandas UDF that processes the entire dataset at once, implementing custom partitioning logic within the UDF to group by stock symbol and maintain state using global variables shared across all executor processes.
- C. Use a grouped_agg Pandas UDF that processes each stock symbol group independently, maintaining state through intermediate aggregation results that get passed between successive UDF calls via broadcast variables.
- D. Use applyInPandas() on a Spark DataFrame that receives all rows for each stock symbol as a Pandas DataFrame, allowing processing within each group while maintaining state variables local to each group's processing function.
Answer: D
Explanation:
The Databricks documentation recommends applyInPandas() for complex per-group operations where maintaining internal state within each group is necessary. When using applyInPandas(), Spark provides all records for each grouping key as a Pandas DataFrame to the function, allowing efficient vectorized operations with local state management. This approach ensures high performance and scalability while maintaining logical isolation between groups. In contrast, SCALAR and SCALAR_ITER UDFs operate on individual rows or batches and cannot maintain inter-row state effectively. grouped_agg UDFs are limited to computing aggregates and do not support complex multi-row transformations. Therefore, applyInPandas() is the correct and Databricks-recommended solution for stateful per-group time-series computations.
NEW QUESTION # 94
Which statement describes Delta Lake optimized writes?
- A. A shuffle occurs prior to writing to try to group data together resulting in fewer files instead of each executor writing multiple files based on directory partitions.
- B. An asynchronous job runs after the write completes to detect if files could be further compacted; yes, an OPTIMIZE job is executed toward a default of 1 GB.
- C. Before a job cluster terminates, OPTIMIZE is executed on all tables modified during the most recent job.
- D. Optimized writes logical partitions instead of directory partitions partition boundaries are only represented in metadata fewer small files are written.
Answer: A
Explanation:
Delta Lake optimized writes involve a shuffle operation before writing out data to the Delta table.
The shuffle operation groups data by partition keys, which can lead to a reduction in the number of output files and potentially larger files, instead of multiple smaller files. This approach can significantly reduce the total number of files in the table, improve read performance by reducing the metadata overhead, and optimize the table storage layout, especially for workloads with many small files.
NEW QUESTION # 95
The following code has been migrated to a Databricks notebook from a legacy workload:
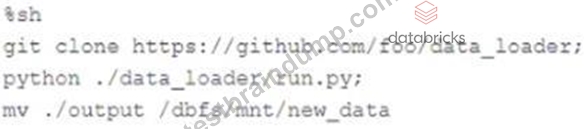
The code executes successfully and provides the logically correct results, however, it takes over
20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
- A. %sh does not distribute file moving operations; the final line of code should be updated to use %fs instead.
- B. Python will always execute slower than Scala on Databricks. The run.py script should be refactored to Scala.
- C. %sh executes shell code on the driver node. The code does not take advantage of the worker nodes or Databricks optimized Spark.
- D. Instead of cloning, the code should use %sh pip install so that the Python code can get executed in parallel across all nodes in a cluster.
- E. %sh triggers a cluster restart to collect and install Git. Most of the latency is related to cluster startup time.
Answer: C
Explanation:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
NEW QUESTION # 96
......
The opportunity is for those who have patience to wait for. If you got the Certified-Data-Engineer-Professional certification before your IT career starts, it will be a good preparation for you to find a satisfactory job. It is not easy to Pass Certified-Data-Engineer-Professional Exam, but with the help of our Certified-Data-Engineer-Professional study materials provided by our TestBraindump, there are so many candidates have pass the exam. Do you want to be one of them? Let our products to help you.
Online Certified-Data-Engineer-Professional Test: https://www.testbraindump.com/Certified-Data-Engineer-Professional-exam-prep.html
- Professional Exam Certified-Data-Engineer-Professional Consultant Spend Your Little Time and Energy to Clear Databricks Certified-Data-Engineer-Professional exam 🤕 Enter ➤ www.vceengine.com ⮘ and search for ➤ Certified-Data-Engineer-Professional ⮘ to download for free 💈Exam Certified-Data-Engineer-Professional Questions
- Quiz Databricks - Certified-Data-Engineer-Professional –High-quality Exam Consultant 🥬 Search for “ Certified-Data-Engineer-Professional ” and obtain a free download on ▷ www.pdfvce.com ◁ 🆎Certified-Data-Engineer-Professional Dumps Reviews
- Download Certified-Data-Engineer-Professional Free Dumps 🎸 Certified-Data-Engineer-Professional Pass Rate ⏳ Certified-Data-Engineer-Professional Reliable Study Notes 🥴 Simply search for ➽ Certified-Data-Engineer-Professional 🢪 for free download on ☀ www.vce4dumps.com ️☀️ 😵Certified-Data-Engineer-Professional Dumps Reviews
- 100% Free Certified-Data-Engineer-Professional – 100% Free Exam Consultant | Online Certified-Data-Engineer-Professional Test 🛅 Easily obtain free download of ▛ Certified-Data-Engineer-Professional ▟ by searching on “ www.pdfvce.com ” 🍩Test Certified-Data-Engineer-Professional Pass4sure
- Download Certified-Data-Engineer-Professional Fee 📎 Certified-Data-Engineer-Professional Reliable Study Notes 😳 Frequent Certified-Data-Engineer-Professional Updates 🦙 Download ➡ Certified-Data-Engineer-Professional ️⬅️ for free by simply entering 《 www.vce4dumps.com 》 website 🛀Valid Certified-Data-Engineer-Professional Exam Syllabus
- [Technology] Databricks Certified-Data-Engineer-Professional Exam Dumps For Good Success 2026 ❇ Search for ☀ Certified-Data-Engineer-Professional ️☀️ and download it for free on ➤ www.pdfvce.com ⮘ website 🎢100% Certified-Data-Engineer-Professional Accuracy
- New Certified-Data-Engineer-Professional Dumps Free 🧝 New Certified-Data-Engineer-Professional Dumps Free 🍬 Relevant Certified-Data-Engineer-Professional Answers 🟦 【 www.troytecdumps.com 】 is best website to obtain 【 Certified-Data-Engineer-Professional 】 for free download 🔛Exam Certified-Data-Engineer-Professional Questions
- Valid Databricks Certified Data Engineer Professional Exam Dumps 100% Guarantee Pass Databricks Certified Data Engineer Professional Exam 👉 Search on { www.pdfvce.com } for ➥ Certified-Data-Engineer-Professional 🡄 to obtain exam materials for free download 🚜Download Certified-Data-Engineer-Professional Fee
- Test Certified-Data-Engineer-Professional Pass4sure 🗼 New Certified-Data-Engineer-Professional Dumps Free 📂 Certified-Data-Engineer-Professional Dumps Reviews 🦘 Download ➤ Certified-Data-Engineer-Professional ⮘ for free by simply entering ➠ www.verifieddumps.com 🠰 website 🆗Relevant Certified-Data-Engineer-Professional Answers
- New Certified-Data-Engineer-Professional Dumps Free 🥉 Certified-Data-Engineer-Professional Dumps Reviews 😝 Certified-Data-Engineer-Professional Reliable Source 🦯 Search for ✔ Certified-Data-Engineer-Professional ️✔️ on 《 www.pdfvce.com 》 immediately to obtain a free download 🧳Certified-Data-Engineer-Professional Pass Rate
- Certified-Data-Engineer-Professional Dumps Reviews 🕺 Certified-Data-Engineer-Professional Valid Test Registration ⌚ Certified-Data-Engineer-Professional Valid Test Registration 🤗 Search for ▷ Certified-Data-Engineer-Professional ◁ on [ www.pdfdumps.com ] immediately to obtain a free download 🐘Certified-Data-Engineer-Professional Valid Learning Materials
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, nvinio.com, www.flirtic.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! Download part of TestBraindump Certified-Data-Engineer-Professional dumps for free: https://drive.google.com/open?id=1txCqqsbflhSxG-WTeXT7wQzwHhDEDBn2