BONUS!!! Tech4Exam MLA-C01ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=14HTioPBFdg21YLzDz3dGpzQ3w-nLknt1
IT業界で仕事している皆さんはIT認定試験の資格の重要性をよく知っていているでしょう。IT認定試験には多くの種類があります。現在最も人気がある試験もいろいろあります。例えばMLA-C01認定試験などです。その中の試験、どちらを受験しましたか。もし一つの認証資格を持っていないなら、IT認定試験を申し込んで試験の資格を取得する必要があります。試験を受ける予定があれば、急いでTech4Examへ来て必要な情報を見つけましょう。Tech4ExamはあなたがMLA-C01認定試験に合格する保障ですから。
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Certificate Validity Period: | 3 years |
| Real Exam Qty: | 65 (50 scored, 15 unscored) |
| Available Languages: | Japanese, Korean, English, Simplified Chinese |
| Exam Price: | 150 USD |
| Passing Score: | 720 (scaled score 100–1000) |
| Exam Format: | Case study, Matching, Ordering, Multiple response, Multiple choice |
| Related Certifications: | AWS Certified AI Practitioner AWS Certified Machine Learning - Specialty |
| Exam Duration: | 130 minutes |
| Recommended Training: | AWS Training and Certification AWS Certified Machine Learning Engineer - Associate Official Exam Guide |
| Exam Registration: | Pearson VUE Registration AWS Certification Portal |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE testing centers |
| Pre Condition: | Recommended: 1+ year hands-on experience with AWS services and machine learning engineering; familiarity with Amazon SageMaker and related ML services. No mandatory prerequisite exams. |
| Official Syllabus URL: | https://docs.aws.amazon.com/aws-certification/latest/machine-learning-engineer-associate-01/machine-learning-engineer-associate-01.html |
AmazonのMLA-C01認定試験は今IT業界の人気試験で多くのIT業界の専門の人士がITの関連の認証試験を取りたいです。Amazonの認証試験の合格書を取ってから更にあなたのIT業界での仕事にとても助けがあると思います。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
質問 # 74
A company stores historical data in .csv files in Amazon S3. Only some of the rows and columns in the .csv files are populated. The columns are not labeled. An ML engineer needs to prepare and store the data so that the company can use the data to train ML models.
Select and order the correct steps from the following list to perform this task. Each step should be selected one time or not at all. (Select and order three.)
* Create an Amazon SageMaker batch transform job for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
* Use Amazon Athena to infer the schemas and available columns.
* Use AWS Glue crawlers to infer the schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.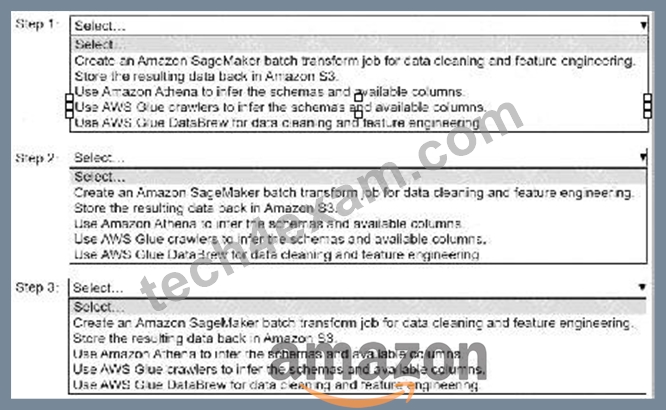
正解:
解説: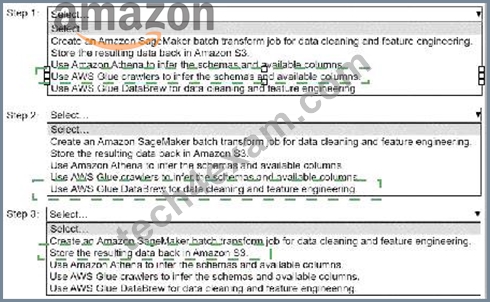
Explanation:
Step 1: Use AWS Glue crawlers to infer the schemas and available columns.
Step 2: Use AWS Glue DataBrew for data cleaning and feature engineering.
Step 3: Store the resulting data back in Amazon S3.
Step 1: Use AWS Glue Crawlers to Infer Schemas and Available Columns
Why? The data is stored in .csv files with unlabeled columns, and Glue Crawlers can scan the raw data in Amazon S3 to automatically infer the schema, including available columns, data types, and any missing or incomplete entries.
How? Configure AWS Glue Crawlers to point to the S3 bucket containing the .csv files, and run the crawler to extract metadata. The crawler creates a schema in the AWS Glue Data Catalog, which can then be used for subsequent transformations.
Step 2: Use AWS Glue DataBrew for Data Cleaning and Feature Engineering Why? Glue DataBrew is a visual data preparation tool that allows for comprehensive cleaning and transformation of data. It supports imputation of missing values, renaming columns, feature engineering, and more without requiring extensive coding.
How? Use Glue DataBrew to connect to the inferred schema from Step 1 and perform data cleaning and feature engineering tasks like filling in missing rows/columns, renaming unlabeled columns, and creating derived features.
Step 3: Store the Resulting Data Back in Amazon S3
Why? After cleaning and preparing the data, it needs to be saved back to Amazon S3 so that it can be used for training machine learning models.
How? Configure Glue DataBrew to export the cleaned data to a specific S3 bucket location. This ensures the processed data is readily accessible for ML workflows.
Order Summary:
Use AWS Glue crawlers to infer schemas and available columns.
Use AWS Glue DataBrew for data cleaning and feature engineering.
Store the resulting data back in Amazon S3.
This workflow ensures that the data is prepared efficiently for ML model training while leveraging AWS services for automation and scalability.
質問 # 75
A company stores time-series data about user clicks in an Amazon S3 bucket. The raw data consists of millions of rows of user activity every day. ML engineers access the data to develop their ML models.
The ML engineers need to generate daily reports and analyze click trends over the past 3 days by using Amazon Athena. The company must retain the data for 30 days before archiving the data.
Which solution will provide the HIGHEST performance for data retrieval?
正解:A
質問 # 76
An ML engineer wants to deploy an Amazon SageMaker AI model for inference. The payload sizes are less than 3 MB. Processing time does not exceed 45 seconds. The traffic patterns will be irregular or unpredictable.
Which inference option will meet these requirements MOST cost-effectively?
正解:B
解説:
Amazon SageMaker Serverless Inference is designed for irregular or unpredictable traffic patterns. It automatically provisions and scales compute resources based on request volume and scales down to zero when idle, making it the most cost-effective option.
Serverless inference supports payloads up to 6 MB and request durations up to 60 seconds, which comfortably meets the stated constraints. Customers are billed only for actual compute usage during inference execution, not for idle capacity.
Asynchronous inference is intended for long-running jobs (up to 1 hour) and large payloads (up to 1 GB).
Real-time inference requires always-on instances, increasing cost during idle periods. Batch transform is designed for offline processing.
Therefore, serverless inference is the optimal choice.
質問 # 77
An ML engineer needs to deploy ML models to get inferences from large datasets in an asynchronous manner. The ML engineer also needs to implement scheduled monitoring of data quality for the models and must receive alerts when changes in data quality occur.
Which solution will meet these requirements?
正解:A
解説:
This requirement combines asynchronous inference on large datasets with automated data quality monitoring and alerting. AWS documentation explicitly recommends Amazon SageMaker batch transform for large- scale, asynchronous inference workloads. Batch transform jobs process large datasets stored in Amazon S3 without requiring a persistent endpoint, making them cost-effective and scalable.
For data quality monitoring, Amazon SageMaker Model Monitor is the AWS-native solution. Model Monitor can be scheduled to analyze inference data, compare it against a baseline, and detect data quality issues such as missing values, schema changes, or statistical drift. When violations occur, Model Monitor emits metrics to Amazon CloudWatch, where alarms can trigger alerts.
Options A, B, and C lack ML-aware data quality monitoring capabilities. AWS Glue and Batch are not designed for model data quality analysis, and CloudTrail tracks API activity-not data quality.
AWS best practices clearly position Batch Transform + Model Monitor as the correct architecture for asynchronous inference with automated monitoring and alerting.
Therefore, Option D is the correct and AWS-verified solution.
質問 # 78
A customer call center uses Amazon Transcribe to convert hundreds of audio recordings of conversations between customers and support agents to text files. The call center wants to use the text files to train an ML model. To comply with industry regulations, the call center must remove customer names, addresses, and phone numbers from the training text files.
Which solution will meet these requirements with the LEAST development effort?
正解:A
解説:
Option B is correct because AWS Glue provides a built-in Detect PII transform that can detect, mask, or remove personally identifiable information with minimal custom development. AWS documentation says the Detect PII transform can process predefined AWS-managed PII entity types and supports actions such as removing or masking values. The examples in AWS docs explicitly mention sensitive entities such as phone numbers and addresses , which directly match the problem statement.
The question specifically asks for the least development effort . That wording makes AWS Glue Detect PII the strongest answer because it is a native transformation capability rather than a custom code-heavy workflow. AWS also documents fine-grained sensitive data detection features that let you apply actions per entity type, improving usability and reducing the need to build custom parsing and redaction logic yourself.
This is much easier than creating Lambda-based transformation code or custom text-cleaning logic inside another ML preprocessing tool.
The other options are less suitable. Amazon Bedrock Guardrails is not the standard AWS service documented for bulk ETL-style redaction of training text files in this context. S3 Object Lambda would require more custom engineering to inspect and redact each object. SageMaker Data Wrangler custom transformation would also involve extra implementation work compared with using a purpose-built Glue transform. Because the call center already has text output and simply needs regulated fields like names, addresses, and phone numbers removed before training, the AWS-native low-effort solution is AWS Glue Detect PII . Therefore, the best verified answer is B .
質問 # 79
......
MLA-C01テスト内容: https://www.tech4exam.com/MLA-C01-pass-shiken.html
P.S.Tech4ExamがGoogle Driveで共有している無料の2026 Amazon MLA-C01ダンプ:https://drive.google.com/open?id=14HTioPBFdg21YLzDz3dGpzQ3w-nLknt1