2026 Latest PrepAwayPDF DY0-001 PDF Dumps and DY0-001 Exam Engine Free Share: https://drive.google.com/open?id=1HIMJkBSZXo07JCD0C8xbMoDmCPpRqIw0
A good brand is not a cheap product, but a brand that goes well beyond its users' expectations. The value of a brand is that the DY0-001 exam questions are more than just exam preparation tool -- it should be part of our lives, into our daily lives. Do this, therefore, our DY0-001 question guide has become the industry well-known brands, but even so, we have never stopped the pace of progress, we have been constantly updated the DY0-001 real study guide. Our DY0-001 real study guide provides users with comprehensive learning materials, so that users can keep abreast of the progress of The Times.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
Through our investigation and analysis of the real problem over the years, our DY0-001 prepare questions can accurately predict the annual DY0-001 exams. In the actual exam process, users will encounter almost half of the problem is similar in our products. Even if the syllabus is changing every year, the DY0-001 quiz guide’s experts still have the ability to master propositional trends. Believe that such a high hit rate can better help users in the review process to build confidence, and finally help users through the qualification examination to obtain a certificate. All in all, we want you to have the courage to challenge yourself, and our DY0-001 Exam Prep will do the best for the user's expectations.
NEW QUESTION # 48
Which of the following distribution methods or models can most effectively represent the actual arrival times of a bus that runs on an hourly schedule?
Answer: C
Explanation:
# A Normal distribution is appropriate for modeling variables that cluster around a central mean and have natural variability - such as bus arrival times around a scheduled time. Even though the bus is scheduled hourly, real-world factors (traffic, weather, etc.) will cause actual arrival times to vary normally around the scheduled mean.
Why the other options are incorrect:
* A: Binomial is for discrete yes/no trials, not continuous time modeling.
* B: Exponential models time between events, typically memoryless - not suitable for arrival distributions with a known mean and variance.
* D: Poisson models event counts per time interval, not the timing of continuous events like arrival times.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 1.3:"Normal distributions are appropriate for modeling real-world continuous variables that fluctuate around a central tendency, such as scheduled processes."
* Statistics for Data Science, Chapter 4 - Distributions:"Arrival times of periodic services often approximate a normal distribution when influenced by continuous variation."
-
NEW QUESTION # 49
A data scientist is building an inferential model with a single predictor variable. A scatter plot of the independent variable against the real-number dependent variable shows a strong relationship between them.
The predictor variable is normally distributed with very few outliers. Which of the following algorithms is the best fit for this model, given the data scientist wants the model to be easily interpreted?
Answer: A
Explanation:
The scenario provided describes a modeling problem with the following characteristics:
* A single continuous predictor variable (independent variable).
* A continuous real-number dependent variable.
* The relationship between the variables appears strong and linear, as observed from the scatter plot.
* The predictor variable is normally distributed with minimal outliers.
* The goal is to maintain interpretability in the model.
Based on the above, the most appropriate modeling technique is:
Linear Regression: This is a statistical method used to model the linear relationship between a continuous dependent variable and one or more independent variables. In simple linear regression, a straight line (y = mx
+ b) represents the relationship, where the slope and intercept can be easily interpreted. This method is preferred when the relationship is linear, the assumptions of normality and homoscedasticity are satisfied, and interpretability is required.
Why the other options are incorrect:
* A. Logistic Regression: This is used when the dependent variable is categorical (e.g., binary classification), not continuous. Therefore, not suitable for this case.
* B. Exponential Regression: Applied when the data shows an exponential growth or decay pattern, which is not implied here.
* D. Probit Regression: Similar to logistic regression but based on a normal cumulative distribution.
Used for categorical outcomes, not continuous variables.
Exact Extract and Official References:
* CompTIA DataX (DY0-001) Official Study Guide, Domain: Modeling, Analysis, and Outcomes:
"Linear regression is the most interpretable form of regression modeling. It assumes a linear relationship between independent and dependent variables and is ideal for inferential modeling when interpretability is important." (Section 3.1, Model Selection Criteria)
* Data Science Fundamentals, by CompTIA and DS Institute:
"Linear regression is a robust and interpretable statistical method used for modeling continuous outcomes. It provides coefficients which help in understanding the strength and direction of the relationship." (Chapter 4, Regression Techniques)
NEW QUESTION # 50
SIMULATION
A data scientist needs to determine whether product sales are impacted by other contributing factors. The client has provided the data scientist with sales and other variables in the data set.
The data scientist decides to test potential models that include other information.
INSTRUCTIONS
Part 1
Use the information provided in the table to select the appropriate regression model.
Part 2
Review the summary output and variable table to determine which variable is statistically significant.
If at any time you would like to bring back the initial state of the simulation, please click the Reset All button.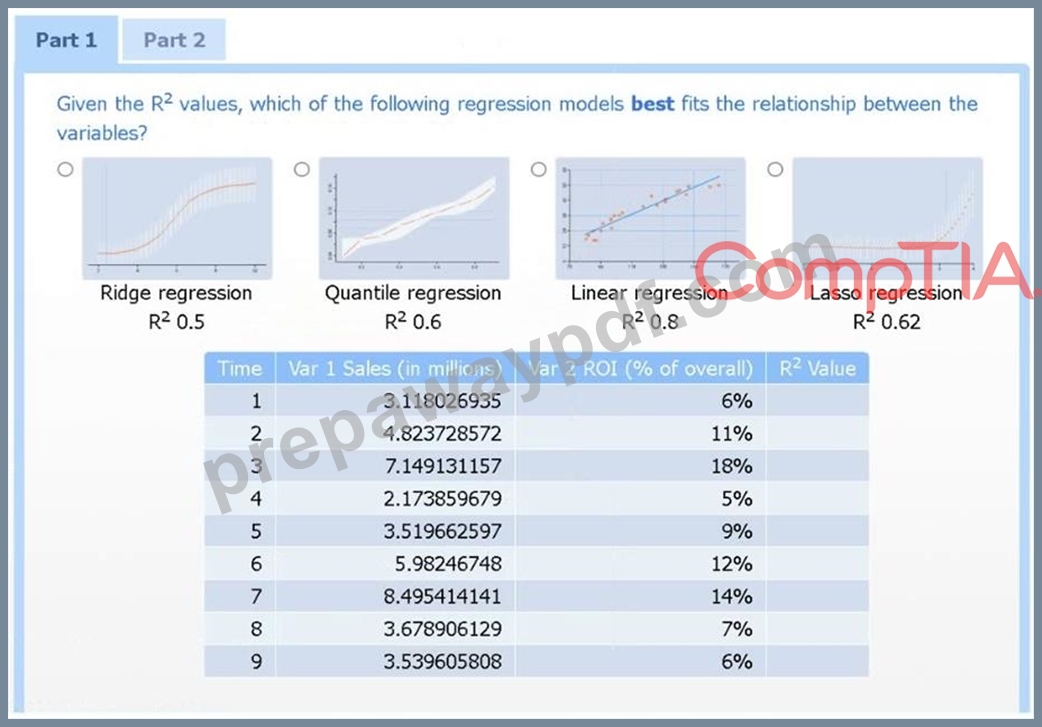



Answer:
Explanation:
Part 1
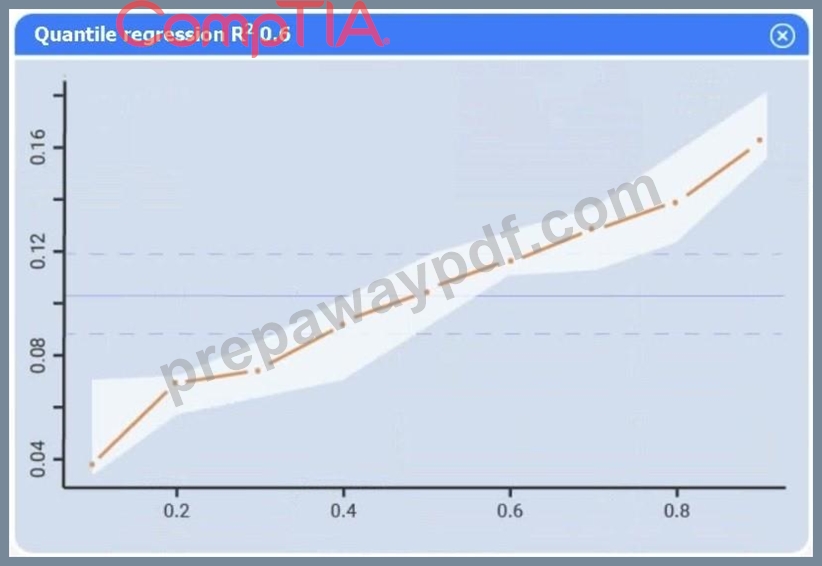
Linear regression.
Of the four models, linear regression has the highest R² (0.8), indicating it explains the greatest proportion of variance in sales.
Part 2
Var 4 - Net operations cost.
Net operations cost has a p-value of essentially 0 (far below 0.05), indicating it is the only additional predictor statistically significant in explaining sales. Neither inventory cost (p≈0.90) nor initial investment (p≈0.23) reach significance.
NEW QUESTION # 51
Which of the following is the layer that is responsible for the depth in deep learning?
Answer: A
Explanation:
In deep learning, the term "depth" refers to the number of layers between the input and output. These intermediate layers are called hidden layers because their outputs are not directly observed.
Hidden layers are where the network learns hierarchical features. As more hidden layers are added, the model becomes deeper, allowing it to learn more complex patterns and representations from the data.
Why the other options are incorrect:
* A. Convolution: This is a specific type of operation applied in convolutional neural networks (CNNs) but is not the general source of model depth.
* B. Dropout: A regularization technique used to prevent overfitting; it doesn't contribute to the model's depth.
* C. Pooling: Reduces the dimensionality of feature maps; not responsible for the depth of the network.
Exact Extract and Official References:
* CompTIA DataX (DY0-001) Official Study Guide, Domain: Machine Learning
"In deep neural networks, hidden layers represent the model's depth. Each hidden layer allows the network to learn more abstract and high-level features." (Section 4.3, Deep Learning Fundamentals)
* Deep Learning Textbook by Ian Goodfellow, Yoshua Bengio, and Aaron Courville:
"Depth in deep learning refers to the number of hidden layers in the network. Each hidden layer extracts increasingly abstract features of the input data." (Chapter 6, Feedforward Deep Networks)
NEW QUESTION # 52
A data scientist wants to predict a person's travel destination. The options are:
* Branson, Missouri, United States
* Mount Kilimanjaro, Tanzania
* Disneyland Paris, Paris, France
* Sydney Opera House, Sydney, Australia
Which of the following models would best fit this use case?
Answer: D
Explanation:
# Linear Discriminant Analysis (LDA) is a supervised classification method used to predict a categorical target (such as travel destination) based on multiple input features. It models decision boundaries between classes - which is appropriate when predicting a fixed set of destinations.
Why the other options are incorrect:
* B: k-means is unsupervised and doesn't use labeled output like travel destination.
* C: Latent Semantic Analysis is used for extracting relationships from textual data - not categorical prediction.
* D: PCA reduces dimensionality but doesn't classify.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 4.1:"Linear Discriminant Analysis is used when the response variable is categorical and the objective is classification."
* Classification Techniques Guide, Chapter 7:"LDA excels in multi-class prediction when the input data is continuous and the output is a known category."
-
NEW QUESTION # 53
......
We have authoritative production team made up by thousands of experts helping you get hang of our DY0-001 study question and enjoy the high quality study experience. We will update the content of DY0-001 test guide from time to time according to recent changes of examination outline and current policies. Besides, our DY0-001 Exam Questions can help you optimize your learning method by simplifying obscure concepts so that you can master better. One more to mention, with our DY0-001 test guide, there is no doubt that you can cut down your preparing time in 20-30 hours of practice before you take the exam.
Test DY0-001 Questions Answers: https://www.prepawaypdf.com/CompTIA/DY0-001-practice-exam-dumps.html
What's more, part of that PrepAwayPDF DY0-001 dumps now are free: https://drive.google.com/open?id=1HIMJkBSZXo07JCD0C8xbMoDmCPpRqIw0