権威のあるDatabricks-Certified-Professional-Data-Engineer試験対策書 &合格スムーズDatabricks-Certified-Professional-Data-Engineer模擬解説集 |一生懸命にDatabricks-Certified-Professional-Data-Engineer復習攻略問題

2026年Tech4Examの最新Databricks-Certified-Professional-Data-Engineer PDFダンプおよびDatabricks-Certified-Professional-Data-Engineer試験エンジンの無料共有:https://drive.google.com/open?id=1EMZskZpmrNvrvwhzBnqz07rBHK3FeBn5
すべての顧客の要求を満たすため、PDFバージョン、ソフトバージョン、APPバージョンの3つの異なるバージョンのDatabricks-Certified-Professional-Data-Engineer学習教材をすべての顧客に提供することをお約束します。さらに、高品質のDatabricks-Certified-Professional-Data-Engineer模擬学習教材をリーズナブルな価格で提供しますが、すべてのお客様にさまざまなメリットがあります。 Databricks-Certified-Professional-Data-Engineer認定ガイドの助けを借りてDatabricks-Certified-Professional-Data-Engineer試験に合格することを心から願っています。ぜひ、Databricks-Certified-Professional-Data-Engineer学習準備を購入してください!
Databricks Databricks-Certified-Professional-Data-Engineer Exam Syllabus Topics:
| Section | Objectives |
|---|
| Data Ingestion and Transformation | - Handle batch and streaming data pipelines
- Ingest data using Apache Spark and Databricks
- Transform and clean datasets using Spark SQL and DataFrame APIs
|
| Data Modeling and Storage | - Schema evolution and data partitioning strategies
- Delta Lake table design and optimization
- Design scalable data lakehouse architectures
|
| Production Pipelines and Orchestration | - Pipeline reliability and fault tolerance
- Automate ETL pipelines and scheduling
- Build and manage workflows using Databricks Jobs
|
| Security, Governance, Monitoring, and Optimization | - Cost optimization and performance tuning
- Implement Unity Catalog governance and access control
- Monitor and optimize Spark workloads
|
>> Databricks-Certified-Professional-Data-Engineer試験対策書 <<
Databricks Databricks-Certified-Professional-Data-Engineer模擬解説集、Databricks-Certified-Professional-Data-Engineer復習攻略問題
Databricks-Certified-Professional-Data-Engineer準備ガイドを使用して、最高の証明書学習体験をお楽しみください。まず、5〜10分でお支払い後、短納期でお届けします。オンラインでDatabricks-Certified-Professional-Data-Engineerガイドトレントをお送りします。つまり、時間の無駄を避けるためにすぐに勉強することができます。加えて、当社のDatabricks-Certified-Professional-Data-Engineer試験トレントの使用中に技術的および運用上の問題に対処するのに問題がある場合は、すぐにご連絡ください。
Databricks Certified Professional Data Engineer Exam 認定 Databricks-Certified-Professional-Data-Engineer 試験問題 (Q94-Q99):
質問 # 94
Which of the following techniques structured streaming uses to create an end-to-end fault toler-ance?
- A. Checkpointing and Water marking
- B. Write ahead logging and water marking
- C. Write ahead logging and idempotent sinks
- D. Checkpointing and idempotent sinks
- E. Stream will failover to available nodes in the cluste
正解:D
解説:
Explanation
The answer is Checkpointing and idempotent sinks
How does structured streaming achieves end to end fault tolerance:
*First, Structured Streaming uses checkpointing and write-ahead logs to record the offset range of data being processed during each trigger interval.
*Next, the streaming sinks are designed to be _idempotent_-that is, multiple writes of the same data (as identified by the offset) do not result in duplicates being written to the sink.
Taken together, replayable data sources and idempotent sinks allow Structured Streaming to en-sure end-to-end, exactly-once semantics under any failure condition.
質問 # 95
The data governance team is reviewing user for deleting records for compliance with GDPR. The following logic has been implemented to propagate deleted requests from the user_lookup table to the user aggregate table.
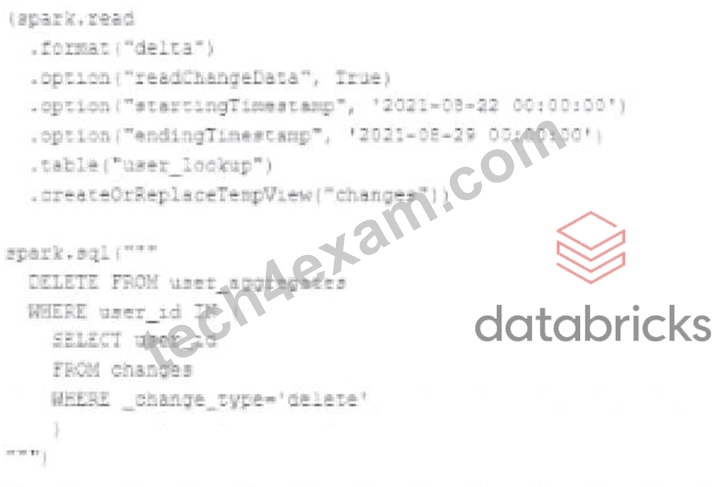
Assuming that user_id is a unique identifying key and that all users have requested deletion have been removed from the user_lookup table, which statement describes whether successfully executing the above logic guarantees that the records to be deleted from the user_aggregates table are no longer accessible and why?
- A. No: the Delta Lake DELETE command only provides ACID guarantees when combined with the MERGE INTO command
- B. No: the change data feed only tracks inserts and updates not deleted records.
- C. No: files containing deleted records may still be accessible with time travel until a BACUM command is used to remove invalidated data files.
- D. Yes: Delta Lake ACID guarantees provide assurance that the DELETE command successed fully and permanently purged these records.
正解:C
解説:
The DELETE operation in Delta Lake is ACID compliant, which means that once the operation is successful, the records are logically removed from the table. However, the underlying files that contained these records may still exist and be accessible via time travel to older versions of the table. To ensure that these records are physically removed and compliance with GDPR is maintained, a VACUUM command should be used to clean up these data files after a certain retention period. The VACUUM command will remove the files from the storage layer, and after this, the records will no longer be accessible.
質問 # 96
A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on Task A.
If task A fails during a scheduled run, which statement describes the results of this run?
- A. Unless all tasks complete successfully, no changes will be committed to the Lakehouse; because task A failed, all commits will be rolled back automatically.
- B. Tasks B and C will be skipped; some logic expressed in task A may have been committed before task failure.
- C. Tasks B and C will attempt to run as configured; any changes made in task A will be rolled back due to task failure.
- D. Tasks B and C will be skipped; task A will not commit any changes because of stage failure.
- E. Because all tasks are managed as a dependency graph, no changes will be committed to the Lakehouse until all tasks have successfully been completed.
正解:B
解説:
Explanation
When a Databricks job runs multiple tasks with dependencies, the tasks are executed in a dependency graph. If a task fails, the downstream tasks that depend on it are skipped and marked as Upstream failed. However, the failed task may have already committed some changes to the Lakehouse before the failure occurred, and those changes are not rolled back automatically. Therefore, the job run may result in a partial update of the Lakehouse. To avoid this, you can use the transactional writes feature of Delta Lake to ensure that the changes are only committed when the entire job run succeeds. Alternatively, you can use the Run if condition to configure tasks to run even when some or all of their dependencies have failed, allowing your job to recover from failures and continue running. References:
transactional writes: https://docs.databricks.com/delta/delta-intro.html#transactional-writes Run if: https://docs.databricks.com/en/workflows/jobs/conditional-tasks.html
質問 # 97
Newly joined data analyst requested read-only access to tables, assuming you are owner/admin which section of Databricks platform is going to facilitate granting select access to the user
- A. Azure RBAC
- B. Admin console
- C. User settings
- D. Azure Databricks control pane IAM
- E. Data explorer
正解:E
解説:
Explanation
Anser is Data Explorer
https://docs.databricks.com/sql/user/data/index.html
Data explorer lets you easily explore and manage permissions on databases and tables. Users can view schema details, preview sample data, and see table details and properties. Administrators can view and change owners, and admins and data object owners can grant and revoke permissions.
To open data explorer, click Data in the sidebar.
質問 # 98
Although the Databricks Utilities Secrets module provides tools to store sensitive credentials and avoid accidentally displaying them in plain text users should still be careful with which credentials are stored here and which users have access to using these secrets.
Which statement describes a limitation of Databricks Secrets?
- A. The Databricks REST API can be used to list secrets in plain text if the personal access token has proper credentials.
- B. Iterating through a stored secret and printing each character will display secret contents in plain text.
- C. Because the SHA256 hash is used to obfuscate stored secrets, reversing this hash will display the value in plain text.
- D. Account administrators can see all secrets in plain text by logging on to the Databricks Accounts console.
- E. Secrets are stored in an administrators-only table within the Hive Metastore; database administrators have permission to query this table by default.
正解:A
解説:
This is the correct answer because it describes a limitation of Databricks Secrets. Databricks Secrets is a module that provides tools to store sensitive credentials and avoid accidentally displaying them in plain text.
Databricks Secrets allows creating secret scopes, which are collections of secrets that can be accessed by users or groups. Databricks Secrets also allows creating and managing secrets using the Databricks CLI or the Databricks REST API. However, a limitation of Databricks Secrets is that the Databricks REST API can be used to list secrets in plain text if the personal access token has proper credentials. Therefore, users should still be careful with which credentials are stored in Databricks Secrets and which users have access to using these secrets. Verified References: [Databricks Certified Data Engineer Professional], under "Databricks Workspace" section; Databricks Documentation, under "List secrets" section.
質問 # 99
......
長年の訂正と修正を受けて、Databricks-Certified-Professional-Data-Engineer試験問題はすでに完璧になっています。彼らは、エラーのない有望な練習資料です。当社はまた、顧客第一です。そのため、まずあなたの興味のある事実を考慮します。お客様のニーズに基づいたすべての先入観とこれらすべてが、満足のいく快適な購入サービスを提供するための当社の信念を説明しています。 Databricks-Certified-Professional-Data-Engineerをシミュレートする実践がすべての責任を負い、予測可能な結果をもたらす可能性があり、私たちを確実に信じることを後悔することはありません。
Databricks-Certified-Professional-Data-Engineer模擬解説集: https://www.tech4exam.com/Databricks-Certified-Professional-Data-Engineer-pass-shiken.html
- Databricks-Certified-Professional-Data-Engineer問題数 🔡 Databricks-Certified-Professional-Data-Engineer的中問題集 🛳 Databricks-Certified-Professional-Data-Engineer的中合格問題集 🥥 Open Webサイト➽ www.japancert.com 🢪検索➠ Databricks-Certified-Professional-Data-Engineer 🠰無料ダウンロードDatabricks-Certified-Professional-Data-Engineer模擬解説集
- 完璧なDatabricks Databricks-Certified-Professional-Data-Engineer試験対策書 - 合格スムーズDatabricks-Certified-Professional-Data-Engineer模擬解説集 | 100%合格率のDatabricks-Certified-Professional-Data-Engineer復習攻略問題 ℹ ➠ Databricks-Certified-Professional-Data-Engineer 🠰の試験問題は▶ www.goshiken.com ◀で無料配信中Databricks-Certified-Professional-Data-Engineerテストサンプル問題
- 完璧なDatabricks Databricks-Certified-Professional-Data-Engineer試験対策書 - 合格スムーズDatabricks-Certified-Professional-Data-Engineer模擬解説集 | 100%合格率のDatabricks-Certified-Professional-Data-Engineer復習攻略問題 🗓 ✔ www.xhs1991.com ️✔️に移動し、[ Databricks-Certified-Professional-Data-Engineer ]を検索して、無料でダウンロード可能な試験資料を探しますDatabricks-Certified-Professional-Data-Engineer日本語版テキスト内容
- Databricks-Certified-Professional-Data-Engineer的中問題集 🤴 Databricks-Certified-Professional-Data-Engineerトレーニング費用 💮 Databricks-Certified-Professional-Data-Engineer的中合格問題集 ⚪ ▷ www.goshiken.com ◁を入力して( Databricks-Certified-Professional-Data-Engineer )を検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineerトレーニング費用
- Databricks-Certified-Professional-Data-Engineer試験の準備方法|認定するDatabricks-Certified-Professional-Data-Engineer試験対策書試験|素敵なDatabricks Certified Professional Data Engineer Exam模擬解説集 🧴 検索するだけで▷ www.xhs1991.com ◁から✔ Databricks-Certified-Professional-Data-Engineer ️✔️を無料でダウンロードDatabricks-Certified-Professional-Data-Engineerトレーニング費用
- Databricks-Certified-Professional-Data-Engineer試験の準備方法|最新なDatabricks-Certified-Professional-Data-Engineer試験対策書試験|効率的なDatabricks Certified Professional Data Engineer Exam模擬解説集 🔢 { Databricks-Certified-Professional-Data-Engineer }を無料でダウンロード⮆ www.goshiken.com ⮄ウェブサイトを入力するだけDatabricks-Certified-Professional-Data-Engineer日本語資格取得
- Databricks-Certified-Professional-Data-Engineer最新な問題集 💎 Databricks-Certified-Professional-Data-Engineer試験解答 💈 Databricks-Certified-Professional-Data-Engineer問題と解答 📲 今すぐ⇛ www.mogiexam.com ⇚で“ Databricks-Certified-Professional-Data-Engineer ”を検索して、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer学習指導
- Databricks-Certified-Professional-Data-Engineer必殺問題集 🟩 Databricks-Certified-Professional-Data-Engineer学習指導 🧧 Databricks-Certified-Professional-Data-Engineer必殺問題集 💘 ウェブサイト⏩ www.goshiken.com ⏪から✔ Databricks-Certified-Professional-Data-Engineer ️✔️を開いて検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer受験料
- Databricks-Certified-Professional-Data-Engineerテストサンプル問題 💺 Databricks-Certified-Professional-Data-Engineerトレーニング 🔋 Databricks-Certified-Professional-Data-Engineer受験料 📅 ➽ www.xhs1991.com 🢪に移動し、➽ Databricks-Certified-Professional-Data-Engineer 🢪を検索して、無料でダウンロード可能な試験資料を探しますDatabricks-Certified-Professional-Data-Engineer最新な問題集
- 更新するDatabricks-Certified-Professional-Data-Engineer試験対策書試験-試験の準備方法-完璧なDatabricks-Certified-Professional-Data-Engineer模擬解説集 ✈ 最新[ Databricks-Certified-Professional-Data-Engineer ]問題集ファイルは[ www.goshiken.com ]にて検索Databricks-Certified-Professional-Data-Engineer問題数
- 完璧なDatabricks Databricks-Certified-Professional-Data-Engineer試験対策書 - 合格スムーズDatabricks-Certified-Professional-Data-Engineer模擬解説集 | 100%合格率のDatabricks-Certified-Professional-Data-Engineer復習攻略問題 🐨 ウェブサイト➤ www.passtest.jp ⮘から▛ Databricks-Certified-Professional-Data-Engineer ▟を開いて検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer試験解答
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, backloggd.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
さらに、Tech4Exam Databricks-Certified-Professional-Data-Engineerダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1EMZskZpmrNvrvwhzBnqz07rBHK3FeBn5