BONUS!!! Download part of PDF4Test DP-750 dumps for free: https://drive.google.com/open?id=1xRpF3JX-atgeZM2EKHBVyzYPn6hPqoYX
PDF4Test have a huge senior IT expert team. They use their professional IT knowledge and rich experience to develop a wide range of different training plans which can help you pass Microsoft certification DP-750 exam successfully. In PDF4Test you can always find out the most suitable training way for you to pass the exam easily. No matter you choose which kind of the training method, PDF4Test will provide you a free one-year update service. PDF4Test's information resources are very wide and also very accurate. When selecting PDF4Test, passing Microsoft Certification DP-750 Exam is much more simple for you.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Data quality and validation
|
| Topic 2: Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Topic 3: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 4: Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
DP-750 exam dumps save your study and preparation time. Our experts have added hundreds of Implementing Data Engineering Solutions Using Azure Databricks (DP-750) questions similar to the real exam. You can prepare for the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam dumps during your job. You don't need to visit the market or any store because PDF4Test Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam questions are easily accessible from the website.
NEW QUESTION # 36
You have an Azure Databricks workspace
You are creating a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically. You need to configure compute for the pipeline. The solution must minimize operational costs and effort. What should you use?
Answer: D
Explanation:
The correct answer is C - a job cluster that uses autoscaling.
Job clusters (also called pipeline clusters in the SDP context) are created exclusively for a pipeline run and terminated when the pipeline stops. You pay only for what the pipeline uses, and there's no idle cost between runs. Autoscaling on a job cluster lets the pipeline expand during heavy processing and contract during lighter stages - the combination of on-demand lifecycle and elastic scaling gives the lowest operational cost.
Option A (all-purpose cluster) runs at a higher DBU rate and persists beyond the pipeline's lifecycle, meaning you're paying for it even when the pipeline isn't running. Option B (SQL warehouse) is optimised for interactive BI and ad-hoc queries, not for the batch/streaming workloads SDP pipelines run. Option D (single- node all-purpose) has no scaling, runs at the all-purpose DBU rate, and is capped at one node - unsuitable for any production pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/configure-pipeline
NEW QUESTION # 37
Drag and Drop Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named finance, finance contains two schemas named default and procurement.
You need to create a table named assets in the procurement schema, assets must contain the following columns:
- asset_id
- asset_type
- asset_name
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.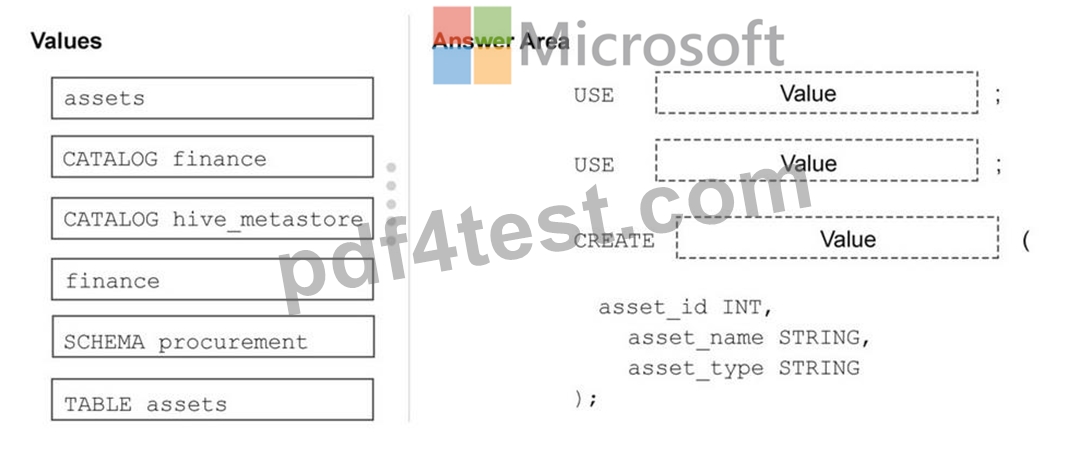
Answer:
Explanation: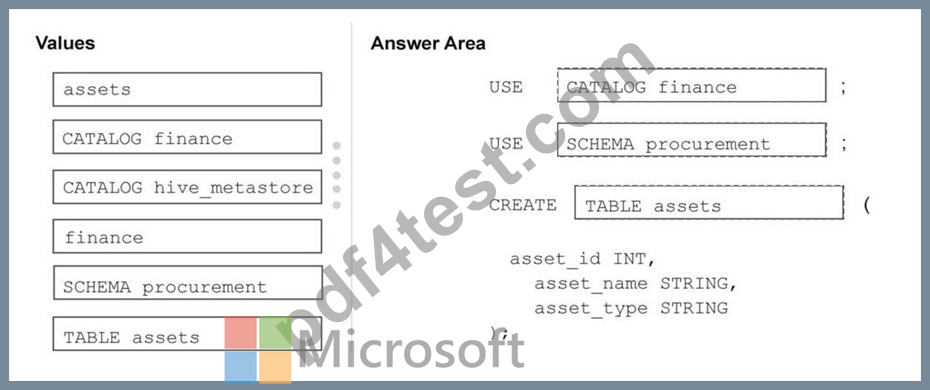
NEW QUESTION # 38
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to implement a daily batch data process that requires complex and highly customized Python transformations. The solution must minimize additional complexity.
What should you include in the solution?
Answer: B
Explanation:
A Databricks notebook provides the flexibility required to implement complex, highly customized Python and PySpark transformations. Scheduling that notebook as a Lakeflow Jobs task supplies native daily orchestration, monitoring, retries, and compute management without introducing another service. Azure Data Factory data flows are oriented toward visually designed transformations and would add external orchestration complexity for logic already implemented most naturally in Python. A continuous job is inappropriate because the workload runs once per day rather than continuously. Spark Declarative Pipelines is effective for declarative batch and streaming ETL, but it is less direct when the core requirement emphasizes highly customized procedural Python transformations. A notebook task therefore provides the necessary programming freedom while keeping scheduling and operation inside Azure Databricks.
NEW QUESTION # 39
You have an Azure Databricks workspace that is attached to a Unity Catalog metastore named metastore1.
Metastore1 contains a catalog named catalog 1.
You need to create a new schema named schema2 that meets the following requirements:
* Is contained in catalog1
* Uses abfss://containergstorageaccount.dfs.core.windows.net/data as the Managed location Which SQL statement should you execute?
Answer: C
Explanation:
The correct answer is A. The Unity Catalog DDL for creating a schema inside a specific catalog and setting a custom managed storage path uses the three-part name (catalog.schema) and the MANAGED LOCATION clause:
CREATE SCHEMA catalog1.schema2 MANAGED LOCATION ' abfss://... ' ;
The three-part name explicitly places the schema inside catalog1. MANAGED LOCATION tells Unity Catalog where to store managed tables and volumes created under this schema - any managed table without its own explicit location will inherit this path.
Option B uses CREATE CATALOG, which creates an entirely new catalog rather than a schema. Option C uses the LOCATION keyword without MANAGED - that syntax is for external locations, not for overriding the managed storage path of a schema. Option D uses WITH DBPROPERTIES, which stores arbitrary key- value metadata but has no effect on where Unity Catalog physically stores data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-ddl-create- schema
NEW QUESTION # 40
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 runs every hour.
Occasionally, Job1 takes longer than one hour to complete.
You need to configure the job scheduling behavior to meet the following requirements:
* Overlapping runs must be prevented to avoid data corruption.
* Scheduled runs must not be discarded when another run is already active.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.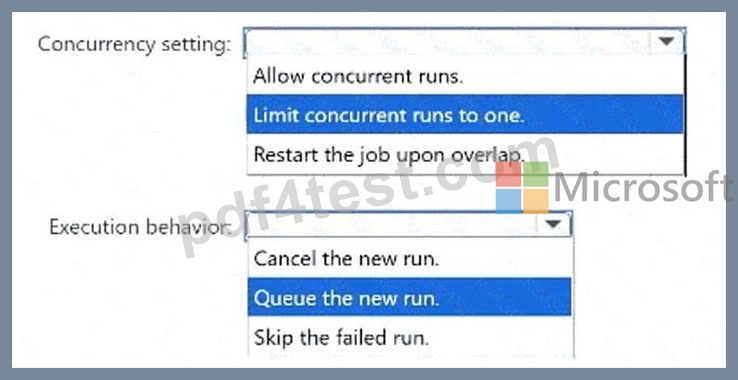
Answer:
Explanation: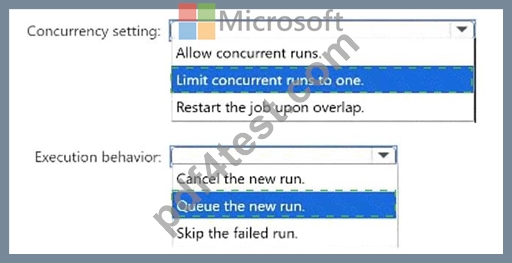
Explanation:
Concurrency setting: Limit concurrent runs to one.
Execution behavior: Queue the new run.
Limiting concurrent runs to one ensures that only one instance of Job1 can execute at a time. This prevents two hourly runs from simultaneously modifying the same tables, files, checkpoints, or downstream systems, thereby reducing the risk of duplicate processing and data corruption. When a scheduled trigger occurs while an earlier execution is still active, queueing the new run preserves that execution and starts it after the active run finishes. Allowing concurrent runs would violate the non-overlap requirement. Restarting the job during an overlap could interrupt partially completed work. Canceling the new run or skipping it would avoid simultaneous execution, but the scheduled processing interval could be lost. Single-run concurrency combined with queueing therefore serializes the executions without discarding scheduled work.
NEW QUESTION # 41
......
Our DP-750 exam questions boost 3 versions and varied functions. The 3 versions include the PDF version, PC version, APP online version. You can use the version you like and which suits you most to learn our DP-750 test practice materials. The 3 versions support different equipment and using method and boost their own merits and functions. For example, the PC version supports the computers with Window system and can stimulate the real exam. Each version of our DP-750 Study Guide provides their own benefits to help the clients learn the DP-750 exam questions efficiently.
New DP-750 Test Testking: https://www.pdf4test.com/DP-750-dump-torrent.html
DOWNLOAD the newest PDF4Test DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1xRpF3JX-atgeZM2EKHBVyzYPn6hPqoYX