BONUS!!! Download part of GuideTorrent SPS-C01 dumps for free: https://drive.google.com/open?id=1rStF-JCgDxHtXHVbD5YmwcQqbb1fx_YG
By Finishing the Snowflake Certified SnowPro Specialty - Snowpark exam, you will save your work and even change to another better door way. By and by, it is not difficult to do Snowflake SPS-C01 dumps as you would confront two or three inconveniences during the trip. By utilizing Snowflake SPS-C01 Dumps, it is especially simple to appear at your goal. We can equip you with explicit tips that could show you the fundamental method for doing battling the difficulties and draw a definite guide toward your objective for the Snowflake Certified SnowPro Specialty - Snowpark exam.
| Section | Weight | Objectives |
|---|---|---|
| Data Transformations and DataFrame Operations | 35% | - Complex data pipelines - Persisting transformed data - Filtering, Aggregating, and Joining DataFrames - Window functions - Using built-in functions |
| Snowpark API for Python | 30% | - Establishing connections and session management - User-Defined Functions (UDFs) and Stored Procedures - Working with Semi-structured data - Reading and writing data - DataFrame creation and manipulation |
| Snowpark Concepts | 15% | - Snowpark architecture and core concepts - Transformations vs. Actions - Client-side vs. Server-side execution - Snowpark DataFrames and query plans - Snowpark Sessions and connection management - Stored procedures and conditional logic |
| Performance Optimization and Best Practices | 20% | - Query pushdown and optimization - Minimizing data transfer - Warehouse sizing for Snowpark - Debugging and explain plans - Caching strategies - Vectorized UDFs |
Knowledge is a great impetus for the progress of human civilization. In the century today, we have to admit that unemployment is getting worse. Many jobs have been replaced by intelligent robots, so you have to learn practical knowledge, such as our Snowflake Certified SnowPro Specialty - Snowpark exam dumps, it can meet the needs of users. With the help of our SPS-C01 test material, users will learn the knowledge necessary to obtain the Snowflake certificate and be competitive in the job market and gain a firm foothold in the workplace. Our SPS-C01 Quiz guide’ reputation for compiling has created a sound base for our beautiful future business. We are clearly concentrated on the international high-end market, thereby committing our resources to the specific product requirements of this key market sector, as long as cater to all the users who wants to get the test Snowflake certification.
NEW QUESTION # 328
You have a Snowpark DataFrame named 'employee_df in VS Code. You want to define a user-defined function (UDF) in Python that calculates the bonus for each employee based on their salary and performance rating. The UDF should take the salary (SALARY) and performance rating (PERFORMANCE RATING) as inputs and return the bonus amount. Assume you have already established a Snowpark session. Which code snippet accurately defines and registers a UDF named 'calculate_bonus' that can be applied to the 'employee_df DataFrame?





Answer: A,B
Explanation:
Options A and B are both correct methods. Option A defines the Python function and then registers it as a UDF using session.udf.register' . It explicitly specifies the return type, input types, UDF name, and the 'replace=True' option to allow overwriting if the UDF already exists. Option B uses the guff decorator to directly register the function as a UDF, providing a more concise way to define and register UDFs. Option A is also valid as the user defined datatypes and name. Option C requires the snowflake-snowpark-python package (which is already installed via dependencies) and the 'fune argument is redundant. Option D is wrong as would remove the currently configured packages. Option E is incorrect because making the UDF permanent requires additional privileges and setup that aren't covered by default.
NEW QUESTION # 329
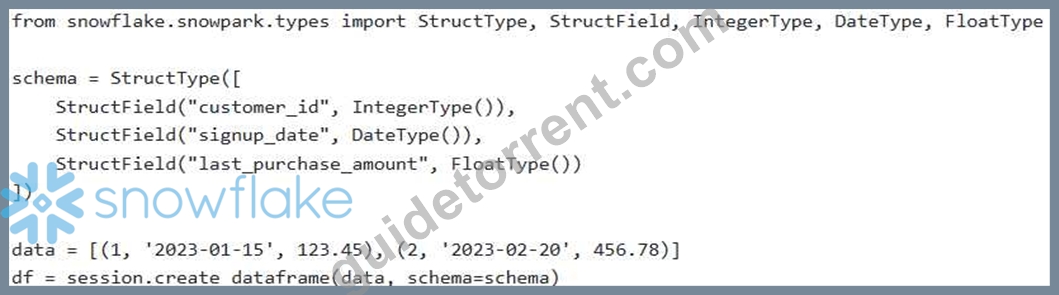
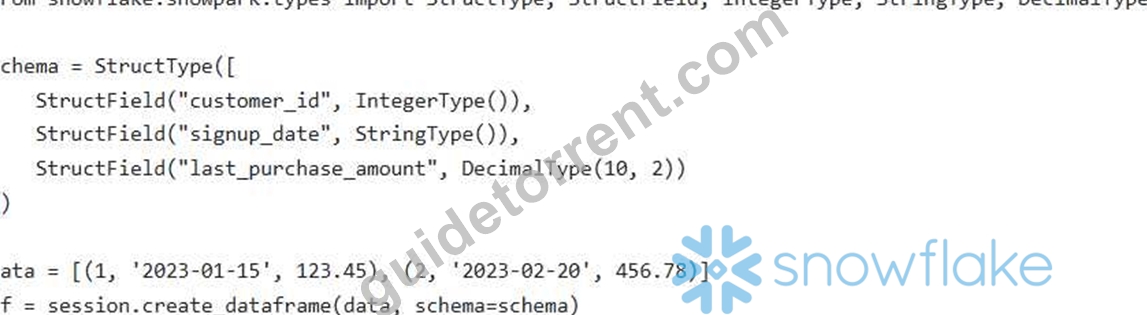
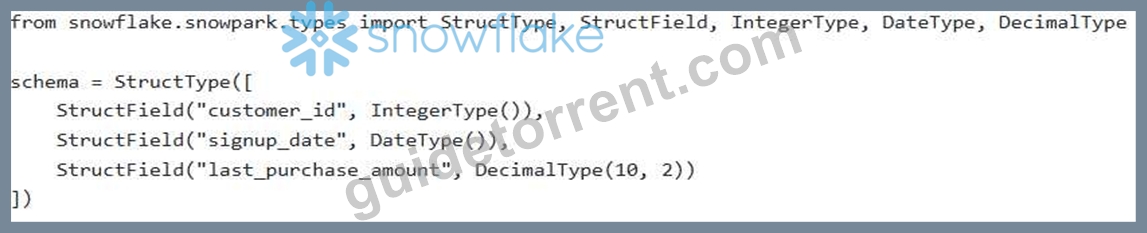
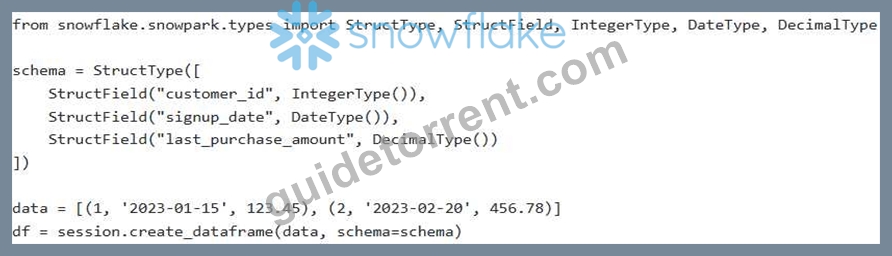
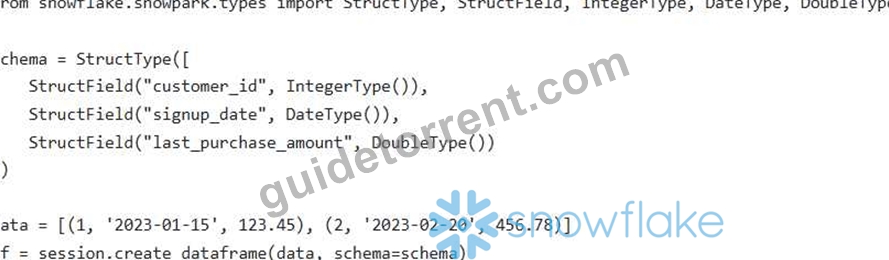
You are tasked with creating a Snowpark DataFrame from a Python list of tuples. Each tuple represents a customer record with the following structure: '(customer_id, signup_date, The 'customer _ id' should be an integer, 'signup_date' should be a date, and should be a decimal. You want to define the schema explicitly for type safety and performance. Which of the following code snippets correctly defines the schema and creates the Snowpark DataFrame?
Answer: C
Explanation:
Option A correctly defines the schema using 'StructType', 'StructField', 'Integer Type', 'DateType' , and 'DecimalType' . It also specifies the precision and scale for the 'DecimalType' which is important for accurately representing monetary values. The date values in the data are also compatible with DateType. The other options use incorrect data types for the last_purchase_amount (FloatType, DoubleType, StringType) or don't specify precision and scale for the DecimalType. Note that Snowflake DateType only accepts values formatted as YYYY-MM-DD'.
NEW QUESTION # 330
You are tasked with building a Snowpark application that processes sensor data. The data arrives continuously and is ingested into a Snowflake table called 'RAW SENSOR DATA'. You need to create a Snowpark DataFrame that applies a user-defined function (UDF) to each row to enrich the data. The UDF, named 'ENRICH SENSOR DATA, is written in Python and resides in a stage called 'UDF STAGE. The UDF takes three arguments: 'timestamp', and 'raw_value', all of which are STRING type in Snowflake. Which of the following code snippets correctly defines and calls the UDF using Snowpark?





Answer: B
Explanation:
Option E is correct because it uses 'call_udf function which correctly calls pre existing UDF function defined in Snowflake database. Option A & D are syntactically incorrect since return_type and input_types are required by @udf decorator. Option B attempts to define a UDTF (User-Defined Table Function) which is not what's requested in the question, and the 'select' function is not used correctly in this context. Option C defines the UDF inline, which is a valid approach, but it's less efficient than calling an existing one, and it misses the point that the UDF already exists.
NEW QUESTION # 331
You're using Snowpark in Python and need to execute a complex SQL query. The query involves several joins and aggregations, and you want to optimize its performance. You are using "session.sql(query)' to execute the query. Which of the following strategies, applied before executing 'session.sql(query)' , would likely lead to the most significant performance improvement for a very large dataset?
Answer: B
Explanation:
Option A provides the most significant improvement because Snowpark DataFrame operations allow Snowflake's query optimizer to leverage pushdown optimizations. When you express your logic as DataFrame operations, Snowpark translates these into SQL that is specifically tailored for Snowflake's engine. This gives Snowflake more control over the execution plan compared to simply passing in a pre-written SQL query via 'session.sql(queryy. DataFrame operations allow the query optimizer to push down operations such as filters and aggregations to the data source, significantly reducing the amount of data transferred and processed. Option B is incorrect because comments only improve readability, not performance. Option C, , can help if the DataFrame is used multiple times, but it doesn't address the initial optimization of the query itself. Option D could help, but converting to DataFrame operations provides more comprehensive optimization. Option E can assist, but often DataFrame creation and optimal query plan generation can be better using Option A.
NEW QUESTION # 332
A Snowpark application processes streaming data from Kafka, performing complex windowing aggregations. The application is configured with auto-scaling enabled for the virtual warehouse. During peak hours, the application exhibits high latency despite the warehouse scaling up. Upon investigation, you observe sustained high CPU utilization on the single active warehouse. Which actions, alone or in combination, would MOST effectively improve performance while minimizing cost?
Answer: A,E
Explanation:
Optimizing the Snowpark code (Option B) reduces the overall CPU load, while repartitioning the data (Option C) distributes the work more evenly across multiple clusters, reducing hotspots and enabling parallel processing. Increasing MAX_CLUSTER_COUNT (Option A) only helps if the workload is already evenly distributed. Increasing MIN_CLUSTER COUNT (Option D) may add to cost without addressing the underlying code issues or data skew. Decreasing SCALING_POLICY (Option E) may help with responsiveness but isn't a fundamental solution.
NEW QUESTION # 333
......
Nowadays passing the SPS-C01 test certification is extremely significant for you and can bring a lot of benefits to you. Passing the SPS-C01 test certification does not only prove that you are competent in some area but also can help you enter in the big company and double your wage. And our SPS-C01 Exam Questions are in good quality. As long as you study with our SPS-C01 learning guide, you will find that the content is easily to understand and the displays are enjoyable.
SPS-C01 Accurate Test: https://www.guidetorrent.com/SPS-C01-pdf-free-download.html
2026 Latest GuideTorrent SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1rStF-JCgDxHtXHVbD5YmwcQqbb1fx_YG