2026 Latest TrainingDumps MLA-C01 PDF Dumps and MLA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1DcG2SailPGcHlDVFx4pL0oqF5H0wqls6
You can download a free demo of Amazon - MLA-C01 exam study material at TrainingDumps The free demo of MLA-C01 exam product will eliminate doubts about our AWS Certified Machine Learning Engineer - Associate PDF and practice exams. You should avail this opportunity of MLA-C01 exam dumps free demo. It will help you pay money without any doubt in mind. We ensure that our AWS Certified Machine Learning Engineer - Associate exam questions will meet your AWS Certified Machine Learning Engineer - Associate test preparation needs. If you remain unsuccessful in the MLA-C01 test after using our MLA-C01 product, you can ask for a full refund. TrainingDumps will refund you as per the terms and conditions.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> New MLA-C01 Learning Materials <<
Due to busy routines, applicants of the AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam need real AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam questions. When they don't study with updated Amazon MLA-C01 practice test questions, they fail and lose money. If you want to save your resources, choose updated and actual AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam questions of TrainingDumps.
NEW QUESTION # 133
A government agency is conducting a national census to assess program needs by area and city. The census form collects approximately 500 responses from each citizen. The agency needs to analyze the data to extract meaningful insights. The agency wants to reduce the dimensions of the high-dimensional data to uncover hidden patterns.
Which solution will meet these requirements?
Answer: B
Explanation:
The primary requirement is dimensionality reduction on high-dimensional structured data to uncover hidden patterns. Principal Component Analysis (PCA) is a linear dimensionality reduction technique specifically designed for this purpose and is available as a built-in algorithm in Amazon SageMaker.
PCA transforms the original features into a smaller set of orthogonal components that preserve the maximum possible variance. This makes PCA ideal for large tabular datasets such as census data, where hundreds of correlated variables are common.
t-SNE (Option B) is mainly used for visualization in very low dimensions (2D or 3D) and does not scale well for large datasets or production analysis. k-means (Option C) is a clustering algorithm, not a dimensionality reduction method. Random Cut Forest (Option D) is used for anomaly detection.
Therefore, PCA is the correct and AWS-recommended solution.
NEW QUESTION # 134
A company has deployed a model to predict the churn rate for its games by using Amazon SageMaker Studio.
After the model is deployed, the company must monitor the model performance for data drift and inspect the report. Select and order the correct steps from the following list to model monitor actions. Select each step one time. (Select and order THREE.) .
Check the analysis results on the SageMaker Studio console. .
Create a Shapley Additive Explanations (SHAP) baseline for the model by using Amazon SageMaker Clarify.
Schedule an hourly model explainability monitor.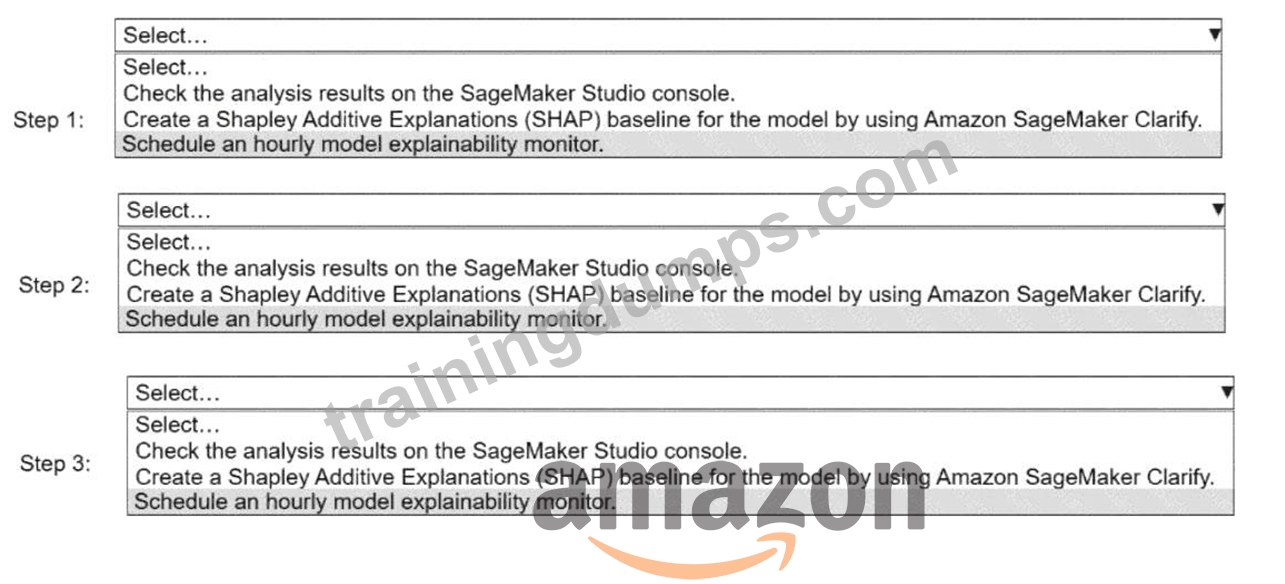
Answer:
Explanation: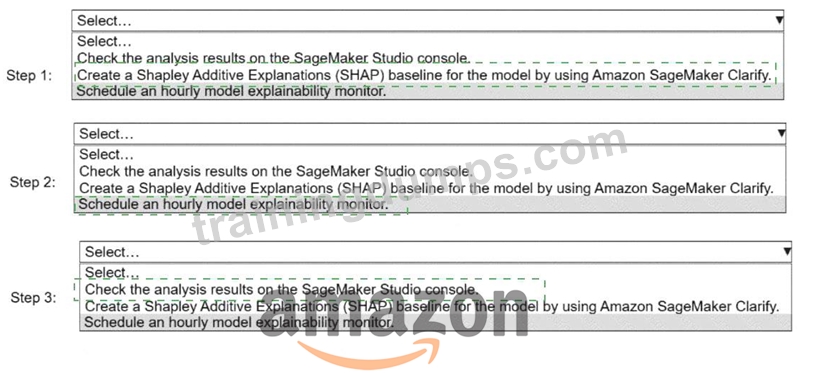
Explanation:
Step 1:
Create a Shapley Additive Explanations (SHAP) baseline for the model by using Amazon SageMaker Clarify.
Step 2:
Schedule an hourly model explainability monitor.
Step 3:
Check the analysis results on the SageMaker Studio console.
When monitoring a deployed model for data drift and explainability, AWS prescribes a specific workflow using SageMaker Clarify and SageMaker Model Monitor:
Create a SHAP baseline (Step 1)Before any monitoring can occur, SageMaker Clarify must establish a baseline explainability configuration. This baseline captures the reference SHAP values for feature importance using training or baseline data. Model Monitor uses this baseline to compare future inferences and detect drift in feature attributions.
Schedule the model explainability monitor (Step 2)After the baseline is created, an explainability monitoring schedule must be configured (hourly in this case). The monitor periodically analyzes inference data, compares it against the SHAP baseline, and generates reports that highlight drift or anomalies in feature contributions.
Inspect results in SageMaker Studio (Step 3)Once monitoring jobs run, SageMaker stores the analysis results in Amazon S3 and surfaces them in the SageMaker Studio console, where engineers can review metrics, violations, and visual reports.
This sequence is mandatory because:
A monitor cannot run without a baseline
Results cannot be reviewed until the monitor executes
NEW QUESTION # 135
A company wants to share data with a vendor in real time to improve the performance of the vendor's ML models. The vendor needs to ingest the data in a stream. The vendor will use only some of the columns from the streamed data.
Which solution will meet these requirements?
Answer: A
Explanation:
The requirement specifies real-time streaming ingestion and column-level transformation before sharing data with a vendor. Amazon Kinesis Data Streams is designed for low-latency, real-time data ingestion and delivery.
To extract only required columns from the stream, AWS recommends using Amazon Managed Service for Apache Flink as a stream consumer. Flink enables real-time transformations such as filtering, projection, and enrichment on streaming data before delivering it downstream.
Option A and D are batch-oriented and not suitable for real-time streaming. Option C is incorrect because S3 bucket policies cannot enforce column-level access controls.
Therefore, Kinesis Data Streams combined with Apache Flink meets all requirements.
NEW QUESTION # 136
A company wants to use large language models (LLMs) that are supported by Amazon Bedrock to develop a chat interface for the company ' s internal technical documentation. The company stores the documentation as dozens of text files that are several megabytes in total size. The company updates the text files often.
Which solution will meet these requirements MOST cost-effectively?
Answer: B
Explanation:
Option D is correct because Amazon Bedrock Knowledge Bases are designed for applications that need to answer questions using private documents without retraining or repeatedly fine-tuning a foundation model.
AWS documentation states that with Amazon Bedrock Knowledge Bases, you can build applications enriched by context retrieved from a knowledge base, and that this provides an out-of-the-box RAG solution. AWS also explicitly says that adding a knowledge base increases cost-effectiveness by removing the need to continually train your model to use your private data. That matches this use case very closely.
The question also says the documentation consists of text files that are only several megabytes total and are updated often. A retrieval-based approach is more economical and operationally simpler than creating a new model or repeatedly fine-tuning one whenever the documents change. AWS documentation for Bedrock knowledge bases describes adding data sources and running ingestion jobs to process and index the content, which is exactly the pattern needed for frequently updated internal documentation used by a chat interface.
The other options are not as cost-effective. Creating a new LLM is far beyond the need here. Guardrails help control model behavior and policy enforcement, but they do not serve as a document retrieval layer for internal documentation. Fine-tuning a model on frequently changing text files is usually more expensive and less flexible than using retrieval augmentation. For a modest-sized, frequently updated documentation corpus, the AWS-native and most cost-effective solution is to load the files into an Amazon Bedrock knowledge base and use it to provide context at inference time. Therefore, the best verified answer is D.
NEW QUESTION # 137
Case Study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
Which AWS service or feature can aggregate the data from the various data sources?
Answer: A
NEW QUESTION # 138
......
With over a decade's business experience, our MLA-C01 test torrent attached great importance to customers' purchasing experience. There is no need to worry about the speed on buying electronic products. For we make endless efforts to assess and evaluate our MLA-C01 exam prep' reliability for a long time and put forward a guaranteed purchasing scheme. If neccessary, you can also have our remotely online guidance to use our MLA-C01 Test Torrent. Normally, you can get our MLA-C01 practice questions in a few minutes after purchase with high efficiency!
MLA-C01 Valid Exam Guide: https://www.trainingdumps.com/MLA-C01_exam-valid-dumps.html
BTW, DOWNLOAD part of TrainingDumps MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1DcG2SailPGcHlDVFx4pL0oqF5H0wqls6