Exams-boost is a wonderful study platform that contains our hearty wish for you to pass the exam by our DP-750 exam materials. So our responsible behaviors are our instinct aim and tenet. By devoting in this area so many years, we are omnipotent to solve the problems about the DP-750 learning questions with stalwart confidence. we can claim that only studing our DP-750 study guide for 20 to 30 hours, then you will pass the exam for sure.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Topic 2: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Topic 3: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Topic 4: Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
>> DP-750 Latest Exam Materials <<
As you can find on our website, we have three versions of our DP-750 learning questions: the PDF, Software and APP online. The online test engine and window software need to run on computers. The PDF version of the DP-750 training engine is easy to make notes. In short, all of the three packages are filled with useful knowledge. You can try our free trails before making final decisions since we also have demos of our DP-750 Exam Materials for you to free download before your payment.
NEW QUESTION # 73
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a Databricks access connector.
Does this meet the goal?
Answer: A
Explanation:
The correct answer is B - No.
A Databricks Access Connector is an Azure resource that provides a managed identity for Databricks to authenticate to Azure Storage services. It is an authentication bridge - nothing more. Creating one doesn't register any external database, doesn't create any Unity Catalog objects representing DB1, and doesn't enable querying of SQL Server data from Databricks.
An Access Connector is a prerequisite for setting up storage credentials and external locations in Unity Catalog (to access ADLS Gen2, for example), but it has no role in Lakehouse Federation or foreign catalog creation. It cannot expose an external database's schemas and tables in Unity Catalog alongside native objects.
The correct solution for this scenario is a foreign catalog (Q47), which requires a connection object pointing to DB1 - not an Access Connector.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/storage-credentials
NEW QUESTION # 74
You have an Azure Databricks workspace named Workspace! that uses a Git repository. The repository contains a Databricks notebook named Notebook1.
From the main branch, you create a feature branch named Branch! and commit changes to Notebooks Another user commits changes to Notebook1 in main.
When you attempt to merge Branch! into main, the merge fails due to conflicts.
You need to merge Branch! into the main branch. The solution must ensure that Notebook1 includes all the changes from both the branches.
What should you do?
Answer: D
Explanation:
The correct answer is D - apply the main branch changes to Branch1 and resolve the conflicts.
When a merge fails due to conflicts, the right workflow is to bring main's changes into the feature branch, resolve conflicts there, and then merge the clean feature branch into main. This is the standard Git conflict resolution pattern - resolve in the feature branch, not in main - because it protects the main branch from partial or broken states during resolution.
Option A (clone Branch1 as a new repository) creates a disconnected copy; it doesn't resolve the conflict and breaks the relationship with the remote. Option B (apply changes directly to main) bypasses the feature branch entirely and risks overwriting the other developer's work. Option C (clone main as a new repository) again creates a disconnected copy - none of Branch1's changes would be incorporated, and history would be lost.
Reference: https://learn.microsoft.com/en-us/azure/databricks/repos/git-operations-with-repos
NEW QUESTION # 75
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
db1.sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the db1.sales_orders table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.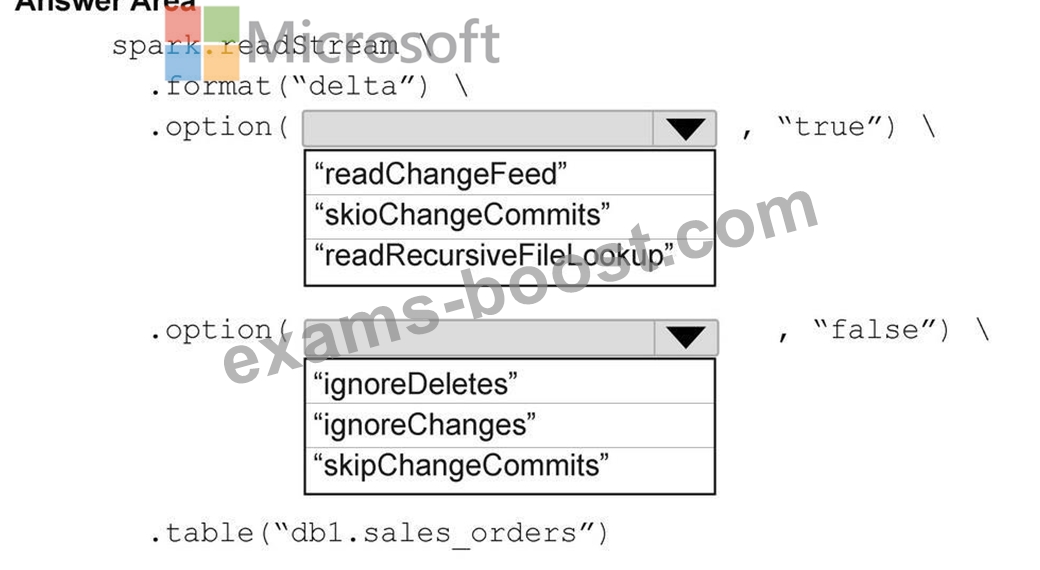
Answer:
Explanation: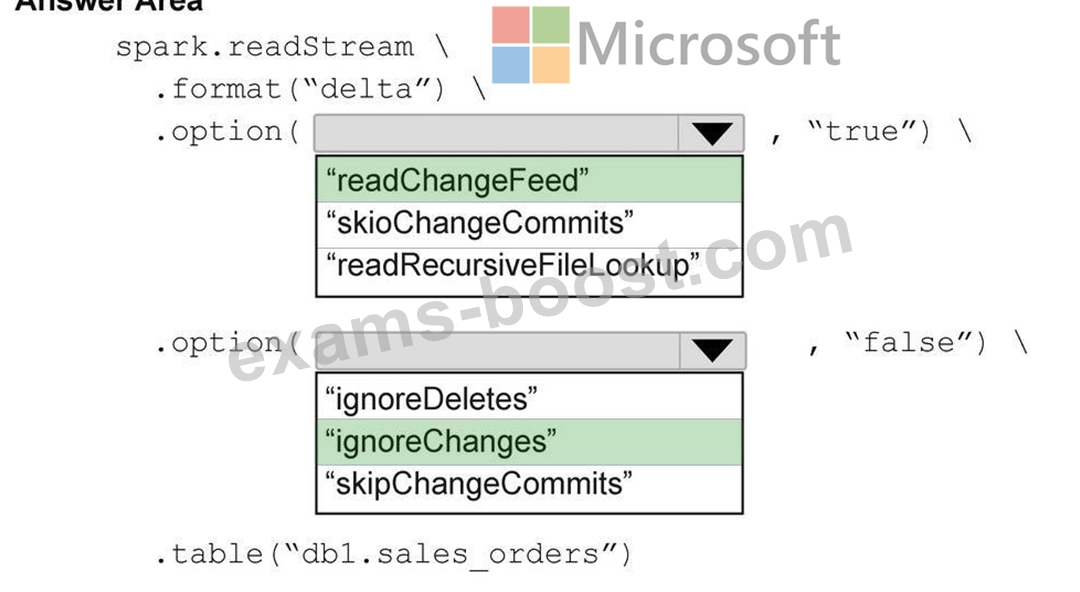
NEW QUESTION # 76
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to share curated data with an external organization. The solution must meet the following requirements:
* The organization will use its own compute platform to query the data.
* Access to the data must be centrally governed by using Unity Catalog.
* Administrative effort must be minimized.
What should you do?
Answer: A
Explanation:
Delta Sharing is designed to share governed data securely with recipients outside an Azure Databricks workspace. The external organization can query the shared data from its own compatible compute platform without receiving workspace access or requiring a Databricks SQL warehouse. Unity Catalog centrally controls which tables, views, or other objects are included in the share and which recipients can access them.
Moving files to an SFTP server creates additional copies and requires custom transfer and security administration. Lakeflow Connect is intended for ingesting data into Databricks rather than sharing curated data externally. Granting workspace access or creating a SQL warehouse would require the recipient to use Databricks-managed resources. Delta Sharing therefore provides the required open access model, centralized governance, and minimal administrative effort.
NEW QUESTION # 77
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Answer: C
Explanation:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don ' t prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely. Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
NEW QUESTION # 78
......
As we all know, the influence of DP-750 exam guides even have been extended to all professions and trades in recent years. Passing the DP-750 exam is not only for obtaining a paper certification, but also for a proof of your ability. Most people regard Microsoft certification as a threshold in this industry, therefore, for your convenience, we are fully equipped with a professional team with specialized experts to study and design the most applicable DP-750 exam prepare. We have organized a team to research and study question patterns pointing towards various learners. Our company keeps pace with contemporary talent development and makes every learners fit in the needs of the society. Based on advanced technological capabilities, our DP-750 Study Materials are beneficial for the masses of customers. Our experts have plenty of experience in meeting the requirement of our customers and try to deliver satisfied DP-750 exam guides to them. Our DP-750 exam prepare is definitely better choice to help you go through the test.
DP-750 Latest Learning Materials: https://www.exams-boost.com/DP-750-valid-materials.html