BTW, DOWNLOAD part of DumpStillValid Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1Zn6_qYUD38lz08if0gVbp1c6UiXaa-G6
In case the clients encounter the tricky issues we will ask our professional to provide the long-distance assistance on Databricks-Generative-AI-Engineer-Associate exam questions. Please take it easy and don't worry that our customer service staff will be offline because our customer service staff works for the whole day and the whole year. And the clients can enjoy our considerate and pleasant service and like our Databricks-Generative-AI-Engineer-Associate Study Materials. Then the expert team processes them elaborately and compiles them into the test bank. Our system will timely and periodically send the latest update of the Databricks-Generative-AI-Engineer-Associate exam practice guide to our clients.
| Section | Objectives |
|---|---|
| Topic 1: Foundations of Generative AI | - Large Language Models (LLMs)
|
| Topic 2: Retrieval-Augmented Generation (RAG) | - RAG architecture
|
| Topic 3: Databricks Mosaic AI Platform | - Model development and serving
|
| Topic 4: Prompt Engineering | - Prompt design techniques
|
| Topic 5: Responsible AI and Governance | - AI safety and ethics
|
>> Valid Databricks-Generative-AI-Engineer-Associate Test Discount <<
Each user's situation is different. Databricks-Generative-AI-Engineer-Associate simulating exam will develop the most suitable learning plan for each user. We will contact the user to ensure that they fully understand the user's situation, including their own level, available learning time on Databricks-Generative-AI-Engineer-Associate Training Questions. Our experts will fully consider the gradual progress of knowledge and create the most effective learning plan on the Databricks-Generative-AI-Engineer-Associate exam questions for you.
NEW QUESTION # 35
A Generative Al Engineer has created a RAG application to look up answers to questions about a series of fantasy novels that are being asked on the author's web forum. The fantasy novel texts are chunked and embedded into a vector store with metadata (page number, chapter number, book title), retrieved with the user' s query, and provided to an LLM for response generation. The Generative AI Engineer used their intuition to pick the chunking strategy and associated configurations but now wants to more methodically choose the best values.
Which TWO strategies should the Generative AI Engineer take to optimize their chunking strategy and parameters? (Choose two.)
Answer: C,E
Explanation:
To optimize a chunking strategy for a Retrieval-Augmented Generation (RAG) application, the Generative AI Engineer needs a structured approach to evaluating the chunking strategy, ensuring that the chosen configuration retrieves the most relevant information and leads to accurate and coherent LLM responses.
Here's whyCandEare the correct strategies:
Strategy C: Evaluation Metrics (Recall, NDCG)
* Define an evaluation metric: Common evaluation metrics such as recall, precision, or NDCG (Normalized Discounted Cumulative Gain) measure how well the retrieved chunks match the user's query and the expected response.
* Recallmeasures the proportion of relevant information retrieved.
* NDCGis often used when you want to account for both the relevance of retrieved chunks and the ranking or order in which they are retrieved.
* Experiment with chunking strategies: Adjusting chunking strategies based on text structure (e.g., splitting by paragraph, chapter, or a fixed number of tokens) allows the engineer to experiment with various ways of slicing the text. Some chunks may better align with the user's query than others.
* Evaluate performance: By using recall or NDCG, the engineer can methodically test various chunking strategies to identify which one yields the highest performance. This ensures that the chunking method provides the most relevant information when embedding and retrieving data from the vector store.
Strategy E: LLM-as-a-Judge Metric
* Use the LLM as an evaluator: After retrieving chunks, the LLM can be used to evaluate the quality of answers based on the chunks provided. This could be framed as a "judge" function, where the LLM compares how well a given chunk answers previous user queries.
* Optimize based on the LLM's judgment: By having the LLM assess previous answers and rate their relevance and accuracy, the engineer can collect feedback on how well different chunking configurations perform in real-world scenarios.
* This metric could be a qualitative judgment on how closely the retrieved information matches the user's intent.
* Tune chunking parameters: Based on the LLM's judgment, the engineer can adjust the chunk size or structure to better align with the LLM's responses, optimizing retrieval for future queries.
By combining these two approaches, the engineer ensures that the chunking strategy is systematically evaluated using both quantitative (recall/NDCG) and qualitative (LLM judgment) methods. This balanced optimization process results in improved retrieval relevance and, consequently, better response generation by the LLM.
NEW QUESTION # 36
A Generative AI Engineer I using the code below to test setting up a vector store: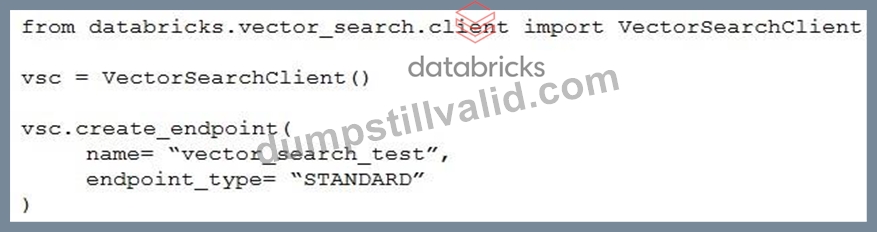
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: A
Explanation:
* Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
* Explanation of Options:
Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, hence Option B.
NEW QUESTION # 37
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: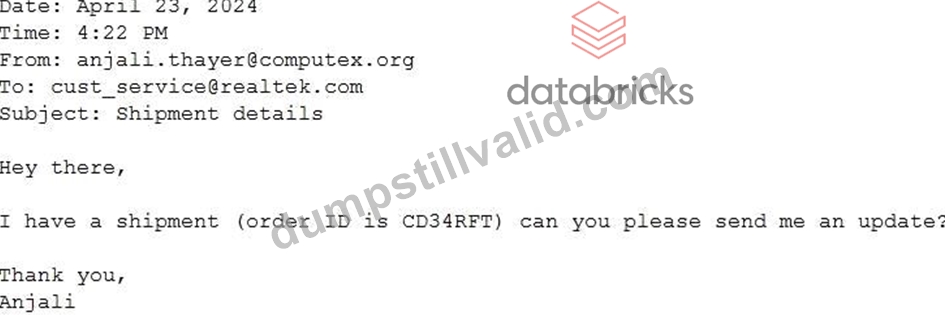
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Answer: C
Explanation:
Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM' s responses.
Explanation of Options:
* Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
* Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
* Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
* Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore,Option Bis optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
NEW QUESTION # 38
A Generative AI Engineer is experimenting with using parameters to configure an agent in Mosaic Agent Framework. However, they are struggling to get the agent to respond with relevant information with this configuration:
config = { " prompt_template " : " You are a trivia bot. Generate a question based on the user ' s input:
{user_input} " , " input_vars " : [ " user_input " ], " parameters " : { " temperature " : 0.01, " max_tokens " :
500}}
Which error is causing the problem?
Answer: D
Explanation:
In the Mosaic AI Agent Framework and underlying LangChain-based configurations, the " input_vars " or " input_variables " must be correctly mapped and referenced within the template. If the configuration dictionary identifies user_input as the variable but the logic executing the chain does not correctly " inject " the runtime value into the {user_input} placeholder, the LLM will receive a literal string (or an empty value) rather than the user ' s actual question. This results in the model failing to provide relevant information because it essentially doesn ' t know what the user asked. Engineering standards require ensuring that the key used in the input_vars list matches the key in the JSON payload sent to the model serving endpoint. If there is a mismatch or a failure to parse, the prompt remains static, leading to generic or irrelevant responses.
NEW QUESTION # 39
A company has a typical RAG-enabled, customer-facing chatbot on its website.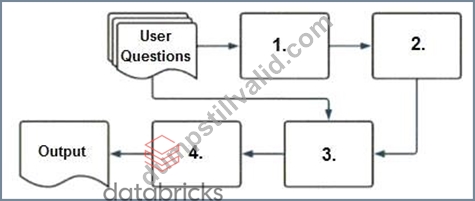
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: C
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1):The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2):The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3):The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4):Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
* B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence isembedding model, vector search, context-augmented prompt, response- generating LLM, which is option A.
NEW QUESTION # 40
......
With Databricks-Generative-AI-Engineer-Associate test answers, you are not like the students who use other materials. As long as the syllabus has changed, they need to repurchase new learning materials. This not only wastes a lot of money, but also wastes a lot of time. Our industry experts are constantly adding new content to Databricks-Generative-AI-Engineer-Associate test dumps based on constantly changing syllabus and industry development breakthroughs. All the language used in Databricks-Generative-AI-Engineer-Associate Study Materials is very simple and easy to understand. With Databricks-Generative-AI-Engineer-Associate test answers, you don't have to worry about that you don't understand the content of professional books. You also don't need to spend expensive tuition to go to tutoring class. Databricks-Generative-AI-Engineer-Associate test dumps can help you solve all the problems in your study.
Practice Databricks-Generative-AI-Engineer-Associate Test Engine: https://www.dumpstillvalid.com/Databricks-Generative-AI-Engineer-Associate-prep4sure-review.html
DOWNLOAD the newest DumpStillValid Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1Zn6_qYUD38lz08if0gVbp1c6UiXaa-G6