P.S. Free 2026 Google Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by ActualCollection: https://drive.google.com/open?id=1HDzbCTXQRBGo3C9onW1cGhq7oZzmUAkh
It is known that our Professional-Machine-Learning-Engineer valid study guide materials have dominated the leading position in the global market with the decades of painstaking efforts of our experts and professors. There are many special functions about Professional-Machine-Learning-Engineer study materials to help a lot of people to reduce the heavy burdens when they are preparing for the Professional-Machine-Learning-Engineer Exams for the Professional-Machine-Learning-Engineer study practice question from our company can help all customers to make full use of their sporadic time. Hust buy our Professional-Machine-Learning-Engineer exam questions, you will be able to pass the Professional-Machine-Learning-Engineer exam easily.
| Section | Objectives |
|---|---|
| Data preparation and processing | - Data ingestion and pipelines
|
| Deployment and operations | - Model deployment
|
| Designing ML solutions | - ML architecture design
|
| ML model development | - Model training and tuning
|
| ML pipeline automation and orchestration | - Pipeline design
|
>> Latest Professional-Machine-Learning-Engineer Dumps <<
First of all, we have the best and most first-class operating system, in addition, we also solemnly assure users that users can receive the information from the Professional-Machine-Learning-Engineer certification guide within 5-10 minutes after their payment. Second, once we have written the latest version of the Professional-Machine-Learning-Engineer certification guide, our products will send them the latest version of the Professional-Machine-Learning-Engineer Test Practice question free of charge for one year after the user buys the Professional-Machine-Learning-Engineer exam questions. Last but not least, our perfect customer service staff will provide users with the satisfaction in the hours.
NEW QUESTION # 289
You are training an object detection machine learning model on a dataset that consists of three million X-ray images, each roughly 2 GB in size. You are using Vertex AI Training to run a custom training application on a Compute Engine instance with 32-cores, 128 GB of RAM, and 1 NVIDIA P100 GPU. You notice that model training is taking a very long time. You want to decrease training time without sacrificing model performance.
What should you do?
Answer: C
NEW QUESTION # 290
You are designing an architecture with a serveress ML system to enrich customer support tickets with informative metadata before they are routed to a support agent. You need a set of models to predict ticket priority, predict ticket resolution time, and perform sentiment analysis to help agents make strategic decisions when they process support requests. Tickets are not expected to have any domain-specific terms or jargon.
The proposed architecture has the following flow: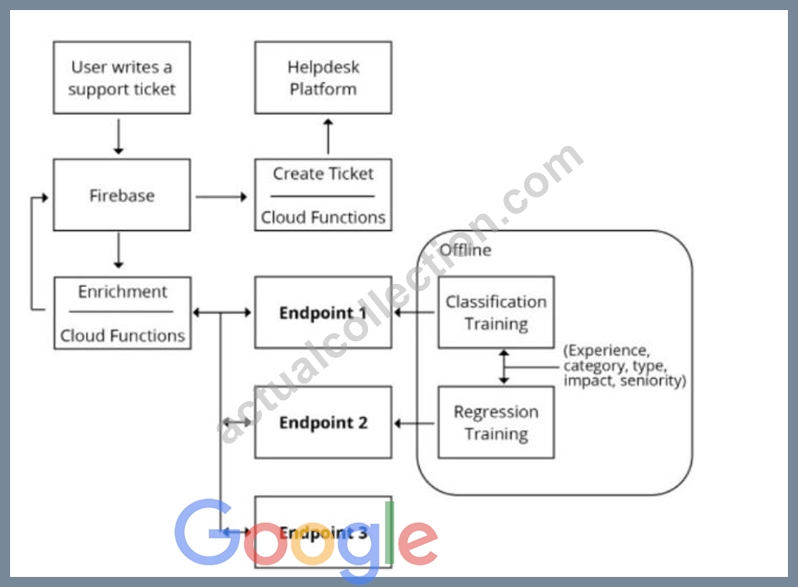
Which endpoints should the Enrichment Cloud Functions call?
Answer: B
Explanation:
https://cloud.google.com/architecture/architecture-of-a-serverless-ml-model#architecture The architecture has the following flow:
A user writes a ticket to Firebase, which triggers a Cloud Function.
-The Cloud Function calls 3 different endpoints to enrich the ticket:
-An AI Platform endpoint, where the function can predict the priority.
-An AI Platform endpoint, where the function can predict the resolution time.
-The Natural Language API to do sentiment analysis and word salience.
-For each reply, the Cloud Function updates the Firebase real-time database.
-The Cloud Function then creates a ticket into the helpdesk platform using the RESTful API.
NEW QUESTION # 291
You are building a TensorFlow model for a financial institution that predicts the impact of consumer spending on inflation globally. Due to the size and nature of the data, your model is long-running across all types of hardware, and you have built frequent checkpointing into the training process. Your organization has asked you to minimize cost. What hardware should you choose?
Answer: A
Explanation:
The best hardware to choose for your model while minimizing cost is a Vertex AI Workbench user-managed notebooks instance running on an n1-standard-16 with a preemptible v3-8 TPU. This hardware configuration can provide you with high performance, scalability, and efficiency for your TensorFlow model, as well as low cost and flexibility for your long-running and checkpointing process. The v3-8 TPU is a cloud tensor processing unit (TPU) device, which is a custom ASIC chip designed by Google to accelerate ML workloads.
It can handle large and complex models and datasets, and offer fast and stable training and inference. The n1-standard-16 is a general-purpose VM that can support the CPU and memory requirements of your model, as well as the data preprocessing and postprocessing tasks. By choosing a preemptible v3-8 TPU, you can take advantage of the lower price and availability of the TPU devices, as long as you can tolerate the possibility of the device being reclaimed by Google at any time. However, since you have built frequent checkpointing into your training process, you can resume your model from the last saved state, and avoid losing any progress or data. Moreover, you can use the Vertex AI Workbench user-managed notebooks to create and manage your notebooks instances, and leverage the integration with Vertex AI and other Google Cloud services.
The other options are not optimal for the following reasons:
* A. A Vertex AI Workbench user-managed notebooks instance running on an n1-standard-16 with 4 NVIDIA P100 GPUs is not a good option, as it has higher cost and lower performance than the v3-8 TPU. The NVIDIA P100 GPUs are the previous generation of GPUs from NVIDIA, which have lower performance, scalability, and efficiency than the latest NVIDIA A100 GPUs or the TPUs. They also have higher price and lower availability than the preemptible TPUs, which can increase the cost and complexity of your solution.
* B. A Vertex AI Workbench user-managed notebooks instance running on an n1-standard-16 with an NVIDIA P100 GPU is not a good option, as it has higher cost and lower performance than the v3-8 TPU. It also has less GPU memory and compute power than the option with 4 NVIDIA P100 GPUs, which can limit the size and complexity of your model, and affect the training and inference speed and quality.
* C. A Vertex AI Workbench user-managed notebooks instance running on an n1-standard-16 with a
* non-preemptible v3-8 TPU is not a good option, as it has higher cost and lower flexibility than the preemptible v3-8 TPU. The non-preemptible v3-8 TPU has the same performance, scalability, and efficiency as the preemptible v3-8 TPU, but it has higher price and lower availability, as it is reserved for your exclusive use. Moreover, since your model is long-running and checkpointing, you do not need the guarantee of the device not being reclaimed by Google, and you can benefit from the lower cost and higher availability of the preemptible v3-8 TPU.
References:
* Professional ML Engineer Exam Guide
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
* Google Cloud launches machine learning engineer certification
* Cloud TPU
* Vertex AI Workbench user-managed notebooks
* Preemptible VMs
* NVIDIA Tesla P100 GPU
NEW QUESTION # 292
You are a data scientist at an industrial equipment manufacturing company. You are developing a regression model to estimate the power consumption in the company's manufacturing plants based on sensor data collected from all of the plants. The sensors collect tens of millions of records every day. You need to schedule daily training runs for your model that use all the data collected up to the current date. You want your model to scale smoothly and require minimal development work. What should you do?
Answer: A
Explanation:
BigQuery ML is a powerful tool that allows you to build and deploy machine learning models directly within BigQuery, Google's fully-managed, serverless data warehouse. It allows you to create regression models using SQL, which is a familiar and easy-to-use language for many data scientists. It also allows you to scale smoothly and require minimal development work since you don't have to worry about cluster management and it's fully-managed by Google.
BigQuery ML also allows you to run your training on the same data where it's stored, this will minimize data movement, and thus minimize cost and time.
Reference:
BigQuery ML
BigQuery ML for regression
BigQuery ML for scalability
NEW QUESTION # 293
You are developing ML models with Al Platform for image segmentation on CT scans. You frequently update your model architectures based on the newest available research papers, and have to rerun training on the same dataset to benchmark their performance. You want to minimize computation costs and manual intervention while having version control for your code. What should you do?
Answer: C
Explanation:
Developing ML models with AI Platform for image segmentation on CT scans requires a lot of computation and experimentation, as image segmentation is a complex and challenging task that involves assigning a label to each pixel in an image. Image segmentation can be used for various medical applications, such as tumor detection, organ segmentation, or lesion localization1 To minimize the computation costs and manual intervention while having version control for the code, one should use Cloud Build linked with Cloud Source Repositories to trigger retraining when new code is pushed to the repository. Cloud Build is a service that executes your builds on Google Cloud Platform infrastructure. Cloud Build can import source code from Cloud Source Repositories, Cloud Storage, GitHub, or Bitbucket, execute a build to your specifications, and produce artifacts such as Docker containers or Java archives2 Cloud Build allows you to set up automated triggers that start a build when changes are pushed to a source code repository. You can configure triggers to filter the changes based on the branch, tag, or file path3 Cloud Source Repositories is a service that provides fully managed private Git repositories on Google Cloud Platform. Cloud Source Repositories allows you to store, manage, and track your code using the Git version control system. You can also use Cloud Source Repositories to connect to other Google Cloud services, such as Cloud Build, Cloud Functions, or Cloud Run4 To use Cloud Build linked with Cloud Source Repositories to trigger retraining when new code is pushed to the repository, you need to do the following steps:
* Create a Cloud Source Repository for your code, and push your code to the repository. You can use the Cloud SDK, Cloud Console, or Cloud Source Repositories API to create and manage your repository5
* Create a Cloud Build trigger for your repository, and specify the build configuration and the trigger settings. You can use the Cloud SDK, Cloud Console, or Cloud Build API to create and manage your trigger.
* Specify the steps of the build in a YAML or JSON file, such as installing the dependencies, running the tests, building the container image, and submitting the training job to AI Platform. You can also use the
* Cloud Build predefined or custom build steps to simplify your build configuration.
* Push your new code to the repository, and the trigger will start the build automatically. You can monitor the status and logs of the build using the Cloud SDK, Cloud Console, or Cloud Build API.
The other options are not as easy or feasible. Using Cloud Functions to identify changes to your code in Cloud Storage and trigger a retraining job is not ideal, as Cloud Functions has limitations on the memory, CPU, and execution time, and does not provide a user interface for managing and tracking your builds. Using the gcloud command-line tool to submit training jobs on AI Platform when you update your code is not optimal, as it requires manual intervention and does not leverage the benefits of Cloud Build and its integration with Cloud Source Repositories. Creating an automated workflow in Cloud Composer that runs daily and looks for changes in code in Cloud Storage using a sensor is not relevant, as Cloud Composer is mainly designed for orchestrating complex workflows across multiple systems, and does not provide a version control system for your code.
References: 1: Image segmentation 2: Cloud Build overview 3: Creating and managing build triggers 4: Cloud Source Repositories overview 5: Quickstart: Create a repository : [Quickstart: Create a build trigger] :
[Configuring builds] : [Viewing build results]
NEW QUESTION # 294
......
The software keeps track of the previous Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) practice exam attempts and shows the changes of each attempt. You don't need to wait days or weeks to get your performance report. The software displays the result of the Google Professional-Machine-Learning-Engineer Practice Test immediately, which is an excellent way to understand which area needs more attention.
Valid Professional-Machine-Learning-Engineer Exam Forum: https://www.actualcollection.com/Professional-Machine-Learning-Engineer-exam-questions.html
What's more, part of that ActualCollection Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=1HDzbCTXQRBGo3C9onW1cGhq7oZzmUAkh