We promise you will pass the exam and obtain the Snowflake Certified SnowPro Specialty - Snowpark certificate successfully with our help of SPS-C01 exam questions. According to recent survey of our previous customers, 99% of them can achieve their goals, so believe that we can be the helping hand to help you achieve your ultimate goal. Bedsides we have high-quality SPS-C01 test guide for managing the development of new knowledge, thus ensuring you will grasp every study points in a well-rounded way. On the other hand, if you fail to pass the exam with our SPS-C01 Exam Questions unfortunately, you can receive a full refund only by presenting your transcript. At the same time, if you want to continue learning, our SPS-C01 test guide will still provide free updates to you and you can have a discount more than one year. Finally our refund process is very simple. If you have any question about Snowflake Certified SnowPro Specialty - Snowpark study question, please contact us immediately.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark API and Development | 30% | - Python API fundamentals
|
| Topic 2: Data Transformations and Operations | 35% | - Advanced operations
|
| Topic 3: Performance and Best Practices | 10% | - Security and governance
|
| Topic 4: Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
|
>> SPS-C01 New Braindumps Pdf <<
We don't want you to prepare and practice the old questions and waste time. Therefore, our team of certified experts includes updated Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 Exam Questions as soon as they are released. Test4Engine provides up-to-date Snowflake exam questions.
NEW QUESTION # 99
You are using Snowpark Python to process a large dataset. You need to persist a DataFrame to a Snowflake table but want to ensure the operation is as efficient as possible and minimizes the data transfer overhead. The table already exists with the appropriate schema. Which of the following strategies would be the MOST efficient way to write the DataFrame to the existing table?
Answer: B
Explanation:
is generally the most efficient method for appending data to an existing Snowflake table using Snowpark. It directly inserts the data into the table without the overhead of creating a new table or overwriting the existing one. with the default 'append' mode (A) might work, but 'insertlnto' is more explicit and potentially optimized for this specific scenario. (B) would replace the entire table, which is not efficient if you only want to add new data. Creating a temporary table and then using 'CREATE OR REPLACE TABLE AS SELECT (D) involves unnecessary steps and data transfer. Writing to a stage and then using 'COPY INTO' (E) is also less efficient than directly inserting the data using Snowpark.
NEW QUESTION # 100
You are working with image files stored in a Snowflake internal stage named 'image_stage'. You need to write a Snowpark Python application to resize these images using a Python library called 'PIG. The resizing logic is encapsulated in a function called resize_image(snowflake_file: SnowflakeFile, width: int, height: int) -> bytes. Which of the following code snippets correctly registers he 'resize image' function as a UDF and applies it to the image files?
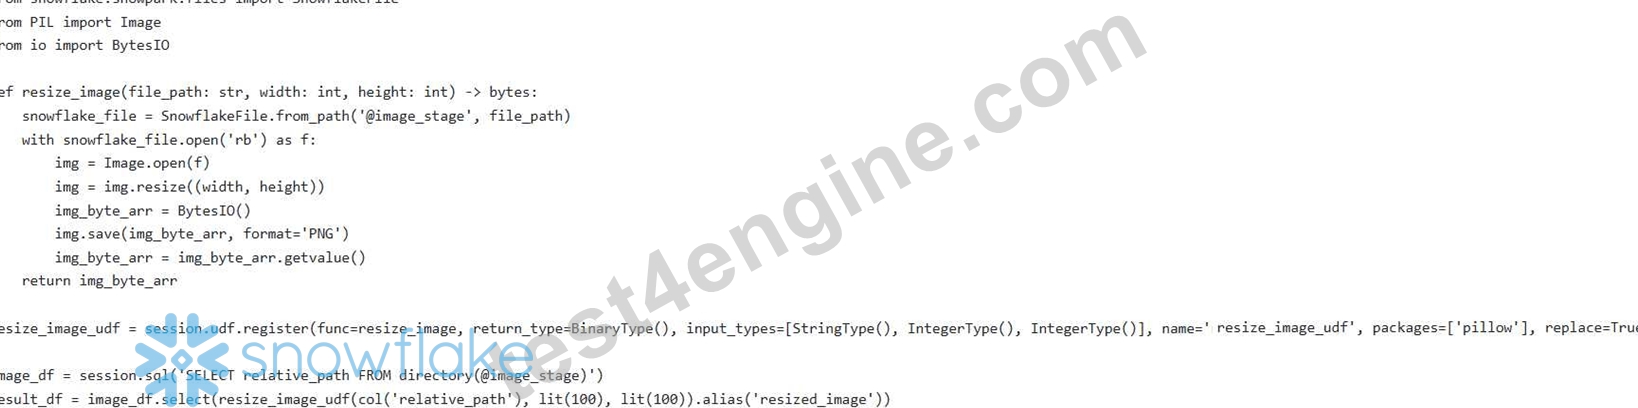
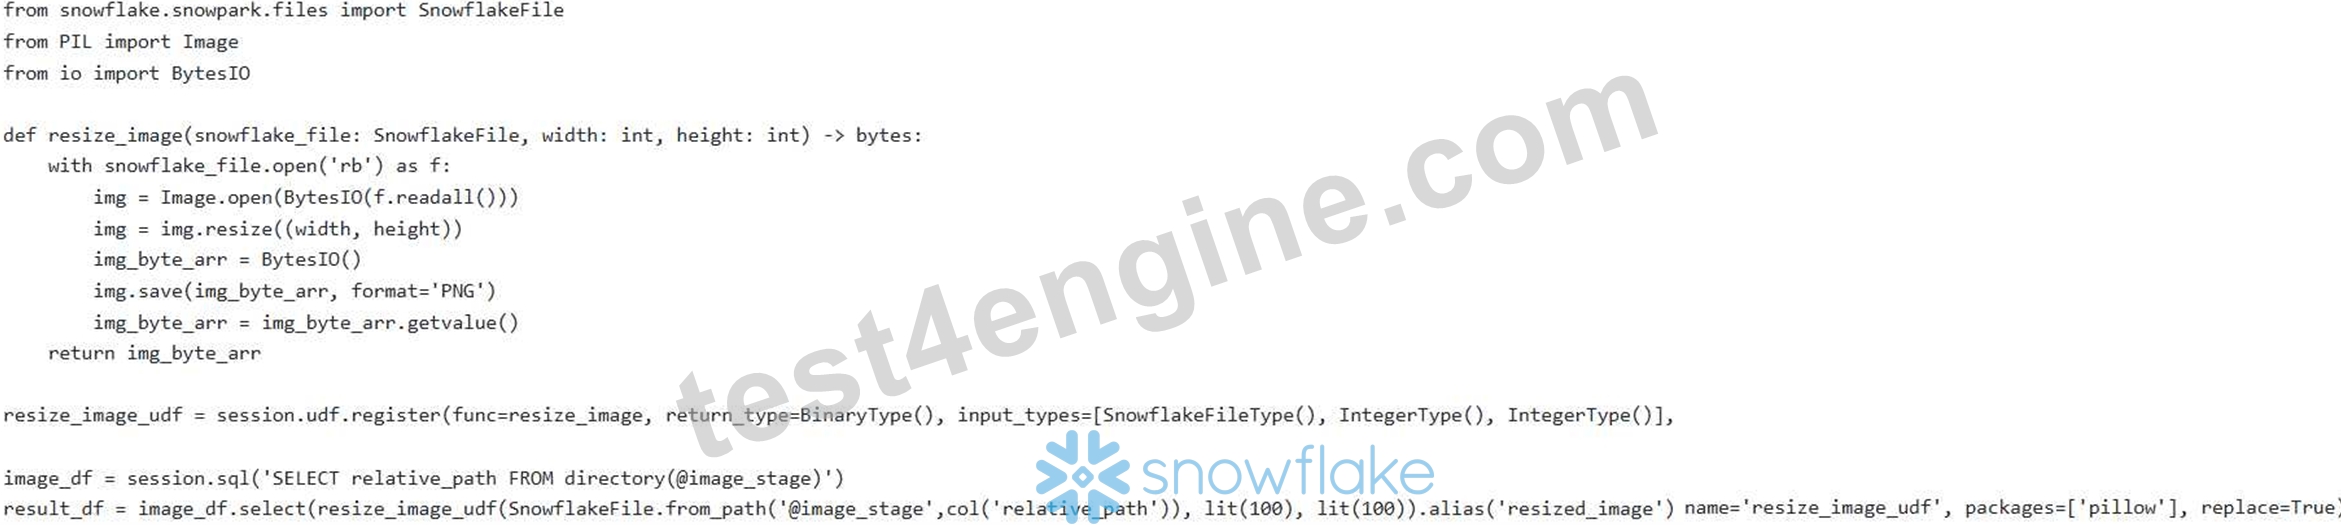
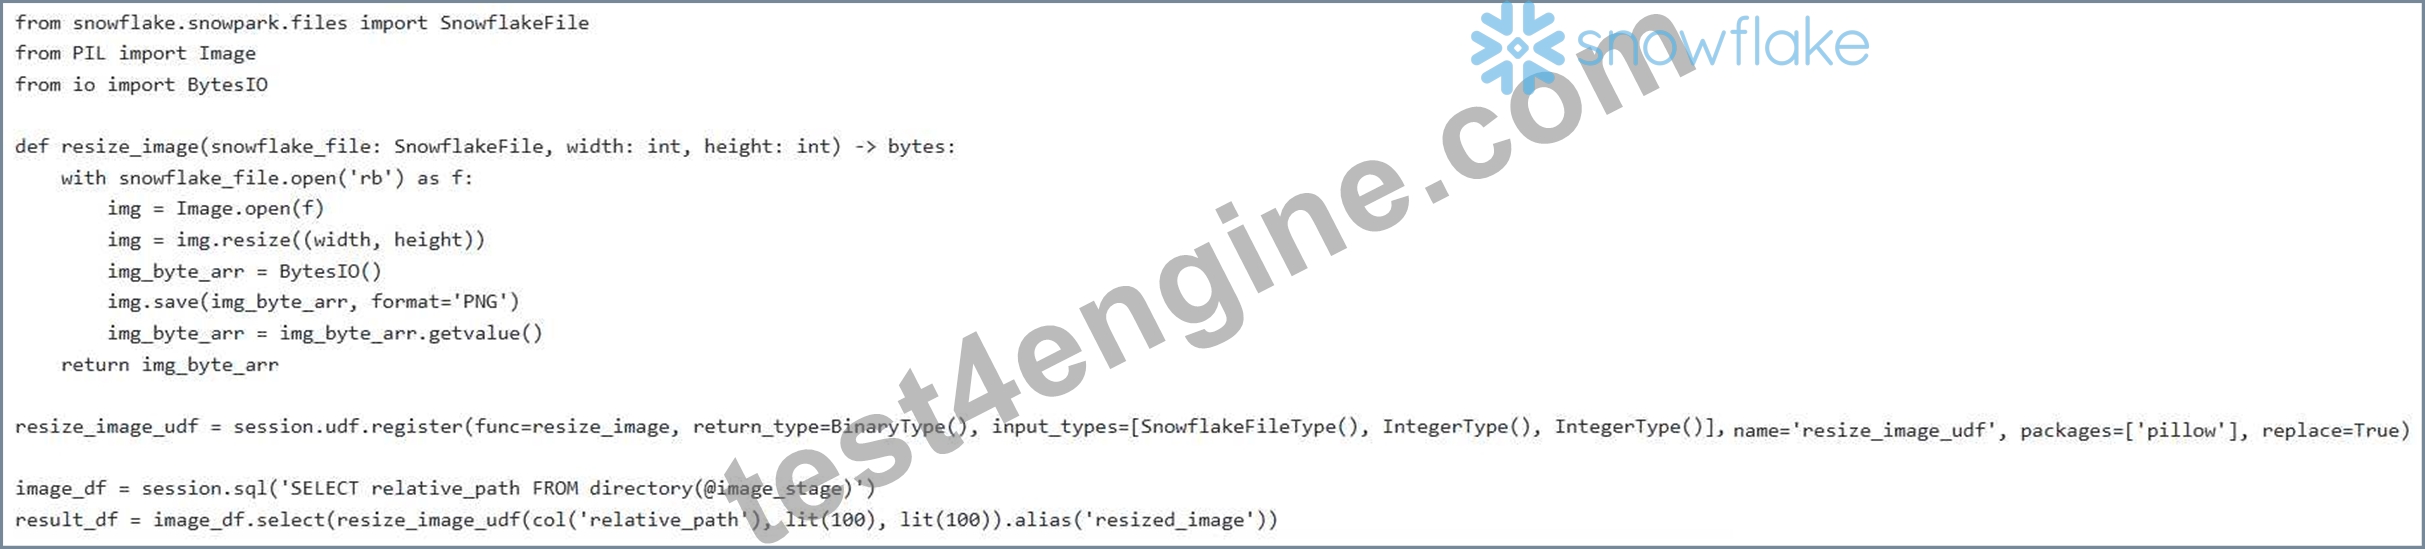
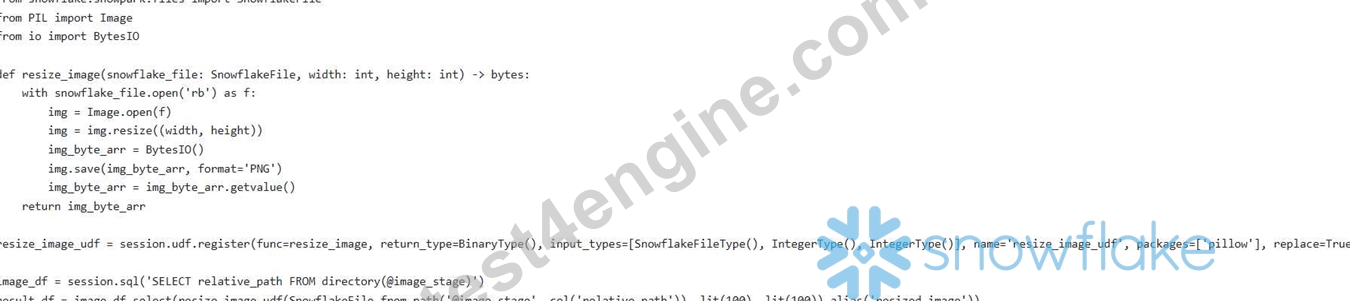
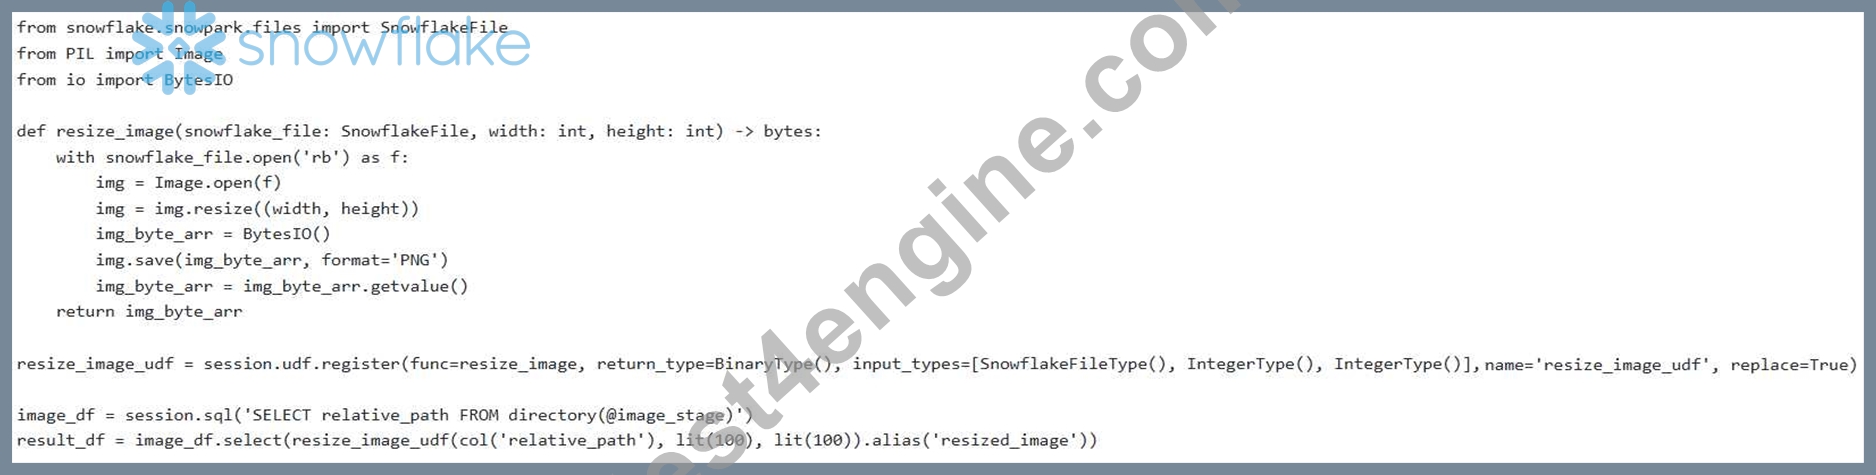
Answer: E
Explanation:
Option E correctly implements the image resizing using Snowpark UDF and 'SnowflakeFile' object. - The 'resize_image' function takes the as input and constructs the SnowflakeFile object correctly - 'SnowflakeFile.from_path('@image_stage', file_path)' correctly creates Snowflake file object based on provided file path - The UDF registration specifies the correct input type 'StringType' for file path , BinaryType' for the return and includes the 'pillow' package. - The final select statement calls the UDF correctly with the 'relative_path' column. Option D is incorrect because 'f.readall()' returns bytes, and PIL.lmage.open expects a file-like object or filename, wrapping this within ByteslO is unnecessary. Option B is wrong because the snowflake file object should be created in the python function itself, UDF creation and calling both are wrong Option A and C have registration issue for packages, as it is not provided to function registration.
NEW QUESTION # 101
Consider the following Snowpark Python code snippet designed to aggregate sales data by region: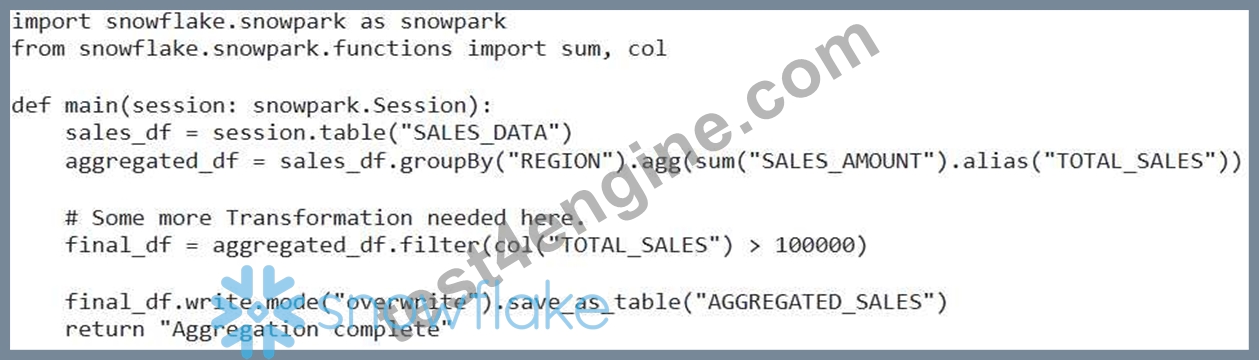
During testing, you observe that the performance of this code is suboptimal, especially when dealing with very large 'SALES DATA tables. Using Snowflake's query history, you notice that a significant amount of time is spent on data shuffling during the operation. What optimization strategies could you employ within this Snowpark code to minimize data shuffling and improve the overall performance?
Answer: A,B,E
Explanation:
Filtering early reduces data shuffling by reducing the volume of data that needs to be grouped. Repartitioning ensures that rows with the same region are on the same node before the group by which reduces shuffling significantly. Creating the source SALES_DATA table as a clustered table with REGION as the clustering key colocates the data for each region in the same micropartitions, reducing shuffling. Increasing warehouse size will help overall performance but will not directly reduce shuffling. Hints apply to Joins, not group by operations.
NEW QUESTION # 102
You are troubleshooting a Snowpark application that fails to connect to Snowflake intermittently. The error message indicates an issue with the specified account identifier Which of the following actions could help resolve this issue? Select all that apply.
Answer: A,B,D
Explanation:
A faulty account identifier would obviously cause issues. Also, It is crucial to verify that the account identifier is correctly specified, including the region if your account is not in the default AWS US West (Oregon) region. Also check if Snowflake service outage and if connecting IP address has access to Snowflake. Option B is relevant to authorization, but not directly to account identifier issues. Option E might help in some situations, but it is not directly related to account identifier problems, so we can exclude it. Note that, network policies can cause intermittent connection issues.
NEW QUESTION # 103
You need to perform a set difference operation between two DataFrames in Snowpark Python. 'dfl' contains customer IDs from a marketing campaign, and 'df2 contains customer IDs from a recent purchase event. You want to identify customers who were targeted in the campaign but did not make a recent purchase. Both DataFrames have a column named 'customer id'. Which of the following approaches provides the most efficient way to accomplish this task in Snowpark?





Answer: A
Explanation:
Option C, using a 'left_anti' join, is the most efficient way to perform a set difference operation between two DataFrames in Snowpark. A join returns only the rows from the left DataFrame Cdfl s) where the join condition is not met in the right DataFrame Cdf2). This leverages Snowflake's query optimizer for optimal performance. Option A, 'subtract(df2)' , is equivalent to 'exceptAll(df2)' (Option B) and removes duplicate rows. While functionally correct, join is often more performant, especially for larger datasets. Option D is highly inefficient as it collects the 'customer_id' from 'df2 to the driver, it should be avoided. Option E calculates intersection, not difference.
NEW QUESTION # 104
......
With rapid development of IT industry, more and more requirements have been taken on those who are working in IT industry. So if you don't want to be eliminated in the competition, to pass SPS-C01 exam is a necessary for you. If you worry that you will not get the satisfied results after you have taken too much time and energy to prepare the SPS-C01 Exam. Now let our Test4Engine help you! Countless SPS-C01 exam software users of our Test4Engine let us have the confidence to tell you that using our test software, you will have the most reliable guarantee to pass SPS-C01 exam.
SPS-C01 Valid Test Registration: https://www.test4engine.com/SPS-C01_exam-latest-braindumps.html