The software version of the Databricks-Generative-AI-Engineer-Associate exam reference guide is very practical. This version has helped a lot of customers pass their exam successfully in a short time. The most important function of the software version is to help all customers simulate the real examination environment. If you choose the software version of the Databricks-Generative-AI-Engineer-Associate Test Dump from our company as your study tool, you can have the right to feel the real examination environment. In addition, the software version is not limited to the number of the computer. So hurry to buy the Databricks-Generative-AI-Engineer-Associate study question from our company.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Latest Databricks Databricks-Generative-AI-Engineer-Associate Exam Online <<
The Databricks-Generative-AI-Engineer-Associate certificate you have obtained can really prove your ability to work. Of course, our Databricks-Generative-AI-Engineer-Associate study materials will also teach you how to improve your work efficiency. No matter how good the newcomer is, your status will not be shaken! Our Databricks-Generative-AI-Engineer-Associate Practice Braindumps really are so powerful. If you still have concerns, you can use the free trial versions first. They are the free demos of the Databricks-Generative-AI-Engineer-Associate exam questions for you to free download.
NEW QUESTION # 61
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.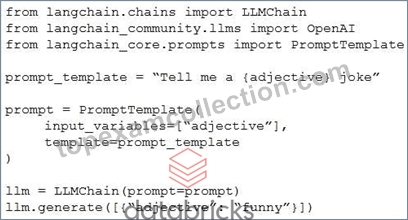
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?

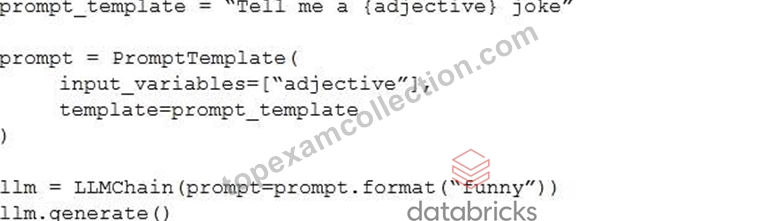
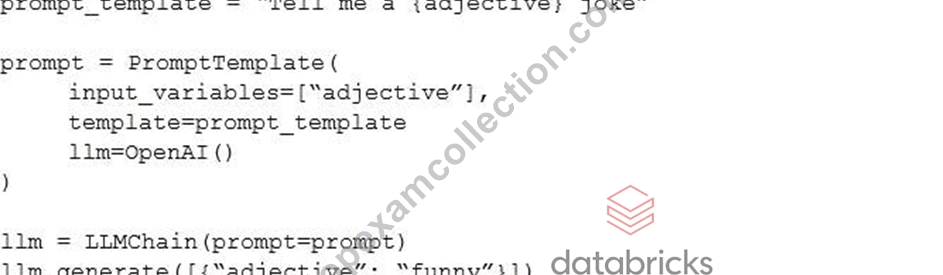
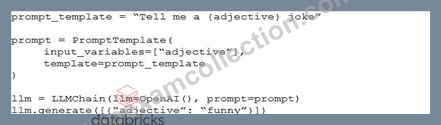
Answer: C
Explanation:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods:
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
* Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
* Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 62
A Generative Al Engineer is building a RAG application that answers questions about internal documents for the company SnoPen AI.
The source documents may contain a significant amount of irrelevant content, such as advertisements, sports news, or entertainment news, or content about other companies.
Which approach is advisable when building a RAG application to achieve this goal of filtering irrelevant information?
Answer: C
Explanation:
In a Retrieval-Augmented Generation (RAG) application built to answer questions about internal documents, especially when the dataset contains irrelevant content, it's crucial to guide the system to focus on the right information. The best way to achieve this is byincluding a clear instruction in the system prompt(option C).
* System Prompt as Guidance:The system prompt is an effective way to instruct the LLM to limit its focus to SnoPen AI-related content. By clearly specifying that the model should avoid answering questions unrelated to SnoPen AI, you add an additional layer of control that helps the model stay on- topic, even if irrelevant content is present in the dataset.
* Why This Approach Works:The prompt acts as a guiding principle for the model, narrowing its focus to specific domains. This prevents the model from generating answers based on irrelevant content, such as advertisements or news unrelated to SnoPen AI.
* Why Other Options Are Less Suitable:
* A (Keep All Articles): Retaining all content, including irrelevant materials, without any filtering makes the system prone to generating answers based on unwanted data.
* B (Include in the System Prompt about SnoPen AI): This option doesn't address irrelevant content directly, and without filtering, the model might still retrieve and use irrelevant data.
* D (Consolidating Documents into a Single Chunk): Grouping documents into a single chunk makes the retrieval process less efficient and won't help filter out irrelevant content effectively.
Therefore, instructing the system in the prompt not to answer questions unrelated to SnoPen AI (option C) is the best approach to ensure the system filters out irrelevant information.
NEW QUESTION # 63
A Generative Al Engineer is tasked with developing a RAG application that will help a small internal group of experts at their company answer specific questions, augmented by an internal knowledge base. They want the best possible quality in the answers, and neither latency nor throughput is a huge concern given that the user group is small and they're willing to wait for the best answer. The topics are sensitive in nature and the data is highly confidential and so, due to regulatory requirements, none of the information is allowed to be transmitted to third parties.
Which model meets all the Generative Al Engineer's needs in this situation?
Answer: D
Explanation:
Problem Context : The Generative AI Engineer needs a model for a Retrieval-Augmented Generation (RAG) application that provides high-quality answers, where latency and throughput are not major concerns.
The key factors are confidentiality and sensitivity of the data, as well as the requirement for all processing to be confined to internal resources without external data transmission.
Explanation of Options :
* Option A: Dolly 1.5B : This model does not typically support RAG applications as it ' s more focused on image generation tasks.
* Option B: OpenAI GPT-4 : While GPT-4 is powerful for generating responses, its standard deployment involves cloud-based processing, which could violate the confidentiality requirements due to external data transmission.
* Option C: BGE-large : The BGE (Big Green Engine) large model is a suitable choice if it is configured to operate on-premises or within a secure internal environment that meets regulatory requirements. Assuming this setup, BGE-large can provide high-quality answers while ensuring that data is not transmitted to third parties, thus aligning with the project ' s sensitivity and confidentiality needs.
* Option D: Llama2-70B : Similar to GPT-4, unless specifically set up for on-premises use, it generally relies on cloud-based services, which might risk confidential data exposure.
Given the sensitivity and confidentiality concerns, BGE-large is assumed to be configurable for secure internal use, making it the optimal choice for this scenario.
NEW QUESTION # 64
A Generative AI Engineer is building an interactive catalog for a company's inventory system that allows users to search for any item using a plain-text description. There are currently about 17,000 items, and new items are not frequently added. They need a solution that will be the most cost-effective and easy for the company to maintain.
Which solution should the engineer choose?
Answer: C
Explanation:
Option D best matches the small catalog, infrequent updates, and maintenance requirements. Databricks- managed embeddings remove the need to build and maintain a separate embedding-generation pipeline. A Delta Sync index connects the searchable content to its source Delta table. Triggered synchronization updates the index when explicitly invoked, making it suitable when inventory changes are occasional. Continuous synchronization maintains a running streaming pipeline and therefore introduces additional synchronization costs that this scenario does not justify. Self-managed embeddings add engineering responsibilities without a stated benefit. Storage-optimized endpoints primarily address much larger vector collections. Triggered synchronization reduces synchronization overhead; it does not eliminate the separate costs of serving the vector index or computing embeddings. Databricks documentation
NEW QUESTION # 65
A company has a typical RAG-enabled, customer-facing chatbot on its website.
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: C
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
Embedding Model (1):
The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
Vector Search (2):
The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
Context-Augmented Prompt (3):
The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
Response-Generating LLM (4):
Finally, the context-augmented prompt is fed into a response-generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence is embedding model, vector search, context-augmented prompt, response-generating LLM, which is option A.
NEW QUESTION # 66
......
It’s our responsibility to offer instant help to every user on our Databricks-Generative-AI-Engineer-Associate exam questions. If you have any question about Databricks-Generative-AI-Engineer-Associate study materials, please do not hesitate to leave us a message or send us an email. Our customer service staff will be delighted to answer your questions on the Databricks-Generative-AI-Engineer-Associate learing engine. And we will give you the most professional suggeston on the Databricks-Generative-AI-Engineer-Associate practice prep with kind and considerate manner in 24/7 online.
Databricks-Generative-AI-Engineer-Associate Guaranteed Passing: https://www.topexamcollection.com/Databricks-Generative-AI-Engineer-Associate-vce-collection.html