Our product boosts many advantages and it is worthy for you to buy it. You can have a free download and tryout of our DP-750 exam torrents before purchasing. After you purchase our product you can download our DP-750 study materials immediately. We will send our product by mails in 5-10 minutes. We provide free update and the discounts for the old client. If you have any doubts or questions you can contact us by mails or the online customer service personnel and we will solve your problem as quickly as we can. Our DP-750 Exam Materials boost high passing rate and if you are unfortunate to fail in exam we can refund you in full at one time immediately. The learning costs you little time and energy and you can commit yourself mainly to your jobs or other important things.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Topic 2: Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Topic 3: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Topic 4: Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
After decades of hard work, our products are currently in a leading position in the same kind of education market, our DP-750 learning materials, with their excellent quality and constantly improved operating system, In many areas won the unanimous endorsement of many international customers. Advanced operating systems enable users to quickly log in and use, in constant practice and theoretical research, our DP-750 learning materials have come up with more efficient operating system to meet user needs, so we can assure users here , after user payment , users can perform a review of the DP-750 Exam in real time , because our advanced operating system will immediately send users DP-750 learning material to the email address where they are paying , this greatly facilitates the user, lets the user be able to save more study time.
NEW QUESTION # 62
You need to deploy Databricks Asset Bundles to a development environment. The solution must support automated and repeatable deployments across environments.
What should you use?
Answer: C
Explanation:
The correct answer is C - the Databricks CLI.
Databricks Asset Bundles are deployed using the Databricks CLI (v0.205+) with the commands databricks bundle validate, databricks bundle deploy, and databricks bundle run. The CLI reads the databricks.yml file, resolves the target environment settings, and creates or updates all declared resources (jobs, pipelines, apps) in the workspace. This is the documented, supported deployment mechanism for DABs and integrates naturally into CI/CD pipelines.
Option A (Azure Developer CLI / azd) is a general Azure IaC tool with no native understanding of Databricks bundles. Option B (Git folders) syncs notebook and file content from a Git repository into a workspace - useful for code, but it doesn't deploy Lakeflow Jobs, SDP pipelines, or bundle configurations. Option D (Azure CLI) manages Azure infrastructure (resource groups, storage accounts, etc.) and has no native DAB deployment support.
Reference: https://learn.microsoft.com/en-us/azure/databricks/dev-tools/bundles/deploy-bundle
NEW QUESTION # 63
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount.isNotNull())
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
NEW QUESTION # 64
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two managed Delta tables named sales.schema1.table1 and sales.schema1.table2.
sales.schema1.table1 contains sales data from the current year.
sales.schema1.table2 contains historical data.
You need to load all the rows from sales.schema1.table1 into sales.schema1.table2. The solution must preserve any existing data in sales.schema1.table2 and minimize processing effort.
Which command should you run?
Answer: D
Explanation:
The correct answer is A - INSERT INTO.
INSERT INTO appends all rows from the source to the target. Existing rows in table2 are untouched - the historical data stays intact - and the current year's rows from table1 are added. That is exactly what the requirement asks: 'preserve any existing data and minimise processing effort.' Option B (CREATE TABLE AS SELECT) would fail if table2 already exists, or if used with CREATE OR REPLACE it wipes table2 entirely before writing - historical data gone. Option C (INSERT OVERWRITE) replaces the entire table content with only the table1 rows, also destroying table2's existing data. Option D (CREATE OR REPLACE TABLE AS SELECT) explicitly drops and recreates the table, eliminating all historical records.
INSERT INTO is deliberately the simplest possible command here - one line, no special options, no risk of accidental data loss.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-insert-into
NEW QUESTION # 65
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.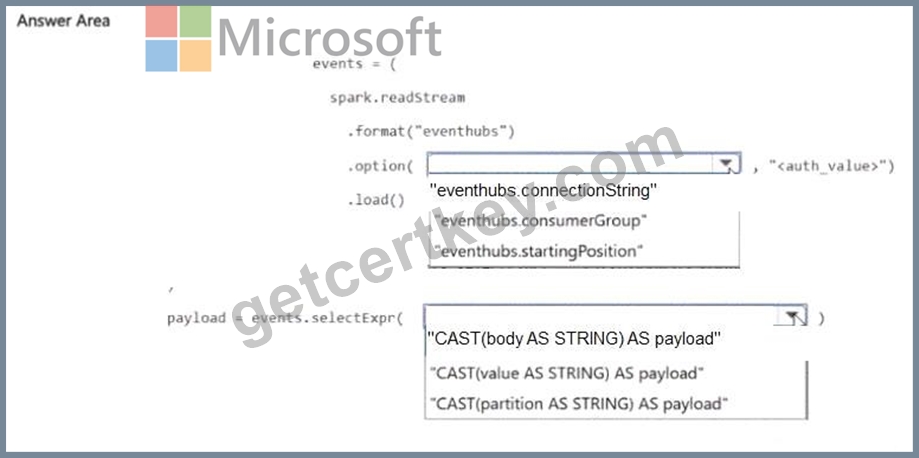
Answer:
Explanation: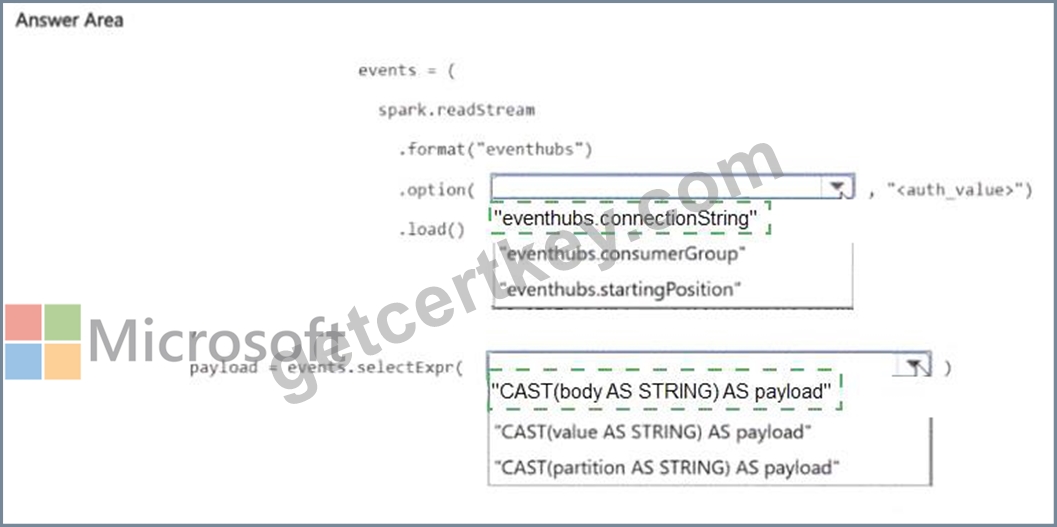
Explanation:
Reading from Azure Event Hubs in Spark Structured Streaming requires three things:
An EventHubsConf object built with the Event Hubs connection string (eventhubs.connectionString). This object is then converted to a map with .toMap before being passed to Spark.
spark.readStream.format( ' eventhubs ' ).options(**ehConf).load() to create the streaming DataFrame. The ' eventhubs ' format is provided by the azure-eventhubs-spark connector library.
A cast( ' string ' ) on the body column to decode the binary payload. Event Hubs delivers messages with the raw event bytes in a column called body - without the cast, you get binary data rather than the readable JSON or text payload.
This is the standard, documented integration pattern for connecting Azure Databricks to Event Hubs with Structured Streaming, providing the checkpoint-based exactly-once semantics required by the Contoso telemetry pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/storage/events/eventhubs
NEW QUESTION # 66
You have a Declarative Automation Bundle.
You plan to use the Databricks CLI to deploy the bundle to an environment named dev.
How should you complete the CLI command? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
The databricks bundle command group is used to validate, deploy, run, and manage Declarative Automation Bundles. The deploy subcommand deploys the bundle's defined resources-such as Lakeflow jobs, pipelines, dashboards, files, and notebooks-to the target Azure Databricks workspace.
The --target dev option selects the target named dev from the targets mapping in the bundle's databricks.yml configuration. Therefore, the complete command is databricks bundle deploy --target dev. The shorter -t dev syntax is also valid, but the answer area provides the full --target form. Microsoft Learn databricks workspace manages workspace objects and is not the command group for deploying bundles. az databricks workspace manages Azure Databricks workspace resources through the Azure CLI. The run dev option would attempt to execute a deployed bundle resource, while sync --target dev synchronizes local files with the workspace but does not deploy the complete bundle configuration.
NEW QUESTION # 67
......
It is an important process that filling in the correct mail address in order that it is easier for us to send our DP-750 study guide to you after purchase, therefore, this personal message is particularly important. We are selling virtual DP-750 learning dumps, and the order of our DP-750 training materials will be immediately automatically sent to each purchaser's mailbox according to our system. It is very fast and convenient to have our DP-750 practice questions.
Practice DP-750 Online: https://www.getcertkey.com/DP-750_braindumps.html