BONUS!!! Laden Sie die vollständige Version der DeutschPrüfung SPS-C01 Prüfungsfragen kostenlos herunter: https://drive.google.com/open?id=1D-U2YtI_dfeIHsXHaGlWsSvtYR23Plft
DeutschPrüfung hat eine starke Gruppe, die aus IT-Eliten besteht. Sie verfolgen ständig die neuesten Informationen über die Schulungsunterlagen der Snowflake SPS-C01 Zertifizierung mit ihren professionellen Perspektiven. Mit unseren Schulungsunterlagen zur Snowflake SPS-C01 Zertifizierung können Sie die Snowflake SPS-C01 Prüfung leichter bestehen, statt zu viel Zeit zu kosten. Nach dem Kauf unserer Produkte werden Sie einjährige Aktualisierung genießen.
| Section | Objectives |
|---|---|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| Data Engineering with Snowpark | - Pipeline development
|
| Testing, Debugging, and Deployment | - Production readiness
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
>> SPS-C01 Online Praxisprüfung <<
Mit der Ankunft der Informationsepoche im 21. Jahrhunderts wird das Snowflake SPS-C01 Zertifikat auch unerlässlich in der IT-Branche. Ob Sie ein Anfänger oder ein Pendler sind, können Sie Ihre erwünschte Ergebnisse nur mit Häflte der Bemühungen von anderen erzeilen, denn es gibt bei DeutschPrüfung für Sie maßgeschneidete Fragenkataloge zur Snowflake SPS-C01 Zertifizierungsprüfung. DeutschPrüfung wird Ihnen begleiten, für den Traum zu kämpfen. Worauf warten Sie noch?
41. Frage
You have a Snowflake table named 'CUSTOMER DATA' with columns 'CUSTOMER ID', 'NAME, 'CITY , and 'ORDER COUNT. You want to create a Snowpark DataFrame named 'customer_df containing only customers from 'New York' with an 'ORDER COUNT greater than 10. Which of the following code snippets is the MOST efficient and correct way to achieve this, minimizing data transfer and maximizing pushdown optimization to Snowflake?



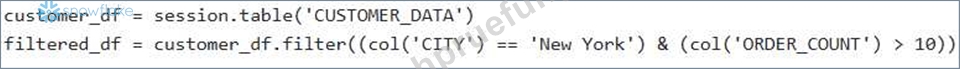

Antwort: D
Begründung:
Option A is the most efficient. It directly uses the 'filter' method with the combined condition, allowing Snowpark to push down the entire filter to Snowflake for execution. Option B uses 'session.sqr, which might not be as optimized as using the table API directly. Option C pulls the entire table into Pandas, which is highly inefficient for large tables, defeating the purpose of Snowpark. Option D, while functional, is less readable than A, and the multiple 'where' calls are logically equivalent to a single 'filter' with combined conditions. Option E, while functional, contains redundant 'select(' 'V operation.
42. Frage
You are developing a secure UDF in Snowpark Python that needs to access sensitive data stored in an internal stage. The UDF should be accessible to users without granting them direct access to the stage. Which of the following security measures and code snippets are required to achieve this, assuming the stage is already created?
Antwort: C
Begründung:
Secure UDFs are designed to execute with the privileges of the UDF owner, not the caller. allows secure access to stage credentials. Option B is incorrect because granting USAGE on the stage directly grants access to the data in the stage. Option C is a valid approach but unnecessary complex. Option D concerns external functions, not secure UDFs within Snowflake. Option E is incorrect because 'VOLATILE doesn't affect privilege handling.
43. Frage
You are working with a Snowpark DataFrame named 'employees_df' that contains employee data, including a column named 'hire_date' of type String. The date format in the 'hire_date' column is 'MM/DD/YYYY'. You need to convert this column to a DateType so you can perform date-based calculations. Which of the following Snowpark code snippets correctly converts the column to a DateType?





Antwort: E
Begründung:
Option C is correct. The 'to_date' function in Snowpark requires the column to be converted as the first argument and the date format as the second argument to correctly parse the string representation of the date. Option A will attempt to convert, but since no format is provided it will fail or produce unexpected results, if the string format matches the default date format. Option B provides the wrong separator. Option D passes column name as string to 'to_date' function, it requires column object and Option E converts to 'TimestampType' , whereas we need 'DateType'.
44. Frage
You are tasked with processing a Snowpark DataFrame named 'orders df that contains order information. The DataFrame includes the following columns: 'order _ id' (INTEGER), 'customer_id' (INTEGER), 'order_date' (DATE), 'order_total' (STRING), and 'discount_code' (STRING). The 'order_total' column contains values with leading dollar signs and commas (e.g., '$1 ,234.56'). The column can contain codes like 'SAVEIO', 'SAVE20', or be NULL. Your goal is to create a new DataFrame 'transformed_df that includes the following transformations: 1 . Convert the 'order_total' column to a numeric value (DOUBLE) after removing the dollar signs and commas. 2. Apply a discount based on the 'discount_code'. If the 'discount_code' is 'SAVEIO', apply a 10% discount; if it's 'SAVE20', apply a 20% discount. If the 'discount_code' is NULL or any other value, apply no discount (0%). 3. Calculate the 'final_total' after applying the discount. Which of the following code snippets correctly and efficiently implements these transformations using Snowpark?





Antwort: D
Begründung:
Option A correctly implements all transformations efficiently using Snowpark functions. It converts 'order_totar to a numeric value, applies the discount based on the using 'when' , and calculates the 'final_totar. It avoids using IJDFs or 'collect' operations, which can be less efficient. Using 'lit' with numeric values isn't necessary or best practice, so option B is less preferable. Option C attempts to use a IJDF, which is less efficient than using built-in Snowpark functions. Also 'to_number' and for IJDF is not required. Option D calculates the discount amount directly instead of the discount rate. Option E attempts to use 'rdd.map' which is not available and it's generally advised against as it removes parallelism.
45. Frage
You are tasked with creating a Snowpark DataFrame from a complex JSON structure stored in a VARIANT column named 'payload' within a table called 'events'. The 'payload' contains nested objects and arrays, and you need to extract specific fields into separate columns of the DataFrame. You need to extract the 'event_id' (INT) from the top level of the JSON, the 'user _ id' (INT) from the 'user' object nested within the 'payload' , and the first element of the 'tags' array (VARCHAR) also nested within the 'payload'. Which of the following code snippets correctly defines the schema using 'StructType' and 'StructField' and applies it during DataFrame creation assuming events table contains multiple rows?





Antwort: C
Begründung:
Option B extracts the necessary data and creates schema separately. Option A cannot chain the schema to after select operatiom Option C defines payload as VariantType, which is already there. option D has with_schema function which does not exist in current snowflake version. Option E tries to apply schema before select statement which is logically wrong.
46. Frage
......
Wie kann man Erfolge erlangen. Es gibt nur eine Ankürzung, nämlich: die Lernhilfe zur Snowflake SPS-C01Zertifizierungsprüfung von DeutschPrüfung zu benutzen. Das ist unser Vorschlag für jeden Kandidaten. Wir hoffen, dass Sie Ihren Traum erfüllen können.
SPS-C01 Prüfungsmaterialien: https://www.deutschpruefung.com/SPS-C01-deutsch-pruefungsfragen.html
2026 Die neuesten DeutschPrüfung SPS-C01 PDF-Versionen Prüfungsfragen und SPS-C01 Fragen und Antworten sind kostenlos verfügbar: https://drive.google.com/open?id=1D-U2YtI_dfeIHsXHaGlWsSvtYR23Plft