2026 DumpTOP 최신 Databricks-Certified-Data-Engineer-Professional PDF 버전 시험 문제집과 Databricks-Certified-Data-Engineer-Professional 시험 문제 및 답변 무료 공유: https://drive.google.com/open?id=1fCS3ytJjb1mmJFSirNSVA1laD6jgPlBu
DumpTOP의 Databricks 인증 Databricks-Certified-Data-Engineer-Professional시험덤프공부자료 출시 당시 저희는 이런 크나큰 인지도를 갖출수 있을지 생각도 못했었습니다. 저희를 믿어주시고 구매해주신 분께 너무나도 감사한 마음에 더욱 열심히 해나가자는 결심을 하였습니다. Databricks 인증 Databricks-Certified-Data-Engineer-Professional덤프자료는DumpTOP의 전문가들이 최선을 다하여 갈고닦은 예술품과도 같습니다.100% 시험에서 패스하도록 저희는 항상 힘쓰고 있습니다.
| Section | Objectives |
|---|---|
| Topic 1: Production Pipelines and Orchestration | - Job scheduling and monitoring - Databricks Workflows - Error handling and recovery strategies |
| Topic 2: Data Modeling and Transformation | - Spark SQL transformations - Performance optimization techniques - Dimensional modeling concepts |
| Topic 3: Delta Lake and Data Management | - Time travel and versioning - Delta Lake transactions and ACID properties - Schema evolution and enforcement |
| Topic 4: Databricks Lakehouse Platform Architecture | - Workspace and cluster architecture - Data governance concepts (Unity Catalog basics) - Medallion architecture (Bronze, Silver, Gold) |
| Topic 5: Data Ingestion and Processing | - Batch and streaming ingestion with Auto Loader - Structured Streaming fundamentals - ETL pipeline design patterns |
>> Databricks-Certified-Data-Engineer-Professional시험대비 덤프 최신문제 <<
Databricks-Certified-Data-Engineer-Professional인증시험은Databricks인증시험중의 하나입니다.그리고 또한 비중이 아주 큰 인증시험입니다. 그리고Databricks Databricks-Certified-Data-Engineer-Professional인증시험 패스는 진짜 어렵다고 합니다. 우리DumpTOP에서는 여러분이Databricks-Certified-Data-Engineer-Professional인증시험을 편리하게 응시하도록 전문적이 연구팀에서 만들어낸 최고의Databricks-Certified-Data-Engineer-Professional덤프를 제공합니다, DumpTOP와 만남으로 여러분은 아주 간편하게 어려운 시험을 패스하실 수 있습니다,
질문 # 64
Each configuration below is identical to the extent that each cluster has 400 GB total of RAM 160 total cores and only one Executor per VM.
Given an extremely long-running job for which completion must be guaranteed, which cluster configuration will be able to guarantee completion of the job in light of one or more VM failures?
정답:C
설명:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
질문 # 65
Two data engineers are working on the same Databricks notebook in separate branches. Both have edited the same section of code. When one tries to merge the other's branch into their own using the Databricks Git folders UI, a merge conflict occurs on that notebook file. The UI highlights the conflict and presents options for resolution. How should the data engineers resolve this merge conflict using Databricks Git folders?
정답:D
설명:
In the Databricks Git folders integration, when merge conflicts arise in notebooks, the UI provides a visual diff editor that highlights conflicting code segments. Users can manually choose which changes to keep from each branch, edit directly in the notebook UI, and remove conflict markers.
After resolving, the engineer must mark the conflict as resolved, save, and commit the final version.
This process ensures that both contributors' valid code segments are merged correctly and version history is maintained.
Forcing a push (C) or deleting notebooks (B) introduces data loss or versioning issues. Aborting without review (A) violates collaborative best practices. Therefore, D is the only correct and Databricks-approved way to resolve notebook merge conflicts.
질문 # 66
In order to prevent accidental commits to production data, a senior data engineer has instituted a policy that all development work will reference clones of Delta Lake tables. After testing both deep and shallow clone, development tables are created using shallow clone. A few weeks after initial table creation, the cloned versions of several tables implemented as Type 1 Slowly Changing Dimension (SCD) stop working. The transaction logs for the source tables show that vacuum was run the day before.
Why are the cloned tables no longer working?
정답:C
설명:
In Delta Lake, a shallow clone creates a new table by copying the metadata of the source table without duplicating the data files. When the vacuum command is run on the source table, it removes old data files that are no longer needed to maintain the transactional log's integrity, potentially including files referenced by the shallow clone's metadata. If these files are purged, the shallow cloned tables will reference non-existent data files, causing them to stop working properly. This highlights the dependency of shallow clones on the source table's data files and the impact of data management operations like vacuum on these clones.
질문 # 67
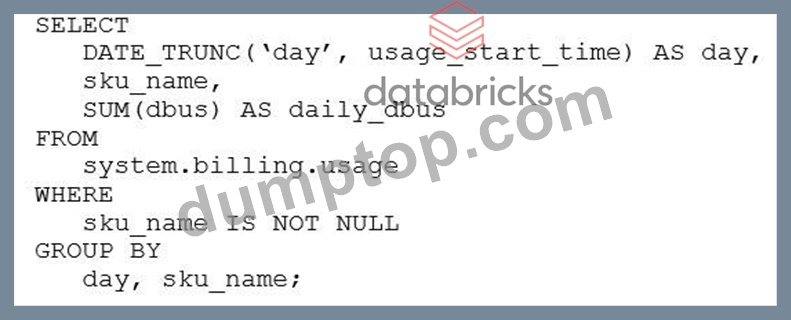
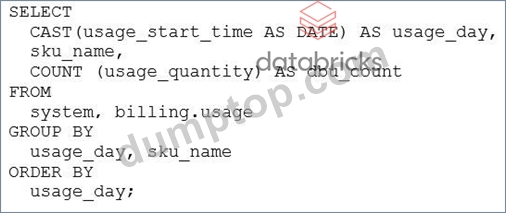
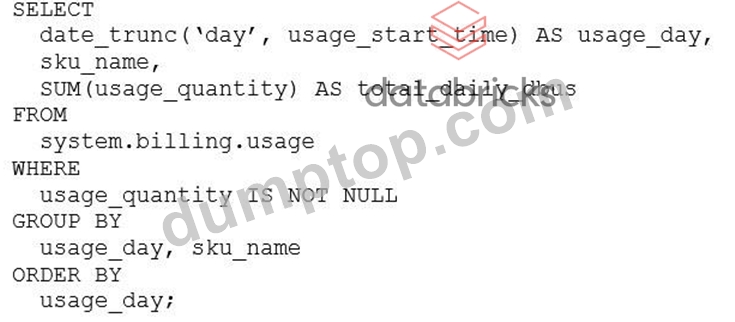
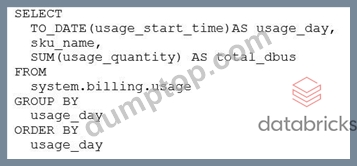
A platform engineer needs to report the resource consumption, categorized by SKU tier, across all workspaces. The engineer decides to use the system.billing.usage system table to create a query. Which SQL query will accurately return the daily usage by product?
정답:C
설명:
This query correctly aggregates usage at a daily granularity by truncating the usage start timestamp to the day and summing the usage quantity, which represents DBUs. Grouping by both the derived daily value and the SKU name ensures usage is accurately categorized by product tier across all workspaces.
질문 # 68
A data engineer is building a Lakeflow Declarative Pipelines pipeline to process healthcare claims data. A metadata JSON file defines data quality rules for multiple tables, including:
{
"claims": [
{"name": "valid_patient_id", "constraint": "patient_id IS NOT NULL"},
{"name": "non_negative_amount", "constraint": "claim_amount >= 0"}
]
}
The pipeline must dynamically apply these rules to the claims table without hardcoding the rules.
How should the data engineer achieve this?
정답:C
설명:
Lakeflow Declarative Pipelines provide the expect_all method for programmatically applying multiple data quality expectations at once. The documentation explains that @dlt.expect_all accepts a dictionary of expectation names mapped to SQL constraints, allowing rules to be dynamically loaded from metadata such as JSON files. This ensures that pipelines remain maintainable and scalable without needing to hardcode individual @dlt.expect decorators. The event logs will track each expectation's pass and fail counts individually, making it auditable.
질문 # 69
......
경쟁율이 치열한 IT업계에서 아무런 목표없이 아무런 희망없이 무미건조한 생활을 하고 계시나요? 다른 사람들이 모두 취득하고 있는 자격증에 관심도 없는 분은 치열한 경쟁속에서 살아남기 어렵습니다. Databricks인증 Databricks-Certified-Data-Engineer-Professional시험패스가 힘들다한들DumpTOP덤프만 있으면 어려운 시험도 쉬워질수 밖에 없습니다. Databricks인증 Databricks-Certified-Data-Engineer-Professional덤프에 있는 문제만 잘 이해하고 습득하신다면Databricks인증 Databricks-Certified-Data-Engineer-Professional시험을 패스하여 자격증을 취득해 자신의 경쟁율을 업그레이드하여 경쟁시대에서 안전감을 보유할수 있습니다.
Databricks-Certified-Data-Engineer-Professional시험대비 덤프문제: https://www.dumptop.com/Databricks/Databricks-Certified-Data-Engineer-Professional-dump.html
그리고 DumpTOP Databricks-Certified-Data-Engineer-Professional 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1fCS3ytJjb1mmJFSirNSVA1laD6jgPlBu