In the matter of quality, our AI-200 practice engine is unsustainable with reasonable prices. Despite costs are constantly on the rise these years from all lines of industry, our AI-200 learning materials remain low level. That is because our company beholds customer-oriented tenets that guide our everyday work. The achievements of wealth or prestige is no important than your exciting feedback about efficiency and profession of our AI-200 Study Guide.
| Section | Objectives |
|---|---|
| Topic 1: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Topic 2: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Topic 3: Connect to and consume Azure services | - Integrate Azure services
|
| Topic 4: Develop containerized solutions on Azure | - Implement containerized applications
|
>> AI-200 Hot Spot Questions <<
We have to admit that the exam of gaining the AI-200 certification is not easy for a lot of people, especial these people who have no enough time. If you also look forward to change your present boring life, maybe trying your best to have the AI-200 Certification is a good choice for you. Now it is time for you to take an exam for getting the certification.
NEW QUESTION # 52
You are developing a .NET application that uses Azure Cosmos DB for NoSQL to store application data The application uses the Azure Cosmos DB for NoSQL SDK to interact with the database account. The application must perform the following tasks
* Initialize the connection by using the account endpoint and key.
* Define shared throughput.
* Perform create, read, update, and delete (CRUD) operations on items stored in a container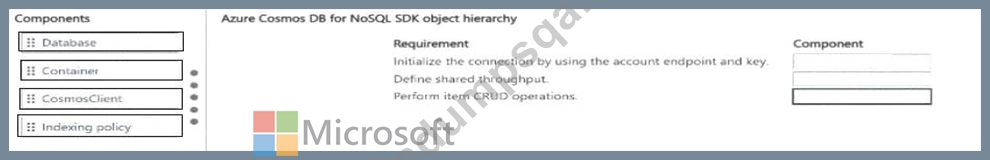
Answer:
Explanation: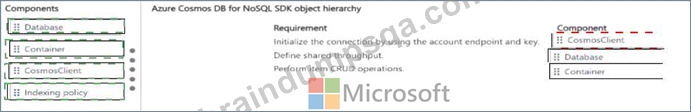
Explanation: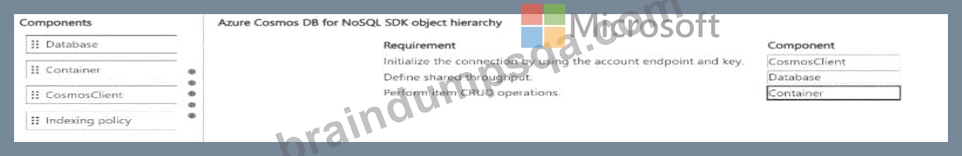
Verified Answer: Initialize connection: CosmosClient. Define shared throughput: Database. Perform item CRUD: Container.
Detailed Explanation: The Cosmos DB SDK follows the service resource hierarchy. CosmosClient represents the account connection and is initialized with the account endpoint and credential. Shared throughput is configured at the database level when multiple containers share database throughput. Item create, read, update, and delete operations are performed through a container object because containers hold items and define partitioning/indexing behavior. An indexing policy is configuration attached to a container, not the SDK object used for CRUD.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Cosmos DB databases, containers, and items
NEW QUESTION # 53
You have an Azure web app that uses Azure Cosmos DB as a data store. You create a Cosmos DB container by running the following PowerShell script: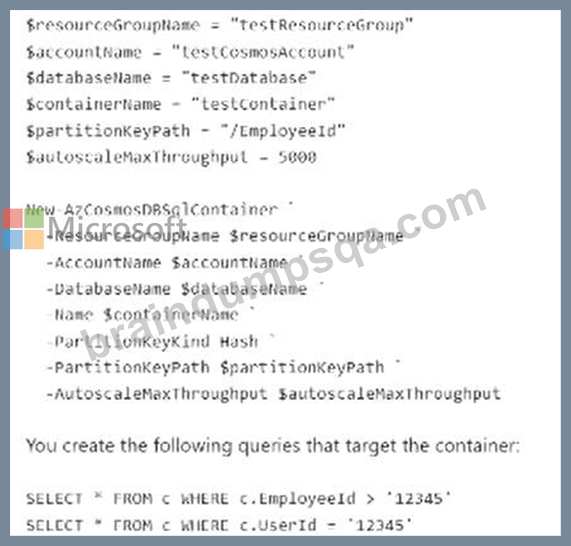
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.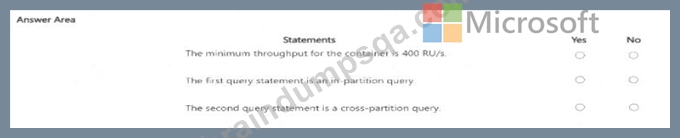
Answer:
Explanation: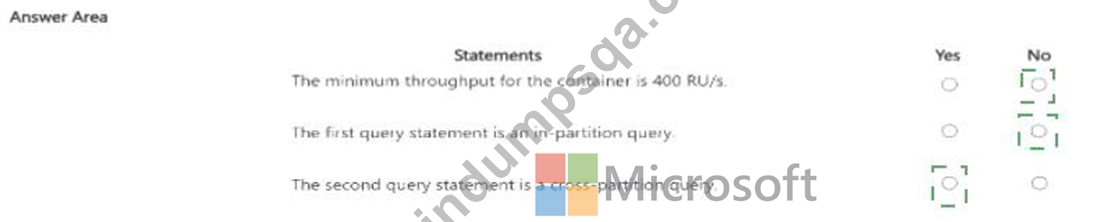
Explanation: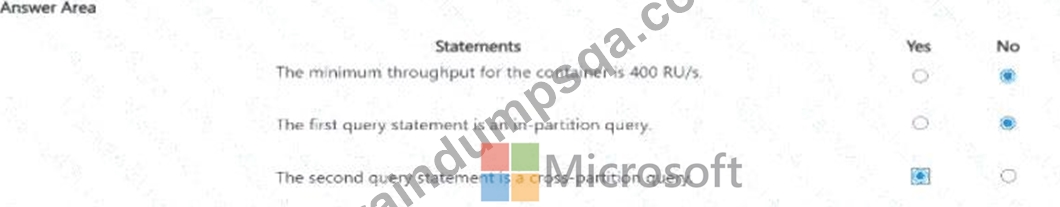
The question maps directly to the AI-200 objective "Develop AI solutions by using Azure Cosmos DB for NoSQL," which includes running queries and optimizing query performance and Request Unit (RU) consumption.
Statement 1: No - The minimum throughput is not 400 RU/s.
The PowerShell command provisions the container with:
-AutoscaleMaxThroughput 5000
Azure Cosmos DB autoscale operates between approximately 10% and 100% of the configured maximum throughput . Microsoft documentation specifically gives the example of an autoscale container provisioned with 5,000 RU/s scaling between 500 RU/s and 5,000 RU/s . Therefore, for this container, the minimum operating autoscale throughput is 500 RU/s , not 400 RU/s.
Therefore:
"The minimum throughput for the container is 400 RU/s." # No
Statement 2: No - The first query is not an in-partition query.
The container uses:
/EmployeeId
as its partition key.
The first query is:
SELECT * FROM c WHERE c.EmployeeId > ' 12345 '
Although the query references the partition key, it uses a range predicate ( > ) , not an equality predicate.
Microsoft explicitly states that a range filter on a partition key is not scoped to a single physical partition .
To qualify as an in-partition query, the filter must identify the applicable partition, typically through an equality predicate such as:
WHERE c.EmployeeId = ' 12345 '
Microsoft ' s documentation provides essentially the same example: a query using DeviceId > ... against a container partitioned by DeviceId is not an in-partition query .
Therefore:
"The first query statement is an in-partition query." # No
Statement 3: Yes - The second query is a cross-partition query.
The second query is:
SELECT * FROM c WHERE c.UserId = ' 12345 '
The container ' s partition key is /EmployeeId, not /UserId. Because the query contains no filter on the partition key , Azure Cosmos DB cannot route it to one logical partition. It must fan out the query across the applicable physical partitions and combine the results.
Microsoft describes this behavior directly: when a query does not contain a filter on the partition key, it must execute across the partitions.
Therefore:
"The second query statement is a cross-partition query." # Yes
NEW QUESTION # 54
Hotspot Question
You deploy a Linux container image to App Service.
The container requires the following environment variables at runtime:
- A non-sensitive configuration value named MODEL_VERSION
- A database password that must remain secure
You need to configure App Service to provide these environment variables at runtime.
Which configurations should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.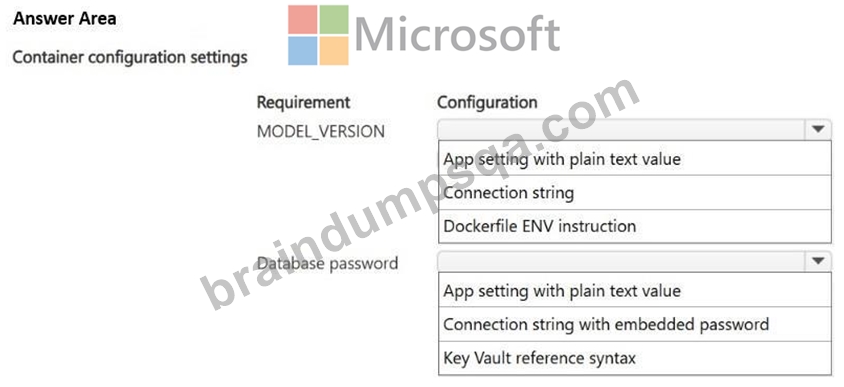
Answer:
Explanation: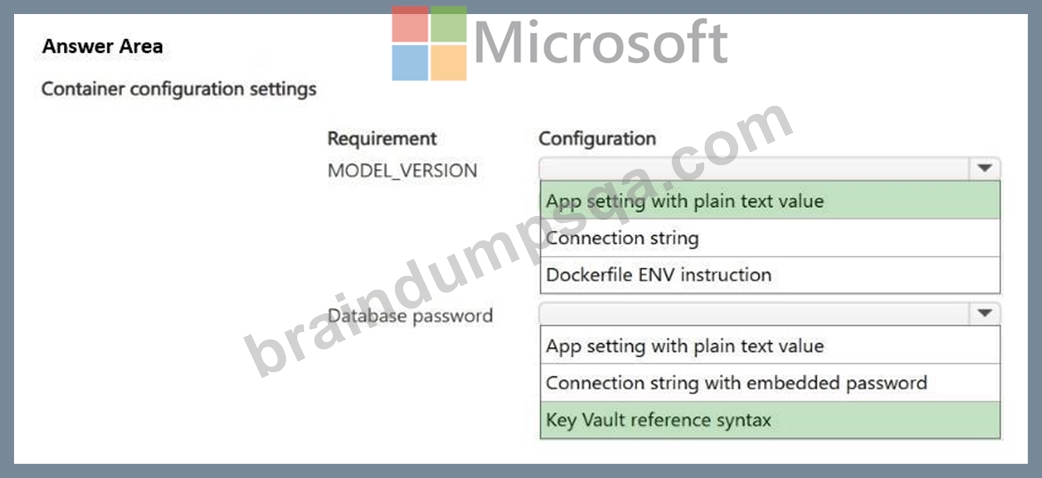
Explanation:
Box 1: App setting with plain text value
To provide a non-sensitive environment variable named MODEL_VERSION to a Linux custom container deployed to Azure App Service, you should configure it as an Application Setting (App Setting). In Azure App Service, any custom configuration defined within the Application Settings is automatically injected into Linux containers as an environment variable at runtime.
Box 2: Key Vault reference syntax
You should configure the database password as an Azure Key Vault reference inside App Service Application Settings. This prevents the secret from being stored in plaintext in the app configuration and injects it securely into the container as an environment variable at runtime.
Reference:
https://learn.microsoft.com/en-us/azure/app-service/tutorial-custom-container?tabs=azure-cli&pivots=container-linux
NEW QUESTION # 55
A semantic search application queries Azure Database for PostgreSQL and stores document embeddings and metadata in a table with the following columns:
* embedding (pgvector)
* department
* created_at
The application must return the top five most similar documents for a given query embedding only from the finance department. You need to implement semantic retrieval with metadata filtering.
Which query components should you select? To answer, move the appropriate query components to the correct requirements. You may use each query component once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.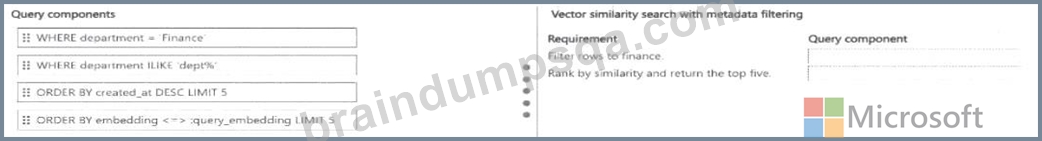
Answer:
Explanation: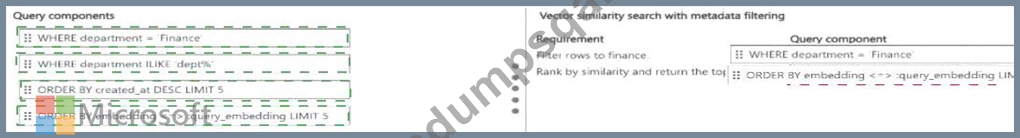
Explanation: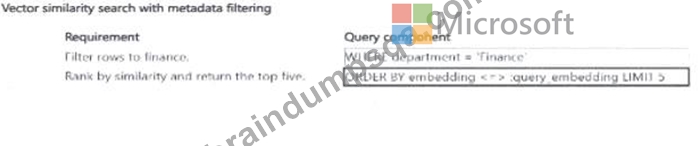
Verified Answer: Filter: `WHERE department = ' finance ' `. Rank/top five: `ORDER BY embedding < = > query_embedding LIMIT 5`.
Detailed Explanation: The metadata predicate must restrict the candidate rows to the Finance department, so the `WHERE department = ' finance ' ` component supplies the required filter. The pgvector cosine-distance operator ` < = > ` orders rows by vector distance to the supplied query embedding, and `LIMIT 5` keeps only the five nearest matches. Ordering by creation date would rank recency rather than semantic similarity, and a wildcard department filter would not satisfy the Finance-only requirement.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector similarity search with Azure PostgreSQL
NEW QUESTION # 56
Your application stores conversation history so a multi-turn chatbot can reference earlier turns, but the context window is limited. You need to keep the most relevant history within token limits.
What should you implement?
Answer: C
NEW QUESTION # 57
......
Our AI-200 practice dumps compiled by the most professional experts can offer you with high quality and accuracy practice materials for your success. Up to now, we have more than tens of thousands of customers around the world supporting our AI-200 Exam Questions. If you are unfamiliar with our AI-200 study materials, please download the free demos for your reference, and to some unlearned exam candidates, you can master necessities by our AI-200 training guide quickly.
AI-200 Trustworthy Exam Content: https://www.braindumpsqa.com/AI-200_braindumps.html