The Channel Partner Program Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer certification enables you to move ahead in your career later. With the Databricks Databricks-Certified-Professional-Data-Engineer certification exam you can climb up the corporate ladder faster and achieve your professional career objectives. Do you plan to enroll in the Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer Certification Exam? Looking for a simple and quick way to crack the Databricks Databricks-Certified-Professional-Data-Engineer test?
The DCPDE exam is a comprehensive assessment that covers a wide range of topics related to data engineering on Databricks. Databricks-Certified-Professional-Data-Engineer Exam consists of multiple-choice questions and performance-based tasks that require candidates to demonstrate their ability to design, build, and deploy scalable data pipelines on the Databricks platform.
>> Databricks-Certified-Professional-Data-Engineer Certificate Exam <<
Certificate is not only an affirmation for the professional ability, but also can improve your competitive force in the job market. Databricks-Certified-Professional-Data-Engineer training materials will help you pass the exam just one time. Databricks-Certified-Professional-Data-Engineer exam materials are high quality and accuracy, due to we have a professional team to collect the latest information for the exam. We are pass guarantee and money back guarantee if you fail to pass the exam, and the money will be returned to your payment account. Databricks-Certified-Professional-Data-Engineer Exam Dumps have free update for one year, that is to say, in the following year, you can get the latest version for free.
Databricks Certified Professional Data Engineer exam is a certification program offered by Databricks, a unified data analytics platform that provides a collaborative workspace for data science teams. Databricks Certified Professional Data Engineer Exam certification program is designed for data professionals who want to demonstrate their knowledge and skills in building reliable, scalable, and performant data pipelines using Databricks.
NEW QUESTION # 166
Incorporating unit tests into a PySpark application requires upfront attention to the design of your jobs, or a potentially significant refactoring of existing code.
Which statement describes a main benefit that offset this additional effort?
Answer: A
NEW QUESTION # 167
What is a method of installing a Python package scoped at the notebook level to all nodes in the currently active cluster?
Answer: D
Explanation:
Installing a Python package scoped at the notebook level to all nodes in the currently active cluster in Databricks can be achieved by using the Libraries tab in the cluster UI. This interface allows you to install libraries across all nodes in the cluster. While the %pip command in a notebook cell would only affect the driver node, using the cluster UI ensures that the package is installed on all nodes.
Reference:
Databricks Documentation on Libraries: Libraries
NEW QUESTION # 168
A data engineer is attempting to execute the following PySpark code:
df = spark.read.table( " sales " )
result = df.groupBy( " region " ).agg(sum( " revenue " ))
However, upon inspecting the execution plan and profiling the Spark job, they observe excessive data shuffling during the aggregation phase.
Which technique should be applied to reduce shuffling during the groupBy aggregation operation?
Answer: D
Explanation:
Databricks documents that shuffle occurs when Spark redistributes data across partitions for grouping or joining. To optimize aggregation performance, repartitioning by the grouping key (region) ensures rows with the same key are co-located in the same partition, thus minimizing shuffle movement. Caching improves reuse of DataFrames but does not reduce shuffle volume. coalesce() reduces the number of partitions after computation and cannot prevent shuffle. Broadcast joins are unrelated to single-table aggregations. The recommended practice for reducing shuffle in aggregation is explicit repartitioning by the grouping column.
NEW QUESTION # 169
A transactions table has been liquid clustered on the columns product_id, user_id, and event_date.
Which operation lacks support for cluster on write?
Answer: B
Explanation:
Delta Lake'sLiquid Clusteringis an advanced feature that improves query performance by dynamically clustering data without requiring costly compaction steps like traditional Z-ordering.
When performing writes to aLiquid Clusteredtable, some write operations automatically maintain clustering, while othersdo not.
Explanation of Each Option:
* (A) spark.writestream.format('delta').mode('append') (Correct Answer)
* Reason:Streaming writes (writestream) donotsupportLiquid Clusteringbecause streaming data arrives in micro-batches.
* Since Liquid Clustering needs efficient global reorganization of files, streaming append operations don't provide sufficient data volume at a time to be effectively clustered.
* Delta Lake documentation states that Liquid Clustering is only supported for batch writes.
* (B) CTAS and RTAS statements
* Reason:CREATE TABLE AS SELECT (CTAS) and REPLACE TABLE AS SELECT (RTAS) are batch operationsand can enforce Liquid Clustering.
* These operations create or replace a table based on a query result, and since they are batch-based, Liquid Clustering applies.
* (C) INSERT INTO operations
* Reason:INSERT INTOis supportedfor Liquid Clustering because it is a batch operation.
* While it may not be as efficient as MERGE or COPY INTO, clustering is applied upon execution.
* (D) spark.write.format('delta').mode('append')
* Reason:Batch append operationsare supportedfor Liquid Clustering.
* Unlike streaming append, batch writes allow the optimizer to re-cluster data efficiently.
Conclusion:
Sincestreaming append operations do not support Liquid Clustering, option(A)is the correct answer.
References:
* Liquid Clustering in Delta Lake - Databricks Documentation
NEW QUESTION # 170
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.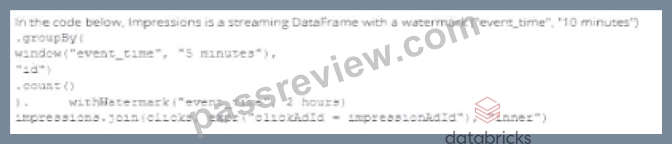
Which solution would improve the performance?




Answer: A
Explanation:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time.
However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
NEW QUESTION # 171
......
Databricks-Certified-Professional-Data-Engineer Trustworthy Practice: https://www.passreview.com/Databricks-Certified-Professional-Data-Engineer_exam-braindumps.html