100% Pass-Rate Databricks-Certified-Data-Engineer-Professional Valid Real Test Offer You The Best Test Result | Databricks Certified Data Engineer Professional Exam

The Databricks wants to become the first choice for quick and complete Databricks Databricks-Certified-Data-Engineer-Professional exam preparation. To achieve this objective the Databricks has hired a team of experienced and qualified Databricks-Certified-Data-Engineer-Professional Exam trainers. They have years of experience in verifying Databricks Certified Data Engineer Professional Exam exam practice test questions.
| Section | Weight | Objectives |
|---|
| Data Transformation, Cleansing, and Quality | 10% | - Apply data cleansing and validation rules
- Implement schema evolution and management
- Enforce data quality standards
|
| Data Governance | 7% | - Use Unity Catalog for governance
- Enforce data policies and standards
- Manage data assets and metadata
|
| Monitoring and Alerting | 10% | - Set up alerts and notifications
- Track data lineage and metrics
- Monitor pipeline performance and health
|
| Data Ingestion & Acquisition | 7% | - Use Auto Loader and structured streaming
- Ingest data from diverse sources
- Handle incremental and batch data loads
|
| Developing Code for Data Processing using Python and SQL | 22% | - Implement complex data processing logic
- Write efficient and maintainable code
- Use Databricks-specific libraries and APIs
|
| Data Sharing and Federation | 5% | - Use Delta Sharing for secure data sharing
- Manage cross-platform data access
- Implement Lakehouse Federation
|
| Debugging and Deploying | 10% | - Implement CI/CD and DevOps practices
- Deploy using Asset Bundles, CLI, and APIs
- Troubleshoot and debug pipelines
|
| Ensuring Data Security and Compliance | 10% | - Ensure data privacy and compliance
- Secure data at rest and in transit
- Implement access control and permissions
|
| Data Modelling | 6% | - Implement dimensional and relational models
- Design Medallion Architecture
- Optimize table design and partitioning
|
| Cost & Performance Optimisation | 13% | - Apply cost management best practices
- Optimize compute and storage resources
- Improve query and pipeline performance
|
>> Databricks-Certified-Data-Engineer-Professional Valid Real Test <<
Test Databricks-Certified-Data-Engineer-Professional Result, Databricks-Certified-Data-Engineer-Professional Test Tutorials
The FreeDumps is also committed to ace the Databricks Databricks-Certified-Data-Engineer-Professional exam preparation journey and enable you to get success in the final Databricks Certified Data Engineer Professional Exam Databricks-Certified-Data-Engineer-Professional exam. To achieve this objective the FreeDumps is offering real, updated, and error-free Databricks Certified Data Engineer Professional Exam Databricks-Certified-Data-Engineer-Professional Dumps in three easy-to-use and compatible formats. These formats are Databricks-Certified-Data-Engineer-Professional PDF dumps files, desktop FreeDumps Databricks-Certified-Data-Engineer-Professional practice exam software, and web-based Databricks-Certified-Data-Engineer-Professional practice test software.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q173-Q178):
NEW QUESTION # 173
Which REST API call can be used to review the notebooks configured to run as tasks in a multi- task job?
- A. /jobs/runs/list
- B. /jobs/list
- C. /jobs/runs/get-output
- D. /jobs/get
- E. /jobs/runs/get
Answer: D
Explanation:
https://docs.databricks.com/api/workspace/jobs/getresponses/settings/tasks/notebook_task/noteb ook_path
NEW QUESTION # 174
The Databricks CLI is use to trigger a run of an existing job by passing the job_id parameter. The response that the job run request has been submitted successfully includes a filed run_id.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from Which statement describes what the number alongside this field represents?
- A. The job_id and number of times the job has been are concatenated and returned.
- B. The total number of jobs that have been run in the workspace.
- C. The globally unique ID of the newly triggered run.
- D. The number of times the job definition has been run in the workspace.
- E. The job_id is returned in this field.
Answer: C
Explanation:
When triggering a job run using the Databricks CLI, the run_id field in the response represents a globally unique identifier for that particular run of the job. This run_id is distinct from the job_id.
While the job_id identifies the job definition and is constant across all runs of that job, the run_id is unique to each execution and is used to track and query the status of that specific job run within the Databricks environment. This distinction allows users to manage and reference individual executions of a job directly.
NEW QUESTION # 175
A data engineer is masking a column containing email addresses. The goal is to produce output strings of identical length for all rows, while generating different outputs for different email values.
Which SQL function should be used to achieve this?
- A. hash(email)
- B. sha1(email)
- C. mask(email, '?')
- D. sha2(email, 0)
Answer: A
Explanation:
The hash() function in Databricks SQL returns a deterministic fixed-length integer (or hexadecimal string) derived from the input. When applied to sensitive identifiers like email addresses, it produces a unique value for each distinct input while ensuring uniform output size, making it suitable for anonymization where referential consistency is required.
Functions like mask() perform pattern-based substitutions that change string lengths, and sha1() or sha2() produce long hexadecimal strings of varying lengths (depending on hash size), which may not match requirements for fixed-length masking.
Therefore, the correct choice for fixed-length, deterministic pseudonymization of email addresses is hash(email), as it maintains analytical usability while anonymizing sensitive data.
NEW QUESTION # 176
The marketing team is looking to share data in an aggregate table with the sales organization, but the field names used by the teams do not match, and a number of marketing specific fields have not been approval for the sales org.
Which of the following solutions addresses the situation while emphasizing simplicity?
- A. Instruct the marketing team to download results as a CSV and email them to the sales organization.
- B. Create a new table with the required schema and use Delta Lake's DEEP CLONE functionality to sync up changes committed to one table to the corresponding table.
- C. Create a view on the marketing table selecting only these fields approved for the sales team alias the names of any fields that should be standardized to the sales naming conventions.
- D. Use a CTAS statement to create a derivative table from the marketing table configure a production jon to propagation changes.
- E. Add a parallel table write to the current production pipeline, updating a new sales table that varies Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from as required from marketing table.
Answer: C
Explanation:
Creating a view is a straightforward solution that can address the need for field name standardization and selective field sharing between departments. A view allows for presenting a transformed version of the underlying data without duplicating it. In this scenario, the view would only include the approved fields for the sales team and rename any fields as per their naming conventions.
NEW QUESTION # 177
The data science team has created and logged a production model using MLflow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, loads the customers table containing the customer_id key column into a DataFrame, and defines the feature columns needed for the model.
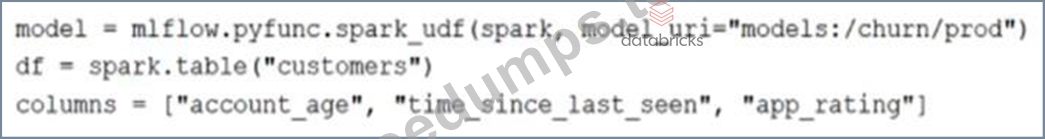
Which code block will output a DataFrame with the schema "customer_id LONG, predictions DOUBLE"?
- A. df.map(lambda x:model(x[columns])).select("customer_id, predictions")
- B. model.predict(df, columns)
- C. df.select("customer_id", model(*columns).alias("predictions"))
- D. df.select("customer_id", pandas_udf(model, columns).alias("predictions"))
- E. df.apply(model, columns).select("customer_id, predictions")
Answer: C
Explanation:
This code block applies the Spark UDF created from the MLflow model to the DataFrame df by selecting the existing customer_id column and the new column produced by the model, which is aliased to predictions. The model(*columns) part is where the UDF is applied to the columns specified in the columns list, and alias("predictions") is used to name the output column of the model's predictions. This will result in a DataFrame with the desired schema: "customer_id LONG, predictions DOUBLE".
NEW QUESTION # 178
......
Finding 60 exam preparation material that suits your learning preferences, timetable, and objectives is essential to prepare successfully for the test. You can prepare for the Databricks Databricks-Certified-Data-Engineer-Professional test in a short time and attain the Databricks Certified Data Engineer Professional Exam certification exam with the aid of our updated and valid exam questions. We emphasize quality over quantity, so we provide you with Databricks Databricks-Certified-Data-Engineer-Professional Actual Exam questions to help you succeed without overwhelming you.
Test Databricks-Certified-Data-Engineer-Professional Result: https://www.freedumps.top/Databricks-Certified-Data-Engineer-Professional-real-exam.html
- Databricks-Certified-Data-Engineer-Professional Exam Sims ☮ Databricks-Certified-Data-Engineer-Professional Online Training Materials 🪕 Databricks-Certified-Data-Engineer-Professional Reliable Test Experience 🔨 Open website ➡ www.troytecdumps.com ️⬅️ and search for [ Databricks-Certified-Data-Engineer-Professional ] for free download 🔵Databricks-Certified-Data-Engineer-Professional Reliable Test Experience
- Databricks-Certified-Data-Engineer-Professional Torrent 🥉 Databricks-Certified-Data-Engineer-Professional Torrent 🍣 Databricks-Certified-Data-Engineer-Professional Reliable Test Dumps 😝 Search for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ on ▷ www.pdfvce.com ◁ immediately to obtain a free download ◀Test Databricks-Certified-Data-Engineer-Professional Topics Pdf
- Databricks-Certified-Data-Engineer-Professional Latest Test Vce 🧏 Databricks-Certified-Data-Engineer-Professional Minimum Pass Score ⛰ Databricks-Certified-Data-Engineer-Professional Reliable Test Sample 🔻 Search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ on ➠ www.troytecdumps.com 🠰 immediately to obtain a free download 🍿Exam Databricks-Certified-Data-Engineer-Professional Actual Tests
- Databricks-Certified-Data-Engineer-Professional Torrent 🧍 Databricks-Certified-Data-Engineer-Professional Torrent 🏜 Databricks-Certified-Data-Engineer-Professional Reliable Test Sample 🏹 Go to website ➽ www.pdfvce.com 🢪 open and search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ to download for free 🗯Databricks-Certified-Data-Engineer-Professional Latest Test Vce
- Databricks-Certified-Data-Engineer-Professional Exam Valid Real Test- Latest Test Databricks-Certified-Data-Engineer-Professional Result Pass Success 🌻 Immediately open ➤ www.pass4test.com ⮘ and search for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 to obtain a free download 🧫Databricks-Certified-Data-Engineer-Professional Reliable Test Dumps
- Test Databricks-Certified-Data-Engineer-Professional Topics Pdf 🚪 Databricks-Certified-Data-Engineer-Professional Torrent 🖖 Databricks-Certified-Data-Engineer-Professional Reliable Test Experience 🎁 Open 《 www.pdfvce.com 》 enter ➥ Databricks-Certified-Data-Engineer-Professional 🡄 and obtain a free download 🧊Databricks-Certified-Data-Engineer-Professional Reliable Test Dumps
- Databricks-Certified-Data-Engineer-Professional Upgrade Dumps ✒ Databricks-Certified-Data-Engineer-Professional Upgrade Dumps 🟢 Databricks-Certified-Data-Engineer-Professional Torrent 🚾 Simply search for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ for free download on “ www.exam4labs.com ” 🧧Databricks-Certified-Data-Engineer-Professional Upgrade Dumps
- Pass Guaranteed 2026 Databricks The Best Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Valid Real Test 📮 Copy URL ➽ www.pdfvce.com 🢪 open and search for 《 Databricks-Certified-Data-Engineer-Professional 》 to download for free 📨Databricks-Certified-Data-Engineer-Professional Reliable Test Experience
- Test Databricks-Certified-Data-Engineer-Professional Topics Pdf 🦞 Databricks-Certified-Data-Engineer-Professional Training Kit 🥎 Databricks-Certified-Data-Engineer-Professional Reliable Test Dumps 🥒 The page for free download of ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ on ➡ www.practicevce.com ️⬅️ will open immediately 🤙Databricks-Certified-Data-Engineer-Professional Torrent
- Pass Guaranteed 2026 Databricks The Best Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Valid Real Test ⏯ Search for 《 Databricks-Certified-Data-Engineer-Professional 》 on ➥ www.pdfvce.com 🡄 immediately to obtain a free download 🎳Databricks-Certified-Data-Engineer-Professional Reliable Test Dumps
- 100% Pass Quiz 2026 Databricks Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Perfect Valid Real Test 💔 Copy URL ⏩ www.examcollectionpass.com ⏪ open and search for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 to download for free 🏁Databricks-Certified-Data-Engineer-Professional Minimum Pass Score
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, experiment.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes