BTW, DOWNLOAD part of ITPassLeader DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=1H7VjLhce5soOc5iV6JcNPh-qA8ZMxF2k
The only use of the internet is to validate the product license for the DP-750 practice exam software. If you are not online, you can still practice for the Microsoft DP-750 exam questions thanks to this feature of ITPassLeader's DP-750 Exam simulation software. As a result, the DP-750 desktop-based practice test software is a particularly useful option for customers who do not constantly have access to the internet.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Topic 2: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Topic 3: Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Topic 4: Prepare and process data | 30-35% | - Data transformation and modeling
|
>> Reliable DP-750 Practice Questions <<
Do you often envy the colleagues around you can successfully move to a larger company to achieve the value of life? Are you often wondering why your classmate, who has scores similar to yours, can receive a large company offer after graduation and you are rejected? In fact, what you lack is not hard work nor luck, but DP-750 Guide question. If you do not have extraordinary wisdom, do not want to spend too much time on learning, but want to reach the pinnacle of life through DP-750 exam, then you must have DP-750 question torrent.
NEW QUESTION # 79
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.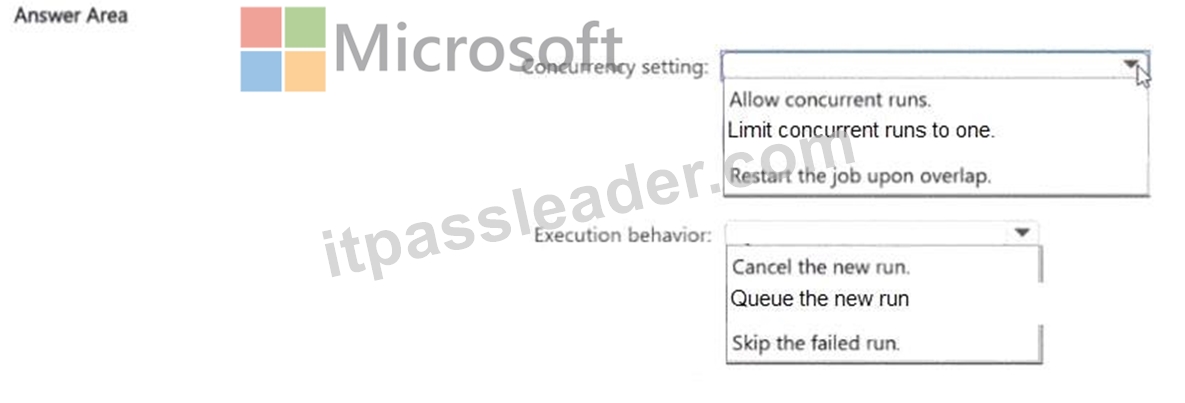
Answer:
Explanation: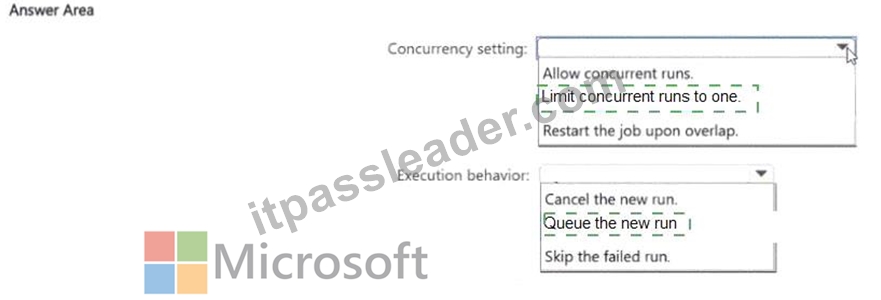
Explanation:
Two settings address the overlapping-run problem:
Concurrent Runs policy set to ' Skip ' (or ' Allow only one concurrent run ' ). When a new scheduled trigger fires while the previous run is still in progress, the new run is skipped rather than starting alongside the ongoing one. This prevents two runs from writing to the same tables at the same time - which is the data corruption risk the question highlights.
Cron-based schedule for the hourly trigger. A cron expression defines the regular execution cadence.
Combined with the concurrency setting, the job runs hourly but never overlaps.
An alternative to ' Skip ' is ' Wait ' (queue the new run), which ensures every scheduled run eventually executes - but for this scenario where overlapping is the primary concern, skipping the missed run is typically preferable to building up a queue of back-to-back executions.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#concurrent-runs
NEW QUESTION # 80
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.dropna(subset=["order_amount"])
Does this meet the goal?
Answer: A
Explanation:
The correct answer is A - Yes.
df.dropna(subset=['order_amount']) is the idiomatic PySpark way to remove rows where a specific column contains a null. It inspects only the columns listed in subset and drops any row where those columns are null.
The resulting DataFrame contains only rows where order_amount is not null - exactly what the requirement asks for.
The subset parameter is important: without it, dropna() would drop rows where ANY column is null, which could incorrectly exclude rows that have nulls in other columns but a valid order_amount. By specifying subset=['order_amount'], the filter is applied precisely and only to the column in question.
This method is semantically equivalent to df.filter(df.order_amount.isNotNull()) and to the SQL clause WHERE order_amount IS NOT NULL. Both are correct - dropna with a subset is arguably the more readable Pythonic approach.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 81
You use Databricks Asset Bundles to manage two jobs and an app.
You need to deploy the bundle to development and production environments. The solution must meet the following requirements:
- Deploy the app to both environments.
- Deploy only one job to development.
- Minimize administrative effort.
What should you use?
Answer: C
Explanation:
To meet your deployment needs with minimal administrative overhead, you should use Databricks Asset Bundle (DAB) targets combined with resource overrides or conditional lookups using Go template syntax in your databricks.yml file.
Instead of creating separate bundles or complex CI/CD logic, you can declare both jobs and the app inside the main resources block, and then filter or modify them per target environment.
Implementation Options
Depending on your preference for keeping configuration declarative or fully conditional, choose one of the two standard patterns:
*-> Option 1: Resource Overrides via targets (Recommended)
Define all components globally, but use the targets block to remove or empty out the configuration of the job you want to skip in development.yamlbundle:
name: my-unified-bundle
apps:
my_app:
# App configurations go here...
jobs:
job_shared:
# Configurations for the job deployed to BOTH dev and prod...
job_prod_only:
name: Only for Production
# Production configurations...
targets:
dev:
mode: development
workspace:
host: https://dev-workspace.cloud.databricks.com
# Keep administrative work low by overriding the prod job to null/empty resources:
jobs:
job_prod_only: !null
prod:
mode: production
workspace:
host: https://prod-workspace.cloud.databricks.com
Option 2: Go Template Conditional LogicIf you prefer not to use !null overrides, you can evaluate the target environment dynamically at deployment time using standard Go templates.
Reference:
https://docs.databricks.com/aws/en/dev-tools/bundles/workspace-deploy
NEW QUESTION # 82
Case Study 1 - Contoso, Inc.
Overview
Company Information
Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
Existing Environment
Azure Environment
Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
Workspace1 contains all-purpose clusters for both development and production workloads.
The company's Azure environment contains:
- In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
- A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
- An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Data Environment Contoso ingests the following operational and business data:
- Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
- Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
- Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
- External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
- ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
Problem Statements
The company's existing analytics environment has several issues:
Ingestion
- Telemetry pipelines fall behind during peak loads.
- Telemetry ingestion fails when schema drift occurs.
- Streaming pipelines reprocess events after a pipeline restarts.
Compute
Production and development workloads run on the same all-purpose clusters.
Production and development workloads do NOT support autoscaling or workload isolation.
Governance
- The ERP data is duplicated across systems and development teams.
- Naming conventions are inconsistent across development teams, regions, and products.
- Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
- Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names.
Historical values are NOT required.
Pipeline operations
- Pipelines lack resiliency, alerting, and centralized scheduling.
Requirements
Planned Changes
Contoso plans to implement the following changes:
- Implement scalable data pipeline orchestration.
- Create a managed analytics catalog in Unity Catalog.
- Implement a consistent approach to creating curated datasets.
- Establish a centralized governance model across ingestion, cleansed, and curated layers.
- Grant data engineers access to the ERP tables by using minimal development effort.
- Adopt a compute strategy that isolates production workloads and supports autoscaling.
- Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
Technical Requirements
Contoso identifies the following environment and compute requirements:
- Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
- Provide fast and consistent performance for business intelligence (BI) workloads.
- Prevent development activity from affecting production pipelines.
- Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Contoso identifies the following data ingestion and processing requirements:
- Auto-scale ingestion pipelines to handle bursty workloads.
- Handle schema drift for the maintenance and telemetry data.
- Ingest file-based telemetry data by using minimal operational effort.
- Store all the ingested data in a format that supports incremental processing.
- Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
- Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
- Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
- Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
Contoso identifies the following data modeling and optimization requirements:
- Build curated tables that standardize business logic.
- Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
Contoso identifies the following pipeline deployment and operation requirements:
- Orchestrate multi-step ingestion and transformation workflows.
- Define a clear execution order and dependencies.
- Automatically retry failed steps and notify operators.
- Schedule ingestion and transformation workloads consistently.
Governance Requirements
Contoso identifies the following governance requirements:
- Centralize the metadata catalog.
- Provide isolated development areas that follow standard naming conventions.
- Establish a consistent structure for organizing raw, cleansed, and curated data.
- Provide a read-only mechanism to reference the ERP data through a foreign catalog.
Business Requirements
Contoso identifies the following business requirements:
- Improve ingestion reliability and reduce operational effort.
- Standardize data definitions across development teams.
You need to develop the task logic for a new job in Lakeflow Jobs that processes telemetry data.
Each task must contain only the appropriate logic for its step in the pipeline. The solution must support the planned changes and meet the data ingestion and processing requirements.
What should you do?
Answer: A
Explanation:
Create separate tasks for ingestion, cleansing, and curation is the best architectural fit.
This modular workflow approach natively addresses the scenario's technical challenges:
Modularity and Resource Efficiency: Splitting the pipeline into distinct, sequential tasks allows you to configure dedicated, non-interactive compute clusters tailored to the specific resource requirements of each phase (e.g., lightweight for ingestion, heavier memory for curation).
Handling Peak Loads: Independent task scaling ensures that the heavy ingestion phase can scale up to handle event hub spikes without dragging down or over-allocating resources for downstream processing.
Checkpointing & Schema Drift: Separate tasks allow structured streaming checkpoints to be cleanly isolated for each step, ensuring that if a pipeline restarts, it continues exactly where it left off without reprocessing old events. Schema evolution can also be intercepted and handled gracefully between stages rather than breaking a monolith script.
Scenario:
Technical Requirements, Contoso identifies the following environment and compute requirements:
-> Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Technical Requirements, Contoso identifies the following data ingestion and processing requirements:
-> Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
Problem Statements, The company's existing analytics environment has several issues:
Ingestion
Telemetry pipelines fall behind during peak loads.
Telemetry ingestion fails when schema drift occurs.
Streaming pipelines reprocess events after a pipeline restarts.
Reference:
https://www.meegle.com/en_us/topics/etl-pipeline/etl-pipeline-for-hadoop-ecosystems
NEW QUESTION # 83
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount != None)
Does this meet the goal?
Answer: A
Explanation:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
NEW QUESTION # 84
......
After your payment is successful, you will receive an e-mail from our system within 5-10 minutes, and then, you can use high-quality DP-750 exam guide to learn immediately. Everyone knows that time is very important and hopes to learn efficiently, especially for those who have taken a lot of detours and wasted a lot of time. The sooner you download and use DP-750 Training Materials the sooner you get the DP-750 certificate.
Reliable DP-750 Exam Guide: https://www.itpassleader.com/Microsoft/DP-750-dumps-pass-exam.html
BTW, DOWNLOAD part of ITPassLeader DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=1H7VjLhce5soOc5iV6JcNPh-qA8ZMxF2k