2026 DY0-001: Fantastic CompTIA DataAI Certification Exam Associate Level Exam

P.S. Free & New DY0-001 dumps are available on Google Drive shared by TestPDF: https://drive.google.com/open?id=12tpYN8Yym_dWXCd0IvGrfVd49ox56X5L
To upgrade skills, hundreds of candidates attempt the CompTIA DataAI Certification Exam (DY0-001) certification exam and try to be smart and more efficient than the rest. In that case, they are now finding ways by which they can get help to crack the CompTIA DataAI Certification Exam (DY0-001) certification exams. Let's discuss the sources that can prove to be a major help if you are planning to take the exam.
| Topic | Details |
|---|
| Topic 1 | - Machine Learning: This section of the exam measures skills of a Machine Learning Engineer and covers foundational ML concepts such as overfitting, feature selection, and ensemble models. It includes supervised learning algorithms, tree-based methods, and regression techniques. The domain introduces deep learning frameworks and architectures like CNNs, RNNs, and transformers, along with optimization methods. It also addresses unsupervised learning, dimensionality reduction, and clustering models, helping candidates understand the wide range of ML applications and techniques used in modern analytics.
|
| Topic 2 | - Specialized Applications of Data Science: This section of the exam measures skills of a Senior Data Analyst and introduces advanced topics like constrained optimization, reinforcement learning, and edge computing. It covers natural language processing fundamentals such as text tokenization, embeddings, sentiment analysis, and LLMs. Candidates also explore computer vision tasks like object detection and segmentation, and are assessed on their understanding of graph theory, anomaly detection, heuristics, and multimodal machine learning, showing how data science extends across multiple domains and applications.
|
| Topic 3 | - Operations and Processes: This section of the exam measures skills of an AI
- ML Operations Specialist and evaluates understanding of data ingestion methods, pipeline orchestration, data cleaning, and version control in the data science workflow. Candidates are expected to understand infrastructure needs for various data types and formats, manage clean code practices, and follow documentation standards. The section also explores DevOps and MLOps concepts, including continuous deployment, model performance monitoring, and deployment across environments like cloud, containers, and edge systems.
|
| Topic 4 | - Mathematics and Statistics: This section of the exam measures skills of a Data Scientist and covers the application of various statistical techniques used in data science, such as hypothesis testing, regression metrics, and probability functions. It also evaluates understanding of statistical distributions, types of data missingness, and probability models. Candidates are expected to understand essential linear algebra and calculus concepts relevant to data manipulation and analysis, as well as compare time-based models like ARIMA and longitudinal studies used for forecasting and causal inference.
|
| Topic 5 | - Modeling, Analysis, and Outcomes: This section of the exam measures skills of a Data Science Consultant and focuses on exploratory data analysis, feature identification, and visualization techniques to interpret object behavior and relationships. It explores data quality issues, data enrichment practices like feature engineering and transformation, and model design processes including iterations and performance assessments. Candidates are also evaluated on their ability to justify model selections through experiment outcomes and communicate insights effectively to diverse business audiences using appropriate visualization tools.
|
>> DY0-001 Associate Level Exam <<
New DY0-001 Test Topics - Test DY0-001 Pdf
When new changes or knowledge are updated, our experts add additive content into our DY0-001 latest material. They have always been in a trend of advancement. Admittedly, our DY0-001 real questions are your best choice. We also estimate the following trend of exam questions may appear in the next exam according to syllabus. So they are the newest and also the most trustworthy DY0-001 Exam Prep to obtain.
CompTIA DataAI Certification Exam Sample Questions (Q16-Q21):
NEW QUESTION # 16
A data scientist is performing a linear regression and wants to construct a model that explains the most variation in the dat a. Which of the following should the data scientist maximize when evaluating the regression performance metrics?
- A. Accuracy
- B. p value
- C. R2
- D. AUC
Answer: C
NEW QUESTION # 17
A data scientist needs to:
Build a predictive model that gives the likelihood that a car will get a flat tire.
Provide a data set of cars that had flat tires and cars that did not.
All the cars in the data set had sensors taking weekly measurements of tire pressure similar to the sensors that will be installed in the cars consumers drive. Which of the following is the most immediate data concern?
- A. Lagged observations
- B. Insufficient domain expertise
- C. Granularity misalignment
- D. Multivariate outliers
Answer: A
Explanation:
Because tire-pressure sensors report only weekly measurements, you risk missing the critical pressure drop immediately preceding a flat. Those stale ("lagged") readings may not reflect the condition just before failure, undermining your model's ability to learn the true precursors to a flat tire.
NEW QUESTION # 18
A data scientist is building a proof of concept for a commercialized machine-learning model. Which of the following is the best starting point?
- A. Literature review
- B. Model performance evaluation
- C. Model selection
- D. Hyperparameter tuning
Answer: C
Explanation:
# In the proof-of-concept phase, the first practical step is model selection - identifying which modeling technique is most appropriate based on the nature of the problem, data, and business goal. Literature reviews are helpful but usually precede model experimentation.
Why the other options are incorrect:
* A: Literature review informs planning but isn't the first hands-on step.
* B: Performance evaluation comes after models are built.
* C: Hyperparameter tuning applies after a model is chosen.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 5.1:"Model selection is a critical step during early prototyping when evaluating different algorithms for feasibility."
* CRISP-DM Framework - Modeling Phase:"Selecting candidate models is the first step in model development after understanding the data."
NEW QUESTION # 19
A company created a very popular collectible card set. Collectors attempt to collect the entire set, but the availability of each card varies, because some cards have higher production volumes than others. The set contains a total of 12 cards. The attributes of the cards are shown.
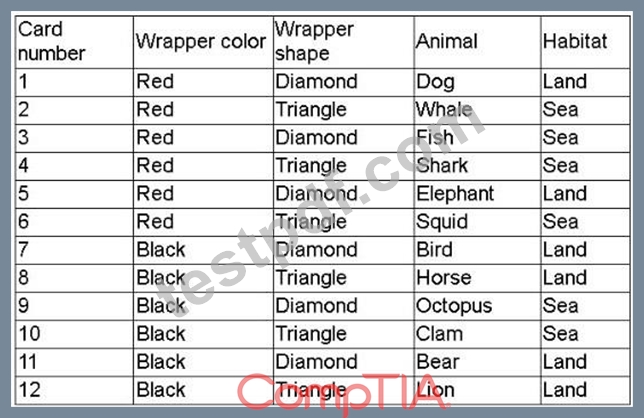
The data scientist is tasked with designing an initial model iteration to predict whether the animal on the card lives in the sea or on land, given the card's features: Wrapper color, Wrapper shape, and Animal.
Which of the following is the best way to accomplish this task?
- A. Association rules
- B. ARIMA
- C. Decision trees
- D. Linear regression
Answer: C
Explanation:
# Decision trees are supervised classification models that can be used to predict a categorical target variable (e.
g., Habitat: Land or Sea) based on input features (e.g., Wrapper color, Wrapper shape, Animal type). They are interpretable, require minimal preprocessing, and are ideal for structured categorical data like this.
Why the other options are incorrect:
* A: ARIMA (AutoRegressive Integrated Moving Average) is used for time-series forecasting, not classification.
* B: Linear regression is used for predicting continuous numeric values, not categorical variables like
"Land" or "Sea".
* C: Association rules (like in market basket analysis) are used to discover relationships or co-occurrence among variables, not to build predictive models.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.1 & 4.2:"Decision trees are powerful classifiers for categorical output variables and allow for interpretable models based on feature splits."
* Machine Learning Textbook, Chapter 6:"Decision trees are ideal for early-stage model prototyping when the output is categorical and the data structure is tabular."
NEW QUESTION # 20
A data scientist wants to digitize historical hard copies of documents. Which of the following is the best method for this task?
- A. Optical character recognition
- B. Word2vec
- C. Semantic segmentation
- D. Latent semantic analysis
Answer: A
Explanation:
# Optical Character Recognition (OCR) is the process of converting scanned images or hard copy text into machine-encoded text. It is the standard technique for digitizing printed or handwritten content.
Why the other options are incorrect:
* A: Word2vec is for generating word embeddings from digital text.
* C: Latent Semantic Analysis analyzes semantic structure of existing digital documents.
* D: Semantic segmentation is used in image processing for pixel-wise classification - not text extraction.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 6.3:"OCR converts scanned physical documents into text files that can be searched, analyzed, or stored digitally."
* Practical NLP Applications, Chapter 2:"OCR is a prerequisite for turning printed or written material into structured data suitable for text analytics."
-
NEW QUESTION # 21
......
If candidates are going to buy DY0-001 test dumps, they may consider the problem of the fund safety. If you are thinking the same question like this, our company will eradicate your worries. We choose the international third party to ensure the safety of the fund. The DY0-001 Test Dumps are effective and conclusive, you just need to use the least time to pass it. I f you choose us, it means you choose the pass.
New DY0-001 Test Topics: https://www.testpdf.com/DY0-001-exam-braindumps.html
- Practice DY0-001 Exam Pdf 🍈 DY0-001 Exam Success 🍙 DY0-001 Latest Exam Format 🤬 Open ▶ www.pass4test.com ◀ enter ➡ DY0-001 ️⬅️ and obtain a free download 😦Valid DY0-001 Test Labs
- DY0-001 Valid Exam Simulator 🥴 DY0-001 Free Learning Cram 🙄 DY0-001 Valid Test Cram 🦊 Easily obtain ✔ DY0-001 ️✔️ for free download through ▶ www.pdfvce.com ◀ 🥵Exam DY0-001 Discount
- DY0-001 Valid Exam Simulator 💨 Valid Braindumps DY0-001 Sheet 🌃 DY0-001 Dumps Cost 🧕 Copy URL ⮆ www.pdfdumps.com ⮄ open and search for ✔ DY0-001 ️✔️ to download for free 📞DY0-001 Valid Test Cram
- DY0-001 training study torrent - DY0-001 guaranteed valid questions - DY0-001 exam test simulator 🍈 Copy URL ➽ www.pdfvce.com 🢪 open and search for [ DY0-001 ] to download for free 🚒DY0-001 Latest Exam Labs
- DY0-001 Associate Level Exam - 100% Pass Quiz DY0-001 CompTIA DataAI Certification Exam First-grade New Test Topics 🚕 Search for ▶ DY0-001 ◀ and easily obtain a free download on ⮆ www.exam4labs.com ⮄ 🏟Exam DY0-001 Discount
- Quiz DY0-001 - The Best CompTIA DataAI Certification Exam Associate Level Exam ⏳ Easily obtain ⏩ DY0-001 ⏪ for free download through ▷ www.pdfvce.com ◁ 🔵DY0-001 Dumps Cost
- Easy to Use www.testkingpass.com CompTIA DY0-001 Practice Questions Formats 🚹 Search for 【 DY0-001 】 and download exam materials for free through “ www.testkingpass.com ” 🔑DY0-001 Exam Success
- DY0-001 training study torrent - DY0-001 guaranteed valid questions - DY0-001 exam test simulator 🥟 Simply search for ➠ DY0-001 🠰 for free download on 【 www.pdfvce.com 】 🥯Valid DY0-001 Test Labs
- High-praised DY0-001 Training Guide: CompTIA DataAI Certification Exam Carries You Outstanding Exam Braindumps - www.examcollectionpass.com 🎢 Search on “ www.examcollectionpass.com ” for 《 DY0-001 》 to obtain exam materials for free download 🐈DY0-001 Reliable Test Cost
- DY0-001 Exam Success ➖ DY0-001 Valid Exam Simulator 💳 DY0-001 Valid Exam Dumps 👭 Enter 【 www.pdfvce.com 】 and search for ➠ DY0-001 🠰 to download for free 🟧DY0-001 Exam Success
- High-praised DY0-001 Training Guide: CompTIA DataAI Certification Exam Carries You Outstanding Exam Braindumps - www.validtorrent.com 🥉 Search for ➤ DY0-001 ⮘ on 【 www.validtorrent.com 】 immediately to obtain a free download 😗DY0-001 Dumps Cost
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, fortunetelleroracle.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BTW, DOWNLOAD part of TestPDF DY0-001 dumps from Cloud Storage: https://drive.google.com/open?id=12tpYN8Yym_dWXCd0IvGrfVd49ox56X5L