DOWNLOAD the newest ExamsReviews Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1KT53HaBi6FXxUZNHXr_Tl9MlSoOBHvzd
For more than ten years, our Data-Engineer-Associate practice engine is the best seller in the market. More importantly, our good Data-Engineer-Associate guide questions and perfect after sale service are approbated by our local and international customers. If you want to pass your practice exam, we believe that our Data-Engineer-Associate Learning Engine will be your indispensable choices. More and more people have bought our Data-Engineer-Associate guide questions in the past years. What are you waiting for? Just rush to buy our Data-Engineer-Associate exam braindumps and become successful!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Operations and Support | 22% | - Manage and troubleshoot data processes
|
| Topic 2: Data Ingestion and Transformation | 34% | - Orchestrate data pipelines
|
| Topic 3: Data Security and Governance | 18% | - Implement data quality checks
|
| Topic 4: Data Store Management | 26% | - Design data models
|
>> Data-Engineer-Associate Exam Questions Answers <<
Our Data-Engineer-Associate practice questions enjoy great popularity in this line. We provide our Data-Engineer-Associate exam braindumps on the superior quality and being confident that they will help you expand your horizon of knowledge of the exam. They are time-tested Data-Engineer-Associate Learning Materials, so they are classic. As well as our after-sales services. And we can always give you the most professional services on our Data-Engineer-Associate training guide.
NEW QUESTION # 185
A company needs to set up a data catalog and metadata management for data sources that run in the AWS Cloud. The company will use the data catalog to maintain the metadata of all the objects that are in a set of data stores. The data stores include structured sources such as Amazon RDS and Amazon Redshift. The data stores also include semistructured sources such as JSON files and .xml files that are stored in Amazon S3.
The company needs a solution that will update the data catalog on a regular basis. The solution also must detect changes to the source metadata.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: B
Explanation:
This solution will meet the requirements with the least operational overhead because it uses the AWS Glue Data Catalog as the central metadata repository for data sources that run in the AWS Cloud. The AWS Glue Data Catalog is a fully managed service that provides a unified view of your data assets across AWS and on- premises data sources. It stores the metadata of your data in tables, partitions, and columns, and enables you to access and query your data using various AWS services, such as Amazon Athena, Amazon EMR, and Amazon Redshift Spectrum. You can use AWS Glue crawlers to connect to multiple data stores, such as Amazon RDS, Amazon Redshift, and Amazon S3, and to update the Data Catalog with metadata changes.
AWS Glue crawlers can automatically discover the schema and partition structure of your data, and create or update the corresponding tables in the Data Catalog. You can schedule the crawlers to run periodically to update the metadata catalog, and configure them to detect changes to the source metadata, such as new columns, tables, or partitions12.
The other options are not optimal for the following reasons:
A. Use Amazon Aurora as the data catalog. Create AWS Lambda functions that will connect to the data catalog. Configure the Lambda functions to gather the metadata information from multiple sources and to update the Aurora data catalog. Schedule the Lambda functions to run periodically. This option is not recommended, as it would require more operational overhead to create and manage an Amazon Aurora database as the data catalog, and to write and maintain AWS Lambda functions to gather and update the metadata information from multiple sources. Moreover, this option would not leverage the benefits of the AWS Glue Data Catalog, such as data cataloging, data transformation, and data governance.
C. Use Amazon DynamoDB as the data catalog. Create AWS Lambda functions that will connect to the data catalog. Configure the Lambda functions to gather the metadata information from multiple sources and to update the DynamoDB data catalog. Schedule the Lambda functions to run periodically. This option is also not recommended, as it would require more operational overhead to create and manage an Amazon DynamoDB table as the data catalog, and to write and maintain AWS Lambda functions to gather and update the metadata information from multiple sources. Moreover, this option would not leverage the benefits of the AWS Glue Data Catalog, such as data cataloging, data transformation, and data governance.
D. Use the AWS Glue Data Catalog as the central metadata repository. Extract the schema for Amazon RDS and Amazon Redshift sources, and build the Data Catalog. Use AWS Glue crawlers for data that is in Amazon S3 to infer the schema and to automatically update the Data Catalog. This option is not optimal, as it would require more manual effort to extract the schema for Amazon RDS and Amazon Redshift sources, and to build the Data Catalog. This option would not take advantage of the AWS Glue crawlers' ability to automatically discover the schema and partition structure of your data from various data sources, and to create or update the corresponding tables in the Data Catalog.
1: AWS Glue Data Catalog
2: AWS Glue Crawlers
Amazon Aurora
AWS Lambda
Amazon DynamoDB
NEW QUESTION # 186
An airline company is collecting metrics about flight activities for analytics. The company is conducting a proof of concept (POC) test to show how analytics can provide insights that the company can use to increase on-time departures.
The POC test uses objects in Amazon S3 that contain the metrics in .csv format. The POC test uses Amazon Athena to query the data. The data is partitioned in the S3 bucket by date.
As the amount of data increases, the company wants to optimize the storage solution to improve query performance.
Which combination of solutions will meet these requirements? (Choose two.)
Answer: A,E
Explanation:
Using an S3 bucket that is in the same AWS Region where the company runs Athena queries can improve query performance by reducing data transfer latency and costs. Preprocessing the .csv data to Apache Parquet format can also improve query performance by enabling columnar storage, compression, and partitioning, which can reduce the amount of data scanned and fetched by the query. These solutions can optimize the storage solution for the POC test without requiring much effort or changes to the existing data pipeline. The other solutions are not optimal or relevant for this requirement. Adding a randomized string to the beginning of the keys in Amazon S3 can improve the throughput across partitions, but it can also make the data harder to query and manage. Using an S3 bucket that is in the same account that uses Athena to query the data does not have any significant impact on query performance, as long as the proper permissions are granted.
Preprocessing the .csv data to JSON format does not offer any benefits over the .csv format, as both are row- based and verbose formats that require more data scanning and fetching than columnar formats like Parquet.
References:
* Best Practices When Using Athena with AWS Glue
* Optimizing Amazon S3 Performance
* AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide
NEW QUESTION # 187
A data engineer has a one-time task to read data from objects that are in Apache Parquet format in an Amazon S3 bucket. The data engineer needs to query only one column of the data.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: A
Explanation:
Option B is the best solution to meet the requirements with the least operational overhead because S3 Select is a feature that allows you to retrieve only a subset of data from an S3 object by using simple SQL expressions. S3 Select works on objects stored in CSV, JSON, or Parquet format. By using S3 Select, you can avoid the need to download and process the entire S3 object, which reduces the amount of data transferred and the computation time. S3 Select is also easy to use and does not require any additional services or resources.
Option A is not a good solution because it involves writing custom code and configuring an AWS Lambda function to load data from the S3 bucket into a pandas dataframe and query the required column. This option adds complexity and latency to the data retrieval process and requires additional resources and configuration. Moreover, AWS Lambda has limitations on the execution time, memory, and concurrency, which may affect the performance and reliability of the data retrieval process.
Option C is not a good solution because it involves creating and running an AWS Glue DataBrew project to consume the S3 objects and query the required column. AWS Glue DataBrew is a visual data preparation tool that allows you to clean, normalize, and transform data without writing code. However, in this scenario, the data is already in Parquet format, which is a columnar storage format that is optimized for analytics. Therefore, there is no need to use AWS Glue DataBrew to prepare the data. Moreover, AWS Glue DataBrew adds extra time and cost to the data retrieval process and requires additional resources and configuration.
Option D is not a good solution because it involves running an AWS Glue crawler on the S3 objects and using a SQL SELECT statement in Amazon Athena to query the required column. An AWS Glue crawler is a service that can scan data sources and create metadata tables in the AWS Glue Data Catalog. The Data Catalog is a central repository that stores information about the data sources, such as schema, format, and location. Amazon Athena is a serverless interactive query service that allows you to analyze data in S3 using standard SQL. However, in this scenario, the schema and format of the data are already known and fixed, so there is no need to run a crawler to discover them. Moreover, running a crawler and using Amazon Athena adds extra time and cost to the data retrieval process and requires additional services and configuration.
Reference:
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide
S3 Select and Glacier Select - Amazon Simple Storage Service
AWS Lambda - FAQs
What Is AWS Glue DataBrew? - AWS Glue DataBrew
Populating the AWS Glue Data Catalog - AWS Glue
What is Amazon Athena? - Amazon Athena
NEW QUESTION # 188
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?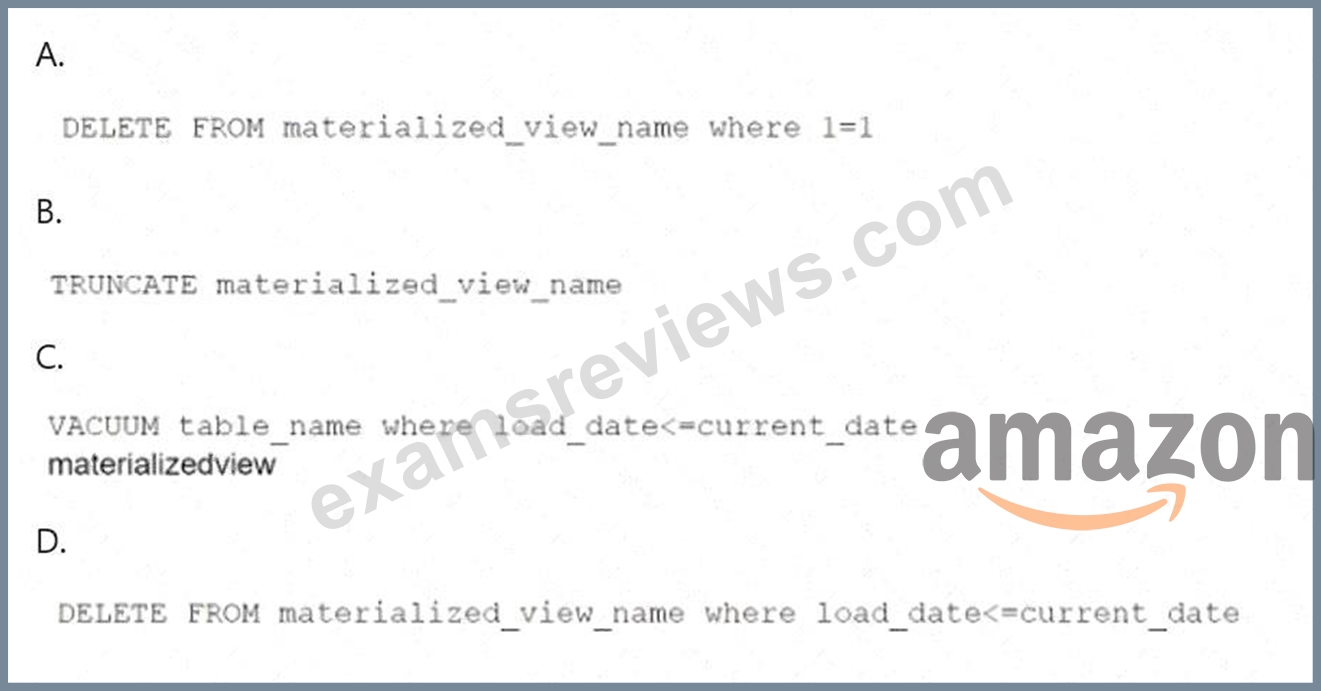
Answer: C
Explanation:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
Option A: DELETE FROM materialized_view_name WHERE 1=1;This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
References:
Amazon Redshift Materialized Views Documentation
Deleting Data from Redshift
NEW QUESTION # 189
A company needs to use an AWS Glue PySpark job to read specific data from an Amazon DynamoDB table.
The company knows the partition key values for the required records. The existing processing logic of the AWS Glue PySpark job requires the data to be in DynamicFrame format. The company needs a solution to ensure that the job reads only the specified data.
Which solution will meet this requirement with the MINIMUM number of read capacity units (RCUs)?
Answer: B
Explanation:
Comprehensive and Detailed Explanation (150-250 words)
Amazon DynamoDB is optimized for Query operations, which retrieve items efficiently using the partition key and optionally the sort key. Queries consume significantly fewer RCUs than Scan operations because only matching partitions are read.
By performing a Query using the partition key in the key condition expression, the AWS Glue job reads only the required items directly from DynamoDB. This minimizes the number of read capacity units consumed and avoids unnecessary reads.
Using a Scan operation, even when followed by filtering in a DynamicFrame, consumes RCUs for the entire table or index and is highly inefficient. Using only the sort key in a query is invalid without the partition key and would not meet DynamoDB query requirements. The Glue DynamoDB connector filter option still performs a scan under the hood and does not minimize RCUs.
The queried data can be directly loaded into a DynamicFrame, satisfying the existing processing logic requirement without additional transformations.
Therefore, Option D provides the most efficient and cost-effective solution.
NEW QUESTION # 190
......
ExamsReviews is determined to give hand to the candidates who want to pass their Data-Engineer-Associate exam smoothly and with ease by their first try. Our professional experts have compiled the most visual version: the PDF version of our Data-Engineer-Associate exam questions, which owns the advantage of convenient to be printed on the paper for it shows the entirety. In such a way, you can overcome your lack of confidence as well since you can have an overall look. The PDF version of our Data-Engineer-Associate Study Guide will provide you the easiest, the most flexible and leisure study experience to success.
New Data-Engineer-Associate Exam Objectives: https://www.examsreviews.com/Data-Engineer-Associate-pass4sure-exam-review.html
P.S. Free 2026 Amazon Data-Engineer-Associate dumps are available on Google Drive shared by ExamsReviews: https://drive.google.com/open?id=1KT53HaBi6FXxUZNHXr_Tl9MlSoOBHvzd