2026 Latest PrepAwayExam DP-700 PDF Dumps and DP-700 Exam Engine Free Share: https://drive.google.com/open?id=1NFpn-Fp31EWyevht9icQuNkJBr72ItgA
In order to facilitate the wide variety of users' needs the DP-700 study guide have developed three models with the highest application rate in the present - PDF, software and online. No matter you are a student, a office staff or even a housewife, you can always find your most situable way to study our DP-700 Exam Q&A. Generally speaking, these three versions of our DP-700 learning guide can support study on paper, computer and all kinds of eletronic devices. They are quite convenient.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement and manage an analytics solution | 30–35% | - Configure workspace settings
|
| Topic 2: Ingest and transform data | 30–35% | - Design and implement data loading patterns
|
| Topic 3: Monitor and optimize an analytics solution | 30–35% | - Troubleshoot issues
|
We promise during the process of installment and payment of our Implementing Data Engineering Solutions Using Microsoft Fabric prep torrent, the security of your computer or cellphone can be guaranteed, which means that you will be not afraid of virus intrusion and personal information leakage. Besides we have the right to protect your email address and not release your details to the 3rd parties. Moreover if you are not willing to continue our DP-700 Test Braindumps service, we would delete all your information instantly without doubt. The main reason why we try our best to protect our customers’ privacy is that we put a high value on the reliable relationship and mutual reliance to create a sustainable business pattern.
NEW QUESTION # 18
You have the development groups shown in the following table.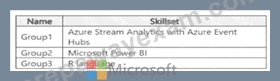
You have the projects shown in the following table.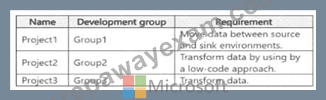
You need to recommend which Fabric item to use based on each development group ' s skillset The solution must meet the project requirements and minimize development effort What should you recommend for each group? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.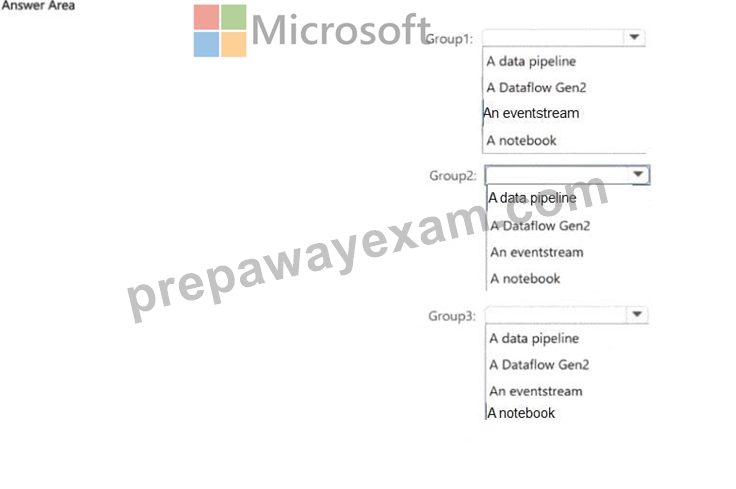
Answer:
Explanation: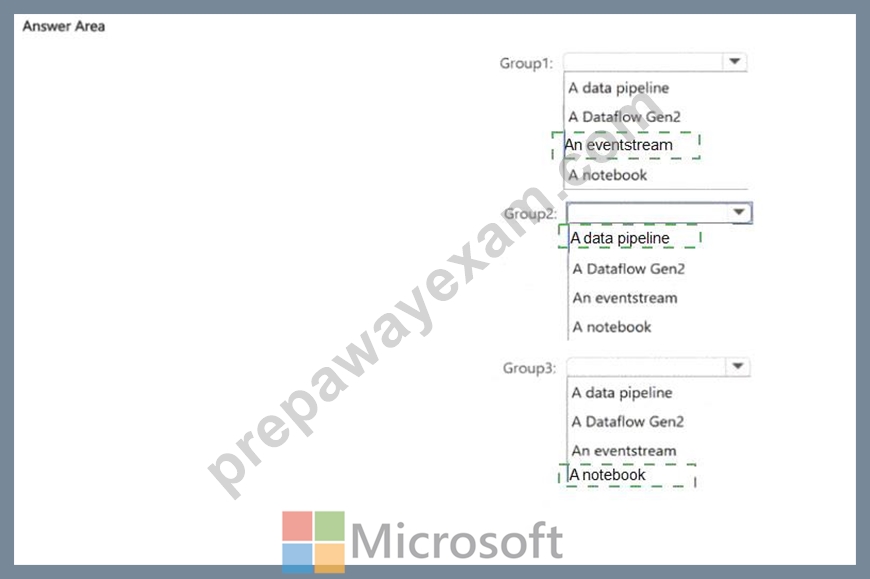
Explanation: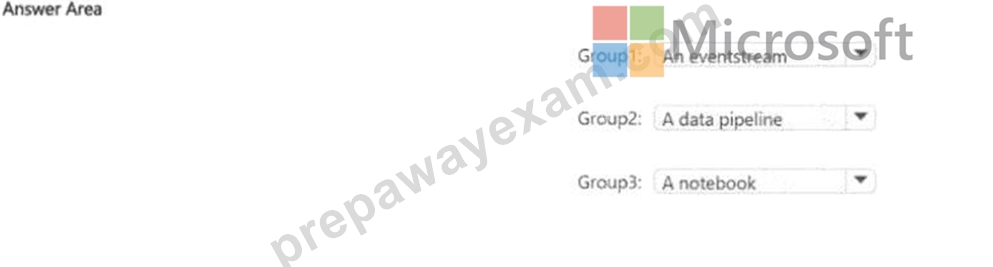
NEW QUESTION # 19
You have a Fabric workspace that contains a lakehouse named Lakehouse1. Data is ingested into Lakehouse1 as one flat table. The table contains the following columns.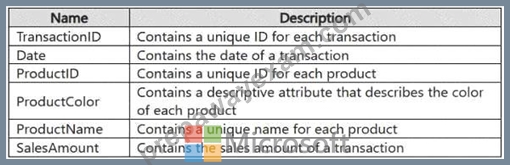
You plan to load the data into a dimensional model and implement a star schema. From the original flat table, you create two tables named FactSales and DimProduct. You will track changes in DimProduct.
You need to prepare the data.
Which three columns should you include in the DimProduct table? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: C,D,F
Explanation:
In a star schema, the DimProduct table serves as a dimension table that contains descriptive attributes about products. It will provide context for the FactSales table, which contains transactional data. The following columns should be included in the DimProduct table:
* ProductName: The ProductName is an important descriptive attribute of the product, which is needed for analysis and reporting in a dimensional model.
* ProductColor: ProductColor is another descriptive attribute of the product. In a star schema, it makes sense to include attributes like color in the dimension table to help categorize products in the analysis.
* ProductID: ProductID is the primary key for the DimProduct table, which will be used to join the FactSales table to the product dimension. It's essential for uniquely identifying each product in the model.
NEW QUESTION # 20
You need to recommend a Fabric streaming solution that will use the sources shown in the following table.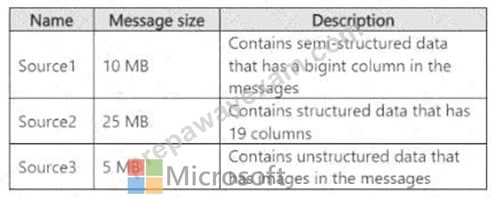
The solution must minimize development effort.
What should you include in the recommendation for each source? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.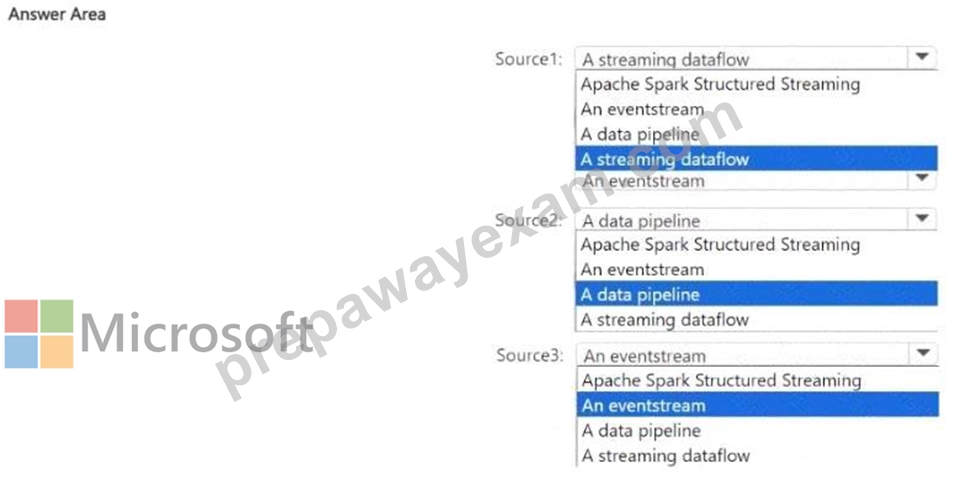
Answer:
Explanation: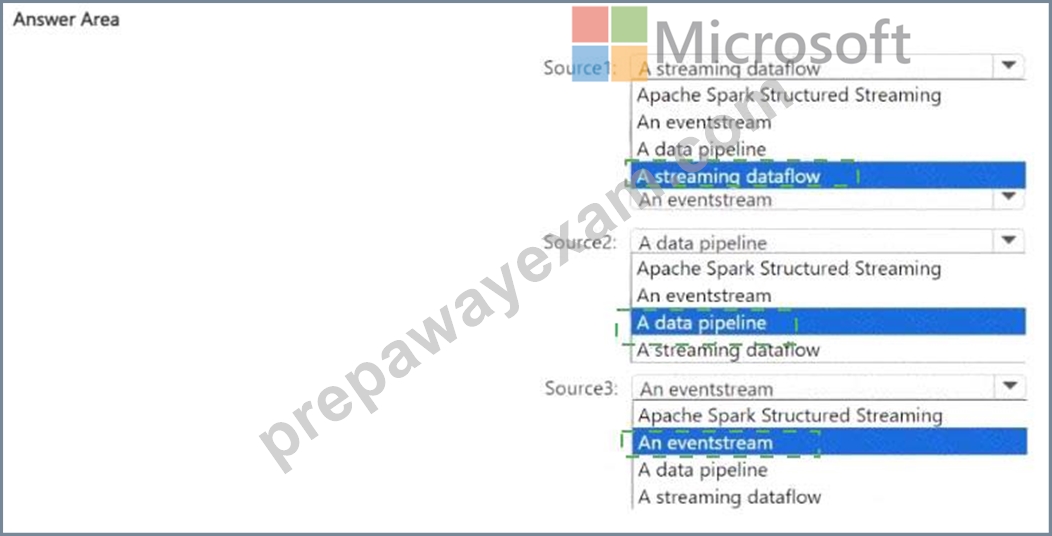
Explanation: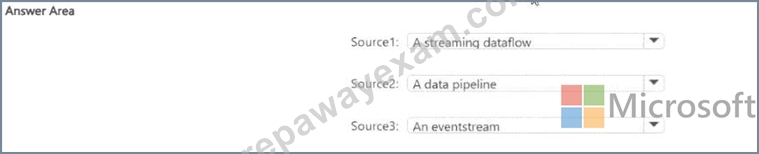
NEW QUESTION # 21
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric eventstream that loads data into a table named Bike_Location in a KQL database. The table contains the following columns:
BikepointID
Street
Neighbourhood
No_Bikes
No_Empty_Docks
Timestamp
You need to apply transformation and filter logic to prepare the data for consumption. The solution must return data for a neighbourhood named Sands End when No_Bikes is at least 15. The results must be ordered by No_Bikes in ascending order.
Solution: You use the following code segment: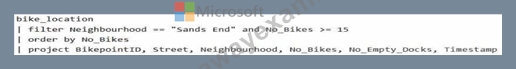
Does this meet the goal?
Answer: A
Explanation:
This code does not meet the goal because it uses order by, which is not valid in KQL. The correct term in KQL is sort by.
Correct code should look like: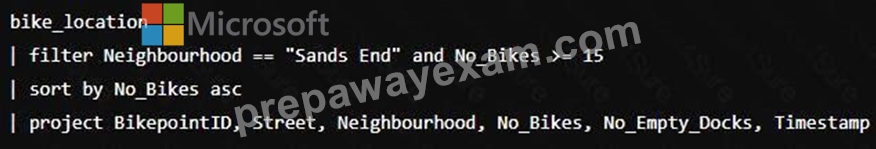
NEW QUESTION # 22
You have a Fabric F32 capacity that contains a workspace. The workspace contains a warehouse named DW1 that is modelled by using MD5 hash surrogate keys.
DW1 contains a single fact table that has grown from 200 million rows to 500 million rows during the past year.
You have Microsoft Power BI reports that are based on Direct Lake. The reports show year-over-year values.
Users report that the performance of some of the reports has degraded over time and some visuals show errors.
You need to resolve the performance issues. The solution must meet the following requirements:
Provide the best query performance.
Minimize operational costs.
Which should you do?
Answer: A
Explanation:
In this case, the key issue causing performance degradation likely stems from the use of MD5 hash surrogate keys. MD5 hashes are 128-bit values, which can be inefficient for large datasets like the 500 million rows in your fact table. Using a more efficient data type for surrogate keys (such as integer or bigint) would reduce the storage and processing overhead, leading to better query performance. This approach will improve performance while minimizing operational costs because it reduces the complexity of querying and indexing, as smaller data types are generally faster and more efficient to process.
NEW QUESTION # 23
......
Our DP-700 exam questions are often in short supply. Every day, large numbers of people crowd into our website to browser our DP-700 study materials. Then they will purchase various kinds of our DP-700 learning braindumps at once. How diligent they are! As you can see, our products are absolutely popular in the market. And the pass rate of our DP-700 training guide is high as 98% to 100%. Just buy it and you will love it!
DP-700 Free Sample: https://www.prepawayexam.com/Microsoft/braindumps.DP-700.ete.file.html
P.S. Free 2026 Microsoft DP-700 dumps are available on Google Drive shared by PrepAwayExam: https://drive.google.com/open?id=1NFpn-Fp31EWyevht9icQuNkJBr72ItgA