DOWNLOAD the newest Exam4PDF ACD-301 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1zqK0MWVJIt4gZ_01KbiCbZHig7zi2EET
Some of our customers are white-collar workers with no time to waste, and need a Appian certification urgently to get their promotions, meanwhile the other customers might aim at improving their skills. So we try to meet different requirements by setting different versions of our ACD-301 question and answers. The special one is online ACD-301 engine version. As an online tool, it is convenient and easy to study, supports all Web Browsers and system including Windows, Mac, Android, iOS and so on. You can apply this version of ACD-301 exam questions on all eletric devices.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Management | 25% | - Design secure and efficient data models - Leverage Data Fabric, data types, and migration strategies - Troubleshoot complex data and database performance issues |
| Topic 2: Application Design and Development | 25% | - Apply best practices for multi-application development - Evaluate how Appian meets user requirements - Design applications with reusability and consistency |
| Topic 3: Platform & Solution Architecture | 15% | - Manage deployments and environment configurations - Make architecture decisions for maintainability and scalability - Understand enterprise platform architecture |
| Topic 4: Extending Appian & Integrations | 15% | - Design advanced APIs and connected systems - Troubleshoot integration and API errors - Implement authentication and secure integrations |
| Topic 5: Scalability and Performance Design | 20% | - Design and build high-performance components - Plan and execute load testing and monitoring - Troubleshoot application-level performance bottlenecks |
When you buy things online, you must ensure the security of online purchasing, otherwise your rights will be harmed. Our ACD-301 study tool purchase channel is safe, we invite experts to design a secure purchasing process for our ACD-301 qualification test, and the performance of purchasing safety has been certified, so personal information of our clients will be fully protected. All customers can feel comfortable when they choose to buy our ACD-301 Study Tool. We have specialized software to prevent the leakage of your information and we will never sell your personal information because trust is the foundation of cooperation between both parties. A good reputation is the driving force for our continued development. Our company has absolute credit, so you can rest assured to buy our ACD-301 test guides.
NEW QUESTION # 11
Users must be able to navigate throughout the application while maintaining complete visibility in the application structure and easily navigate to previous locations. Which Appian Interface Pattern would you recommend?
Answer: D
Explanation:
Comprehensive and Detailed In-Depth Explanation:
The requirement emphasizes navigation with complete visibility of the application structure and the ability to return to previous locations easily. The Breadcrumbs pattern is specifically designed to meet this need. According to Appian's design best practices, the Breadcrumbs pattern provides a visual trail of the user's navigation path, showing the hierarchy of pages or sections within the application. This allows users to understand their current location relative to the overall structure and quickly navigate back to previous levels by clicking on the breadcrumb links.
Option A (Billboards as Cards): This pattern is useful for presenting high-level options or choices on a homepage in a visually appealing way. However, it does not address navigation visibility or the ability to return to previous locations, making it irrelevant to the requirement.
Option B (Activity History): This pattern tracks and displays a log of activities or actions within the application, typically for auditing or monitoring purposes. It does not enhance navigation or provide visibility into the application structure.
Option C (Drilldown Report): This pattern allows users to explore detailed data within reports by drilling into specific records. While it supports navigation within data, it is not designed for general application navigation or maintaining structural visibility.
Option D (Breadcrumbs): This is the correct choice as it directly aligns with the requirement. Per Appian's Interface Patterns documentation, Breadcrumbs improve usability by showing a hierarchical path (e.g., Home > Section > Subsection) and enabling backtracking, fulfilling both visibility and navigation needs.
NEW QUESTION # 12
An existing integration is implemented in Appian. Its role is to send data for the main case and its related objects in a complex JSON to a REST API, to insert new information into an existing application. This integration was working well for a while. However, the customer highlighted one specific scenario where the integration failed in Production, and the API responded with a 500 Internal Error code. The project is in Post-Production Maintenance, and the customer needs your assistance. Which three steps should you take to troubleshoot the issue?
Answer: A,C,E
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer in a Post-Production Maintenance phase, troubleshooting a failed integration (HTTP 500 Internal Server Error) requires a systematic approach to isolate the root cause-whether it's Appian-side, API-side, or environmental. A 500 error typically indicates an issue on the server (API) side, but the developer must confirm Appian's contribution and collaborate with the customer. The goal is to select three steps that efficiently diagnose the specific scenario while adhering to Appian's best practices. Let's evaluate each option:
A . Send the same payload to the test API to ensure the issue is not related to the API environment:
This is a critical step. Replicating the failure by sending the exact payload (from the failed Production call) to a test API environment helps determine if the issue is environment-specific (e.g., Production-only configuration) or inherent to the payload/API logic. Appian's Integration troubleshooting guidelines recommend testing in a non-Production environment first to isolate variables. If the test API succeeds, the Production environment or API state is implicated; if it fails, the payload or API logic is suspect. This step leverages Appian's Integration object logging (e.g., request/response capture) and is a standard diagnostic practice.
B . Send a test case to the Production API to ensure the service is still up and running:
While verifying Production API availability is useful, sending an arbitrary test case risks further Production disruption during maintenance and may not replicate the specific scenario. A generic test might succeed (e.g., with simpler data), masking the issue tied to the complex JSON. Appian's Post-Production guidelines discourage unnecessary Production interactions unless replicating the exact failure is controlled and justified. This step is less precise than analyzing existing behavior (C) and is not among the top three priorities.
C . Analyze the behavior of subsequent calls to the Production API to ensure there is no global issue, and ask the customer to analyze the API logs to understand the nature of the issue:
This is essential. Reviewing subsequent Production calls (via Appian's Integration logs or monitoring tools) checks if the 500 error is isolated or systemic (e.g., API outage). Since Appian can't access API server logs, collaborating with the customer to review their logs is critical for a 500 error, which often stems from server-side exceptions (e.g., unhandled data). Appian Lead Developer training emphasizes partnership with API owners and using Appian's Process History or Application Monitoring to correlate failures-making this a key troubleshooting step.
D . Obtain the JSON sent to the API and validate that there is no difference between the expected JSON format and the sent one:
This is a foundational step. The complex JSON payload is central to the integration, and a 500 error could result from malformed data (e.g., missing fields, invalid types) that the API can't process. In Appian, you can retrieve the sent JSON from the Integration object's execution logs (if enabled) or Process Instance details. Comparing it against the API's documented schema (e.g., via Postman or API specs) ensures Appian's output aligns with expectations. Appian's documentation stresses validating payloads as a first-line check for integration failures, especially in specific scenarios.
E . Ensure there were no network issues when the integration was sent:
While network issues (e.g., timeouts, DNS failures) can cause integration errors, a 500 Internal Server Error indicates the request reached the API and triggered a server-side failure-not a network issue (which typically yields 503 or timeout errors). Appian's Connected System logs can confirm HTTP status codes, and network checks (e.g., via IT teams) are secondary unless connectivity is suspected. This step is less relevant to the 500 error and lower priority than A, C, and D.
Conclusion: The three best steps are A (test API with same payload), C (analyze subsequent calls and customer logs), and D (validate JSON payload). These steps systematically isolate the issue-testing Appian's output (D), ruling out environment-specific problems (A), and leveraging customer insights into the API failure (C). This aligns with Appian's Post-Production Maintenance strategies: replicate safely, analyze logs, and validate data.
Appian Documentation: "Troubleshooting Integrations" (Integration Object Logging and Debugging).
Appian Lead Developer Certification: Integration Module (Post-Production Troubleshooting).
Appian Best Practices: "Handling REST API Errors in Appian" (500 Error Diagnostics).
NEW QUESTION # 13
Your application contains a process model that is scheduled to run daily at a certain time, which kicks off a user input task to a specified user on the 1st time zone for morning data collection. The time zone is set to the (default) pm!timezone. In this situation, what does the pm!timezone reflect?
Answer: A
Explanation:
Comprehensive and Detailed In-Depth Explanation:
In Appian, the pm!timezone variable is a process variable automatically available in process models, reflecting the time zone context for scheduled or time-based operations. Understanding its behavior is critical for scheduling tasks accurately, especially in scenarios like this where a process runs daily and assigns a user input task.
Option C (The default time zone for the environment as specified in the Administration Console):
This is the correct answer. Per Appian's Process Model documentation, when a process model uses pm!timezone and no custom time zone is explicitly set, it defaults to the environment's time zone configured in the Administration Console (under System > Time Zone settings). For scheduled processes, such as one running "daily at a certain time," Appian uses this default time zone to determine when the process triggers. In this case, the task assignment occurs based on the schedule, and pm!timezone reflects the environment's setting, not the user's location.
Option A (The time zone of the server where Appian is installed): This is incorrect. While the server's time zone might influence underlying system operations, Appian abstracts this through the Administration Console's time zone setting. The pm!timezone variable aligns with the configured environment time zone, not the raw server setting.
Option B (The time zone of the user who most recently published the process model): This is irrelevant. Publishing a process model does not tie pm!timezone to the publisher's time zone. Appian's scheduling is system-driven, not user-driven in this context.
Option D (The time zone of the user who is completing the input task): This is also incorrect. While Appian can adjust task display times in the user interface to the assigned user's time zone (based on their profile settings), the pm!timezone in the process model reflects the environment's default time zone for scheduling purposes, not the assignee's.
For example, if the Administration Console is set to EST (Eastern Standard Time), the process will trigger daily at the specified time in EST, regardless of the assigned user's location. The "1st time zone" phrasing in the question appears to be a typo or miscommunication, but it doesn't change the fact that pm!timezone defaults to the environment setting.
NEW QUESTION # 14
You are deciding the appropriate process model data management strategy.
For each requirement. match the appropriate strategies to implement. Each strategy will be used once.
Note: To change your responses, you may deselect your response by clicking the blank space at the top of the selection list.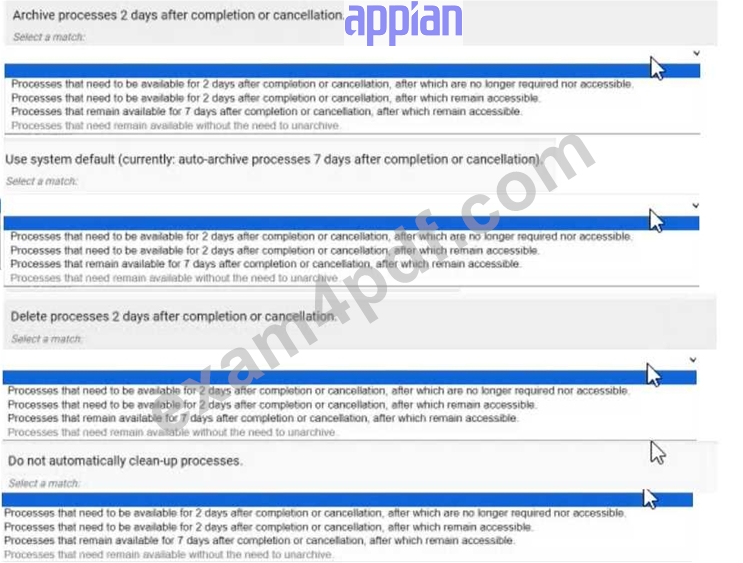
Answer:
Explanation: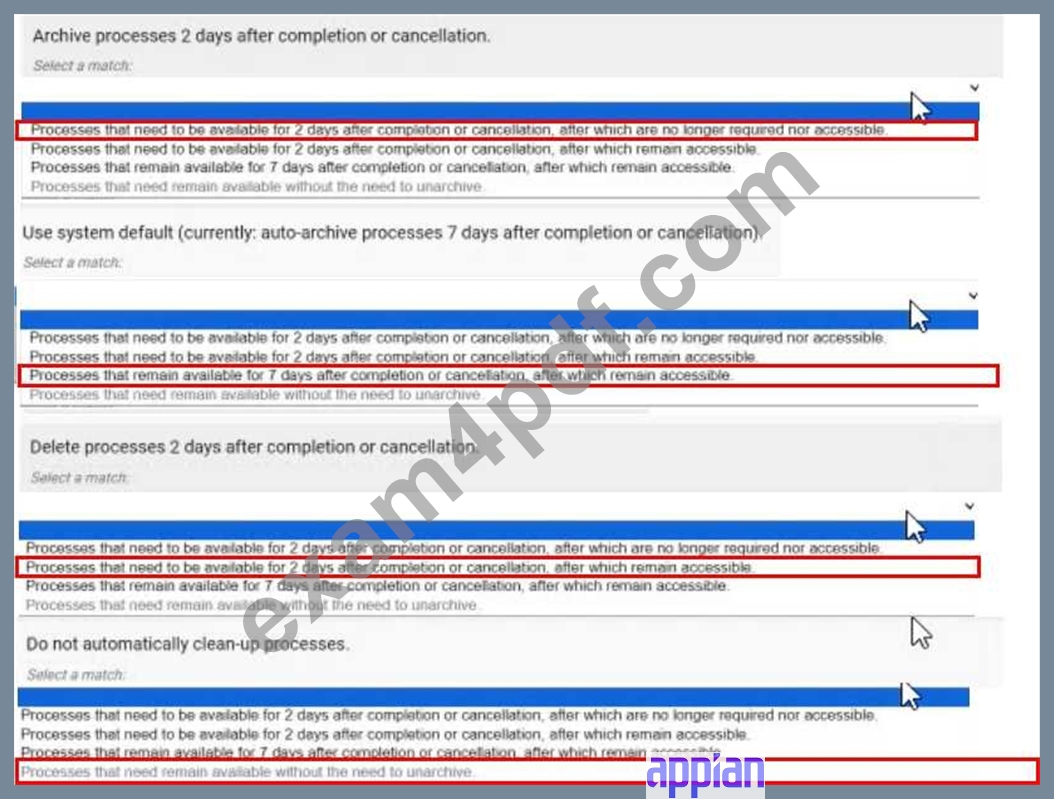
NEW QUESTION # 15
You are developing a case management application to manage support cases for a large set of sites. One of the tabs in this application s site Is a record grid of cases, along with Information about the site corresponding to that case. Users must be able to filter cases by priority level and status.
You decide to create a view as the source of your entity-backed record, which joins the separate case/site tables (as depicted in the following Image).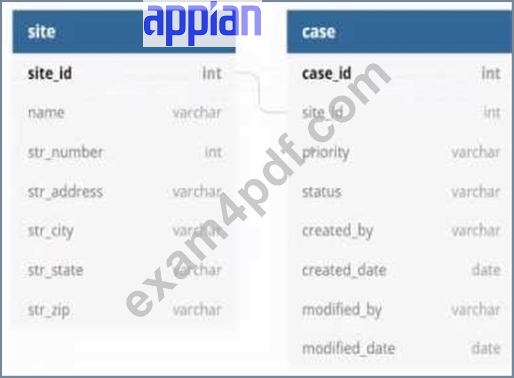
Which three column should be indexed?
Answer: B,D,E
Explanation:
Indexing columns can improve the performance of queries that use those columns in filters, joins, or order by clauses. In this case, the columns that should be indexed are site_id, status, and priority, because they are used for filtering or joining the tables. Site_id is used to join the case and site tables, so indexing it will speed up the join operation. Status and priority are used to filter the cases by the user's input, so indexing them will reduce the number of rows that need to be scanned. Name, modified_date, and case_id do not need to be indexed, because they are not used for filtering or joining. Name and modified_date are only used for displaying information in the record grid, and case_id is only used as a unique identifier for each record. Verified Appian Records Tutorial,Appian Best Practices As an Appian Lead Developer, optimizing a database view for an entity-backed record grid requires indexing columns frequently used in queries, particularly for filtering and joining. The scenario involves a record grid displaying cases with site information, filtered by "priority level" and "status," and joined via the site_id foreign key. The image shows two tables (site and case) with a relationship via site_id. Let's evaluate each column based on Appian's performance best practices and query patterns:
A . site_id:This is a primary key in the site table and a foreign key in the case table, used for joining the tables in the view. Indexing site_id in the case table (and ensuring it's indexed in site as a PK) optimizes JOIN operations, reducing query execution time for the record grid. Appian's documentation recommends indexing foreign keys in large datasets to improve query performance, especially for entity-backed records. This is critical for the join and must be included.
B . status:Users filter cases by "status" (a varchar column in the case table). Indexing status speeds up filtering queries (e.g., WHERE status = 'Open') in the record grid, particularly with large datasets. Appian emphasizes indexing columns used in WHERE clauses or filters to enhance performance, making this a key column for optimization. Since status is a common filter, it's essential.
C . name:This is a varchar column in the site table, likely used for display (e.g., site name in the grid). However, the scenario doesn't mention filtering or sorting by name, and it's not part of the join or required filters. Indexing name could improve searches if used, but it's not a priority given the focus on priority and status filters. Appian advises indexing only frequently queried or filtered columns to avoid unnecessary overhead, so this isn't necessary here.
D . modified_date:This is a date column in the case table, tracking when cases were last updated. While useful for sorting or historical queries, the scenario doesn't specify filtering or sorting by modified_date in the record grid. Indexing it could help if used, but it's not critical for the current requirements. Appian's performance guidelines prioritize indexing columns in active filters, making this lower priority than site_id, status, and priority.
E . priority:Users filter cases by "priority level" (a varchar column in the case table). Indexing priority optimizes filtering queries (e.g., WHERE priority = 'High') in the record grid, similar to status. Appian's documentation highlights indexing columns used in WHERE clauses for entity-backed records, especially with large datasets. Since priority is a specified filter, it's essential to include.
F . case_id:This is the primary key in the case table, already indexed by default (as PKs are automatically indexed in most databases). Indexing it again is redundant and unnecessary, as Appian's Data Store configuration relies on PKs for unique identification but doesn't require additional indexing for performance in this context. The focus is on join and filter columns, not the PK itself.
Conclusion: The three columns to index are A (site_id), B (status), and E (priority). These optimize the JOIN (site_id) and filter performance (status, priority) for the record grid, aligning with Appian's recommendations for entity-backed records and large datasets. Indexing these columns ensures efficient querying for user filters, critical for the application's performance.
Appian Documentation: "Performance Best Practices for Data Stores" (Indexing Strategies).
Appian Lead Developer Certification: Data Management Module (Optimizing Entity-Backed Records).
Appian Best Practices: "Working with Large Data Volumes" (Indexing for Query Performance).
NEW QUESTION # 16
......
The passing rate of our ACD-301 study materials is 99% and the hit rate is also high. Our study materials are selected strictly based on the real ACD-301 exam. Our expert team guarantees that each answer and question is useful and valuable. We also update frequently to guarantee that the client can get more learning ACD-301 resources and follow the trend of the times. So if you use our study materials you will pass the test with high success probability.
Test ACD-301 Dates: https://www.exam4pdf.com/ACD-301-dumps-torrent.html
DOWNLOAD the newest Exam4PDF ACD-301 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1zqK0MWVJIt4gZ_01KbiCbZHig7zi2EET