P.S. Free & New AI-200 dumps are available on Google Drive shared by RealExamFree: https://drive.google.com/open?id=13IoBbtlLTJ_Aa68QnwwBaJQse8OAZm4a
Our AI-200 exam torrent is compiled by first-rank experts with a good command of professional knowledge, and our experts adept at this exam practice materials area over ten years' long, so they are terrible clever about this thing. They exert great effort to boost the quality and accuracy of our AI-200 study tools and is willing to work hard as well as willing to do their part in this area. The wording is fully approved in our AI-200 Exam Guide. They handpicked what the AI-200 exam torrent usually tests in exam recent years and devoted their knowledge accumulated into these AI-200 study tools. Besides, they keep the quality and content according to the trend of the AI-200 practice exam. As approved AI-200 exam guide from professional experts their quality is unquestionable.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
| Topic 2: Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
| Topic 3: Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
| Topic 4: Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
To be successful in a professional exam like the Microsoft AI-200 exam, you must know the criteria to pass it. You should know the type of Developing AI Cloud Solutions on Azure questions, the pattern of the Developing AI Cloud Solutions on Azure exam, and the time limit to complete the AI-200 Exam. All these factors help you pass the Microsoft AI-200 exam. RealExamFree is your reliable partner in getting your AI-200 certification. The Microsoft AI-200 exam dumps help you achieve your professional goals.
NEW QUESTION # 66
You optimize an AI inference API that uses Redis caching.
You must reduce the risk of serving outdated data while minimizing cache management overhead.
You need to implement the caching strategy that satisfies the requirements.
What should you do?
Answer: A
Explanation:
Trigger invalidation when source data changes is the best action.
Data Freshness: This is a proactive cache-aside or write-through approach. By explicitly deleting or updating the specific Redis key when the underlying database or model data changes, you completely eliminate the risk of serving stale data.
Low Overhead: It keeps cache management overhead minimal because invalidation logic is execution-dependent (event-driven). Instead of constantly updating expirations or relying on heavy computing logic, you only trigger an action when a write/change event occurs.
Incorrect:
[not B]
Set eviction policy to allkeys-lru:
This policy is a memory management feature, not a data-freshness strategy. It only deletes the Least Recently Used (LRU) keys when your Redis instance runs out of RAM. If memory usage is stable, outdated data will sit in the cache forever, posing a major risk of serving stale inferences.
[not D]
Reset expiration on each read (Sliding TTL):
This actively increases the risk of serving outdated data. If a specific AI response is highly popular and read continuously, its expiration window will extend indefinitely. The data remains stuck in the cache even if the source data undergoes critical updates.
Reference:
https://oneuptime.com/blog/post/2026-01-30-llm-caching-strategies/view
NEW QUESTION # 67
Hotspot Question
You are developing several microservices to run on Azure Container Apps.
You need to monitor and diagnose the microservices.
Which features should you use? To answer, select the appropriate feature in the answer area.
NOTE: Each correct selection is worth one point.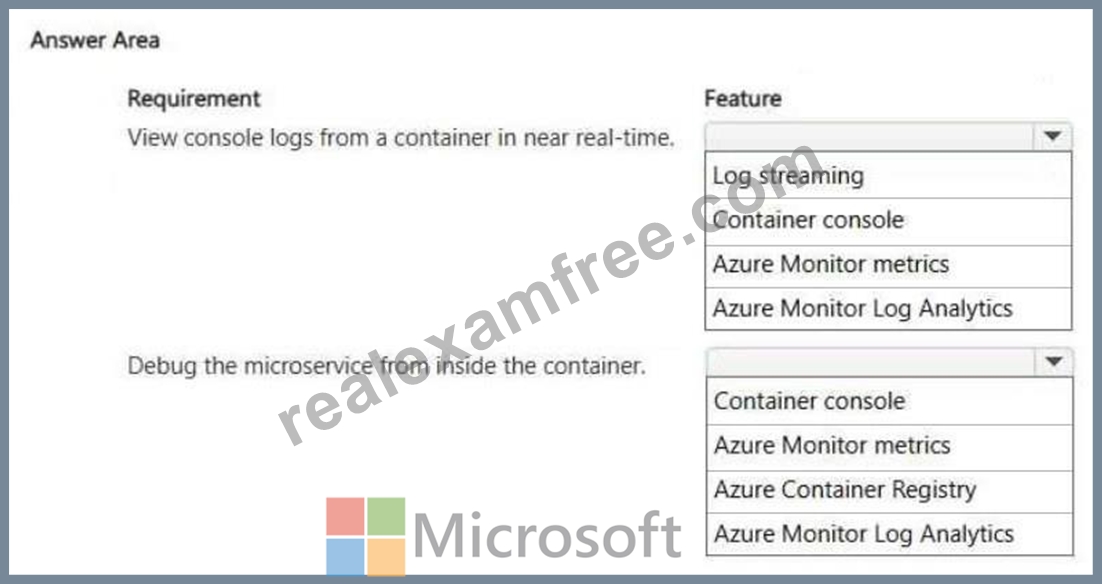
Answer:
Explanation: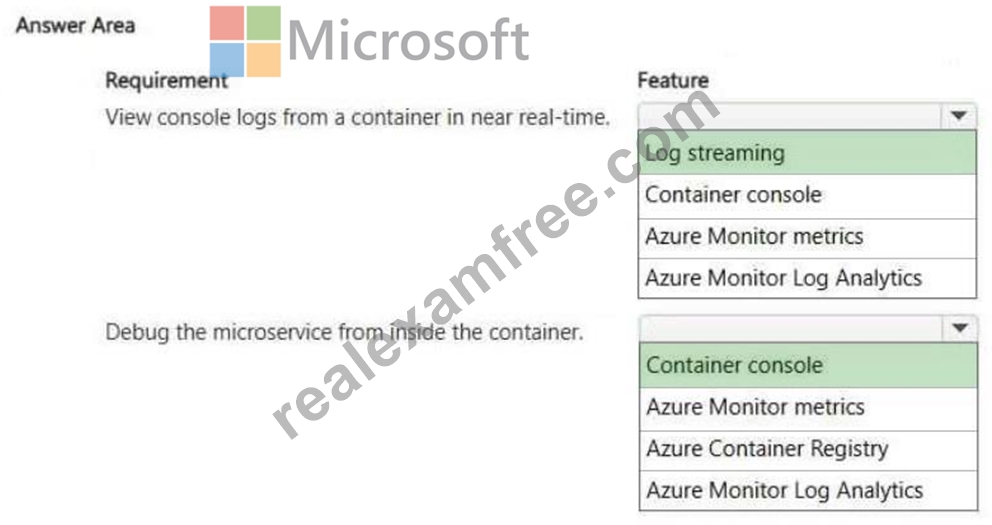
Explanation:
Box 1: Log streaming
To view console logs from an Azure Container App in near real-time, you should use the Log stream feature.
How to Access Log Stream
Navigate to your container app in the Azure portal.
Under the Monitoring section of the sidebar menu, select Log stream.
Set the log type to Console to instantly stream your application's stdout and stderr streams.
Box 2: Container console
To debug your microservice from inside the container, you should use the Container console feature.
Key Features for Debugging and Monitoring
Container console: This feature allows you to connect directly to the Linux console/shell inside your running container instance. You can use it to execute commands, inspect files, and troubleshoot the container's environment in real-time.
Log stream: This tool is used alongside the console to view streaming system and console logs from your container in near real-time.
Azure Monitor Logs: Used for querying and analyzing historical application and system logs over longer periods.
Reference:
https://learn.microsoft.com/en-us/azure/container-apps/observability
NEW QUESTION # 68
You are troubleshooting a production Azure OpenAI service that is experiencing intermittent connectivity issues. All telemetry is sent to a Log Analytics workspace.
You must write a KQL query that analyzes the AppRequests table. The query must filter for requests that occurred within the last 30 minutes and have a failed status.
The final output must display the total number of failures for each unique operation.
You need to select the KQL operators required to filter the time range and aggregate the failure counts.
Which two operators should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,D
Explanation:
You should use both the where and summarize operators to achieve this. The where operator filters the data by time and status, while the summarize operator aggregates the failure counts by operation.
Example code:
AppRequests
| where TimeGenerated > ago(30m)
| where Success == false
| summarize FailureCount = count() by OperationName
Reference:
https://digitalmaterial.ch/blog/query-data-from-the-application-insights-workspace-with-the-rest-api/
NEW QUESTION # 69
A Python API retrieves a document from Azure Database for PostgreSQL by using a SQL statement. The API accepts the document ID from user input. The current implementation inserts the document ID directly into the SQL statement.
You need to secure the SQL statement execution by using a parameterized query. You must minimize the possibility of SQL injection.
How should you update the implementation to execute the SQL statement safely? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. you may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Verified answer: Modify SQL: use a parameterized query. Bind input: pass the ID as an argument. Execute:
supply the parameter tuple to the SDK/driver method.
Detailed Explanation: The security boundary is created by separating SQL syntax from user-supplied values.
The statement should contain a parameter placeholder rather than concatenated input, and the document ID should be supplied separately through the database driver's parameter mechanism. The driver then performs the correct protocol-level binding and escaping. Manually escaping quotation marks is error-prone and does not provide the same injection resistance as true parameterization.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector similarity search with Azure PostgreSQL
NEW QUESTION # 70
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Hotspot Question
You need to configure the database resources for the Azure Database for PostgreSQL instance.
How should you complete the configuration to meet the business and technical requirements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Box 1: Increase compute vCores
Technical requirements, Performance: Semantic search latency must remain under 200 milliseconds at peak load.
To reduce semantic search latency under 200 milliseconds at peak load, the best action is to Increase compute vCores.
Vector similarity search and semantic retrieval are highly CPU-intensive operations. The math behind vector distance calculations (such as Cosine similarity, Dot Product, or Euclidean distance) relies heavily on mathematical operations executed per query. When a system experiences peak load, compute vCores easily become the primary bottleneck. Adding more vCores directly increases parallel processing capacity, dramatically shortening the execution time of similarity calculations and keeping retrieval latency within the required 200 ms SLA.
Box 2: Increase memory allocation
The best action is to increase memory allocation.
High-dimensional vector indexes (such as HNSW or IVFFlat managed by the pgvector extension) are highly resource-intensive and rely heavily on RAM. To maintain fast vector similarity searches and avoid high-latency disk operations, the entire vector index must fit into memory (RAM residency). Scaling up the database instance's memory directly expands the PostgreSQL shared buffers and cache, ensuring the high-dimensional index remains resident in RAM for rapid semantic retrieval.
Box 3: Enable storage autoscale
Enable storage autoscale is the best action to support the continuous ingestion of transaction- based embeddings.
Continuous Ingestion Demands Dynamic Space: Continuous transaction processing causes vector databases (such as Azure Database for PostgreSQL with pgvector or Azure SQL Database) to expand constantly over time.
Preventing Ingestion Failures: If storage reaches capacity limits, the database switches into a read-only state. This immediately fails and halts all incoming real-time embedding write operations. Enabling storage autoscale allows the environment to dynamically provision storage on the fly without downtime.
Reference:
https://dl.acm.org/doi/10.1145/3695053.3731013
https://learn.microsoft.com/en-us/training/paths/develop-ai-solutions-azure-database-postgresql/
https://learn.microsoft.com/en-us/azure/architecture/guide/technology-choices/vector-search
NEW QUESTION # 71
......
It is not hard to know that Developing AI Cloud Solutions on Azure torrent prep is compiled by hundreds of industry experts based on the syllabus and development trends of industries that contain all the key points that may be involved in the examination. Therefore, with AI-200 exam questions, you no longer need to purchase any other review materials, and you also don’t need to spend a lot of money on tutoring classes. At the same time, AI-200 Test Guide will provide you with very flexible learning time in order to help you pass the exam.
Exam AI-200 Experience: https://www.realexamfree.com/AI-200-real-exam-dumps.html
BTW, DOWNLOAD part of RealExamFree AI-200 dumps from Cloud Storage: https://drive.google.com/open?id=13IoBbtlLTJ_Aa68QnwwBaJQse8OAZm4a