Our Databricks-Certified-Professional-Data-Engineer study prep has a pass rate of 98% to 100% because of the high test hit rate. So our Databricks-Certified-Professional-Data-Engineer study materials are not only effective but also useful. As we all know, time is very important to everyone. Some candidates are very busy with their own work and families. It is very difficult to take time out to review the Databricks-Certified-Professional-Data-Engineer Exam. But if you use Databricks-Certified-Professional-Data-Engineer exam materials, you will learn very little time and have a high pass rate. Our Databricks-Certified-Professional-Data-Engineer study materials are worthy of your trust.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Certificate Validity Period: | 2 years |
| Exam Price: | $200 USD |
| Related Certifications: | Databricks Certified Data Analyst Associate Databricks Certified Associate Developer |
| Real Exam Qty: | 60 |
| Available Languages: | English |
| Exam Duration: | 90 minutes |
| Exam Format: | Multiple Choice, Multiple Select |
| Passing Score: | 70% |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored exam (Pearson VUE) |
| Pre Condition: | Recommended: 6+ months of hands-on experience with Databricks and data engineering concepts; familiarity with Python or Scala and SQL is strongly recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/professional-data-engineer |
>> Free Databricks-Certified-Professional-Data-Engineer Dumps <<
Although the Databricks Databricks-Certified-Professional-Data-Engineer exam prep is of great importance, you do not need to be over concerned about it. With scientific review and arrangement from professional experts as your backup, and the most accurate and high quality content of our Databricks Databricks-Certified-Professional-Data-Engineer Study Materials, you will cope with it like a piece of cake. So Databricks Databricks-Certified-Professional-Data-Engineer learning questions will be your indispensable practice materials during your way to success.
Databricks Certified Professional Data Engineer (Databricks-Certified-Professional-Data-Engineer) Certification Exam is a highly respected credential within the data engineering industry. Databricks Certified Professional Data Engineer Exam certification is specifically designed for professionals who have a deep understanding of data engineering principles, practices, and technologies. With this certification, data engineers can demonstrate their expertise in designing and building data pipelines, managing data workflows, and implementing data analytics solutions using Databricks.
Databricks Certified Professional Data Engineer Certification Exam can be attempted by professionals and students who have experience in data engineering, data management, ETL, and data processing. The preparation for the exam can be done via online training courses such as the Databricks Data Engineering Certification Preparation Course, the online Databricks Documentation, and different study materials such as books and videos from verified training providers.
Preparing for the Databricks Certified Professional Data Engineer exam is crucial for anyone looking to advance their career in data engineering. Databricks offers several resources to help candidates prepare for the exam, including online training courses, study materials, and practice exams. By earning this certification, data engineers can demonstrate their proficiency in using Databricks to build scalable and efficient data pipelines, which can lead to new career opportunities and higher salaries.
NEW QUESTION # 51
The operations team is interested in monitoring the recently launched product, team wants to set up an email alert when the number of units sold increases by more than 10,000 units. They want to monitor this every 5 mins.
Fill in the below blanks to finish the steps we need to take
* Create ___ query that calculates total units sold
* Setup ____ with query on trigger condition Units Sold > 10,000
* Setup ____ to run every 5 mins
* Add destination ______
Answer: A
Explanation:
Explanation
The answer is SQL, Alert, Refresh, email address
Here the steps from Databricks documentation,
Create an alert
Follow these steps to create an alert on a single column of a query.
1.Do one of the following:
*Click Create in the sidebar and select Alert.
*Click Alerts in the sidebar and click the + New Alert button.
2.Search for a target query.
Graphical user interface, text, application Description automatically generated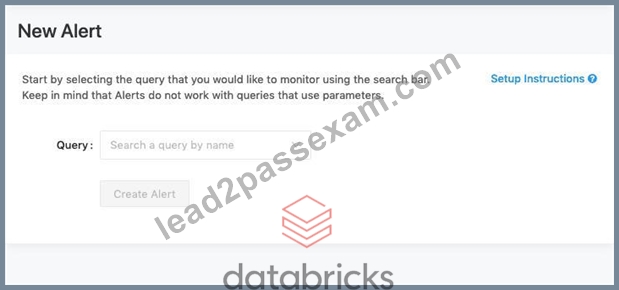
To alert on multiple columns, you need to modify your query. See Alert on multiple col-umns.
3.In the Trigger when field, configure the alert.
*The Value column drop-down controls which field of your query result is evaluated.
*The Condition drop-down controls the logical operation to be applied.
*The Threshold text input is compared against the Value column using the Condition you specify.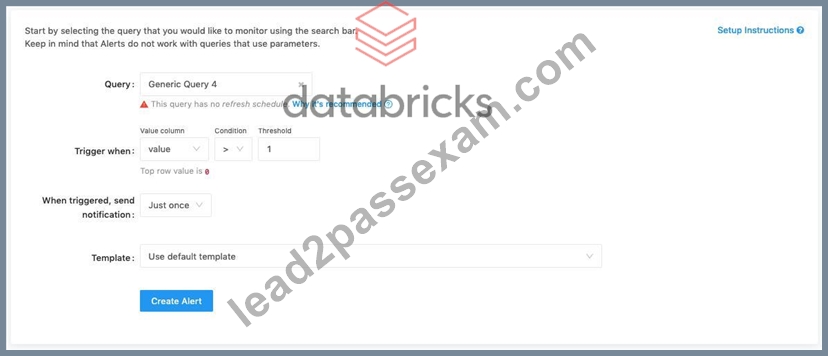
Note
If a target query returns multiple records, Databricks SQL alerts act on the first one. As you change the Value column setting, the current value of that field in the top row is shown beneath it.
4.In the When triggered, send notification field, select how many notifications are sent when your alert is triggered:
*Just once: Send a notification when the alert status changes from OK to TRIGGERED.
*Each time alert is evaluated: Send a notification whenever the alert status is TRIGGERED regardless of its status at the previous evaluation.
*At most every: Send a notification whenever the alert status is TRIGGERED at a spe-cific interval. This choice lets you avoid notification spam for alerts that trigger of-ten.
Regardless of which notification setting you choose, you receive a notification whenever the status goes from OK to TRIGGERED or from TRIGGERED to OK. The schedule settings affect how many notifications you will receive if the status remains TRIGGERED from one execution to the next. For details, see Notification frequency.
5.In the Template drop-down, choose a template:
*Use default template: Alert notification is a message with links to the Alert configuration screen and the Query screen.
*Use custom template: Alert notification includes more specific information about the alert.
a.A box displays, consisting of input fields for subject and body. Any static content is valid, and you can incorporate built-in template variables:
*ALERT_STATUS: The evaluated alert status (string).
*ALERT_CONDITION: The alert condition operator (string).
*ALERT_THRESHOLD: The alert threshold (string or number).
*ALERT_NAME: The alert name (string).
*ALERT_URL: The alert page URL (string).
*QUERY_NAME: The associated query name (string).
*QUERY_URL: The associated query page URL (string).
*QUERY_RESULT_VALUE: The query result value (string or number).
*QUERY_RESULT_ROWS: The query result rows (value array).
*QUERY_RESULT_COLS: The query result columns (string array).
An example subject, for instance, could be: Alert "{{ALERT_NAME}}" changed status to
{{ALERT_STATUS}}.
b.Click the Preview toggle button to preview the rendered result.
Important
The preview is useful for verifying that template variables are rendered cor-rectly. It is not an accurate representation of the eventual notification content, as each alert destination can display notifications differently.
c.Click the Save Changes button.
6.In Refresh, set a refresh schedule. An alert's refresh schedule is independent of the query's refresh schedule.
*If the query is a Run as owner query, the query runs using the query owner's cre-dential on the alert's refresh schedule.
*If the query is a Run as viewer query, the query runs using the alert creator's cre-dential on the alert's refresh schedule.
7.Click Create Alert.
8.Choose an alert destination.
Important
If you skip this step you will not be notified when the alert is triggered.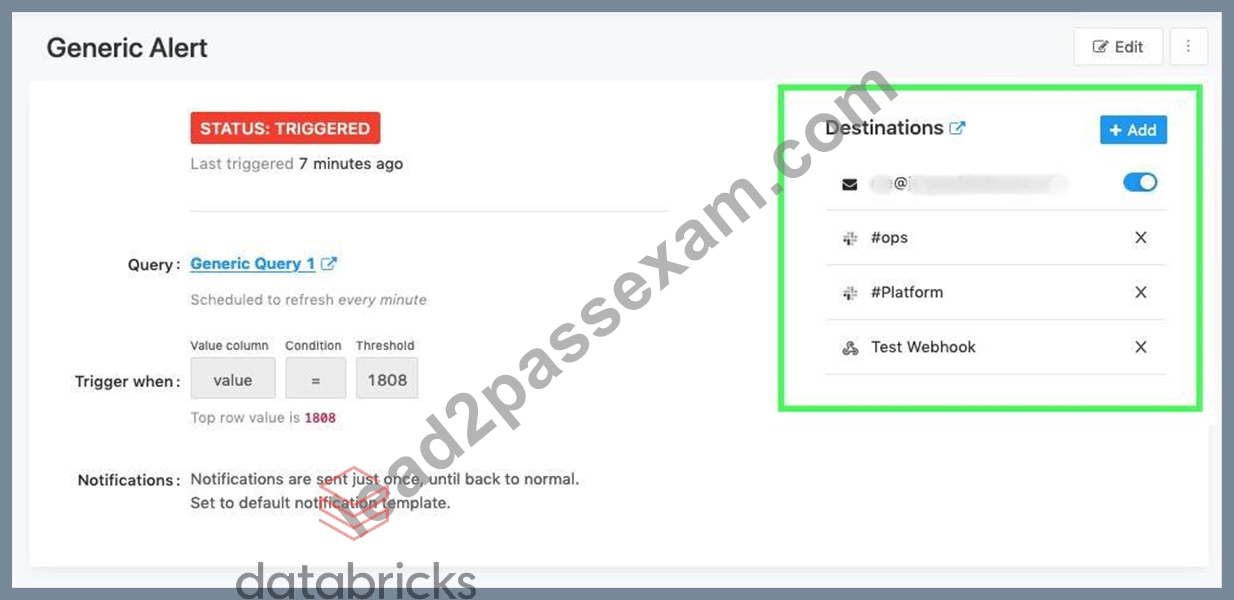
NEW QUESTION # 52
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.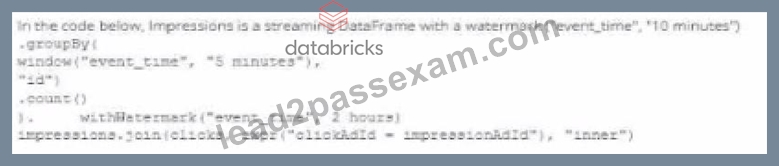
Which solution would improve the performance?




Answer: D
Explanation:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time. However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
NEW QUESTION # 53
Which statement describes Delta Lake optimized writes?
Answer: D
Explanation:
Delta Lake optimized writes involve a shuffle operation before writing out data to the Delta table. The shuffle operation groups data by partition keys, which can lead to a reduction in the number of output files and potentially larger files, instead of multiple smaller files. This approach can significantly reduce the total number of files in the table, improve read performance by reducing the metadata overhead, and optimize the table storage layout, especially for workloads with many small files.
References:
* Databricks documentation on Delta Lake performance tuning: https://docs.databricks.com/delta
/optimizations/auto-optimize.html
NEW QUESTION # 54
The data architect has mandated that all tables in the Lakehouse should be configured as external (also known as "unmanaged") Delta Lake tables.
Which approach will ensure that this requirement is met?
Answer: A
Explanation:
To create an external or unmanaged Delta Lake table, you need to use the EXTERNAL keyword in the CREATE TABLE statement. This indicates that the table is not managed by the catalog and the data files are not deleted when the table is dropped. You also need to provide a LOCATION clause to specify the path where the data files are stored. For example:
CREATE EXTERNAL TABLE events ( date DATE, eventId STRING, eventType STRING, data STRING) USING DELTA LOCATION '/mnt/delta/events'; This creates an external Delta Lake table named events that references the data files in the '/mnt/delta/events' path. If you drop this table, the data files will remain intact and you can recreate the table with the same statement.
:
https://docs.databricks.com/delta/delta-batch.html#create-a-table
https://docs.databricks.com/delta/delta-batch.html#drop-a-table
NEW QUESTION # 55
The data engineering team maintains a table of aggregate statistics through batch nightly updates. This includes total sales for the previous day alongside totals and averages for a variety of time periods including the 7 previous days, year-to-date, and quarter-to-date. This table is namedstore_saies_summaryand the schema is as follows:
The tabledaily_store_salescontains all the information needed to updatestore_sales_summary. The schema for this table is:
store_id INT, sales_date DATE, total_sales FLOAT
Ifdaily_store_salesis implemented as a Type 1 table and the column might be adjusted after manual data auditing, which approach is the safest to generate accurate reports in thestore_sales_summarytable?
Answer: A
Explanation:
Explanation
The daily_store_sales table contains all the information needed to update store_sales_summary. The schema of the table is:
store_id INT, sales_date DATE, total_sales FLOAT
The daily_store_sales table is implemented as a Type 1 table, which means that old values are overwritten by new values and no history is maintained. The total_sales column might be adjusted after manual data auditing, which means that the data in the table may change over time.
The safest approach to generate accurate reports in the store_sales_summary table is to use Structured Streaming to subscribe to the change data feed for daily_store_sales and apply changes to the aggregates in the store_sales_summary table with each update. Structured Streaming is a scalable and fault-tolerant stream processing engine built on Spark SQL. Structured Streaming allows processing data streams as if they were tables or DataFrames, using familiar operations such as select, filter, groupBy, or join. Structured Streaming also supports output modes that specify how to write the results of a streaming query to a sink, such as append, update, or complete. Structured Streaming can handle both streaming and batch data sources in a unified manner.
The change data feed is a feature of Delta Lake that provides structured streaming sources that can subscribe to changes made to a Delta Lake table. The change data feed captures both data changes and schema changes as ordered events that can be processed by downstream applications or services. The change data feed can be configured with different options, such as starting from a specific version or timestamp, filtering by operation type or partition values, or excluding no-op changes.
By using Structured Streaming to subscribe to the change data feed for daily_store_sales, one can capture and process any changes made to the total_sales column due to manual data auditing. By applying these changes to the aggregates in the store_sales_summary table with each update, one can ensure that the reports are always consistent and accurate with the latest data. Verified References: [Databricks Certified Data Engineer Professional], under "Spark Core" section; Databricks Documentation, under "Structured Streaming" section; Databricks Documentation, under "Delta Change Data Feed" section.
NEW QUESTION # 56
......
Databricks-Certified-Professional-Data-Engineer Test Online: https://www.lead2passexam.com/Databricks/valid-Databricks-Certified-Professional-Data-Engineer-exam-dumps.html