SPS-C01최신덤프문제, SPS-C01최신시험최신덤프

참고: Pass4Test에서 Google Drive로 공유하는 무료 2026 Snowflake SPS-C01 시험 문제집이 있습니다: https://drive.google.com/open?id=1tXUpNV73I_giUGIhanVG7Ixexov6oVOw
Pass4Test의 Snowflake인증 SPS-C01시험덤프자료는 IT인사들의 많은 찬양을 받아왔습니다.이는Pass4Test의 Snowflake인증 SPS-C01덤프가 신뢰성을 다시 한번 인증해주는것입니다. Snowflake인증 SPS-C01시험덤프의 인기는 이 시험과목이 얼마나 중요한지를 증명해줍니다. Pass4Test의 Snowflake인증 SPS-C01덤프로 이 중요한 IT인증시험을 준비하시면 우수한 성적으로 시험을 통과하여 인정받는 IT전문가로 될것입니다.
Snowflake SPS-C01 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Performance and Best Practices | 10% | - Optimization techniques
- 1. Query pushdown and execution plans
- 2. Minimizing data movement
- 3. Caching and warehouse sizing
- Security and governance
- 1. Data protection and compliance
- 2. Access control and permissions
|
| Topic 2: Data Transformations and Operations | 35% | - User-defined logic
- 1. Stored procedures with Snowpark
- 2. UDFs, UDAFs, UDTFs
- Advanced operations
- 1. Semi-structured data processing
- 2. Pivot and unpivot transformations
- 3. Window functions and analytics
- DataFrame manipulation
- 1. Filtering, sorting, grouping, aggregation
- 2. Selection, projection, renaming, casting
- 3. Joins, unions, set operations
|
| Topic 3: Snowpark API and Development | 30% | - Python API fundamentals
- 1. Data persistence and writing results
- 2. Column operations and functions
- 3. DataFrame creation from tables, views, SQL
- Multi-language support
- 1. Java and Scala API basics
- 2. Environment setup and dependencies
|
| Topic 4: Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
- 1. Client-side vs server-side processing
- 2. Transformations vs actions
- 3. Lazy evaluation and DAG execution
- Session management and connection
- 1. Authentication and connection settings
- 2. Create and configure Snowpark sessions
|
>> SPS-C01최신 덤프문제 <<
SPS-C01최신 덤프문제 시험대비 인증덤프
Pass4Test의 Snowflake SPS-C01덤프를 공부하면 100% Snowflake SPS-C01 시험패스를 보장해드립니다. 만약 Snowflake SPS-C01 덤프자료를 구매하여 공부한후 시험에 탈락할시 불합격성적표와 주문번호를 메일로 보내오시면 덤프비용을 바로 환불해드립니다. 저희 Pass4Test Snowflake SPS-C01덤프로 자격증부자되세요.
최신 Snowflake Certification SPS-C01 무료샘플문제 (Q262-Q267):
질문 # 262
Consider the following Snowpark Python code snippet designed to create a DataFrame and then register a custom function (UDF):
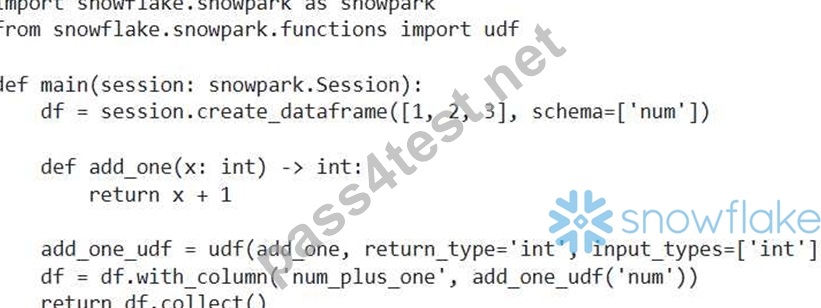
This code runs successfully. However, you need to deploy this as a stored procedure. What minimal changes are required to make this code runnable as a Snowpark Python stored procedure and callable from SQL?
- A. No changes are required; the code will function as a stored procedure as is.
- B. The 'return df.collect()' line must be replaced with 'return and the 'return_type' and 'input_typeS arguments of udf must be removed to allow inference. The rest of the code remains unchanged.
- C. The 'return df.collect()' line must be replaced with 'return df and create a DataFrame. The rest of the code remains unchanged.
- D. The 'return df.collect()' line must be replaced with 'return and 'return_type' and 'input_typeS arguments of udf must be removed. The rest of the code remains unchanged.
- E. The 'return df.collect()' line must be replaced with 'return and the Snowflake session object must be explicitly passed to the UDF when it is called.
정답:B
설명:
When deploying as a stored procedure, 'return will cause an error since stored procedures cannot return Snowpark DataFrames directly to SQL. You need to return the DataFrame to pandas using 'return and remove 'return_type' and 'input_types' arguments of udf to allow inference.
질문 # 263
Given a Snowpark DataFrame 'df with a column named 'data' of VARIANT type, where the VARIANT contains JSON objects with nested fields. You need to extract the value of the nested field 'address.city' as a STRING and the value of as a DOUBLE, handling cases where either 'address' or 'items' might be missing. Which combination of Snowpark functions is best suited to achieve this robustly and efficiently?
정답:C
설명:
Option C is the most robust because it uses 'get_patW combined with and 'get_patm is specifically designed for extracting nested fields from VARIANT data, and handle cases where the path doesn't exist (returning NULL instead of an error).option A will fail if 'address' or 'items' is missing. Option B doesn't handle the NULL cases gracefully and 'to_double' expects a string not a variant. Option D doesn't handle the NULL cases gracefully and used 'to_varchaff which is deprecated. Option E will fail if 'address' or 'items' is missing and doesn't use get_path
질문 # 264
A Snowpark application needs to dynamically switch between different Snowflake accounts based on the environment (development, staging, production). Which of the following approaches provides the MOST secure and maintainable way to manage account credentials without hardcoding them in the application? Assume that deployment will occur via docker, Kubernetes or other modern deployment practices.
- A. Store credentials in environment variables managed by the deployment platform (e.g., Kubernetes secrets) and access them using
- B. Store credentials in separate .env' files for each environment and load the appropriate file based on an environment variable indicating the current environment.
- C. Use the Snowflake CLI configuration file ('-/.snowflake/config') and switch between named profiles based on an environment variable.
- D. Hardcode credentials in the Snowpark application code and rely on network security to prevent unauthorized access.
- E. Encrypt the credentials and store them in a configuration file that is decrypted at runtime using a key stored in a secure vault.
정답:A
설명:
Storing credentials in environment variables managed by the deployment platform (Option B) is the most secure and maintainable approach. It avoids storing sensitive information in files within the application code or requiring manual credential management. Kubernetes secrets are specifically designed to securely store and manage sensitive data. Option A is better than E, but still puts the credetials in file. Option C is valid approach but has more complexity than Option B. Option D Snowflake CLI is designed for user interaction, not necessarily programmatic access from within an application, particularly in containerized deployment scenarios. Option E is never considered a secure solution.
질문 # 265
You have a Python dictionary 'data' representing configuration settings for your Snowpark application. You need to convert this dictionary into a Snowpark DataFrame with a single row and two columns named 'Setting' and 'Value'. The 'Setting' column should contain the keys from the dictionary, and the 'Value' column should contain the corresponding values. The DataFrame needs to be created efficiently and ensure string representation of both the setting and value. Which approach is most suitable, ensuring correctness and conciseness?
- A. python import snowflake.snowpark.types as T settings = list(data.items()) schema = T.StructType([T.StructField('Setting', T.StringType()), T.StructField('Value', T.StringType())]) df = session.createDataFrame(settings, schema=schema)
- B. 'python settings = [1k, v] for k, v in data.items()] df = session.createDataFrame(settings, schema=['Setting', 'Value'])
- C. python import pandas as pd pd_df = pd.DataFrame(data.items(), columns=['Setting', 'Value')) df = session.createDataFrame(pd_df)
- D. python settings = [1k, str(v)] for k, v in data.items()] schema = ['Setting', 'Value'] df = session.createDataFrame(settings, schema=schema)
- E. 'python settings = [{'Setting': k, 'Value': v} for k, v in data.items()] df = session.createDataFrame(settings)
정답:D
설명:
Option D is the most suitable approach. Here's why: Correctness: It correctly transforms the dictionary into a list of lists, where each inner list contains the key and its corresponding value. The 'str(vy ensures all values are converted to strings, meeting the requirement. Efficiency: It directly creates a Snowpark DataFrame without unnecessary intermediate conversions (e.g., to Pandas DataFrame). Clarity: It clearly defines the schema using a list of column names, making the code easy to understand. Option A is not correct, you need list of list for each row, the schema is not correct for dictionary structure Option B introduces Pandas dependency and incurs the overhead of converting to Pandas DataFrame and then to a Snowpark DataFrame. Option C creates a list of dictionaries, where each dictionary has the keys 'Setting' and Value'. This creates as many rows as items in the 'data' dictionary and not a single row, but each config, thus wrong. Option E is nearly correct, but the problem is 'str(v)' which ensure string type casting is missing
질문 # 266
You are tasked with building a Snowpark application to process sensor data from IoT devices. The data arrives as JSON strings and needs to be transformed into a tabular format before being stored in a Snowflake table. You decide to use a User-Defined Table Function (UDTF) written in Python to handle this transformation. Which of the following approaches is the MOST efficient and scalable way to deploy and execute this UDTF in a production Snowpark environment, considering the possibility of high data volumes and concurrency?
- A. Deploy the UDTF as an inline Python function within the Snowpark DataFrame transformation code, relying on the client-side Python interpreter for execution.
- B. Deploy the UDTF as an external function, leveraging an external API gateway to invoke the Python code running on a serverless compute platform.
- C. Deploy the UDTF using the '@udtf decorator and explicitly specify a parameter when registering the function to control the size of input batches processed by each worker node.
- D. Package the Python UDTF into a zip file and upload it to a Snowflake stage. During UDTF registration, specify the stage location and use [...l, return_type=..., packages=['snowflake-snowpark-python', 'your_package'])'. Ensure that is appropriately tuned based on data size and complexity.
- E. Deploy the UDTF as a stored procedure that is then called from your Snowpark application. The UDTF processes the data serially, one record at a time.
정답:D
설명:
Option E is the MOST efficient and scalable. Deploying the UDTF with explicit package management and optimized batch sizing allows Snowflake to distribute the processing across multiple worker nodes, leveraging the platform's parallel processing capabilities. Specifying dependencies using the 'packages' parameter ensures that the required Python libraries are available on each worker node. Properly tuning max_batch_size' prevents memory exhaustion and optimizes processing speed. Options A, C, and D are generally less scalable and efficient due to client-side execution, serial processing, or added external latency. Option B is correct in mentioning batch sizing, but is incomplete. Option E offers the best balance of performance, scalability, and maintainability.
질문 # 267
......
지금 같은 정보시대에, 많은 IT업체 등 사이트에Snowflake SPS-C01인증관련 자료들이 제공되고 있습니다, 하지만 이런 사이트들도 정확하고 최신 시험자료 확보는 아주 어렵습니다. 그들의Snowflake SPS-C01자료들은 아주 기본적인 것들뿐입니다. 전면적이지 못하여 응시자들의 관심을 쌓지 못합니다.
SPS-C01최신 시험 최신 덤프: https://www.pass4test.net/SPS-C01.html
- SPS-C01최고품질 덤프문제모음집 🌅 SPS-C01시험대비 최신버전 덤프샘플 🎰 SPS-C01유효한 최신덤프공부 🦠 오픈 웹 사이트⮆ kr.fast2test.com ⮄검색▷ SPS-C01 ◁무료 다운로드SPS-C01인증시험공부
- SPS-C01최신 덤프문제 퍼펙트한 덤프 ----- IT전문가의 노하우로 만들어진 시험자료 🌮 ➽ www.itdumpskr.com 🢪을 통해 쉽게➡ SPS-C01 ️⬅️무료 다운로드 받기SPS-C01최고덤프자료
- SPS-C01퍼펙트 덤프 최신문제 🍶 SPS-C01시험대비 덤프데모문제 다운 🏌 SPS-C01예상문제 📊 「 www.exampassdump.com 」의 무료 다운로드➽ SPS-C01 🢪페이지가 지금 열립니다SPS-C01퍼펙트 최신버전 자료
- SPS-C01최신 덤프문제 인증시험 대비자료 ❔ 무료 다운로드를 위해【 SPS-C01 】를 검색하려면▶ www.itdumpskr.com ◀을(를) 입력하십시오SPS-C01최신버전 시험자료
- SPS-C01최신 덤프문제 최신덤프자료 ⚔ 지금⏩ www.koreadumps.com ⏪에서➤ SPS-C01 ⮘를 검색하고 무료로 다운로드하세요SPS-C01인증시험공부
- SPS-C01유효한 최신덤프공부 🥤 SPS-C01최고품질 인증시험덤프데모 🧬 SPS-C01인증시험공부 📤 시험 자료를 무료로 다운로드하려면《 www.itdumpskr.com 》을 통해⏩ SPS-C01 ⏪를 검색하십시오SPS-C01인증시험공부
- SPS-C01최신 덤프문제 최신 시험 기출문제 모음 자료 🧷 무료로 다운로드하려면《 www.exampassdump.com 》로 이동하여➠ SPS-C01 🠰를 검색하십시오SPS-C01최고품질 덤프문제모음집
- SPS-C01인기자격증 덤프공부자료 🙉 SPS-C01시험대비 덤프 최신 데모 😎 SPS-C01최고품질 시험덤프 공부자료 🎻 ➽ www.itdumpskr.com 🢪에서 검색만 하면{ SPS-C01 }를 무료로 다운로드할 수 있습니다SPS-C01최고품질 인증시험덤프데모
- SPS-C01최고품질 덤프문제모음집 🕘 SPS-C01최고품질 덤프문제모음집 🐷 SPS-C01퍼펙트 최신버전 자료 ⏏ 검색만 하면⇛ kr.fast2test.com ⇚에서➽ SPS-C01 🢪무료 다운로드SPS-C01최고덤프자료
- 시험패스 가능한 SPS-C01최신 덤프문제 덤프 샘플문제 다운받기 🥨 무료 다운로드를 위해《 SPS-C01 》를 검색하려면➡ www.itdumpskr.com ️⬅️을(를) 입력하십시오SPS-C01덤프문제집
- 최신 SPS-C01최신 덤프문제 덤프는 Snowflake Certified SnowPro Specialty - Snowpark시험문제의 모든 유형과 범위를 커버 🐫 { kr.fast2test.com }웹사이트에서[ SPS-C01 ]를 열고 검색하여 무료 다운로드SPS-C01예상문제
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
그 외, Pass4Test SPS-C01 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1tXUpNV73I_giUGIhanVG7Ixexov6oVOw




