HOT Valid Certified-Data-Engineer-Professional Guide Files 100% Pass | Valid Reliable Databricks Certified Data Engineer Professional Dumps Ebook Pass for sure

And if you still feel uncertain about the content, wondering whether it is the exact Certified-Data-Engineer-Professional exam material that you want, you can free download the demo to check it out. You will be quite surprised by the convenience to have an overview just by clicking into the link, and you can experience all kinds of Certified-Data-Engineer-Professional versions. Though the content of the Certified-Data-Engineer-Professional exam questions is the same, but the displays vary to make sure that you can study by your favorite way.
| Section | Weight | Objectives |
|---|
| CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines
- Deploy with Declarative Automation Bundles, CLI, and REST API
|
| Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs
- Implement row-level security, column masking, and compliance
|
| Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering
- Apply dimensional modeling techniques
|
| Developing Code for Data Processing using Python and SQL | ~22% | - Implement scalable Python/SQL code and project structures
- Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader
- Manage dependencies, libraries, and UDFs
|
| Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures
- Use Spark UI, Query Profiler, and system tables
|
| Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations
- Enforce data quality and quarantine bad data
|
| Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage
- Leverage system tables and observability tools
|
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation
|
| Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines
- Apply AUTO CDC APIs and exactly-once semantics
|
>> Valid Certified-Data-Engineer-Professional Guide Files <<
Latest updated Valid Certified-Data-Engineer-Professional Guide Files | Amazing Pass Rate For Certified-Data-Engineer-Professional Exam | Top Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional
We will provide 24-hour online service for you on our Certified-Data-Engineer-Professional exam questios. If you can’t decide what kind of Certified-Data-Engineer-Professional exam practice to choose, you shall have a chance to consult us, You can ask the questions that you want to know about our Certified-Data-Engineer-Professional Study Guide, we will listen to you carefully, according to your Certified-Data-Engineer-Professional exam, we guarantee to meet your requirements without wasting your purchasing funds.
Databricks Certified Data Engineer Professional Sample Questions (Q84-Q89):
NEW QUESTION # 84
A DLT pipeline includes the following streaming tables:
Raw_lot ingest raw device measurement data from a heart rate tracking device.
Bpm_stats incrementally computes user statistics based on BPM measurements from raw_lot.
How can the data engineer configure this pipeline to be able to retain manually deleted or updated records in the raw_iot table while recomputing the downstream table when a pipeline update is run?
- A. Set the SkipChangeCommits flag to true raw_lot
- B. Set the skipChangeCommits flag to true on bpm_stats
- C. Set the pipelines, reset, allowed property to false on bpm_stats
- D. Set the pipelines, reset, allowed property to false on raw_iot
Answer: D
Explanation:
In Databricks Lakehouse, to retain manually deleted or updated records in the raw_iot table while recomputing downstream tables when a pipeline update is run, the property pipelines.reset.allowed should be set to false. This property prevents the system from resetting the state of the table, which includes the removal of the history of changes, during a pipeline update. By keeping this property as false, any changes to the raw_iot table, including manual deletes or updates, are retained, and recomputation of downstream tables, such as bpm_stats, can occur with the full history of data changes intact.
NEW QUESTION # 85
A user wants to use DLT expectations to validate that a derived table report contains all records from the source, included in the table validation_copy.
The user attempts and fails to accomplish this by adding an expectation to the report table definition.
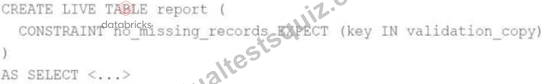
Which approach would allow using DLT expectations to validate all expected records are present in this table?
- A. Define a function that performs a left outer join on validation_copy and report and report, and check against the result in a DLT expectation for the report table
- B. Define a view that performs a left outer join on validation_copy and report, and reference this view in DLT expectations for the report table
- C. Define a SQL UDF that performs a left outer join on two tables, and check if this returns null values for report key values in a DLT expectation for the report table.
- D. Define a temporary table that perform a left outer join on validation_copy and report, and define an expectation that no report key values are null
Answer: B
Explanation:
To validate that all records from the source are included in the derived table, creating a view that performs a left outer join between the validation_copy table and the report table is effective. The view can highlight any discrepancies, such as null values in the report table's key columns, indicating missing records. This view can then be referenced in DLT (Delta Live Tables) expectations for the report table to ensure data integrity. This approach allows for a comprehensive comparison between the source and the derived table.
NEW QUESTION # 86
A data engineer, while designing a Pandas UDF to process financial time-series data with complex calculations that require maintaining state across rows within each stock symbol group, must ensure the function is efficient and scalable. Which approach will solve the problem with minimum overhead while preserving data integrity?
- A. Use applyInPandas() on a Spark DataFrame that receives all rows for each stock symbol as a Pandas DataFrame, allowing processing within each group while maintaining state variables local to each group's processing function.
- B. Use a SCALAR Pandas UDF that processes the entire dataset at once, implementing custom partitioning logic within the UDF to group by stock symbol and maintain state using global variables shared across all executor processes.
- C. Use a SCALAR_ITER Pandas UDF with iterator-based processing, implementing state management through persistent storage (Delta tables) that gets updated after each batch to maintain continuity across iterator chunks.
- D. Use a grouped_agg Pandas UDF that processes each stock symbol group independently, maintaining state through intermediate aggregation results that get passed between successive UDF calls via broadcast variables.
Answer: A
Explanation:
The Databricks documentation recommends applyInPandas() for complex per-group operations where maintaining internal state within each group is necessary. When using applyInPandas(), Spark provides all records for each grouping key as a Pandas DataFrame to the function, allowing efficient vectorized operations with local state management. This approach ensures high performance and scalability while maintaining logical isolation between groups. In contrast, SCALAR and SCALAR_ITER UDFs operate on individual rows or batches and cannot maintain inter-row state effectively. grouped_agg UDFs are limited to computing aggregates and do not support complex multi-row transformations. Therefore, applyInPandas() is the correct and Databricks-recommended solution for stateful per-group time-series computations.
NEW QUESTION # 87
The data engineering team has configured a job to process customer requests to be forgotten (have their data deleted). All user data that needs to be deleted is stored in Delta Lake tables using default table settings.
The team has decided to process all deletions from the previous week as a batch job at 1am each Sunday. The total duration of this job is less than one hour. Every Monday at 3am, a batch job executes a series of VACUUM commands on all Delta Lake tables throughout the organization.
The compliance officer has recently learned about Delta Lake's time travel functionality. They are concerned that this might allow continued access to deleted data.
Assuming all delete logic is correctly implemented, which statement correctly addresses this concern?
- A. Because Delta Lake time travel provides full access to the entire history of a table, deleted records can always be recreated by users with full admin privileges.
- B. Because the vacuum command permanently deletes all files containing deleted records, deleted records may be accessible with time travel for around 24 hours.
- C. Because the default data retention threshold is 7 days, data files containing deleted records will be retained until the vacuum job is run 8 days later.
- D. Because Delta Lake's delete statements have ACID guarantees, deleted records will be permanently purged from all storage systems as soon as a delete job completes.
- E. Because the default data retention threshold is 24 hours, data files containing deleted records will be retained until the vacuum job is run the following day.
Answer: C
Explanation:
https://learn.microsoft.com/en-us/azure/databricks/delta/vacuum
NEW QUESTION # 88
A data engineer is designing an append-only pipeline that needs to handle both batch and streaming data in Delta Lake. The team wants to ensure that the streaming component can efficiently track which data has already been processed. Which configuration should be set to enable this?
- A. overwriteSchema
- B. partitionBy
- C. mergeSchema
- D. checkpointLocation
Answer: D
Explanation:
When working with Delta Lake streaming ingestion, checkpointing is critical for maintaining fault tolerance and ensuring exactly-once data processing semantics.
The checkpointLocation parameter defines the directory where Spark Structured Streaming stores progress information, offsets, and metadata. This allows the engine to resume processing from the last committed offset without reprocessing previously ingested data.
Without checkpointing, each stream restart would reprocess all data, leading to duplicates.
Parameters like partitionBy or schema options (mergeSchema / overwriteSchema) affect table structure, not data lineage tracking. Therefore, the correct and required configuration for efficient streaming state management is checkpointLocation.
NEW QUESTION # 89
......
ActualTestsQuiz Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice material can be accessed instantly after purchase, so you won't have to face any excessive issues for preparation of your desired Certified-Data-Engineer-Professional certification exam. The Certified-Data-Engineer-Professional Exam Dumps of ActualTestsQuiz has been made after seeking advice from many professionals. Our objective is to provide you with the best learning material to clear the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam.
Reliable Certified-Data-Engineer-Professional Dumps Ebook: https://www.actualtestsquiz.com/Certified-Data-Engineer-Professional-test-torrent.html
- Quiz 2026 Databricks Updated Valid Certified-Data-Engineer-Professional Guide Files 🕙 Enter ( www.dumpsmaterials.com ) and search for 《 Certified-Data-Engineer-Professional 》 to download for free 🌸Certified-Data-Engineer-Professional Valid Test Materials
- Certified-Data-Engineer-Professional – 100% Free Valid Guide Files | Trustable Reliable Databricks Certified Data Engineer Professional Dumps Ebook 🥵 The page for free download of [ Certified-Data-Engineer-Professional ] on 《 www.pdfvce.com 》 will open immediately 👕Reliable Certified-Data-Engineer-Professional Exam Syllabus
- Certified-Data-Engineer-Professional Exam Simulator Online 💰 Reliable Certified-Data-Engineer-Professional Exam Preparation 👦 Certified-Data-Engineer-Professional Valid Test Materials ⚽ Search for ➽ Certified-Data-Engineer-Professional 🢪 and download it for free immediately on [ www.dumpsquestion.com ] 🍢Reliable Certified-Data-Engineer-Professional Exam Syllabus
- Reliable Certified-Data-Engineer-Professional Exam Online 🎇 Certified-Data-Engineer-Professional Test Dumps Demo 🐀 Test Certified-Data-Engineer-Professional Guide Online 🍨 Easily obtain ✔ Certified-Data-Engineer-Professional ️✔️ for free download through ➠ www.pdfvce.com 🠰 🦈Test Certified-Data-Engineer-Professional Vce Free
- Valid Certified-Data-Engineer-Professional Guide Files|High Pass Rate - www.exam4labs.com 🔪 Search for { Certified-Data-Engineer-Professional } and download exam materials for free through ⮆ www.exam4labs.com ⮄ 🔛Latest Certified-Data-Engineer-Professional Test Testking
- Certified-Data-Engineer-Professional Dumps 🕋 Certified-Data-Engineer-Professional Hot Spot Questions 🎴 Certified-Data-Engineer-Professional Study Materials Review 🧮 Search for ➥ Certified-Data-Engineer-Professional 🡄 and download exam materials for free through “ www.pdfvce.com ” 🤑Certified-Data-Engineer-Professional Book Free
- Pass Guaranteed 2026 Databricks Certified-Data-Engineer-Professional –Efficient Valid Guide Files 🎏 Search for ▛ Certified-Data-Engineer-Professional ▟ and obtain a free download on 【 www.vce4dumps.com 】 👳Test Certified-Data-Engineer-Professional Vce Free
- Reliable Certified-Data-Engineer-Professional Exam Preparation 😍 Certified-Data-Engineer-Professional Certificate Exam 🥳 Certified-Data-Engineer-Professional Exam Simulator Online 🧗 Search on ➤ www.pdfvce.com ⮘ for ➡ Certified-Data-Engineer-Professional ️⬅️ to obtain exam materials for free download 🐮Latest Certified-Data-Engineer-Professional Test Testking
- Pass Guaranteed Quiz 2026 Databricks Certified-Data-Engineer-Professional: Professional Valid Databricks Certified Data Engineer Professional Guide Files 🥅 Search for ( Certified-Data-Engineer-Professional ) and download it for free on ➽ www.pdfdumps.com 🢪 website 🕵Certified-Data-Engineer-Professional Certification Book Torrent
- Certified-Data-Engineer-Professional – 100% Free Valid Guide Files | Trustable Reliable Databricks Certified Data Engineer Professional Dumps Ebook 👕 Easily obtain free download of ➠ Certified-Data-Engineer-Professional 🠰 by searching on “ www.pdfvce.com ” 🛀Certified-Data-Engineer-Professional Exam Simulator Online
- Test Certified-Data-Engineer-Professional Guide Online 🎭 Test Certified-Data-Engineer-Professional Vce Free 💫 Certified-Data-Engineer-Professional Exam Success 🐍 Enter 《 www.dumpsmaterials.com 》 and search for 「 Certified-Data-Engineer-Professional 」 to download for free 🌄Certified-Data-Engineer-Professional Latest Exam Duration
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, estar.jp, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes