P.S. Free 2026 Microsoft DP-100 dumps are available on Google Drive shared by DumpsFree: https://drive.google.com/open?id=1WXrpMuFpksfq04Sirh-qi6ukNmCi7cjC
If you plan to apply for the Designing and Implementing a Data Science Solution on Azure (DP-100) certification exam, you need the best DP-100 practice test material that can help you maximize your chances of success. You cannot rely on invalid DP-100 Materials and then expect the results to be great. So, you must prepare from the updated Microsoft DP-100 Exam Dumps to crack the DP-100 exam.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Designing and Implementing a Data Science Solution on Azure |
| Exam Number: | DP-100 |
| Certificate Validity Period: | 1 year |
| Exam Price: | $165 USD |
| Exam Format: | Case Study, Multiple Choice, Drag and Drop, Interactive Tasks, Lab |
| Related Certifications: | Microsoft Certified: Azure Data Scientist Associate |
| Passing Score: | 700/1000 |
| Available Languages: | Portuguese, French, German, Spanish, English, Japanese, Korean, Chinese (Simplified) |
| Exam Duration: | 100 minutes |
| Real Exam Qty: | 40-60 |
| Sample Questions: | Microsoft DP-100 Sample Questions |
| Exam Way: | Online proctored exam or test center delivery through Pearson VUE. |
| Pre Condition: | Candidates should have experience with Azure services, Python programming, and machine learning frameworks such as Scikit-Learn, PyTorch, or TensorFlow. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/exams/dp-100/ |
>> Valid DP-100 Exam Objectives <<
They work together and put all their efforts to ensure the top standard of Microsoft DP-100 exam practice test questions. The DP-100 exam practice test questions are being offered in three different formats. These Microsoft DP-100 Exam Questions formats are PDF dumps files, desktop practice test software, and web-based practice test software.
Microsoft DP-100 Exam is a certification exam that validates the skills of individuals in designing and implementing data science solutions on Azure. It is a particularly valuable certification for professionals in the field of data science and machine learning who are interested in utilizing the Azure platform to develop scalable and efficient data solutions. Designing and Implementing a Data Science Solution on Azure certification exam is designed to test the candidate's ability to design and implement data science solutions using Azure technologies, including Azure Machine Learning, Azure Databricks, and Azure Cognitive Services.
NEW QUESTION # 71
Your Azure Machine Learning workspace has a dataset named real_estate_data. A sample of the data in the dataset follows.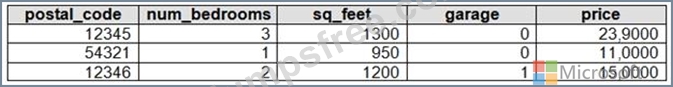
You want to use automated machine learning to find the best regression model for predicting the price column.
You need to configure an automated machine learning experiment using the Azure Machine Learning SDK.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.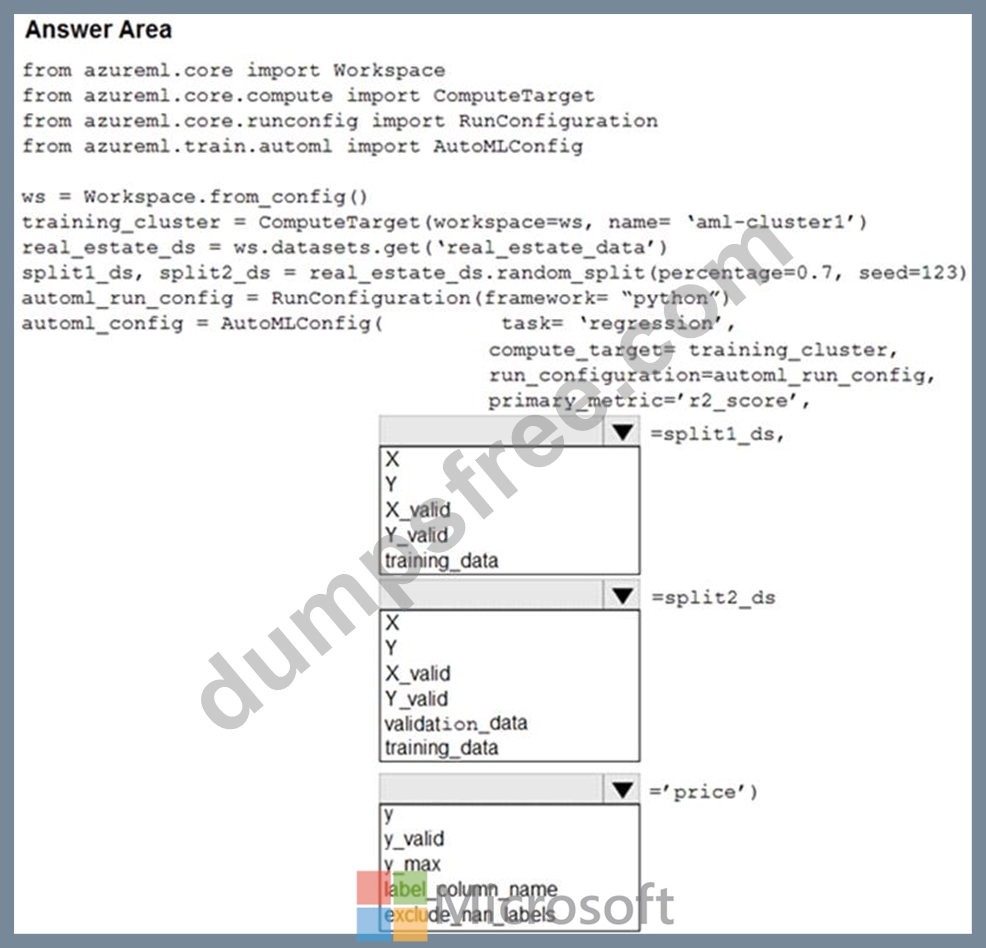
Answer:
Explanation: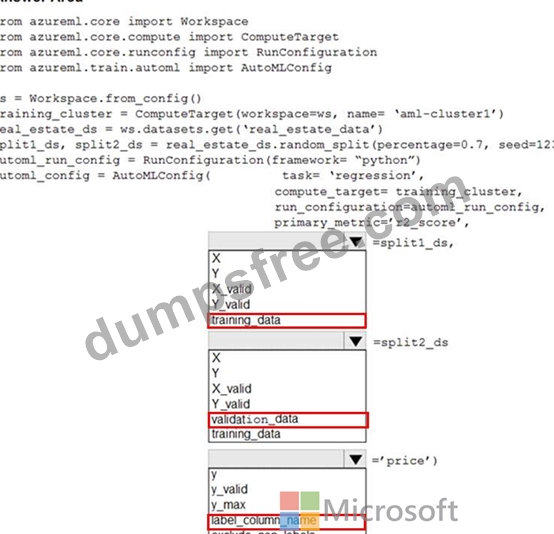
Explanation:
Box 1: training_data
The training data to be used within the experiment. It should contain both training features and a label column (optionally a sample weights column). If training_data is specified, then the label_column_name parameter must also be specified.
Box 2: validation_data
Provide validation data: In this case, you can either start with a single data file and split it into training and validation sets or you can provide a separate data file for the validation set. Either way, the validation_data parameter in your AutoMLConfig object assigns which data to use as your validation set.
Example, the following code example explicitly defines which portion of the provided data in dataset to use for training and validation.
dataset = Dataset.Tabular.from_delimited_files(data)
training_data, validation_data = dataset.random_split(percentage=0.8, seed=1) automl_config = AutoMLConfig(compute_target = aml_remote_compute, task = 'classification', primary_metric = 'AUC_weighted', training_data = training_data, validation_data = validation_data, label_column_name = 'Class' ) Box 3: label_column_name label_column_name:
The name of the label column. If the input data is from a pandas.DataFrame which doesn't have column names, column indices can be used instead, expressed as integers.
This parameter is applicable to training_data and validation_data parameters.
Incorrect Answers:
X: The training features to use when fitting pipelines during an experiment. This setting is being deprecated. Please use training_data and label_column_name instead.
Y: The training labels to use when fitting pipelines during an experiment. This is the value your model will predict. This setting is being deprecated. Please use training_data and label_column_name instead.
X_valid: Validation features to use when fitting pipelines during an experiment.
If specified, then y_valid or sample_weight_valid must also be specified.
Y_valid: Validation labels to use when fitting pipelines during an experiment.
Both X_valid and y_valid must be specified together.
exclude_nan_labels: Whether to exclude rows with NaN values in the label. The default is True.
y_max: y_max (float)
Maximum value of y for a regression experiment. The combination of y_min and y_max are used to normalize test set metrics based on the input data range. If not specified, the maximum value is inferred from the data.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-train-automl-client/azureml.train.automl.automlconfig.automlconfig?view=azure-ml-py
NEW QUESTION # 72
You are building an experiment using the Azure Machine Learning designer.
You split a dataset into training and testing sets. You select the Two-Class Boosted Decision Tree as the algorithm.
You need to determine the Area Under the Curve (AUC) of the model.
Which three modules should you use in sequence? To answer, move the appropriate modules from the list of modules to the answer area and arrange them in the correct order.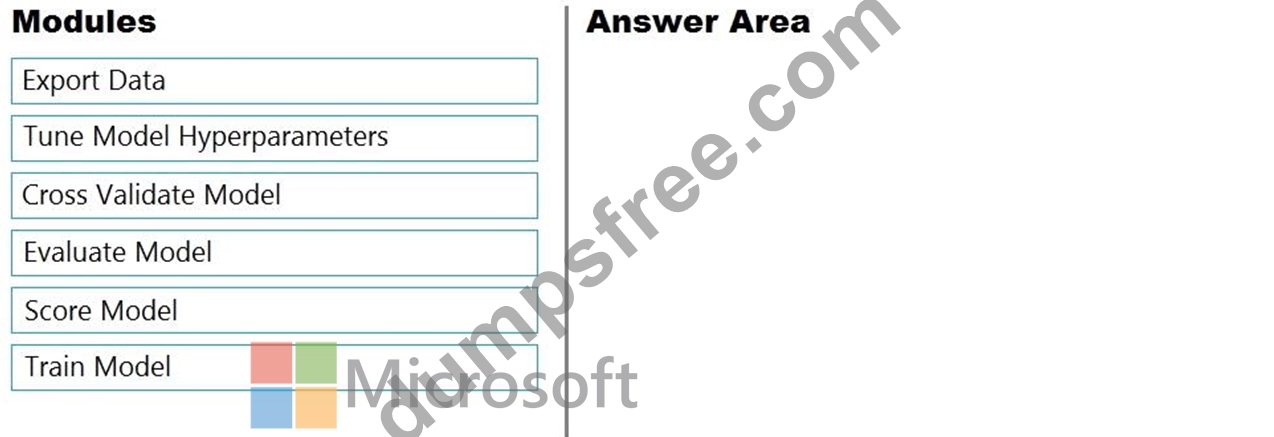
Answer:
Explanation: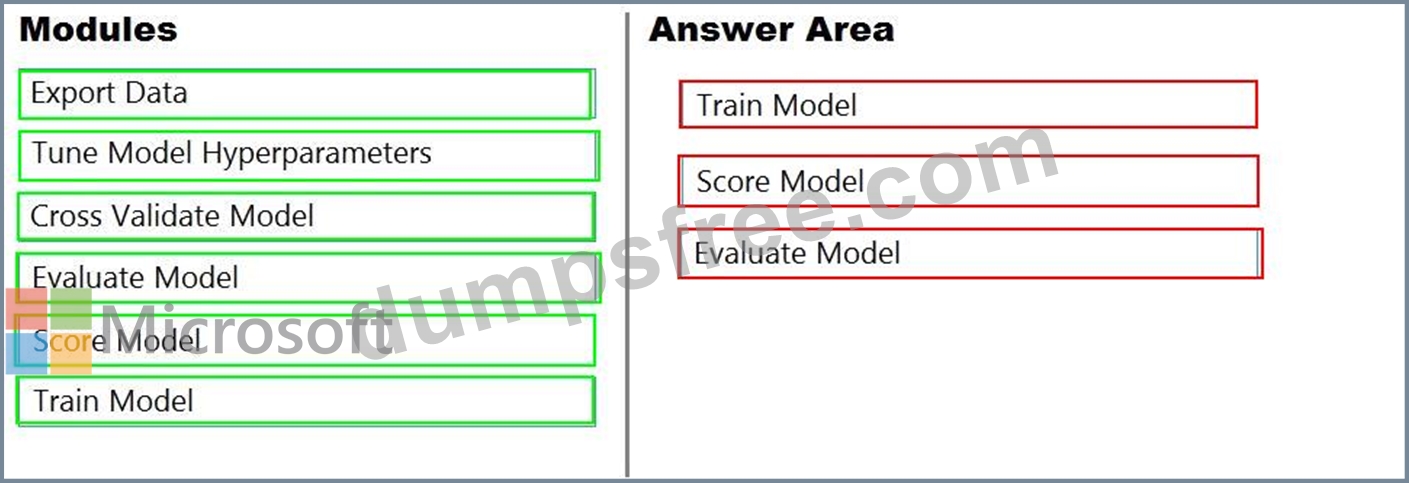
NEW QUESTION # 73
You are retrieving data from a large datastore by using Azure Machine Learning Studio.
You must create a subset of the data for testing purposes using a random sampling seed based on the system clock.
You add the Partition and Sample module to your experiment.
You need to select the properties for the module.
Which values should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.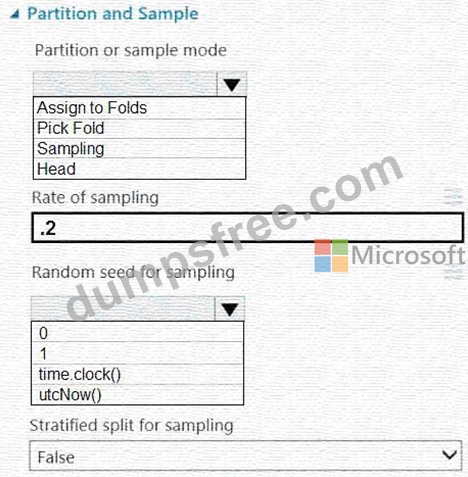
Answer:
Explanation: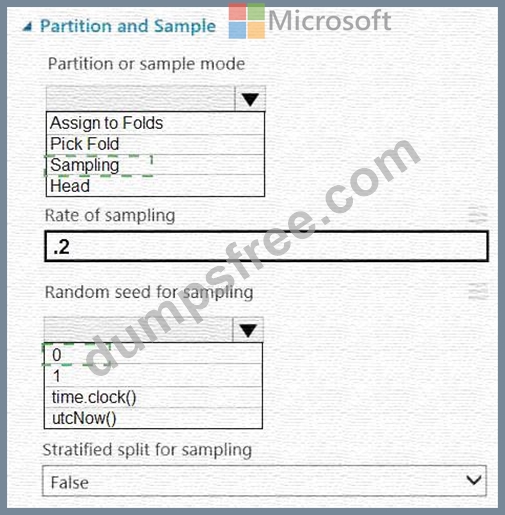
Explanation: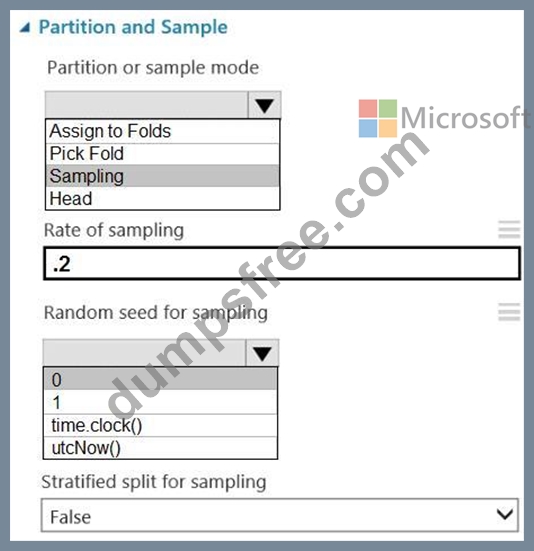
Box 1: Sampling
Create a sample of data
This option supports simple random sampling or stratified random sampling. This is useful if you want to create a smaller representative sample dataset for testing.
1. Add the Partition and Sample module to your experiment in Studio, and connect the dataset.
2. Partition or sample mode: Set this to Sampling.
3. Rate of sampling. See box 2 below.
Box 2: 0
3. Rate of sampling. Random seed for sampling: Optionally, type an integer to use as a seed value.
This option is important if you want the rows to be divided the same way every time. The default value is 0, meaning that a starting seed is generated based on the system clock. This can lead to slightly different results each time you run the experiment.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/partition-and-sample
NEW QUESTION # 74 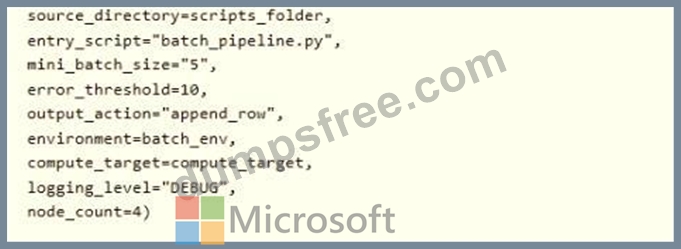
You need to obtain the output from the pipeline execution. Where will you find the output?
Answer: D
Explanation:
output_action (str): How the output is to be organized. Currently supported values are ' append_row ' and ' summary_only ' .
' append_row ' - All values output by run() method invocations will be aggregated into one unique file named parallel_run_step.txt that is created in the output location.
' summary_only '
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-contrib-pipeline-steps/azureml.contrib.pipeline.steps.
parallelrunconfig
NEW QUESTION # 75
You create an Azure Machine Learning workspace and set up a development environment. You plan to train a deep neural network (DNN) by using the Tensorflow framework and by using estimators to submit training scripts.
You must optimize computation speed for training runs.
You need to choose the appropriate estimator to use as well as the appropriate training compute target configuration.
Which values should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.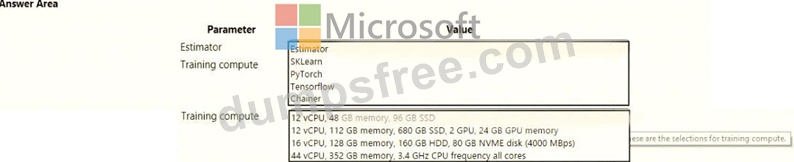
Answer:
Explanation: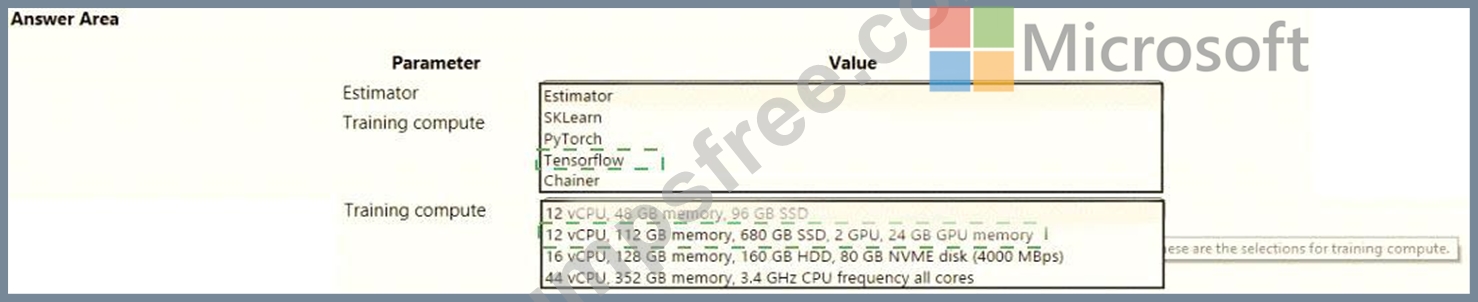
Explanation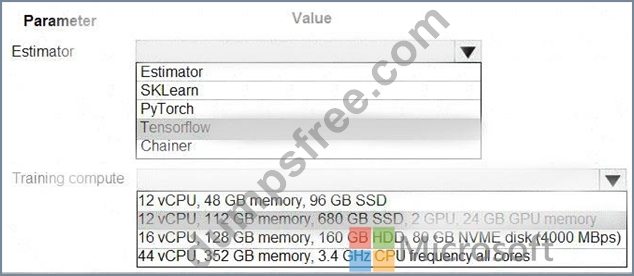
Box 1: Tensorflow
TensorFlow represents an estimator for training in TensorFlow experiments.
Box 2: 12 vCPU, 112 GB memory..,2 GPU,..
Use GPUs for the deep neural network.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-train-core/azureml.train.dnn
NEW QUESTION # 76
......
DP-100 Exam Dumps Demo: https://www.dumpsfree.com/DP-100-valid-exam.html
P.S. Free 2026 Microsoft DP-100 dumps are available on Google Drive shared by DumpsFree: https://drive.google.com/open?id=1WXrpMuFpksfq04Sirh-qi6ukNmCi7cjC