If you are still struggling to prepare for passing Databricks real exam at this moment, our ExamcollectionPass Databricks-Certified-Professional-Data-Engineer vce dumps can help you preparation easier and faster. Our website can provide you Valid Databricks-Certified-Professional-Data-Engineer Exam Cram with high pass rate to help you get certification, and then you will become a good master of certification exam.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Available Languages: | English |
| Related Certifications: | Databricks Certified Data Analyst Associate Databricks Certified Associate Developer |
| Passing Score: | 70% |
| Certificate Validity Period: | 2 years |
| Exam Format: | Multiple Select, Multiple Choice |
| Real Exam Qty: | 60 |
| Exam Price: | $200 USD |
| Exam Duration: | 90 minutes |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored exam (Pearson VUE) |
| Pre Condition: | Recommended: 6+ months of hands-on experience with Databricks and data engineering concepts; familiarity with Python or Scala and SQL is strongly recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/professional-data-engineer |
>> Exam Databricks-Certified-Professional-Data-Engineer Practice <<
The former exam candidates get the passing rate over 98 percent in recent years by choosing our Databricks-Certified-Professional-Data-Engineer practice materials. You must be curious about the advantages of them. These traits briefly sum up our Databricks-Certified-Professional-Data-Engineer study questions. So we take liberty of introducing our Databricks-Certified-Professional-Data-Engineer learning guide for you, hoping you can find the best way to pass the exam. With our Databricks-Certified-Professional-Data-Engineer exam prep, you will pass the exam with ease.
The Databricks Databricks-Certified-Professional-Data-Engineer Exam is intended for data engineers with experience in designing and implementing data solutions using Databricks. Candidates for this certification should have a good understanding of data engineering concepts, data processing frameworks, and programming languages such as Python and SQL. They should also be familiar with cloud platforms such as AWS, Azure, and Google Cloud Platform.
Databricks Certified Professional Data Engineer certification exam is a rigorous and comprehensive assessment of a candidate's knowledge and skills in data engineering. Databricks Certified Professional Data Engineer Exam certification provides a valuable credential for professionals seeking to demonstrate their expertise in designing and building data pipelines, managing data workflows, and implementing data analytics solutions using Databricks. With this certification, professionals can open up new career opportunities and demonstrate their commitment to excellence in the field of data engineering.
NEW QUESTION # 195
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below: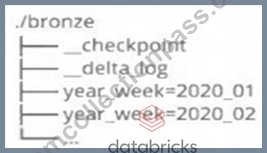
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
Answer: E
Explanation:
Explanation
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss. Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "Checkpointing" section.
NEW QUESTION # 196
The sales team has asked the Data engineering team to develop a dashboard that shows sales per-formance for all stores, but the sales team would like to use the dashboard but would like to select individual store location, which of the following approaches Data Engineering team can use to build this functionality into the dashboard.
Answer: B
Explanation:
Explanation
The answer is
Databricks supports many types of parameters in the dashboard, a drop-down list can be created based on a query that has a unique list of store locations.
Here is a simple query that takes a parameter for
SELECT * FROM sales WHERE field IN ( {{ Multi Select Parameter }} )
Or
SELECT * FROM sales WHERE field = {{ Single Select Parameter }}
Query parameter types
*Text
*Number
*Dropdown List
*Query Based Dropdown List
*Date and Time
NEW QUESTION # 197
An upstream system has been configured to pass the date for a given batch of data to the Databricks Jobs API as a parameter. The notebook to be scheduled will use this parameter to load data with the following code:
df = spark.read.format("parquet").load(f"/mnt/source/(date)")
Which code block should be used to create the date Python variable used in the above code block?
Answer: E
Explanation:
Explanation
The code block that should be used to create the date Python variable used in the above code block is:
dbutils.widgets.text("date", "null") date = dbutils.widgets.get("date") This code block uses the dbutils.widgets API to create and get a text widget named "date" that can accept a string value as a parameter1. The default value of the widget is "null", which means that if no parameter is passed, the date variable will be "null". However, if a parameter is passed through the Databricks Jobs API, the date variable will be assigned the value of the parameter. For example, if the parameter is "2021-11-01", the date variable will be "2021-11-01". This way, the notebook can use the date variable to load data from the specified path.
The other options are not correct, because:
Option A is incorrect because spark.conf.get("date") is not a valid way to get a parameter passed through the Databricks Jobs API. The spark.conf API is used to get or set Spark configuration properties, not notebook parameters2.
Option B is incorrect because input() is not a valid way to get a parameter passed through the Databricks Jobs API. The input() function is used to get user input from the standard input stream, not from the API request3.
Option C is incorrect because sys.argv1 is not a valid way to get a parameter passed through the Databricks Jobs API. The sys.argv list is used to get the command-line arguments passed to a Python script, not to a notebook4.
Option D is incorrect because dbutils.notebooks.getParam("date") is not a valid way to get a parameter passed through the Databricks Jobs API. The dbutils.notebooks API is used to get or set notebook parameters when running a notebook as a job or as a subnotebook, not when passing parameters through the API5.
References: Widgets, Spark Configuration, input(), sys.argv, Notebooks
NEW QUESTION # 198
The data science team has created and logged a production using MLFlow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, load the customer table containing the customer_id key column into a Dataframe, and defines the feature columns needed for the model.
Which code block will output DataFrame with the schema'' customer_id LONG, predictions DOUBLE''?
Answer: A
Explanation:
Given the information that the model is registered with MLflow and assuming predict is the method used to apply the model to a set of columns, we use the model.predict() function to apply the model to the DataFrame df using the specified columns. The model.predict() function is designed to take in a DataFrame and a list of column names as arguments, applying the trained model to these features to produce a predictions column.
When working with PySpark, this predictions column needs to be selected alongside the customer_id to create a new DataFrame with the schema customer_id LONG, predictions DOUBLE.
References:
* MLflow documentation on using Python function models:
https://www.mlflow.org/docs/latest/models.html#python-function-python
* PySpark MLlib documentation on model prediction:
https://spark.apache.org/docs/latest/ml-pipeline.html#pipeline
NEW QUESTION # 199
How do you check the location of an existing schema in Delta Lake?
Answer: A
Explanation:
Explanation
Here is an example of how it looks
Graphical user interface, text, application, email Description automatically generated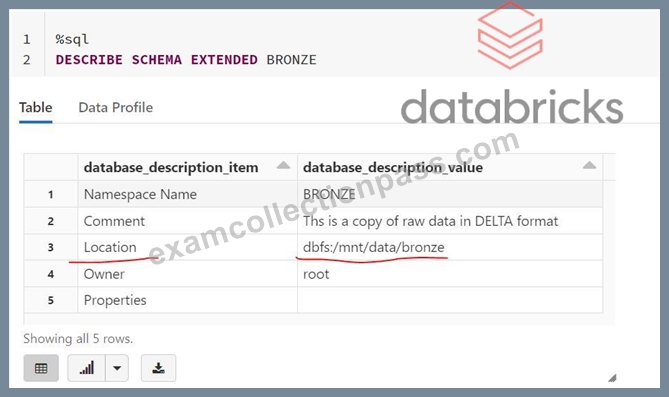
NEW QUESTION # 200
......
Databricks-Certified-Professional-Data-Engineer Current Exam Content: https://www.examcollectionpass.com/Databricks/Databricks-Certified-Professional-Data-Engineer-practice-exam-dumps.html