BONUS!!! Download part of Pass4sures Databricks-Certified-Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1rkUUx-df94K-D-RB516zy5GYHG1vN5AD
As we all know, no pain, no gain. If you want to enter a better company, you must have the competitive force. Databricks-Certified-Data-Engineer-Associate learning materials will offer you such opportunity to pass the exam and get the certificate successfully, so that you can improve your competitive force. Also, you need to spend certain time on practicing the Databricks-Certified-Data-Engineer-Associate Exam Dumps, so that you can get the certificate at last. Besides, we pass guarantee and money back guarantee if you fail to pass the exam after buying Databricks-Certified-Data-Engineer-Associate learning materials. We also offer you free update for one year, and the update version will be sent to your email automatically.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Governance & Quality | 11% | - Unity Catalog implementation
|
| Topic 2: Development and Ingestion | 30% | - Data ingestion patterns and methods
|
| Topic 3: Productionizing Data Pipelines | 18% | - Deployment and CI/CD
|
| Topic 4: Data Processing & Transformations | 31% | - Data transformation techniques
|
| Topic 5: Databricks Intelligence Platform | 10% | - Platform architecture and core concepts
|
>> Databricks-Certified-Data-Engineer-Associate Exam Passing Score <<
Have you learned Pass4sures Databricks Databricks-Certified-Data-Engineer-Associate exam dumps? Why do the people that have used Pass4sures dumps sing its praises? Do you really want to try it whether it have that so effective? Hurry to click Pass4sures.com to download our certification training materials. Every question provides you with demo and if you think our exam dumps are good, you can immediately purchase it. After you purchase Databricks-Certified-Data-Engineer-Associate Exam Dumps, you will get a year free updates. Within a year, only if you would like to update the materials you have, you will get the newer version. With the dumps, you can pass Databricks Databricks-Certified-Data-Engineer-Associate test with ease and get the certificate.
NEW QUESTION # 43
Which of the following must be specified when creating a new Delta Live Tables pipeline?
Answer: B
Explanation:
Option E is the correct answer because it is the only mandatory requirement when creating a new Delta Live Tables pipeline. A pipeline is a data processing workflow that contains materialized views and streaming tables declared in Python or SQL source files. Delta Live Tables infers the dependencies between these tables and ensures updates occur in the correct order. To create a pipeline, you need to specify at least one notebook library to be executed, which contains the Delta Live Tables syntax. You can also specify multiple libraries of different languages within your pipeline. The other options are optional or not applicable for creating a pipeline. Option A is not required, but you can optionally provide a key-value pair configuration to customize the pipeline settings, such as the storage location, the target schema, the notifications, and the pipeline mode.
Option B is not applicable, as the DBU/hour cost is determined by the cluster configuration, not the pipeline creation. Option C is not required, but you can optionally specify a storage location for the output data from the pipeline. If you leave it empty, the system uses a default location. Option D is not required, but you can optionally specify a location of a target database for the written data, either in the Hive metastore or the Unity Catalog.
References: Tutorial: Run your first Delta Live Tables pipeline, What is Delta Live Tables?, Create a pipeline, Pipeline configuration.
NEW QUESTION # 44
A data architect has determined that a table of the following format is necessary: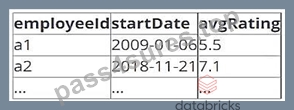
Which of the following code blocks uses SQL DDL commands to create an empty Delta table in the above format regardless of whether a table already exists with this name?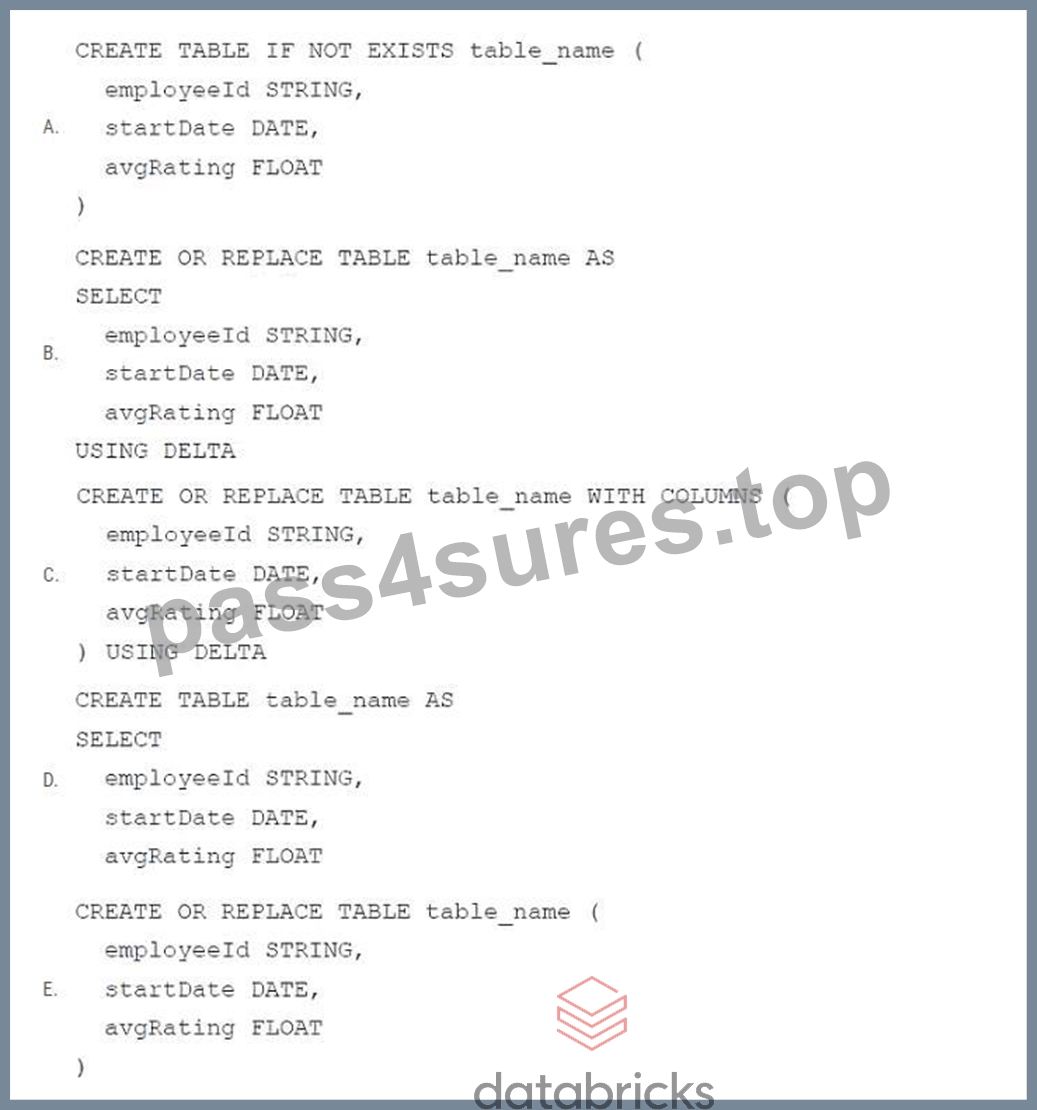
Answer: B
Explanation:
Create a table using SQL | Databricks on AWS, Create a table using SQL - Azure Databricks, Delta Lake Quickstart - Azure Databricks
NEW QUESTION # 45
A data engineer is designing a data pipeline. The source system generates files in a shared directory that is also used by other processes. As a result, the files should be kept as is and will accumulate in the directory. The data engineer needs to identify which files are new since the previous run in the pipeline, and set up the pipeline to only ingest those new files with each run.
Which of the following tools can the data engineer use to solve this problem?
Answer: E
Explanation:
Auto Loader is a tool that can incrementally and efficiently process new data files as they arrive in cloud storage without any additional setup. Auto Loader provides a Structured Streaming source called cloudFiles, which automatically detects and processes new files in a given input directory path on the cloud file storage. Auto Loader also tracks the ingestion progress and ensures exactly-once semantics when writing data into Delta Lake. Auto Loader can ingest various file formats, such as JSON, CSV, XML, PARQUET, AVRO, ORC, TEXT, and BINARYFILE. Auto Loader has support for both Python and SQL in Delta Live Tables, which are a declarative way to build production-quality data pipelines with Databricks. Reference: What is Auto Loader?, Get started with Databricks Auto Loader, Auto Loader in Delta Live Tables
NEW QUESTION # 46
A data engineer is maintaining an ETL pipeline code with a GitHub repository linked to their Databricks account. The data engineer wants to deploy the ETL pipeline to production as a databricks workflow. Which approach should the data engineer use?
Answer: A
Explanation:
The best practice for deploying ETL pipelines to production is to use Databricks Asset Bundles (DAB) with GitHub integration. DAB provides a declarative YAML-based structure for defining workflows and resources, supports CI/CD, and integrates seamlessly with GitHub, enabling version-controlled, automated deployments to production.
NEW QUESTION # 47
A data engineer has developed a data pipeline to ingest data from a JSON source using Auto Loader, but the engineer has not provided any type inference or schema hints in their pipeline. Upon reviewing the data, the data engineer has noticed that all of the columns in the target table are of the string type despite some of the fields only including float or boolean values.
Which of the following describes why Auto Loader inferred all of the columns to be of the string type?
Answer: D
NEW QUESTION # 48
......
Do you feel headache looking at so many IT certification exams and so many exam materials? What should you do? Which materials do you choose? If you don't know how to choose, I choose your best exam materials for you. You can choose to attend Databricks Databricks-Certified-Data-Engineer-Associate exam which is the most popular in recent. Getting Databricks-Certified-Data-Engineer-Associate certificate, you will get great benefits. Moreover, to effectively prepare for the exam, you can select Pass4sures Databricks Databricks-Certified-Data-Engineer-Associate certification training dumps which are the best way to pass the test.
Reliable Databricks-Certified-Data-Engineer-Associate Test Notes: https://www.pass4sures.top/Databricks-Certification/Databricks-Certified-Data-Engineer-Associate-testking-braindumps.html
BONUS!!! Download part of Pass4sures Databricks-Certified-Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1rkUUx-df94K-D-RB516zy5GYHG1vN5AD