2026 Test Certified-Data-Engineer-Professional Voucher 100% Pass | High Pass-Rate Databricks Exam Databricks Certified Data Engineer Professional Price Pass for sure

We are constantly updating our Databricks Certified-Data-Engineer-Professional practice material to ensure that students receive the latest Certified-Data-Engineer-Professional questions based on the actual Databricks Certified Data Engineer Professional exam content. Moreover, we also offer up to 1 year of free updates and free demos. Free4Torrent also offers a money-back guarantee (terms and conditions apply) for applicants who fail to pass the Certified-Data-Engineer-Professional test on the first try.
| Section | Objectives |
|---|
| Topic 1: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Ingest data from message buses and cloud storage
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Topic 2: Ensuring Data Security and Compliance | - Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Apply anonymization and pseudonymization techniques
- Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
|
| Topic 3: Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
- Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
|
| Topic 4: Data Modelling | - Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Design and implement scalable data models using Delta Lake
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Topic 5: Debugging and Deploying | - Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Analyze errors and remediate failed job runs
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
|
| Topic 6: Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Topic 7: Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Apply data skipping and file pruning techniques
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
|
| Topic 8: Monitoring and Alerting | - Monitoring
- 1. Use system tables for resource, cost, audit, and workload monitoring
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 4. Use Query Profiler and Spark UI to monitor workloads
- Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
|
| Topic 9: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Share live Lakehouse data with external computing platforms
- 3. Configure Databricks-to-Databricks Sharing
|
| Topic 10: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Manage and troubleshoot third-party library installations and dependencies
- Building and Testing ETL Pipelines
- 1. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 2. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 3. Develop unit and integration tests for data processing code
- 4. Use APPLY CHANGES APIs for change data capture
- 5. Use control flow operators in pipeline components
- 6. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 7. Configure environments, dependencies, memory, and retry behavior
- 8. Compare streaming tables and materialized views
|
>> Test Certified-Data-Engineer-Professional Voucher <<
Exam Certified-Data-Engineer-Professional Price - Certified-Data-Engineer-Professional Test Tutorials
We have created a number of reports and learning functions for evaluating your proficiency for the Certified-Data-Engineer-Professional exam dumps. In preparation, you can optimize Certified-Data-Engineer-Professional practice exam time and question type by utilizing our Certified-Data-Engineer-Professional Practice Test Free4Torrent. Free4Torrent makes it easy to download Certified-Data-Engineer-Professional exam questions immediately after purchase. You will receive a registration code and download instructions via email.
Databricks Certified Data Engineer Professional Sample Questions (Q15-Q20):
NEW QUESTION # 15
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.

Which command should be removed from the notebook before scheduling it as a job?
- A. Cmd 5
- B. Cmd 6
- C. Cmd 4
- D. Cmd 2
- E. Cmd 3
Answer: B
Explanation:
When scheduling a Databricks notebook as a job, it's generally recommended to remove or modify commands that involve displaying output, such as using the display() function. Displaying data using display() is an interactive feature designed for exploration and visualization within the notebook interface and may not work well in a production job context.
The finalDF.explain() command, which provides the execution plan of the DataFrame transformations and actions, is often useful for debugging and optimizing queries. While it doesn't display interactive visualizations like display(), it can still be informative for understanding how Spark is executing the operations on your DataFrame.
NEW QUESTION # 16
A user wants to use DLT expectations to validate that a derived table report contains all records from the source, included in the table validation_copy.
The user attempts and fails to accomplish this by adding an expectation to the report table definition.

Which approach would allow using DLT expectations to validate all expected records are present in this table?
- A. Define a SQL UDF that performs a left outer join on two tables, and check if this returns null values for report key values in a DLT expectation for the report table.
- B. Define a function that performs a left outer join on validation_copy and report and report, and check against the result in a DLT expectation for the report table
- C. Define a view that performs a left outer join on validation_copy and report, and reference this view in DLT expectations for the report table
- D. Define a temporary table that perform a left outer join on validation_copy and report, and define an expectation that no report key values are null
Answer: C
Explanation:
To validate that all records from the source are included in the derived table, creating a view that performs a left outer join between the validation_copy table and the report table is effective. The view can highlight any discrepancies, such as null values in the report table's key columns, indicating missing records. This view can then be referenced in DLT (Delta Live Tables) expectations for the report table to ensure data integrity. This approach allows for a comprehensive comparison between the source and the derived table.
NEW QUESTION # 17
A data engineer manages a production Lakeflow Declarative Pipeline that processes customer transaction data. The pipeline includes several data quality expectations such as transaction_amount > 0 and customer_id IS NOT NULL. These expectations are defined using the EXPECT clause in SQL.
The engineer aims to monitor the pipeline's data quality by analyzing the number of records that passed or failed each expectation during the latest pipeline update. The Lakeflow Declarative Pipelines event logs are stored in a Delta table named event_log_table.
For the most recent pipeline update, determine a programmatically appropriate approach to extract information like the name of each expectation, associated dataset, count of records that passed the expectation, and count of records that failed the expectation.
Which method retrieves the desired data quality metrics from the Lakeflow Declarative Pipelines event log?
- A. Query the event_log_table for events with event_type = 'data_quality' and directly select the passed_records and failed_records fields.
- B. Access the event_log_table, filter for events where event_type = 'expectation_result', and extract the expectation metrics from the details field.
- C. Access the event_log_table, filter for events where event_type = 'flow_progress', and parse details.flow_progress.data_quality.expectations field to extract the required metrics.
- D. Use the Lakeflow Declarative Pipelines UI to navigate to the specific pipeline, select the dataset, and view the Data Quality tab to manually retrieve the expectation metrics.
Answer: B
Explanation:
The Databricks documentation specifies that for Lakeflow Declarative Pipelines, detailed data quality metrics are logged as events of type expectation_result within the event log. Each record of this type contains fields including expectation_name, dataset_name, passed_records, and failed_records. Filtering on event_type = 'expectation_result' and expanding the details field allows retrieving metrics for each expectation from the most recent pipeline update. While flow_progress provides summary statistics and data_quality events aggregate results, only expectation_result events provide granular, per-expectation metrics required for audit and monitoring automation.
NEW QUESTION # 18
A data engineer is building a Lakeflow Declarative Pipelines pipeline to process healthcare claims data. A metadata JSON file defines data quality rules for multiple tables, including:
{
"claims": [
{"name": "valid_patient_id", "constraint": "patient_id IS NOT NULL"},
{"name": "non_negative_amount", "constraint": "claim_amount >= 0"}
]
}
The pipeline must dynamically apply these rules to the claims table without hardcoding the rules.
How should the data engineer achieve this?
- A. Load the JSON metadata, loop through its entries, and apply expectations using dlt.expect_all.
- B. Invoke an external API to validate records against the metadata rules.
- C. Reference each expectation with @dlt.expect decorators in the table declaration.
- D. Use a SQL CONSTRAINT block referencing the JSON file path.
Answer: A
Explanation:
Lakeflow Declarative Pipelines provide the expect_all method for programmatically applying multiple data quality expectations at once. The documentation explains that @dlt.expect_all accepts a dictionary of expectation names mapped to SQL constraints, allowing rules to be dynamically loaded from metadata such as JSON files. This ensures that pipelines remain maintainable and scalable without needing to hardcode individual @dlt.expect decorators. The event logs will track each expectation's pass and fail counts individually, making it auditable.
NEW QUESTION # 19
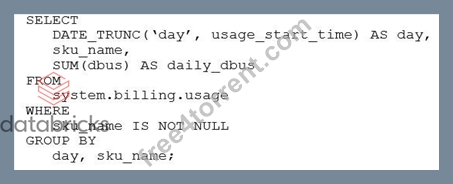
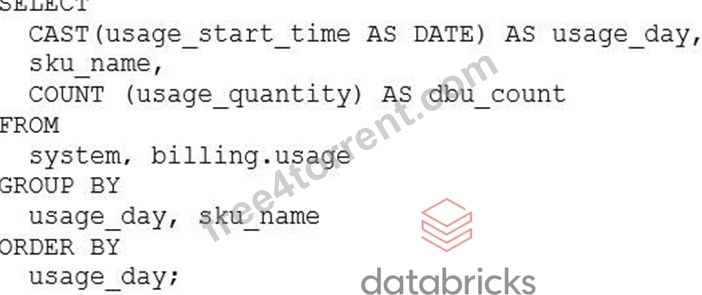
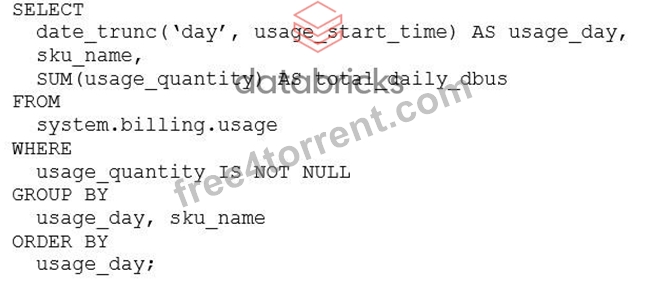
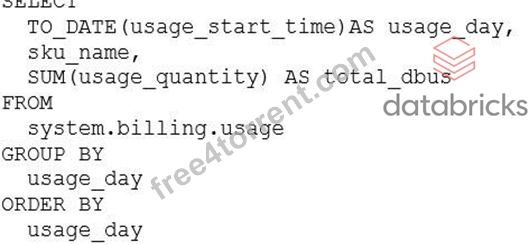
A platform engineer needs to report the resource consumption, categorized by SKU tier, across all workspaces. The engineer decides to use the system.billing.usage system table to create a query. Which SQL query will accurately return the daily usage by product?
Answer: C
Explanation:
This query correctly aggregates usage at a daily granularity by truncating the usage start timestamp to the day and summing the usage quantity, which represents DBUs. Grouping by both the derived daily value and the SKU name ensures usage is accurately categorized by product tier across all workspaces.
NEW QUESTION # 20
......
Our Certified-Data-Engineer-Professional test question with other product of different thing is we have the most core expert team to update our Certified-Data-Engineer-Professional study materials, learning platform to changes with the change of the exam outline. If not timely updating Certified-Data-Engineer-Professional training materials will let users reduce the learning efficiency of even lags behind that of other competitors, the consequence is that users and we don't want to see the phenomenon of the worst, so in order to prevent the occurrence of this kind of risk, the Certified-Data-Engineer-Professional Practice Test materials give supervision and update the progress every day, it emphasized the key selling point of the product.
Exam Certified-Data-Engineer-Professional Price: https://www.free4torrent.com/Certified-Data-Engineer-Professional-braindumps-torrent.html
- Certified-Data-Engineer-Professional Exam Question 👌 Exam Certified-Data-Engineer-Professional Guide 👋 Certified-Data-Engineer-Professional Exam Fee 🌈 Simply search for 「 Certified-Data-Engineer-Professional 」 for free download on ⇛ www.easy4engine.com ⇚ 🥉Valid Certified-Data-Engineer-Professional Exam Pass4sure
- 2026 Test Certified-Data-Engineer-Professional Voucher | Accurate Certified-Data-Engineer-Professional 100% Free Exam Price 🔥 Download 「 Certified-Data-Engineer-Professional 」 for free by simply entering ✔ www.pdfvce.com ️✔️ website 🥀Valid Test Certified-Data-Engineer-Professional Braindumps
- 2026 Test Certified-Data-Engineer-Professional Voucher | Accurate Certified-Data-Engineer-Professional 100% Free Exam Price 🐜 Open “ www.examdiscuss.com ” and search for ✔ Certified-Data-Engineer-Professional ️✔️ to download exam materials for free 🛌Certified-Data-Engineer-Professional Dumps Download
- Certified-Data-Engineer-Professional Mock Exams 🔰 Certified-Data-Engineer-Professional Reliable Braindumps Questions 🤨 Certified-Data-Engineer-Professional Reliable Exam Topics 🏌 Open ➽ www.pdfvce.com 🢪 and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download exam materials for free ⭐Certified-Data-Engineer-Professional Mock Exams
- Valid Test Certified-Data-Engineer-Professional Braindumps ❗ Exam Certified-Data-Engineer-Professional Consultant 🛄 Certified-Data-Engineer-Professional Latest Exam Question 🕦 Search on ☀ www.prepawaypdf.com ️☀️ for ▷ Certified-Data-Engineer-Professional ◁ to obtain exam materials for free download 📗Certified-Data-Engineer-Professional Book Free
- Pass Guaranteed 2026 Newest Databricks Certified-Data-Engineer-Professional: Test Databricks Certified Data Engineer Professional Voucher 🎇 Search for ➥ Certified-Data-Engineer-Professional 🡄 on ➠ www.pdfvce.com 🠰 immediately to obtain a free download 🍕Certified-Data-Engineer-Professional Exam Question
- Examcollection Certified-Data-Engineer-Professional Questions Answers 💆 Certified-Data-Engineer-Professional Exam Fee 🚻 Certified-Data-Engineer-Professional Reliable Braindumps Questions 😘 Search for ➡ Certified-Data-Engineer-Professional ️⬅️ and download exam materials for free through 《 www.examdiscuss.com 》 🆕Certified-Data-Engineer-Professional Dumps Download
- Pass Guaranteed Quiz Certified-Data-Engineer-Professional - High Pass-Rate Test Databricks Certified Data Engineer Professional Voucher 🍇 Copy URL “ www.pdfvce.com ” open and search for 【 Certified-Data-Engineer-Professional 】 to download for free 🎤Certified-Data-Engineer-Professional Reliable Exam Topics
- 2026 Test Certified-Data-Engineer-Professional Voucher | Accurate Certified-Data-Engineer-Professional 100% Free Exam Price 🎄 Open website 【 www.practicevce.com 】 and search for ☀ Certified-Data-Engineer-Professional ️☀️ for free download 🏗Certified-Data-Engineer-Professional Mock Exams
- Certified-Data-Engineer-Professional Reliable Practice Materials 👊 Certified-Data-Engineer-Professional Mock Exams 🛵 Passing Certified-Data-Engineer-Professional Score Feedback 🔍 Search on ▛ www.pdfvce.com ▟ for ➡ Certified-Data-Engineer-Professional ️⬅️ to obtain exam materials for free download 🧵Examcollection Certified-Data-Engineer-Professional Questions Answers
- Pass Guaranteed Quiz Certified-Data-Engineer-Professional - High Pass-Rate Test Databricks Certified Data Engineer Professional Voucher 🧩 Easily obtain ➥ Certified-Data-Engineer-Professional 🡄 for free download through ▛ www.prep4away.com ▟ 🐂Valid Certified-Data-Engineer-Professional Exam Pass4sure
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, blogfreely.net, experiment.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes