In order to let customers enjoy the best service, all AI-200 exam prep of our company were designed by hundreds of experienced experts. Our AI-200 test questions will help customers learn the important knowledge about exam. At the same time, our AI-200 test torrent can help you avoid falling into rote learning habits. You just need to spend 20 to 30 hours on study, and then you can take and pass your AI-200 Exam. In addition, the authoritative production team of our AI-200 exam prep will update the study system every day in order to make our customers enjoy the newest information.
| Section | Objectives |
|---|---|
| Develop containerized solutions on Azure | - Implement containerized applications
|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Connect to and consume Azure services | - Integrate Azure services
|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
>> AI-200 Test Collection Pdf <<
You don't have to spend all your energy to the exam because our AI-200 learning questions are very efficient. Only should you spend a little time practicing them can you pass the exam successfully. In addition, the passing rate of our AI-200 Study Materials is very high, and we are very confident to ensure your success. And we can claim that our AI-200 exam braindumps will help you pass the exam if you study with our AI-200 practice engine.
NEW QUESTION # 74
You develop an application that sells Al generated images based on user input. You recently started a marketing campaign that displays unique ads every second day.
Sales data is stored in Azure Cosmos 06 with the date of each sale being stored in a property named whenFinished ' . The marketing department requires a view that shows the number of sales grouped into two- day periods You need to implement the query for the view.
How should you complete the query? To answer, select the appropriate options in the answer area. NOTE:
Each correct selection is worth one point.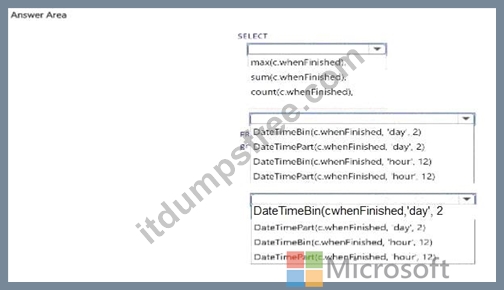
Answer:
Explanation: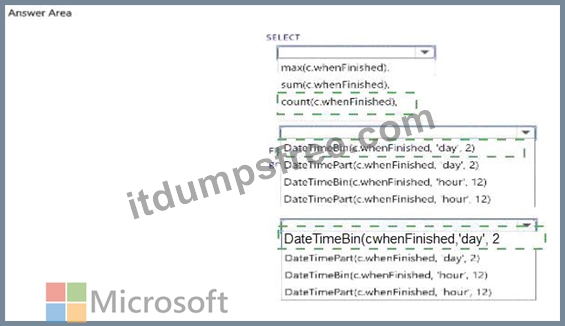
Explanation: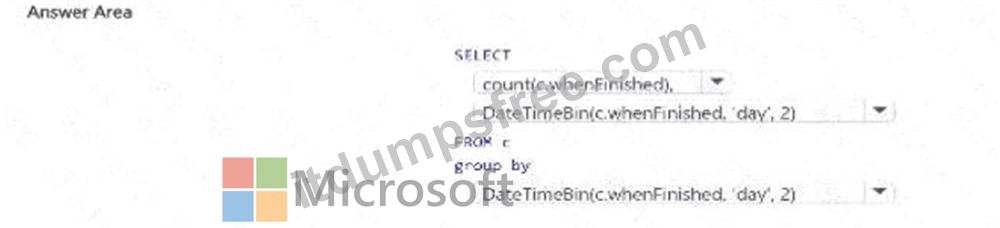
NEW QUESTION # 75
You need to troubleshoot connectivity failures between microservices running in AKS.
Which troubleshooting actions should you perform? To answer, move the appropriate action to the correct troubleshooting scenario. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
* Service fails to communicate with another service: Inspect Kubernetes service endpoints.
* Pod restarts repeatedly: Inspect container logs.
* Readiness probe failures are observed: Inspect Pod descriptions.
For a service-to-service communication failure , first inspect the Kubernetes service endpoints . Microsoft' s AKS troubleshooting guidance recommends verifying that the destination pod IP address and application port appear as endpoints for the Kubernetes Service. An empty or incorrect endpoint list commonly indicates a selector/label mismatch, incorrect port configuration, or unavailable backend pods.
For a pod that restarts repeatedly , inspect the container logs , including the previous container instance when necessary. Microsoft specifically recommends kubectl logs < pod > --previous for workloads that repeatedly restart because it exposes application errors and termination messages from the container immediately before the restart.
For readiness probe failures , inspect the Pod description by using kubectl describe pod. The description exposes the configured health probes, pod conditions, container state, and associated probe-failure events, allowing you to determine whether the probe path, port, timing, or application readiness behavior is incorrect.
Microsoft recommends reviewing kubectl describe output when pods are not Ready or health probes are failing.
Therefore, the correct mapping is service endpoints # container logs # Pod descriptions .
Study Guide references: AKS troubleshooting; Kubernetes Services and endpoints; container logging; Pod health; readiness/liveness probes; kubectl describe and kubectl logs.
NEW QUESTION # 76
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
You need to optimize vector search queries based on the technical requirements. What should you do?
Answer: A
Explanation:
Scenario: Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
*-> Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
To optimize vector similarity queries that must be performed only against products satisfying mandatory metadata constraints, you should Create a B-tree index on metadata filter columns.
1. Evaluate Query Execution OrderIn PostgreSQL with pgvector, combining metadata filters with vector similarity searches often triggers a multi-stage execution plan. When metadata filtering is highly restrictive, creating a B-tree index allows the database engine to quickly narrow down the row scanned before or during the vector evaluation, preventing a costly full-table scan.
2. Assess Indexing Trade-offs
B-tree Index (Metadata): Directly addresses the requirement that vector calculations must be performed only against products satisfying mandatory metadata constraints. It optimizes the metadata filtering step, significantly reducing compute overhead and isolating the target rows for vector processing.
IVFFlat Index (Vector): While an IVFFlat index speeds up high-dimensional approximate nearest neighbor (ANN) searches, it divides vectors into lists. If a metadata filter is applied after an IVFFlat index scan, it can lead to severe recall degradation or inaccurate results because rows matching the metadata might reside in unsearched vector lists. (Note: For newer workloads, HNSW is generally preferred over IVFFlat for better recall and performance, but regular B-trees remain vital for the metadata layer).
3. Ensure Index Residency in RAM
By isolating the dataset using a compact B-tree index on metadata columns, you minimize the active working set. This helps fulfill your operational requirement to ensure that high-dimensional vector indexes and target rows remain resident in RAM for efficient mathematical throughput.
Reference:
https://www.applied-ai.com/briefings/enterprise-rag-architecture/
NEW QUESTION # 77
You are developing a Java application to be deployed in Azure. The application stores sensitive data in Azure Cosmos DB.
You need to configure Always Encrypted to encrypt the sensitive data inside the application.
What should you do first?
Answer: B
Explanation:
To configure Always Encrypted (client-side encryption) for your Java application using Azure Cosmos DB, you must first create a customer-managed key (CMK) and store it in a new Azure Key Vault instance Reference:
https://lennilobel.wordpress.com/2022/08/20/configuring-client-side-encryption-aka-always-encrypted-in-azure-cosmos-db/
NEW QUESTION # 78
A Python API retrieves a document from Azure Database for PostgreSQL by using a SQL statement. The API accepts the document ID from user input. The current implementation inserts the document ID directly into the SQL statement.
You need to secure the SQL statement execution by using a parameterized query. You must minimize the possibility of SQL injection.
How should you update the implementation to execute the SQL statement safely? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. you may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.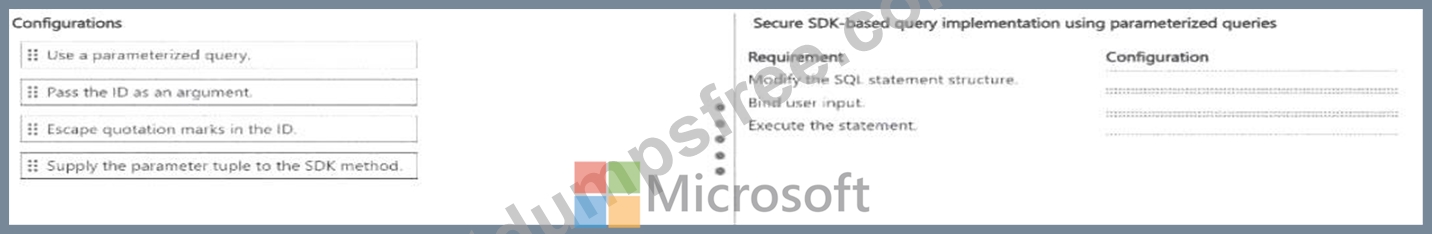
Answer:
Explanation:
Explanation:
Verified Answer: Modify SQL: use a parameterized query. Bind input: pass the ID as an argument. Execute:
supply the parameter tuple to the SDK/driver method.
Detailed Explanation: The security boundary is created by separating SQL syntax from user-supplied values.
The statement should contain a parameter placeholder rather than concatenated input, and the document ID should be supplied separately through the database driver's parameter mechanism. The driver then performs the correct protocol-level binding and escaping. Manually escaping quotation marks is error-prone and does not provide the same injection resistance as true parameterization.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector similarity search with Azure PostgreSQL
NEW QUESTION # 79
......
Getting the related AI-200 certification in your field will be the most powerful way for you to show your professional knowledge and skills. However, it is not easy for the majority of candidates to prepare for the AI-200 exam in order to pass it, if you are one of the candidates who are worrying about the exam now, congratulations, you can have our AI-200 Study Tool. We can assure you that you can pass the exam as well as getting the related certification in a breeze with the guidance of our AI-200 test torrent.
AI-200 Reliable Study Materials: https://www.itdumpsfree.com/AI-200-exam-passed.html