BTW, DOWNLOAD part of Pass4suresVCE DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=1DbITbhpCBAQ4kipohODjr7WKnmtZYiAX
With DP-750 study tool, you no longer need to look at a drowsy textbook. You do not need to study day and night. With DP-750 learning dumps, you only need to spend 20-30 hours on studying, and then you can easily pass the exam. At the same time, the language in DP-750 test question is very simple and easy to understand. Even if you are a newcomer who has just entered the industry, you can learn all the knowledge points without any obstacles. We believe that DP-750 Study Tool will make you fall in love with learning. Come and buy it now.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Prepare and process data | 30–35% | - Optimize and manage data storage
|
In this era of the latest technology, we should incorporate interesting facts, figures, visual graphics, and other tools that can help people read the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam questions with interest. Pass4suresVCE uses pictures that are related to the DP-750 certification exam and can even add some charts, and graphs that show the numerical values. It will not let the reader feel bored with the DP-750 Practice Test. They can engage their attention in Microsoft DP-750 exam visual effects and pictures that present a lot of.
NEW QUESTION # 43
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.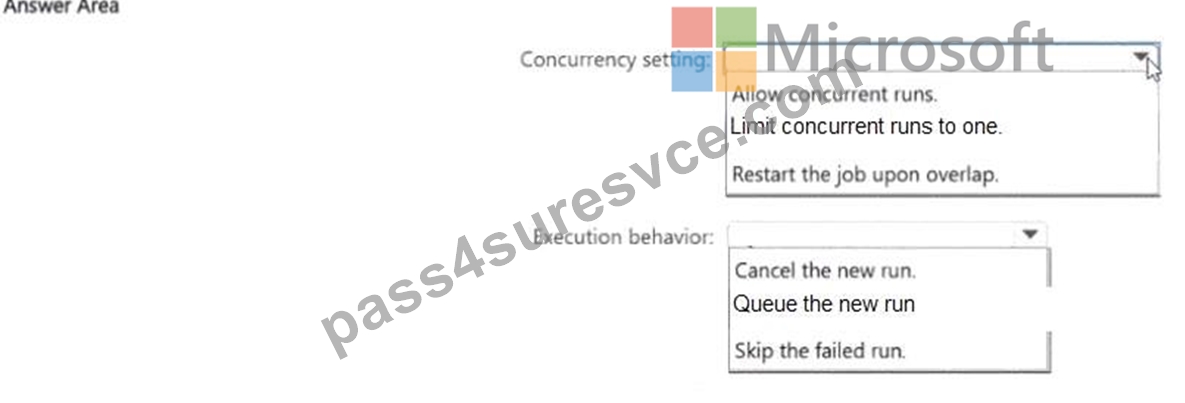
Answer:
Explanation: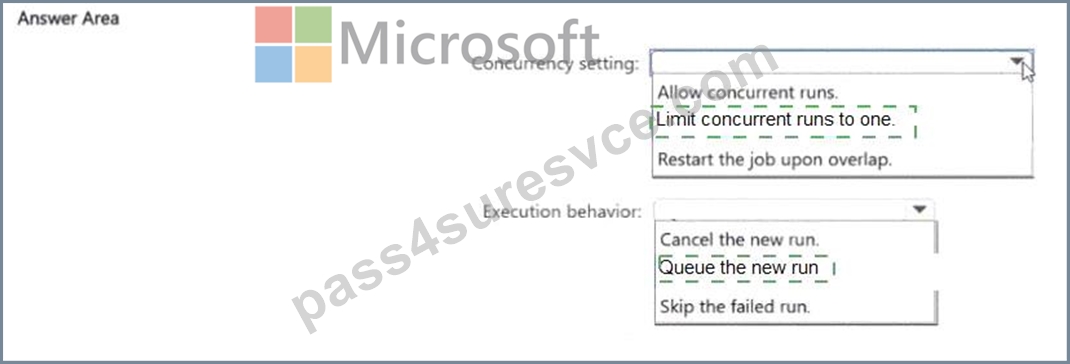
Explanation:
Two settings address the overlapping-run problem:
Concurrent Runs policy set to 'Skip' (or 'Allow only one concurrent run'). When a new scheduled trigger fires while the previous run is still in progress, the new run is skipped rather than starting alongside the ongoing one. This prevents two runs from writing to the same tables at the same time - which is the data corruption risk the question highlights.
Cron-based schedule for the hourly trigger. A cron expression defines the regular execution cadence.
Combined with the concurrency setting, the job runs hourly but never overlaps.
An alternative to 'Skip' is 'Wait' (queue the new run), which ensures every scheduled run eventually executes
- but for this scenario where overlapping is the primary concern, skipping the missed run is typically preferable to building up a queue of back-to-back executions.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#concurrent-runs
NEW QUESTION # 44
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to share curated data with an external organization. The solution must meet the following requirements:
* The organization will use its own compute platform to query the data.
* Access to the data must be centrally governed by using Unity Catalog.
* Administrative effort must be minimized.
What should you do?
Answer: E
Explanation:
Delta Sharing is designed to share governed data securely with recipients outside an Azure Databricks workspace. The external organization can query the shared data from its own compatible compute platform without receiving workspace access or requiring a Databricks SQL warehouse. Unity Catalog centrally controls which tables, views, or other objects are included in the share and which recipients can access them.
Moving files to an SFTP server creates additional copies and requires custom transfer and security administration. Lakeflow Connect is intended for ingesting data into Databricks rather than sharing curated data externally. Granting workspace access or creating a SQL warehouse would require the recipient to use Databricks-managed resources. Delta Sharing therefore provides the required open access model, centralized governance, and minimal administrative effort.
NEW QUESTION # 45
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount.isNotNull())
Does this meet the goal?
Answer: B
Explanation:
The correct answer is A - Yes.
df.filter(df.order_amount.isNotNull()) is the correct PySpark pattern for excluding null rows. The isNotNull() method is a Column method that returns True for every row where order_amount has a value and False for rows where it is null. Spark ' s filter keeps only the rows where the condition evaluates to True, producing a DataFrame with all null order_amount rows removed.
This works correctly because isNotNull() is explicitly null-aware - unlike the != None comparison in Q52, it doesn ' t rely on Python equality semantics. Under the hood it maps to the SQL expression order_amount IS NOT NULL, which is unambiguous in both SQL and Spark.
Both df.filter(df.order_amount.isNotNull()) and df.dropna(subset=[ ' order_amount ' ]) produce identical results. The choice between them is stylistic - isNotNull() reads more explicitly as a filter condition, while dropna is more compact when handling multiple columns.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 46
Hotspot Question
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming. The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.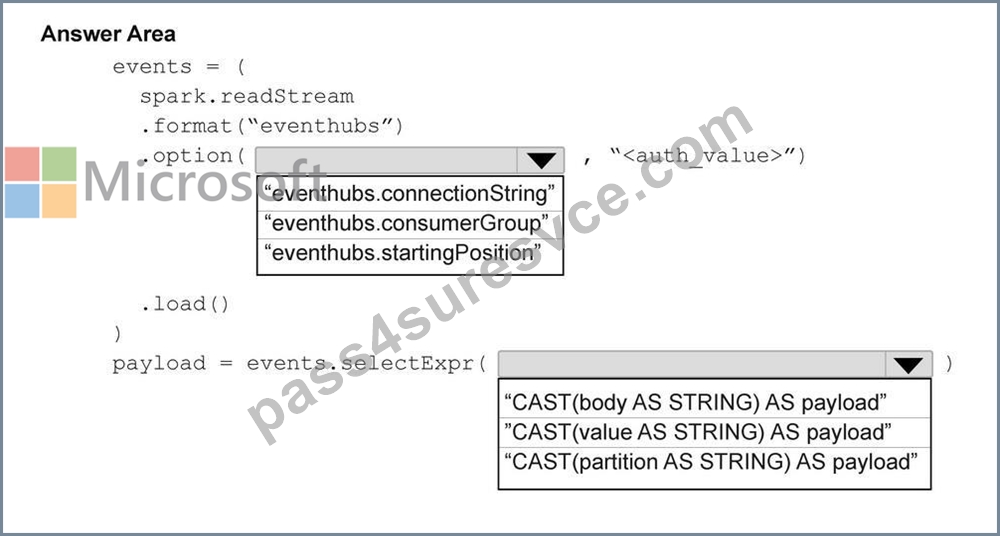
Answer:
Explanation: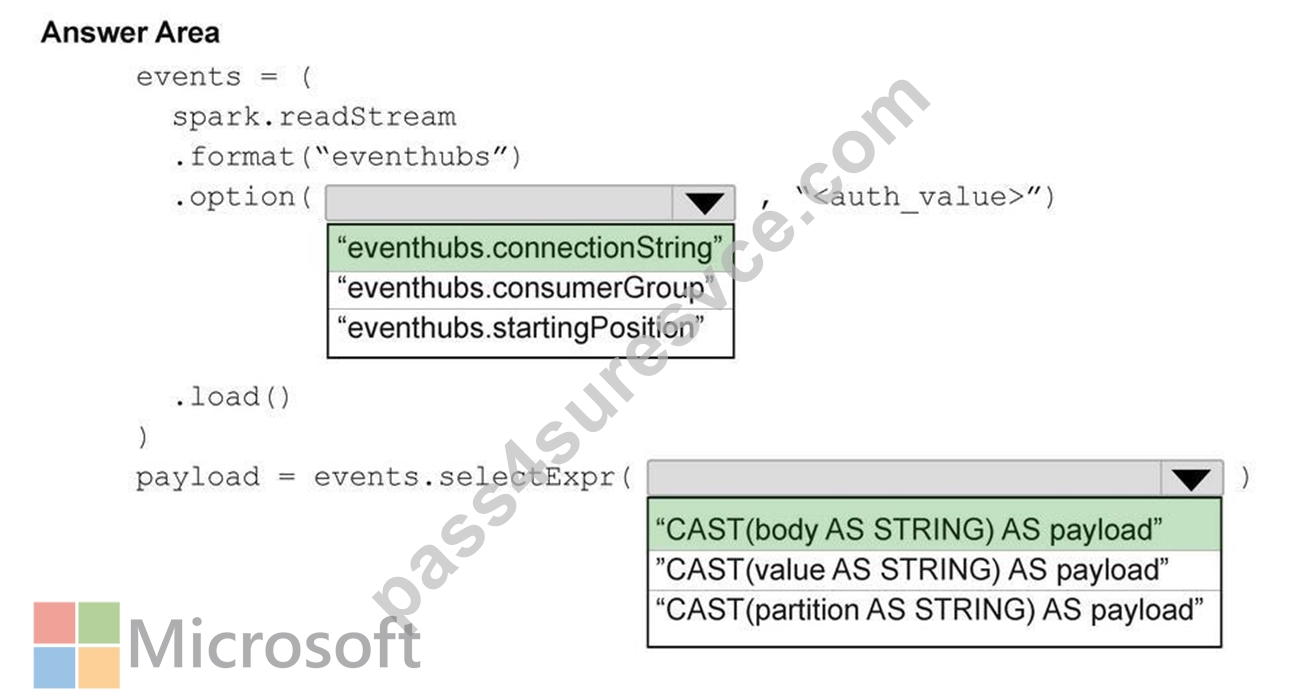
NEW QUESTION # 47
You have an Azure Databricks workspace.
You have an Apache Spark Structured Streaming job named Job! that processes data continuously and fails periodically due to transient errors You need to ensure that Job! meets the following requirements
* Resumes processing from the point that Job1 failed
* Minimizes how long it takes to restart Job!
* Minimizes the costs to restart Job!
What should you do?
Answer: D
Explanation:
The correct answer is B - implement checkpointing.
A checkpoint is a durable record of the streaming job's progress written to ADLS Gen2 or DBFS after each successfully committed micro-batch. When the job restarts after a transient failure, it reads the checkpoint to find the last committed offset and resumes from that exact point - no data is reprocessed, no data is lost.
This satisfies all three requirements directly: checkpointing enables resumption from the failure point (not from the beginning), restart is fast because there's no replay overhead, and costs are minimised because no compute is wasted reprocessing records already handled.
Option A (decrease retry interval) makes the job retry sooner but doesn't control where it resumes from.
Option C (alert and manual restart) adds human latency and doesn't prevent reprocessing without a checkpoint. Option D (increase minimum nodes) reduces the likelihood of resource-related failures but increases cost and doesn't address the recovery behaviour itself.
Reference: https://learn.microsoft.com/en-us/azure/databricks/structured-streaming/query-recovery
NEW QUESTION # 48
......
Our DP-750 study materials are the representative masterpiece and leading in the quality, service and innovation. We collect the most important information about the test DP-750 certification and supplement new knowledge points which are produced and compiled by our senior industry experts and authorized lecturers and authors. We provide the auxiliary functions such as the function to stimulate the real exam to help the clients learn our DP-750 Study Materials efficiently.
Latest DP-750 Exam Topics: https://www.pass4suresvce.com/DP-750-pass4sure-vce-dumps.html
BTW, DOWNLOAD part of Pass4suresVCE DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=1DbITbhpCBAQ4kipohODjr7WKnmtZYiAX