P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Exam4Free: https://drive.google.com/open?id=189JJnbUNqD4jUN-7O-NIk2zGrX7RAxSI
As for buying Databricks-Generative-AI-Engineer-Associate questions and answers for the exam, people may have different concerns. Most candidates can pass the exam by using the Databricks-Generative-AI-Engineer-Associate questions and answers of us just one time, we ensure you that we will give you refund if you can’t pass. Or if you have other exams to attend, we can replace other 2 valid exam dumps for you, at the same time, if Databricks-Generative-AI-Engineer-Associate Questions and answers you buy updates, you can also get the latest version for free. You just need to send us the failure scanned, and we will replace the exam dumps or return your money to you.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Databricks-Generative-AI-Engineer-Associate Valid Exam Testking <<
Here, we provide you with the best Databricks-Generative-AI-Engineer-Associate premium study files which will improve your study efficiency and give you right direction. The content of Databricks-Generative-AI-Engineer-Associate study material is the updated and verified by IT experts. Professional experts are arranged to check and trace the Databricks Databricks-Generative-AI-Engineer-Associate update information every day. The Databricks-Generative-AI-Engineer-Associate exam guide materials are really worthy of purchase. The high quality and accurate Databricks-Generative-AI-Engineer-Associate questions & answers are the guarantee of your success.
NEW QUESTION # 82
A Generative AI Engineer is building an LLM to generate article summaries in the form of a type of poem, such as a haiku, given the article content. However, the initial output from the LLM does not match the desired tone or style.
Which approach will NOT improve the LLM's response to achieve the desired response?
Answer: B
Explanation:
The task at hand is to improve the LLM's ability to generate poem-like article summaries with the desired tone and style. Using aneutralizerto normalize the tone and style of the underlying documents (option B) will not help improve the LLM's ability to generate the desired poetic style. Here's why:
* Neutralizing Underlying Documents:A neutralizer aims to reduce or standardize the tone of input data. However, this contradicts the goal, which is to generate text with aspecific tone and style(like haikus). Neutralizing the source documents will strip away the richness of the content, making it harder for the LLM to generate creative, stylistic outputs like poems.
* Why Other Options Improve Results:
* A (Explicit Instructions in the Prompt): Directly instructing the LLM to generate text in a specific tone and style helps align the output with the desired format (e.g., haikus). This is a common and effective technique in prompt engineering.
* C (Few-shot Examples): Providing examples of the desired output format helps the LLM understand the expected tone and structure, making it easier to generate similar outputs.
* D (Fine-tuning the LLM): Fine-tuning the model on a dataset that contains examples of the desired tone and style is a powerful way to improve the model's ability to generate outputs that match the target format.
Therefore, using a neutralizer (option B) isnotan effective method for achieving the goal of generating stylized poetic summaries.
NEW QUESTION # 83
A company has a typical RAG-enabled, customer-facing chatbot on its website.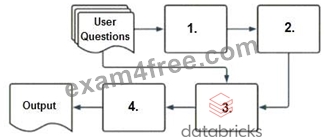
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: D
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1):The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2):The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3):The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4):Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
* B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence isembedding model, vector search, context-augmented prompt, response- generating LLM, which is option A.
NEW QUESTION # 84
A Generative AI Engineer at an automotive company would like to build a question-answering chatbot to help customers answer specific questions about their vehicles. They have:
* A catalog with hundreds of thousands of cars manufactured since the 1960s
* Historical searches with user queries and successful matches
* Descriptions of their own cars in multiple languages
They have already selected an open-source LLM and created a test set of user queries. They need to discard techniques that will not help them build the chatbot. Which do they discard?
Answer: B
Explanation:
According to Generative AI engineering standards for Retrieval-Augmented Generation (RAG), chunking strategy is a critical optimization variable. Setting the chunk size to match the model ' s maximum context window (e.g., 4k or 8k tokens) is a poor practice and should be discarded. Large chunks introduce significant
" noise " into the LLM ' s context, as only a small portion of a massive chunk usually contains the answer to a specific query. This leads to the " lost in the middle " phenomenon where LLMs struggle to extract relevant information from bloated contexts. Furthermore, large chunks reduce the precision of the vector search.
Standard best practices involve using smaller, semantically meaningful chunks (typically 256-512 tokens) with overlap to maintain context. In contrast, metadata filtering (B) is essential for narrowing searches to specific car years, fine-tuning embeddings (C) improves retrieval accuracy for domain-specific technical terms, and few-shot examples (D) guide the LLM ' s output format and tone.
NEW QUESTION # 85
A Generative AI Engineer is implementing a supervisor agent and two specialist agents in Databricks: a Sales Analyst for revenue questions and an HR Analyst for staff questions. Each specialist must retrieve data only from its own governed domain, and the engineer wants to preserve that separation using Databricks-native data access for each agent rather than building custom retrieval logic.
What should the engineer implement?
Answer: A
Explanation:
Separate Genie Spaces provide domain-specific access to structured business datasets through Databricks- native conversational querying. The Sales specialist calls the Sales Space, and the HR specialist calls the HR Space. Each Space should contain the appropriate datasets and business context, with Unity Catalog permissions enforcing access to its underlying resources. Separating Spaces makes domain boundaries explicit and avoids relying only on an LLM's routing instructions. Knowledge Assistants primarily support document-based knowledge retrieval, making Genie the better fit for structured business questions. A shared Space with distinct permissions can enforce security, but separate Spaces better express the requested domain separation. The video's phrase "HR Analyst for stock questions" appears inconsistent; "staff questions" is an inferred typing correction. Databricks documentation
NEW QUESTION # 86
A Generative AI Engineer is managing prompt templates using MLflow v3.x for a document summarization pipeline. A regulatory audit requires the team to demonstrate exactly which prompt version was used to generate outputs on a specific date three months ago, including the exact prompt text and any variables used at that time.
Which combination of MLflow v3.x capabilities allows the engineer to satisfy this audit requirement?
Answer: D
Explanation:
The Prompt Registry preserves identifiable prompt versions, allowing the team to recover the exact template associated with a historical execution. Linking inference activity to the prompt's name and version establishes which registered template the application actually used. MLflow also supports lineage between prompt versions, application versions, and execution traces. However, satisfying the entire audit requires retaining the actual runtime variable values or the fully rendered prompt in the relevant execution records. Registry history alone preserves the template, not every value substituted into it. Therefore, D is the best option, provided the logging captures those inputs. Model webhooks, experiment tags, or table history alone do not provide the same explicit prompt-version lineage and complete historical reconstruction. Databricks documentation
NEW QUESTION # 87
......
Our customers comment that the Databricks-Generative-AI-Engineer-Associate latest dumps pdf covers most questions of actual test. Most questions in our Databricks-Generative-AI-Engineer-Associate dumps valid will appear in the real test because Databricks exam prep is created based on the formal test. If you practice the Databricks-Generative-AI-Engineer-Associate Test Questions and remember the key points of study guide, the rate of you pass will reach to 95%.
Excellect Databricks-Generative-AI-Engineer-Associate Pass Rate: https://www.exam4free.com/Databricks-Generative-AI-Engineer-Associate-valid-dumps.html
P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Exam4Free: https://drive.google.com/open?id=189JJnbUNqD4jUN-7O-NIk2zGrX7RAxSI