PassTestのNutanixのNCP-MCI-7.5試験トレーニング資料はNutanixのNCP-MCI-7.5認定試験を準備するのリーダーです。PassTestの NutanixのNCP-MCI-7.5試験トレーニング資料は高度に認証されたIT領域の専門家の経験と創造を含めているものです。それは正確性が高くて、カバー率も広いです。あなたはPassTestの学習教材を購入した後、私たちは一年間で無料更新サービスを提供することができます。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Monitoring and Troubleshooting | 20% | - Health and performance monitoring
|
| Topic 2: Disaster Recovery and Data Protection | 20% | - Replication and disaster recovery
|
| Topic 3: Advanced Operations | 10% | - Automation and APIs
|
| Topic 4: VM Management | 25% | - VM lifecycle operations
|
| Topic 5: Cluster Management | 25% | - Deploy and configure clusters
|
なぜ我々はあなたが購入した前にやってみることを許しますか。なぜ我々はあなたが利用してからNutanixのNCP-MCI-7.5試験に失敗したら、全額で返金するのを承諾しますか。我々は弊社の商品があなたに試験に合格させるのを信じでいます。NutanixのNCP-MCI-7.5試験が更新するとともに我々の作成するソフトは更新しています。
質問 # 109
A six-node cluster with the Reserve Rebuild Capacity option enabled has stopped accepting write requests.
The cluster has also had several VM outages. What could the cause be?
正解:C
解説:
Nutanix documentation on rebuild capacity reservation and resilient capacity emphasizes that some storage space must remain effectively protected so the cluster can recover from failures and maintain resiliency. If a cluster consumes all capacity beyond that protected threshold, it can reach a point where it no longer safely accepts writes because continuing to do so would violate resiliency guarantees. The symptoms in the question-stopped accepting writes and VM outages-align with a cluster hitting its resilient capacity limit, not merely an EC optimization limit. ( Nutanix ) This distinction matters. Erasure coding limits affect efficiency opportunities, but they do not by themselves explain the cluster refusing writes. A degraded container after a node failure may contribute to pressure, but the wording centers on cluster-wide behavior after rebuild-capacity reservation is enabled. Nutanix's resiliency logic is designed to protect the cluster from entering an unsafe state, and one enforcement mechanism is to stop admitting additional writes when resilient capacity has been exhausted. Therefore, the most likely cause is C: the cluster has reached its resilient capacity limit. ( Nutanix )
質問 # 110
An administrator wants to run a workload at site A, but replicate it to two clusters with different RPOs. Which replication option fits the needs?
正解:B
解説:
The requirement is straightforward: there is one source site (Site A) and the workload must be replicated to two destination clusters, each with potentially different RPO settings. In Nutanix DR design terminology, that is a one-to-many replication pattern. Nutanix documentation for multisite disaster recovery explains that a single protection policy can include replication schedules to multiple recovery clusters, which is how a source can protect workloads to more than one target with different schedule definitions. That makes D the correct answer.
The other choices describe different topologies. Many-to-One means multiple sources targeting one destination. Many-to-Many is broader bidirectional or multiple-source/multiple-target logic than the question requires. Two-Way-Mirroring is not the correct pattern for one source sending copies outward to two other sites. Nutanix's protection-policy model is specifically flexible enough to define different replication schedules toward separate destinations, which is why this exact scenario is best labeled One-to-Many. So for an exam-aligned and documentation-consistent answer, D is the right choice.
質問 # 111
Refer to Exhibit: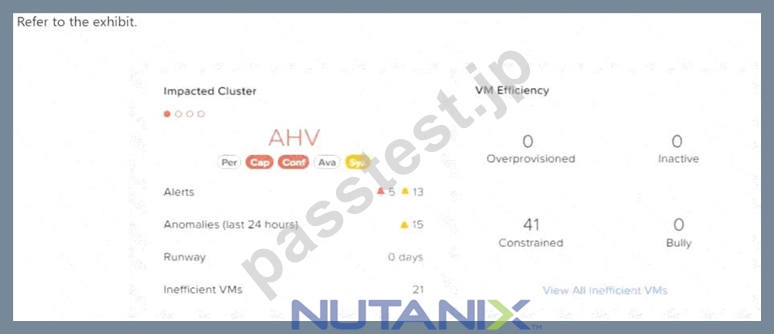
After logging into Prism Central, an administrator observes that there are a large number of constrained VMs.
What does this indicate about those VMs?
正解:D
解説:
In Prism Central VM efficiency and behavioral-learning views, Nutanix groups inefficient VMs into categories such as over-provisioned, inactive, bully, and constrained. A constrained VM is one that does not have enough resources for its workload and is therefore experiencing pressure. Nutanix documentation ties constrained status to signs such as CPU readiness, memory swapping, or other stress indicators that show the VM is not adequately provisioned for what it is trying to do. That means the best interpretation is that those VMs are lacking sufficient resources, which is option B. ( Nutanix Portal ) This category is different from the other distractors. An inactive VM is mostly idle and not making meaningful use of its assigned resources. An over-provisioned VM is wasting capacity because it was allocated too much. A VM that is merely "consuming too much CPU" could be a bully VM or simply a busy VM, but that alone does not define the constrained classification. Nutanix uses the constrained label to signal a right-sizing opportunity in the direction of adding or adjusting resources, not reclaiming them. Therefore the most accurate answer is B, because constrained VMs are the ones that are short on sufficient resources for their workload behavior. ( Nutanix Portal )
質問 # 112
An administrator would like to upgrade LCM (Life Cycle Management) to the latest version on an AHV cluster. Which step should the administrator take to guarantee LCM is upgraded to the latest version?
正解:A
解説:
Nutanix documentation states that when you perform an LCM inventory, Life Cycle Manager first checks and updates its own framework before presenting other upgrade options. Nutanix's guidance for framework updates and recommended upgrade order repeatedly references Perform Inventory as the step that ensures the system discovers and updates the LCM framework itself. That is why A is the correct answer when the goal is specifically to guarantee LCM is upgraded to the latest version. ( Nutanix ) The other actions may be valid parts of broader maintenance, but they do not ensure the LCM framework itself is brought to the latest version. Upgrading AHV or AOS addresses platform components, not the LCM service logic. Running NCC is good pre-upgrade hygiene, but it is not the mechanism that causes LCM to update. Nutanix intentionally ties framework currency to the inventory process, so the correct operational answer is to perform an inventory first. ( Nutanix )
質問 # 113
An administrator is trying to migrate a VM to a new container. The Migration of vDisks stalls.
What could be the cause of this?
正解:D
解説:
A Nutanix vDisk live migration moves the VM's virtual disks into a new storage container while the VM remains online. For that to complete, the destination container must have enough available capacity to receive the migrated vDisk objects. If the target container lacks space, the migration can stall or fail because Nutanix cannot fully place the destination copy and complete the handoff. This makes insufficient storage space in the target storage container the most direct explanation. Nutanix migration and storage workflows consistently rely on adequate target-side capacity before the move can finish successfully. ( portal.nutanix.com ) The distractors are less precise. Source-side snapshots can be part of protection or internal workflow behavior, but the question is specifically about moving to a new container, so target capacity is the key gating factor.
"Local storage container" is too vague and is not the normal object referenced in this workflow.
Operationally, the right next step is to confirm free space, reservations, and any capacity constraints on the destination container before retrying the migration. That is why B is the best answer.
質問 # 114
......
コンテンツの更新に加えて、NCP-MCI-7.5トレーニング資料のシステムも更新されます。ご意見がありましたら、私たちの共通の目標は、ユーザーが満足する製品を作成することであると言えます。学習を開始した後、メールをチェックするための固定時間を設定できることを願っています。 NCP-MCI-7.5実践ガイドまたはシステムの内容が更新された場合、更新された情報を電子メールアドレスに送信します。もちろん、製品の更新状況については、当社の電子メールをご覧ください。 NCP-MCI-7.5模擬試験を使用してNCP-MCI-7.5試験に合格するように協力できることを願っています。
NCP-MCI-7.5関連資格試験対応: https://www.passtest.jp/Nutanix/NCP-MCI-7.5-shiken.html