BONUS!!! Download part of ExamBoosts Databricks-Certified-Data-Analyst-Associate dumps for free: https://drive.google.com/open?id=1l-1UDnVKmwqNa_pm4u8tP0gykJU1MFYq
Compared with other training materials, why ExamBoosts's Databricks Databricks-Certified-Data-Analyst-Associate exam training materials is more welcomed by the majority of candidates? First, this is the problem of resonance. We truly understand the needs of the candidates, and comprehensively than any other site. Second, focus. In order to do the things we decided to complete, we have to give up all the unimportant opportunities. Third, the quality of the product. People always determine a good or bad thing based on the surface. We may have the best products of the highest quality, but if we shows it with a shoddy manner, it naturally will be as shoddy product. However, if we show it with both creative and professional manner, then we will get the best result. The ExamBoosts's Databricks Databricks-Certified-Data-Analyst-Associate Exam Training materials is so successful training materials. It is most suitable for you, quickly select it please.
| Section | Objectives |
|---|---|
| Data Management in Lakehouse | - Data ingestion and preparation
|
| Data Governance and Security | - Access control and permissions
|
| Data Visualization and Dashboards | - Creating dashboards in Databricks SQL
|
| Databricks SQL and SQL Analytics | - Data transformation and analysis
|
>> Test Databricks-Certified-Data-Analyst-Associate Pattern <<
Provided you get the certificate this time with our Databricks-Certified-Data-Analyst-Associate practice materials, you may have striving and excellent friends and promising colleagues just like you. It is also as obvious magnifications of your major ability of profession, so Databricks-Certified-Data-Analyst-Associate practice materials may bring underlying influences with positive effects. The promotion or acceptance will be easy. So it is quite rewarding investment. Propulsion occurs when using our Databricks-Certified-Data-Analyst-Associate practice materials. They can even broaden amplitude of your horizon in this line. Of course, knowledge will accrue to you from our Databricks-Certified-Data-Analyst-Associate practice materials.
NEW QUESTION # 96
A data engineering team has created a Structured Streaming pipeline that processes data in micro-batches and populates gold-level tables. The microbatches are triggered every minute.
A data analyst has created a dashboard based on this gold-level dat
a. The project stakeholders want to see the results in the dashboard updated within one minute or less of new data becoming available within the gold-level tables.
Which of the following cautions should the data analyst share prior to setting up the dashboard to complete this task?
Answer: A
Explanation:
A Structured Streaming pipeline that processes data in micro-batches and populates gold-level tables every minute requires a high level of compute resources to handle the frequent data ingestion, processing, and writing. This could result in a significant cost for the organization, especially if the data volume and velocity are large. Therefore, the data analyst should share this caution with the project stakeholders before setting up the dashboard and evaluate the trade-offs between the desired refresh rate and the available budget. The other options are not valid cautions because:
B . The gold-level tables are assumed to be appropriately clean for business reporting, as they are the final output of the data engineering pipeline. If the data quality is not satisfactory, the issue should be addressed at the source or silver level, not at the gold level.
C . The streaming data is an appropriate data source for a dashboard, as it can provide near real-time insights and analytics for the business users. Structured Streaming supports various sources and sinks for streaming data, including Delta Lake, which can enable both batch and streaming queries on the same data.
D . The streaming cluster is fault tolerant, as Structured Streaming provides end-to-end exactly-once fault-tolerance guarantees through checkpointing and write-ahead logs. If a query fails, it can be restarted from the last checkpoint and resume processing.
E . The dashboard can be refreshed within one minute or less of new data becoming available in the gold-level tables, as Structured Streaming can trigger micro-batches as fast as possible (every few seconds) and update the results incrementally. However, this may not be necessary or optimal for the business use case, as it could cause frequent changes in the dashboard and consume more resources. Reference: Streaming on Databricks, Monitoring Structured Streaming queries on Databricks, A look at the new Structured Streaming UI in Apache Spark 3.0, Run your first Structured Streaming workload
NEW QUESTION # 97
A business analyst has been asked to create a data entity/object called sales_by_employee. It should always stay up-to-date when new data are added to the sales table. The new entity should have the columns sales_person, which will be the name of the employee from the employees table, and sales, which will be all sales for that particular sales person. Both the sales table and the employees table have an employee_id column that is used to identify the sales person.
Which of the following code blocks will accomplish this task?


Answer: C
Explanation:
The SQL code provided in Option D is the correct way to create a view named sales_by_employee that will always stay up-to-date with the sales and employees tables. The code uses the CREATE OR REPLACE VIEW statement to define a new view that joins the sales and employees tables on the employee_id column. It selects the employee_name as sales_person and all sales for each employee, ensuring that the data entity
/object is always up-to-date when new data are added to these tables.
The answer can be verified from Databricks SQL documentation which provides insights on creating views using SQL queries, joining tables, and selecting specific columns to be included in the view. Reference link: Databricks SQL
NEW QUESTION # 98
What describes the variance of a set of values?
Answer: C
Explanation:
Variance is a statistical measure that quantifies the dispersion or spread of a set of values around their mean (central value). It is calculated by taking the average of the squared differences between each value and the mean of the dataset. A higher variance indicates that the data points are more spread out from the mean, while a lower variance suggests that they are closer to the mean. This measure is fundamental in statistics to understand the degree of variability within a dataset.WikipediaWikipedia+1Investopedia+1 Reference: Variance - Wikipedia
NEW QUESTION # 99
Consider the following two statements:
Statement 1: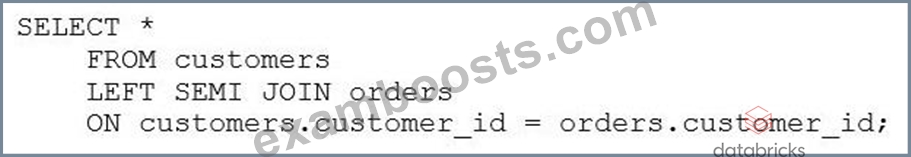
Statement 2: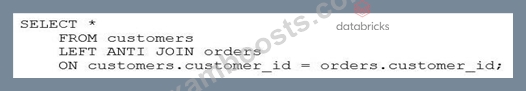
Which of the following describes how the result sets will differ for each statement when they are run in Databricks SQL?
Answer: A
Explanation:
Based on the images you sent, the two statements are SQL queries for different types of joins between the customers and orders tables. A join is a way of combining the rows from two table references based on some criteria. The join type determines how the rows are matched and what kind of result set is returned. The first statement is a query for a LEFT SEMI JOIN, which returns only the rows from the left table reference (customers) that have a match with the right table reference (orders) on the join condition (customer_id). The second statement is a query for a LEFT ANTI JOIN, which returns only the rows from the left table reference (customers) that have no match with the right table reference (orders) on the join condition (customer_id). Therefore, the result sets for the two statements will differ in the following way:
The first statement will return a subset of the customers table that contains only the customers who have placed at least one order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT SEMI JOIN does not include any columns from the orders table.
The second statement will return a subset of the customers table that contains only the customers who have not placed any order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have no orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT ANTI JOIN does not include any columns from the orders table.
The other options are not correct because:
A) The first statement will not return all data from the customers table, as it will exclude the customers who have no orders. The second statement will not return all data from the orders table, as it will exclude the orders that have a matching customer. Neither statement will fill in any missing data with NULL, as they do not return any columns from the other table.
C) There is a difference between the result sets for both statements, as explained above. The LEFT SEMI JOIN and the LEFT ANTI JOIN are not equivalent operations and will produce different outputs.
D) Both statements will not fail, as Databricks SQL does support those join types. Databricks SQL supports various join types, including INNER, LEFT OUTER, RIGHT OUTER, FULL OUTER, LEFT SEMI, LEFT ANTI, and CROSS. You can also use NATURAL, USING, or LATERAL keywords to specify different join criteria.
E) The first statement will not return only the customer_id from the orders table, as it will return all columns from the customers table. The second statement is correct, but it is not the only difference between the result sets.
NEW QUESTION # 100
A data analyst is working with gold-layer tables to complete an ad-hoc project. A stakeholder has provided the analyst with an additional dataset that can be used to augment the gold-layer tables already in use.
Which of the following terms is used to describe this data augmentation?
Answer: B
Explanation:
Data enhancement is the process of adding or enriching data with additional information to improve its quality, accuracy, and usefulness. Data enhancement can be used to augment existing data sources with new data sources, such as external datasets, synthetic data, or machine learning models. Data enhancement can help data analysts to gain deeper insights, discover new patterns, and solve complex problems. Data enhancement is one of the applications of generative AI, which can leverage machine learning to generate synthetic data for better models or safer data sharing1.
In the context of the question, the data analyst is working with gold-layer tables, which are curated business- level tables that are typically organized in consumption-ready project-specific databases234. The gold-layer tables are the final layer of data transformations and data quality rules in the medallion lakehouse architecture, which is a data design pattern used to logically organize data in a lakehouse2. The stakeholder has provided the analyst with an additional dataset that can be used to augment the gold-layer tables already in use. This means that the analyst can use the additional dataset to enhance the existing gold-layer tables with more information, such as new features, attributes, or metrics. This data augmentation can help the analyst to complete the ad-hoc project more effectively and efficiently.
What is the medallion lakehouse architecture? - Databricks
Data Warehousing Modeling Techniques and Their Implementation on the Databricks Lakehouse Platform | Databricks Blog What is the medallion lakehouse architecture? - Azure Databricks What is a Medallion Architecture? - Databricks Synthetic Data for Better Machine Learning | Databricks Blog
NEW QUESTION # 101
......
These latest Databricks Certified Data Analyst Associate Exam (Databricks-Certified-Data-Analyst-Associate) Questions were made by ExamBoosts professionals after working day and night so that users can prepare for the Databricks Databricks-Certified-Data-Analyst-Associate exam successfully. ExamBoosts even guarantees you that you can pass the Databricks Databricks-Certified-Data-Analyst-Associate Certification test on the first try with your untiring efforts.
Databricks-Certified-Data-Analyst-Associate Test Guide: https://www.examboosts.com/Databricks/Databricks-Certified-Data-Analyst-Associate-practice-exam-dumps.html
P.S. Free 2026 Databricks Databricks-Certified-Data-Analyst-Associate dumps are available on Google Drive shared by ExamBoosts: https://drive.google.com/open?id=1l-1UDnVKmwqNa_pm4u8tP0gykJU1MFYq